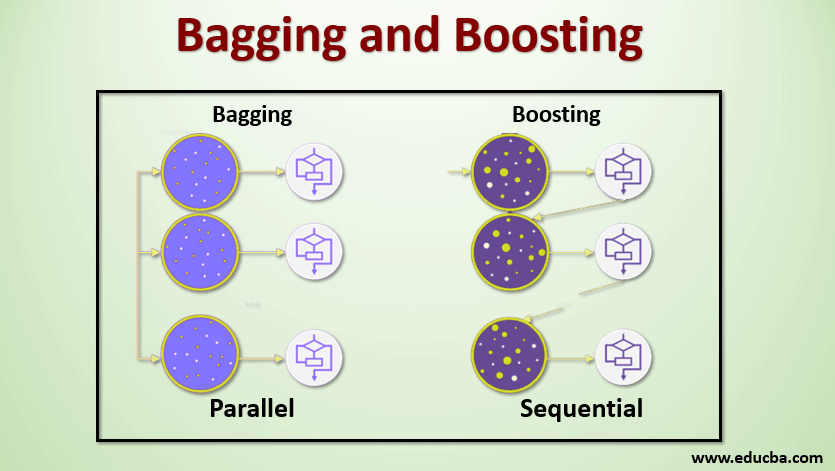
{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# Feedback Prize - Predicting Effective Arguments\n\n \n\n\n\n# **NLP Based Problem: Classification + TextData.....**\n\n## **Goal of the Competition:** \n\nThe goal of this competition is to classify argumentative elements in student writing as \"effective,\" \"adequate,\" or \"ineffective.\" You will create a model trained on data that is representative of the 6th-12th grade population in the United States in order to minimize bias. Models derived from this competition will help pave the way for students to receive enhanced feedback on their argumentative writing. With automated guidance, students can complete more assignments and ultimately become more confident, proficient writers.","metadata":{}},{"cell_type":"markdown","source":"## ***Continue the US pattern matching competition approach:***\n\n1. https://www.kaggle.com/code/venkatkumar001/u-s-p-p-baseline-eda-dataprep\n2. Starter1: https://www.kaggle.com/code/venkatkumar001/nlp-starter1-almost-all-basic-concept\n3. Starter2: https://www.kaggle.com/code/venkatkumar001/nlp-starter2-hf-pretrain-finetune\n4. https://www.kaggle.com/code/venkatkumar001/transformeranatomy-encoder\n\n## ***Now, This feedback price competiton onward!***\n\n1. Starter3: https://www.kaggle.com/venkatkumar001/nlpstarter3-baseline-approach\n\n\n## ***So, I am trying to build baseline Approach of Competition data***\n\n# **Steps:**\n\n### **1. Import Necessary Library**\n\n### **2. Load and analysis the data**\n\n### **3. Preprocessing**\n\n### **4. Feature selection**\n\n### **5. Build the Model**\n\n### **6. Predict Output**\n\n### **7. Generate Submission file**\n\n","metadata":{}},{"cell_type":"markdown","source":"# **Import Necessary Library**","metadata":{}},{"cell_type":"code","source":"import pandas as pd\nimport numpy as np\nimport re\nimport os\nimport matplotlib.pyplot as plt\nimport seaborn as sns\nimport time\nimport datetime\nfrom scipy import sparse\n\n\nfrom sklearn.feature_extraction.text import TfidfVectorizer\nfrom sklearn.model_selection import KFold\nfrom sklearn.preprocessing import OneHotEncoder,LabelEncoder\nfrom sklearn.metrics import log_loss\n\nfrom sklearn import svm\nfrom sklearn.linear_model import LogisticRegression\nfrom sklearn.ensemble import RandomForestClassifier\nfrom sklearn.naive_bayes import BernoulliNB,MultinomialNB\nfrom sklearn.model_selection import cross_val_score\nfrom sklearn.metrics import classification_report, confusion_matrix, accuracy_score, f1_score, precision_score,recall_score","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:54.981032Z","iopub.execute_input":"2022-07-03T15:32:54.981801Z","iopub.status.idle":"2022-07-03T15:32:56.394334Z","shell.execute_reply.started":"2022-07-03T15:32:54.981711Z","shell.execute_reply":"2022-07-03T15:32:56.393376Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import nltk\nfrom nltk.corpus import stopwords\nfrom nltk.stem import SnowballStemmer\nfrom string import punctuation\nfrom nltk.stem.wordnet import WordNetLemmatizer\nfrom tqdm import tqdm\n\n%matplotlib inline\n","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:56.39627Z","iopub.execute_input":"2022-07-03T15:32:56.396592Z","iopub.status.idle":"2022-07-03T15:32:56.836213Z","shell.execute_reply.started":"2022-07-03T15:32:56.396566Z","shell.execute_reply":"2022-07-03T15:32:56.835264Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **Load and Analysis the data**","metadata":{}},{"cell_type":"code","source":"!ls '../input/feedback-prize-effectiveness'","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:56.837759Z","iopub.execute_input":"2022-07-03T15:32:56.838087Z","iopub.status.idle":"2022-07-03T15:32:57.717004Z","shell.execute_reply.started":"2022-07-03T15:32:56.838052Z","shell.execute_reply":"2022-07-03T15:32:57.715688Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train = pd.read_csv('../input/feedback-prize-effectiveness/train.csv')\ntest = pd.read_csv('../input/feedback-prize-effectiveness/test.csv')\nsample = pd.read_csv('../input/feedback-prize-effectiveness/sample_submission.csv')\nprint(f'Train_Shape: {train.shape},Test_Shape: {test.shape},Sample_Shape: {sample.shape}')\ndisplay(train.sample(2))\ndisplay(test.sample(2))\ndisplay(sample.sample(2))","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:57.721913Z","iopub.execute_input":"2022-07-03T15:32:57.722541Z","iopub.status.idle":"2022-07-03T15:32:58.219989Z","shell.execute_reply.started":"2022-07-03T15:32:57.722501Z","shell.execute_reply":"2022-07-03T15:32:58.218756Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train.info()","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:58.22488Z","iopub.execute_input":"2022-07-03T15:32:58.225659Z","iopub.status.idle":"2022-07-03T15:32:58.289488Z","shell.execute_reply.started":"2022-07-03T15:32:58.225614Z","shell.execute_reply":"2022-07-03T15:32:58.28815Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train.describe(include='object')","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:32:58.294908Z","iopub.execute_input":"2022-07-03T15:32:58.297915Z","iopub.status.idle":"2022-07-03T15:32:58.444508Z","shell.execute_reply.started":"2022-07-03T15:32:58.297868Z","shell.execute_reply":"2022-07-03T15:32:58.442176Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train['discourse_type'].value_counts()","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:34:33.583893Z","iopub.execute_input":"2022-07-03T15:34:33.584526Z","iopub.status.idle":"2022-07-03T15:34:33.599221Z","shell.execute_reply.started":"2022-07-03T15:34:33.584488Z","shell.execute_reply":"2022-07-03T15:34:33.598119Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train['discourse_effectiveness'].value_counts()","metadata":{"execution":{"iopub.status.busy":"2022-07-03T15:37:16.369517Z","iopub.execute_input":"2022-07-03T15:37:16.37004Z","iopub.status.idle":"2022-07-03T15:37:16.383466Z","shell.execute_reply.started":"2022-07-03T15:37:16.370003Z","shell.execute_reply":"2022-07-03T15:37:16.382515Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(15,10))\nsns.countplot(x='discourse_id',data=train)","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:31.47514Z","iopub.execute_input":"2022-07-03T12:16:31.475634Z","iopub.status.idle":"2022-07-03T12:16:34.756624Z","shell.execute_reply.started":"2022-07-03T12:16:31.47559Z","shell.execute_reply":"2022-07-03T12:16:34.754854Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(15,10))\nsns.countplot(train['discourse_type'])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(15,10))\nsns.countplot(train['discourse_effectiveness'])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"plt.figure(figsize=(15,10))\nsns.countplot(train['essay_id'])","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train.discourse_type.unique()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **Identify the imbalance of data - discourse_type**","metadata":{}},{"cell_type":"code","source":"#identify the imbalance one\n\ndef count_target(target_list):\n target_dict = {}\n for x in target_list:\n count = len(train['discourse_type'] == x)\n dict_t = dict({x:count})\n target_dict.update(dict_t)\n return target_dict\n\ntarget_list = ['Lead', 'Position', 'Claim', 'Evidence', 'Counterclaim',\n 'Rebuttal', 'Concluding Statement']\ncount_target(target_list)\n","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:07:02.958969Z","iopub.execute_input":"2022-07-02T07:07:02.95934Z","iopub.status.idle":"2022-07-02T07:07:03.004388Z","shell.execute_reply.started":"2022-07-02T07:07:02.959309Z","shell.execute_reply":"2022-07-02T07:07:03.003362Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **KFold**","metadata":{}},{"cell_type":"code","source":"#add extra one columns\ntrain['kfold']=-1\n#Distributing the data 5 shares\nkfold = KFold(n_splits=10, shuffle= True, random_state = 42)\nfor fold, (train_indicies, valid_indicies) in enumerate(kfold.split(X=train)):\n #print(fold,train_indicies,valid_indicies)\n train.loc[valid_indicies,'kfold'] = fold\n\n \nprint(train.kfold.value_counts()) #total data 300000 = kfold split :5 * 60000\n\n#output of train folds data\ntrain.to_csv(\"trainfold_10.csv\",index=False)","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:50.377783Z","iopub.execute_input":"2022-07-03T12:16:50.378589Z","iopub.status.idle":"2022-07-03T12:16:50.914559Z","shell.execute_reply.started":"2022-07-03T12:16:50.378548Z","shell.execute_reply":"2022-07-03T12:16:50.913451Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train = pd.read_csv('./trainfold_10.csv')\ntrain.tail(2)","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:51.963444Z","iopub.execute_input":"2022-07-03T12:16:51.964556Z","iopub.status.idle":"2022-07-03T12:16:52.138926Z","shell.execute_reply.started":"2022-07-03T12:16:51.964501Z","shell.execute_reply":"2022-07-03T12:16:52.137812Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **Preprocessing - NLTK**","metadata":{}},{"cell_type":"markdown","source":"## **1. Clean the discourse_text attribute and generate clean attribute**","metadata":{}},{"cell_type":"code","source":"def cleanup_text(text):\n words = re.sub(pattern = '[^a-zA-Z]',repl = ' ', string = text)\n words = words.lower()\n return words\n\ncleanup_text('VK, is beast mode in my NLP competition ')","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:56.199703Z","iopub.execute_input":"2022-07-03T12:16:56.200132Z","iopub.status.idle":"2022-07-03T12:16:56.209441Z","shell.execute_reply.started":"2022-07-03T12:16:56.2001Z","shell.execute_reply":"2022-07-03T12:16:56.208155Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"text_preprocessed = train['discourse_text'].apply(cleanup_text)\ntext_preprocessed\ntrain['text_preprocessed'] = text_preprocessed\ntrain.sample(2)","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:57.243425Z","iopub.execute_input":"2022-07-03T12:16:57.244179Z","iopub.status.idle":"2022-07-03T12:16:58.398275Z","shell.execute_reply.started":"2022-07-03T12:16:57.24414Z","shell.execute_reply":"2022-07-03T12:16:58.397019Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test_preprocessed = test['discourse_text'].apply(cleanup_text)\ntest_preprocessed\ntest['text_preprocessed'] = test_preprocessed\ntest.head()","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:16:58.400746Z","iopub.execute_input":"2022-07-03T12:16:58.401206Z","iopub.status.idle":"2022-07-03T12:16:58.416877Z","shell.execute_reply.started":"2022-07-03T12:16:58.401155Z","shell.execute_reply":"2022-07-03T12:16:58.415363Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **2. Map the target data**","metadata":{}},{"cell_type":"code","source":"effectiveness_map = {'Ineffective' : 0, 'Adequate':1,'Effective':2}\ntrain['target'] = train['discourse_effectiveness'].map(effectiveness_map)\ntrain.sample(2)","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:00.370223Z","iopub.execute_input":"2022-07-03T12:17:00.370655Z","iopub.status.idle":"2022-07-03T12:17:00.39634Z","shell.execute_reply.started":"2022-07-03T12:17:00.370614Z","shell.execute_reply":"2022-07-03T12:17:00.395254Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **3. Preprocessing - Apply one hot encoding in (discourse type) , TFIDF vectorize in (discourse text and cleaning text)**","metadata":{}},{"cell_type":"code","source":"tf = TfidfVectorizer(ngram_range=(1,2),norm='l2', smooth_idf=True)\ntrain_discourse_tfidf = tf.fit_transform(train[\"discourse_text\"])\ntest_discourse_tfidf = tf.transform(test[\"discourse_text\"])\n ","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:02.601845Z","iopub.execute_input":"2022-07-03T12:17:02.602255Z","iopub.status.idle":"2022-07-03T12:17:07.979141Z","shell.execute_reply.started":"2022-07-03T12:17:02.60222Z","shell.execute_reply":"2022-07-03T12:17:07.977911Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"tf = TfidfVectorizer(ngram_range=(1,2),norm='l2', smooth_idf=True) # Load tf another time because it will learn the new vocabulary for 'text'\ntrain_text_tfidf = tf.fit_transform(train[\"text_preprocessed\"])\ntest_text_tfidf = tf.transform(test[\"text_preprocessed\"])\n ","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:07.981253Z","iopub.execute_input":"2022-07-03T12:17:07.981676Z","iopub.status.idle":"2022-07-03T12:17:12.980602Z","shell.execute_reply.started":"2022-07-03T12:17:07.981641Z","shell.execute_reply":"2022-07-03T12:17:12.979417Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#discourse_type\nohe = OneHotEncoder()\ntrain_type_ohe = sparse.csr_matrix(ohe.fit_transform(train[\"discourse_type\"].values.reshape(-1,1)))\ntest_type_ohe = sparse.csr_matrix(ohe.transform(test[\"discourse_type\"].values.reshape(-1,1)))\n ","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:12.982921Z","iopub.execute_input":"2022-07-03T12:17:12.983337Z","iopub.status.idle":"2022-07-03T12:17:13.005951Z","shell.execute_reply.started":"2022-07-03T12:17:12.983306Z","shell.execute_reply":"2022-07-03T12:17:13.004761Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **4. Stack the all three preprocess data**","metadata":{}},{"cell_type":"code","source":"#Stack each vector representations \ntrain_tfidf = sparse.hstack((train_type_ohe,train_discourse_tfidf,train_text_tfidf))\ntest_tfidf = sparse.hstack((test_type_ohe,test_discourse_tfidf,test_text_tfidf))\n ","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:13.007557Z","iopub.execute_input":"2022-07-03T12:17:13.008736Z","iopub.status.idle":"2022-07-03T12:17:13.146213Z","shell.execute_reply.started":"2022-07-03T12:17:13.008681Z","shell.execute_reply":"2022-07-03T12:17:13.145175Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_tfidf","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:17:14.82227Z","iopub.execute_input":"2022-07-03T12:17:14.822854Z","iopub.status.idle":"2022-07-03T12:17:14.8319Z","shell.execute_reply.started":"2022-07-03T12:17:14.822818Z","shell.execute_reply":"2022-07-03T12:17:14.830516Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **Build the Model**\n\n## **1. Logistic Regression**\n\n## **2. BernoulliNB**\n\n## **3. SVM**\n\n## **4. Boosting Methods**","metadata":{}},{"cell_type":"markdown","source":"## **1. LogisticRegression - First try** \n\n
 ","metadata":{}},{"cell_type":"code","source":"# clf1 = LogisticRegression(max_iter=500,penalty=\"l2\",C=1.0131816333513533)\n# clf1.fit(train_tfidf, train[\"target\"].values)","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:06:29.477881Z","iopub.status.idle":"2022-07-02T07:06:29.478494Z","shell.execute_reply.started":"2022-07-02T07:06:29.478324Z","shell.execute_reply":"2022-07-02T07:06:29.478342Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **2.BernoulliNB-Second try**\n\n
 ","metadata":{}},{"cell_type":"code","source":"# #Model\n# clf2 = BernoulliNB()\n# clf2.fit(train_tfidf, train[\"target\"].values)","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:06:29.48252Z","iopub.status.idle":"2022-07-02T07:06:29.483314Z","shell.execute_reply.started":"2022-07-02T07:06:29.483025Z","shell.execute_reply":"2022-07-02T07:06:29.483052Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **3. SVM-Third try**\n\n
 ","metadata":{}},{"cell_type":"code","source":"# #Model\n# clf3 = svm.SVC(decision_function_shape='ovo')\n# clf3.fit(train_tfidf, train[\"target\"].values)","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:06:29.48456Z","iopub.status.idle":"2022-07-02T07:06:29.485303Z","shell.execute_reply.started":"2022-07-02T07:06:29.485016Z","shell.execute_reply":"2022-07-02T07:06:29.485041Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## 4. **Boosting method - Make a good result**\n\n
 ","metadata":{}},{"cell_type":"markdown","source":"# **CatBoost-Taken Long time to run**","metadata":{}},{"cell_type":"code","source":"# from catboost import CatBoostRegressor,CatBoostClassifier\n\n# #cat\n# catpara={\n# 'learning_rate': 0.001152,\n# \"max_depth\": 3,\n# 'random_state':42,\n# 'n_estimators':1000\n# }\n# cat = CatBoostClassifier(**catpara).fit(train_tfidf, train[\"target\"].values,verbose=False)","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"execution":{"iopub.status.busy":"2022-07-02T07:06:29.486622Z","iopub.status.idle":"2022-07-02T07:06:29.487361Z","shell.execute_reply.started":"2022-07-02T07:06:29.487078Z","shell.execute_reply":"2022-07-02T07:06:29.487103Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **LGBM - Gives the 0.790 this below code ==> if you want more result to try to hyperparameters tuning or go to bert model**","metadata":{}},{"cell_type":"code","source":"\n# #lgb parameters\n# from lightgbm import LGBMRegressor,LGBMClassifier\n# import lightgbm as lgb\n\n# params_lgb = {\n# \"boosting_type\": \"gbdt\",\n# \"objective\": \"multiclass\",\n# 'subsample': 0.95312,\n# 'learning_rate': 0.001635,\n# \"max_depth\": 3,\n# 'random_state':12,\n# 'n_estimators':15000,\n# }\n \n\n\n# model1= LGBMClassifier(**params_lgb )\n \n# model1.fit(train_tfidf, train[\"target\"].values)\n \n","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:06:29.488692Z","iopub.status.idle":"2022-07-02T07:06:29.489432Z","shell.execute_reply.started":"2022-07-02T07:06:29.489165Z","shell.execute_reply":"2022-07-02T07:06:29.48919Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## **XGBoost-Make good result lets try better one**","metadata":{}},{"cell_type":"code","source":"# from xgboost import XGBRegressor,XGBClassifier\n\n# #Model hyperparameter of XGboostRegressor\n# xgb_params = {\n# 'learning_rate': 0.001368,\n# 'subsample': 0.7875490025178,\n# 'colsample_bytree': 0.11807135201147,\n# 'max_depth': 3,\n# 'booster': 'gbtree', \n# 'reg_lambda': 0.0008746338866473539,\n# 'reg_alpha': 23.13181079976304,\n# 'random_state':42,\n# 'n_estimators':8000\n# }\n \n# model= XGBClassifier(**xgb_params,\n# tree_method='gpu_hist',\n# predictor='gpu_predictor',\n# gpu_id=0)\n \n# model.fit(train_tfidf, train[\"target\"].values)","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:06:29.490785Z","iopub.status.idle":"2022-07-02T07:06:29.491513Z","shell.execute_reply.started":"2022-07-02T07:06:29.491246Z","shell.execute_reply":"2022-07-02T07:06:29.491271Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **Try to build KFolding with XGB,LGBM**","metadata":{}},{"cell_type":"code","source":"from xgboost import XGBRegressor,XGBClassifier\nimport lightgbm as lgb\nfrom lightgbm import LGBMClassifier\n#store the final_prediction data and score\n\nfor fold in range(10):\n \n params_lgb = {\n \"boosting_type\": \"gbdt\",\n \"objective\": \"multiclass\",\n 'subsample': 0.95312,\n 'learning_rate': 0.001635,\n \"max_depth\": 3,\n 'random_state':12,\n 'n_estimators':15000,\n }\n \n model= LGBMClassifier(**params_lgb )\n model.fit(train_tfidf, train[\"target\"].values)\n \n print(f\"fold:{fold}\") ","metadata":{"execution":{"iopub.status.busy":"2022-07-03T12:18:00.221653Z","iopub.execute_input":"2022-07-03T12:18:00.222737Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **Predict output - using Boosting Model**","metadata":{}},{"cell_type":"code","source":"test_predict = model.predict_proba(test_tfidf)\ntest_predict","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:14:22.372914Z","iopub.execute_input":"2022-07-02T07:14:22.373317Z","iopub.status.idle":"2022-07-02T07:14:22.393345Z","shell.execute_reply.started":"2022-07-02T07:14:22.373277Z","shell.execute_reply":"2022-07-02T07:14:22.392296Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"sample.loc[:,\"Ineffective\"] = test_predict[:,0]\nsample.loc[:,\"Adequate\"] = test_predict[:,1]\nsample.loc[:,\"Effective\"] = test_predict[:,2]\nsample.to_csv('submission.csv',index=False)","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:15:02.185549Z","iopub.execute_input":"2022-07-02T07:15:02.18591Z","iopub.status.idle":"2022-07-02T07:15:02.198186Z","shell.execute_reply.started":"2022-07-02T07:15:02.185879Z","shell.execute_reply":"2022-07-02T07:15:02.196939Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"print('successfully execute all!')\nsample.head()","metadata":{"execution":{"iopub.status.busy":"2022-07-02T07:15:05.149561Z","iopub.execute_input":"2022-07-02T07:15:05.149902Z","iopub.status.idle":"2022-07-02T07:15:05.167169Z","shell.execute_reply.started":"2022-07-02T07:15:05.149873Z","shell.execute_reply":"2022-07-02T07:15:05.166214Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"","metadata":{},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## ***Next Process Coming Soon..........Preprocessing***\n\n## **\"if you see any errors and your opinion! feel free to share with me\"**\n\ncredit of this notebook: \n\n1. https://www.kaggle.com/code/chandraprajapati/feedback-prize-logistic-regression\n2. https://www.kaggle.com/code/venkatkumar001/nlp-starter1-almost-all-basic-concept\n3. https://www.kaggle.com/code/bhavikardeshna/logisticregression-feedback-price-effectiveness\n\n\n## ⭐️⭐️Thanks for visiting guys⭐️⭐️","metadata":{}}]}