{
  "id": 401185,
  "title": "SAM applied to Vesuvius Challenge?",
  "url": "/competitions/vesuvius-challenge-ink-detection/discussion/401185",
  "author_name": "",
  "post_date": "2023-04-12T06:26:39.294309700Z",
  "votes": 22,
  "comment_count": 8,
  "views": 0,
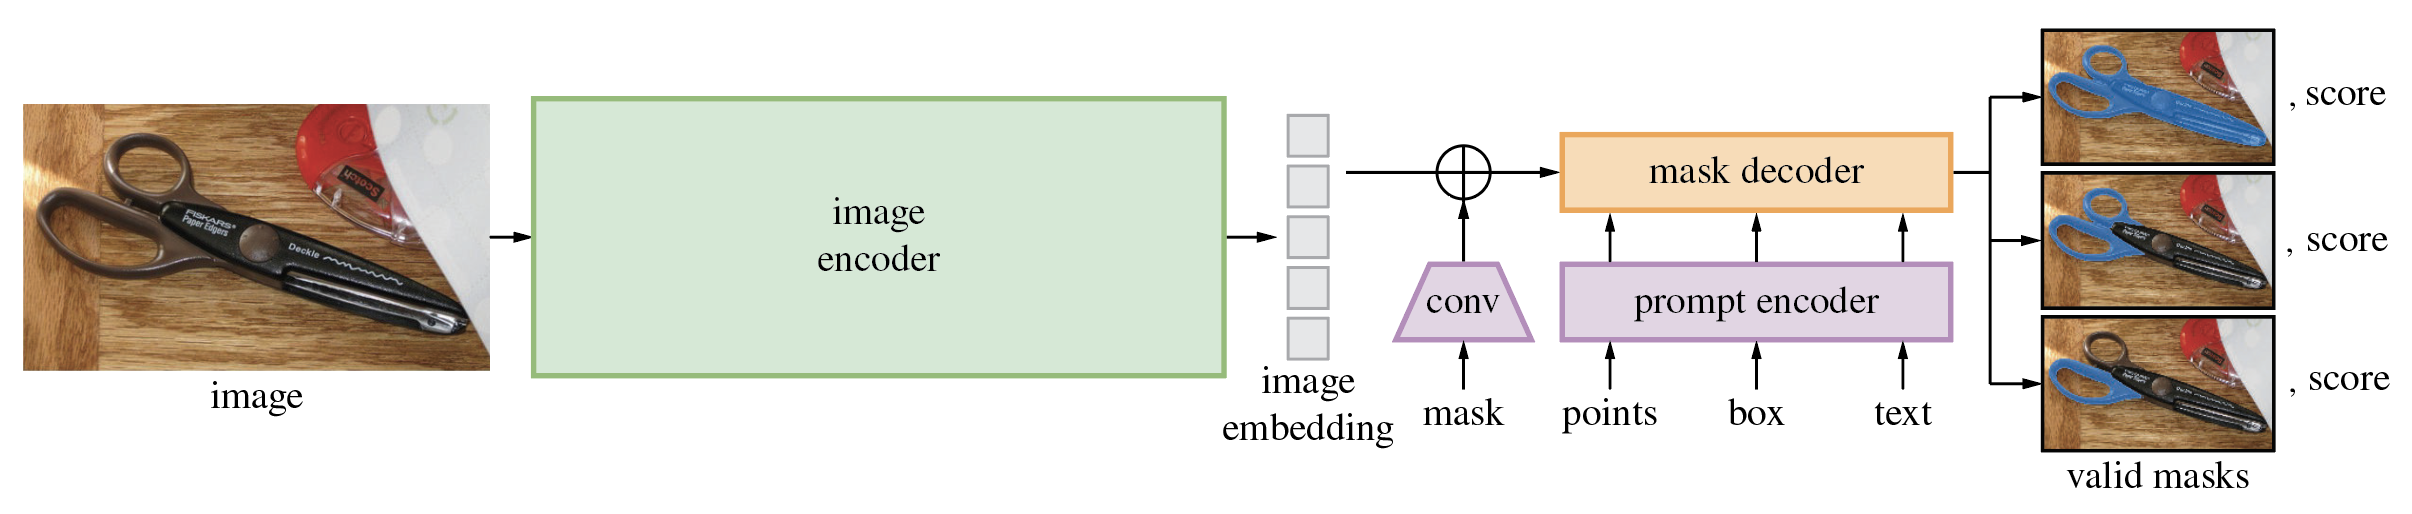
  "content": "<p><strong>SAM</strong>: segment anything model!</p>\n<p>This is a new <strong>segmentation</strong> model by Meta. It can be used to segment all the objects from a given image.</p>\n<p><img src=\"https://raw.githubusercontent.com/facebookresearch/segment-anything/main/assets/model_diagram.png\" alt=\"model architecture\"></p>\n<ul>\n<li>Main page: <a href=\"https://segment-anything.com/\" target=\"_blank\">https://segment-anything.com/</a></li>\n<li>Blog post: <a href=\"https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/\" target=\"_blank\">https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/</a></li>\n<li>Paper: <a href=\"https://arxiv.org/abs/2304.02643\" target=\"_blank\">https://arxiv.org/abs/2304.02643</a></li>\n<li>Code: <a href=\"https://github.com/facebookresearch/segment-anything\" target=\"_blank\">https://github.com/facebookresearch/segment-anything</a></li>\n<li>Dataset: <a href=\"https://ai.facebook.com/datasets/segment-anything/\" target=\"_blank\">https://ai.facebook.com/datasets/segment-anything/</a></li>\n</ul>\n<p>Here is a result applied to one image from the demo (that you can find <a href=\"https://segment-anything.com/demo\" target=\"_blank\">here</a>):</p>\n<p><img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F7db7fa730527714f134373dd1efa2081%2Fsam_vesiuvius.png?generation=1681147493387483&amp;alt=media\" alt=\"sam_example\"></p>\n<p>Looks interesting without even any training. Will try to fine-tune on the training data and share more later. Stay tuned.</p>",
  "messages": [
    {
      "id": "2218926",
      "postDate": "04/12/2023 06:26:39",
      "content": "<p><strong>SAM</strong>: segment anything model!</p>\n<p>This is a new <strong>segmentation</strong> model by Meta. It can be used to segment all the objects from a given image.</p>\n<p><img src=\"https://raw.githubusercontent.com/facebookresearch/segment-anything/main/assets/model_diagram.png\" alt=\"model architecture\"></p>\n<ul>\n<li>Main page: <a href=\"https://segment-anything.com/\" target=\"_blank\">https://segment-anything.com/</a></li>\n<li>Blog post: <a href=\"https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/\" target=\"_blank\">https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/</a></li>\n<li>Paper: <a href=\"https://arxiv.org/abs/2304.02643\" target=\"_blank\">https://arxiv.org/abs/2304.02643</a></li>\n<li>Code: <a href=\"https://github.com/facebookresearch/segment-anything\" target=\"_blank\">https://github.com/facebookresearch/segment-anything</a></li>\n<li>Dataset: <a href=\"https://ai.facebook.com/datasets/segment-anything/\" target=\"_blank\">https://ai.facebook.com/datasets/segment-anything/</a></li>\n</ul>\n<p>Here is a result applied to one image from the demo (that you can find <a href=\"https://segment-anything.com/demo\" target=\"_blank\">here</a>):</p>\n<p><img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F7db7fa730527714f134373dd1efa2081%2Fsam_vesiuvius.png?generation=1681147493387483&amp;alt=media\" alt=\"sam_example\"></p>\n<p>Looks interesting without even any training. Will try to fine-tune on the training data and share more later. Stay tuned.</p>",
      "rawMarkdown": "**SAM**: segment anything model!\n\nThis is a new **segmentation** model by Meta. It can be used to segment all the objects from a given image.\n\n![model architecture](https://raw.githubusercontent.com/facebookresearch/segment-anything/main/assets/model_diagram.png)\n\n- Main page: https://segment-anything.com/\n- Blog post: https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/\n- Paper: https://arxiv.org/abs/2304.02643\n- Code: https://github.com/facebookresearch/segment-anything\n- Dataset: https://ai.facebook.com/datasets/segment-anything/\n\nHere is a result applied to one image from the demo (that you can find [here](https://segment-anything.com/demo)):\n\n![sam_example](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F7db7fa730527714f134373dd1efa2081%2Fsam_vesiuvius.png?generation=1681147493387483&alt=media)\n\nLooks interesting without even any training. Will try to fine-tune on the training data and share more later. Stay tuned.",
      "votes": null
    },
    {
      "id": "2223422",
      "postDate": "04/16/2023 08:44:59",
      "content": "<p><img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F6568959126d1b2a9d1967244150f196a%2Farchitecture_sam.png?generation=1681633900793770&amp;alt=media\" alt=\"sam architecture\"></p>\n<p>The SAM paper contains three main contributions:</p>\n<ul>\n<li>Promptable segmentation:  this tells the model which parts of the image to segment and gives some contextual clues.</li>\n<li>A general-purpose segmentation model: this is the model part that is made of two encoders, one for the image and one for the prompt and a mask decoder. The image encoder is adapted from the ViT architecture.</li>\n<li>A data engine: this was used to collect the SA-1B dataset via a feedback loop (model =&gt; annotate =&gt; data =&gt; train =&gt; model). The dataset is made of 11M images and more than 1B masks.</li>\n</ul>",
      "rawMarkdown": "![sam architecture](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F6568959126d1b2a9d1967244150f196a%2Farchitecture_sam.png?generation=1681633900793770&alt=media)\n\nThe SAM paper contains three main contributions:\n\n- Promptable segmentation:  this tells the model which parts of the image to segment and gives some contextual clues.\n- A general-purpose segmentation model: this is the model part that is made of two encoders, one for the image and one for the prompt and a mask decoder. The image encoder is adapted from the ViT architecture.\n- A data engine: this was used to collect the SA-1B dataset via a feedback loop (model => annotate => data => train => model). The dataset is made of 11M images and more than 1B masks.",
      "votes": null
    },
    {
      "id": "2224752",
      "postDate": "04/17/2023 16:18:59",
      "content": "<p>Is your input one of the volume layers? Did you exported as PNG before importing into the demo? I was taking a look at SAM, but thought it was not possible because it was trained on 3 channel RGB images. </p>",
      "rawMarkdown": "Is your input one of the volume layers? Did you exported as PNG before importing into the demo? I was taking a look at SAM, but thought it was not possible because it was trained on 3 channel RGB images.",
      "votes": null
    },
    {
      "id": "2224789",
      "postDate": "04/17/2023 16:56:13",
      "content": "<p>That's a good point to keep in mind. I have done it on the ink image and not a volume. To make it work on a 3D voxels volume, the model has to be adapted. I will share new insights if I can. </p>",
      "rawMarkdown": "That's a good point to keep in mind. I have done it on the ink image and not a volume. To make it work on a 3D voxels volume, the model has to be adapted. I will share new insights if I can.",
      "votes": null
    },
    {
      "id": "2232535",
      "postDate": "04/24/2023 12:36:08",
      "content": "<p>Consider taking a look at this notebook: <a href=\"https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam\" target=\"_blank\">https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam</a></p>",
      "rawMarkdown": "Consider taking a look at this notebook: https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam",
      "votes": null
    },
    {
      "id": "2232557",
      "postDate": "04/24/2023 13:10:37",
      "content": "<p>Thanks for the link. 👀</p>",
      "rawMarkdown": "Thanks for the link. 👀",
      "votes": null
    },
    {
      "id": "2272601",
      "postDate": "05/24/2023 15:48:31",
      "content": "<p>Did anybody try to fine-tune?</p>",
      "rawMarkdown": "Did anybody try to fine-tune?",
      "votes": null
    },
    {
      "id": "2272780",
      "postDate": "05/24/2023 18:27:35",
      "content": "<p>I am working on something but not yet there. <br>\nIf you want to have an example notebook, check this <a href=\"https://colab.research.google.com/drive/1F6uRommb3GswcRlPZWpkAQRMVNdVH7Ww?usp=sharing\" target=\"_blank\">one</a> or this <a href=\"https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb\" target=\"_blank\">one</a>.</p>",
      "rawMarkdown": "I am working on something but not yet there. \nIf you want to have an example notebook, check this [one](https://colab.research.google.com/drive/1F6uRommb3GswcRlPZWpkAQRMVNdVH7Ww?usp=sharing) or this [one](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb).",
      "votes": null
    },
    {
      "id": "2273732",
      "postDate": "05/25/2023 11:20:02",
      "content": "<p>Great links, thanks!!</p>",
      "rawMarkdown": "Great links, thanks!!",
      "votes": null
    }
  ],
  "comments": [
    {
      "id": 2223422,
      "author_name": "yassinealouini",
      "author_url": "",
      "post_date": "04/16/2023 08:44:59",
      "content": "<p><img src=\"https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F6568959126d1b2a9d1967244150f196a%2Farchitecture_sam.png?generation=1681633900793770&amp;alt=media\" alt=\"sam architecture\"></p>\n<p>The SAM paper contains three main contributions:</p>\n<ul>\n<li>Promptable segmentation:  this tells the model which parts of the image to segment and gives some contextual clues.</li>\n<li>A general-purpose segmentation model: this is the model part that is made of two encoders, one for the image and one for the prompt and a mask decoder. The image encoder is adapted from the ViT architecture.</li>\n<li>A data engine: this was used to collect the SA-1B dataset via a feedback loop (model =&gt; annotate =&gt; data =&gt; train =&gt; model). The dataset is made of 11M images and more than 1B masks.</li>\n</ul>",
      "votes": null,
      "replies": []
    },
    {
      "id": 2224752,
      "author_name": "fpeccia",
      "author_url": "",
      "post_date": "04/17/2023 16:18:59",
      "content": "<p>Is your input one of the volume layers? Did you exported as PNG before importing into the demo? I was taking a look at SAM, but thought it was not possible because it was trained on 3 channel RGB images. </p>",
      "votes": null,
      "replies": [
        {
          "id": 2224789,
          "author_name": "yassinealouini",
          "author_url": "",
          "post_date": "04/17/2023 16:56:13",
          "content": "<p>That's a good point to keep in mind. I have done it on the ink image and not a volume. To make it work on a 3D voxels volume, the model has to be adapted. I will share new insights if I can. </p>",
          "votes": null,
          "replies": []
        }
      ]
    },
    {
      "id": 2232535,
      "author_name": "skalskip",
      "author_url": "",
      "post_date": "04/24/2023 12:36:08",
      "content": "<p>Consider taking a look at this notebook: <a href=\"https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam\" target=\"_blank\">https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam</a></p>",
      "votes": null,
      "replies": [
        {
          "id": 2232557,
          "author_name": "yassinealouini",
          "author_url": "",
          "post_date": "04/24/2023 13:10:37",
          "content": "<p>Thanks for the link. 👀</p>",
          "votes": null,
          "replies": []
        }
      ]
    },
    {
      "id": 2272601,
      "author_name": "polishch",
      "author_url": "",
      "post_date": "05/24/2023 15:48:31",
      "content": "<p>Did anybody try to fine-tune?</p>",
      "votes": null,
      "replies": [
        {
          "id": 2272780,
          "author_name": "yassinealouini",
          "author_url": "",
          "post_date": "05/24/2023 18:27:35",
          "content": "<p>I am working on something but not yet there. <br>\nIf you want to have an example notebook, check this <a href=\"https://colab.research.google.com/drive/1F6uRommb3GswcRlPZWpkAQRMVNdVH7Ww?usp=sharing\" target=\"_blank\">one</a> or this <a href=\"https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb\" target=\"_blank\">one</a>.</p>",
          "votes": null,
          "replies": [
            {
              "id": 2273732,
              "author_name": "polishch",
              "author_url": "",
              "post_date": "05/25/2023 11:20:02",
              "content": "<p>Great links, thanks!!</p>",
              "votes": null,
              "replies": []
            }
          ]
        }
      ]
    }
  ],
  "raw_markdown_by_id": {
    "2218926": "**SAM**: segment anything model!\n\nThis is a new **segmentation** model by Meta. It can be used to segment all the objects from a given image.\n\n![model architecture](https://raw.githubusercontent.com/facebookresearch/segment-anything/main/assets/model_diagram.png)\n\n- Main page: https://segment-anything.com/\n- Blog post: https://ai.facebook.com/blog/segment-anything-foundation-model-image-segmentation/\n- Paper: https://arxiv.org/abs/2304.02643\n- Code: https://github.com/facebookresearch/segment-anything\n- Dataset: https://ai.facebook.com/datasets/segment-anything/\n\nHere is a result applied to one image from the demo (that you can find [here](https://segment-anything.com/demo)):\n\n![sam_example](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F7db7fa730527714f134373dd1efa2081%2Fsam_vesiuvius.png?generation=1681147493387483&alt=media)\n\nLooks interesting without even any training. Will try to fine-tune on the training data and share more later. Stay tuned.",

    "2223422": "![sam architecture](https://www.googleapis.com/download/storage/v1/b/kaggle-forum-message-attachments/o/inbox%2F172860%2F6568959126d1b2a9d1967244150f196a%2Farchitecture_sam.png?generation=1681633900793770&alt=media)\n\nThe SAM paper contains three main contributions:\n\n- Promptable segmentation:  this tells the model which parts of the image to segment and gives some contextual clues.\n- A general-purpose segmentation model: this is the model part that is made of two encoders, one for the image and one for the prompt and a mask decoder. The image encoder is adapted from the ViT architecture.\n- A data engine: this was used to collect the SA-1B dataset via a feedback loop (model => annotate => data => train => model). The dataset is made of 11M images and more than 1B masks.",
    "2224752": "Is your input one of the volume layers? Did you exported as PNG before importing into the demo? I was taking a look at SAM, but thought it was not possible because it was trained on 3 channel RGB images.",
    "2224789": "That's a good point to keep in mind. I have done it on the ink image and not a volume. To make it work on a 3D voxels volume, the model has to be adapted. I will share new insights if I can.",
    "2232535": "Consider taking a look at this notebook: https://www.kaggle.com/code/skalskip/how-to-use-segment-anything-model-sam",
    "2232557": "Thanks for the link. 👀",
    "2272601": "Did anybody try to fine-tune?",
    "2272780": "I am working on something but not yet there. \nIf you want to have an example notebook, check this [one](https://colab.research.google.com/drive/1F6uRommb3GswcRlPZWpkAQRMVNdVH7Ww?usp=sharing) or this [one](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb).",
    "2273732": "Great links, thanks!!"
  },
  "source": "meta"
}