{
  "id": 290617,
  "title": "IoU-based loss functions for bounding box regression",
  "url": "/competitions/sartorius-cell-instance-segmentation/discussion/290617",
  "author_name": "",
  "post_date": "2021-11-25T13:32:00.788388300Z",
  "votes": 14,
  "comment_count": 6,
  "views": 0,
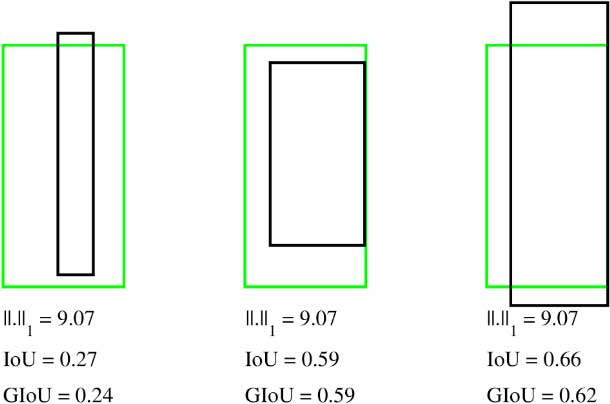
  "content": "<p>I read the papers below and decided to give a try to IoU-based loss functions for bounding box regression.</p>\n<p><a href=\"https://giou.stanford.edu/GIoU.pdf\" target=\"_blank\">https://giou.stanford.edu/GIoU.pdf</a><br>\n<a href=\"https://arxiv.org/pdf/1911.08287.pdf\" target=\"_blank\">https://arxiv.org/pdf/1911.08287.pdf</a><br>\n<a href=\"https://arxiv.org/pdf/2005.03572.pdf\" target=\"_blank\">https://arxiv.org/pdf/2005.03572.pdf</a></p>\n<p>Main motivation of proposing such loss functions is l1 and l2 losses are not strongly correlated with IoU. This problem is illustrated here.</p>\n<p><img src=\"https://giou.stanford.edu/_nuxt/img/9369e27.jpg\" alt=\"l1\"></p>\n<p>In papers, they obtained superior results in many benchmarks but it was the opposite in my case. I got slightly worse mAP and slow convergence. Does anyone see any improvement using them? </p>",
  "messages": [
    {
      "id": "1595201",
      "postDate": "11/25/2021 13:32:00",
      "content": "<p>I read the papers below and decided to give a try to IoU-based loss functions for bounding box regression.</p>\n<p><a href=\"https://giou.stanford.edu/GIoU.pdf\" target=\"_blank\">https://giou.stanford.edu/GIoU.pdf</a><br>\n<a href=\"https://arxiv.org/pdf/1911.08287.pdf\" target=\"_blank\">https://arxiv.org/pdf/1911.08287.pdf</a><br>\n<a href=\"https://arxiv.org/pdf/2005.03572.pdf\" target=\"_blank\">https://arxiv.org/pdf/2005.03572.pdf</a></p>\n<p>Main motivation of proposing such loss functions is l1 and l2 losses are not strongly correlated with IoU. This problem is illustrated here.</p>\n<p><img src=\"https://giou.stanford.edu/_nuxt/img/9369e27.jpg\" alt=\"l1\"></p>\n<p>In papers, they obtained superior results in many benchmarks but it was the opposite in my case. I got slightly worse mAP and slow convergence. Does anyone see any improvement using them? </p>",
      "rawMarkdown": "I read the papers below and decided to give a try to IoU-based loss functions for bounding box regression.\n\nhttps://giou.stanford.edu/GIoU.pdf\nhttps://arxiv.org/pdf/1911.08287.pdf\nhttps://arxiv.org/pdf/2005.03572.pdf\n\nMain motivation of proposing such loss functions is l1 and l2 losses are not strongly correlated with IoU. This problem is illustrated here.\n\n![l1](https://giou.stanford.edu/_nuxt/img/9369e27.jpg)\n\nIn papers, they obtained superior results in many benchmarks but it was the opposite in my case. I got slightly worse mAP and slow convergence. Does anyone see any improvement using them?",
      "votes": null
    },
    {
      "id": "1595238",
      "postDate": "11/25/2021 14:15:33",
      "content": "<p><a href=\"https://www.kaggle.com/gunesevitan\" target=\"_blank\">@gunesevitan</a>  where u modified for changes..</p>",
      "rawMarkdown": "gunesevitan  where u modified for changes..",
      "votes": null
    },
    {
      "id": "1595267",
      "postDate": "11/25/2021 14:47:36",
      "content": "<p>If you are using detectron2, modify these configs : </p>\n<pre><code>cfg.MODEL.RPN.BBOX_REG_LOSS_TYPE = \"ciou\"\ncfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_TYPE = \"ciou\"\n</code></pre>\n<p>By default, they are set to \"smooth_l1\" loss. I remember <a href=\"https://github.com/facebookresearch/detectron2/pull/3481\" target=\"_blank\">adding</a> these losses in detectron2 a few months ago, perfectly in time for the competition :)</p>",
      "rawMarkdown": "If you are using detectron2, modify these configs : \n```\ncfg.MODEL.RPN.BBOX_REG_LOSS_TYPE = \"ciou\"\ncfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_TYPE = \"ciou\"\n```\nBy default, they are set to \"smooth_l1\" loss. I remember [adding](https://github.com/facebookresearch/detectron2/pull/3481) these losses in detectron2 a few months ago, perfectly in time for the competition :)",
      "votes": null
    },
    {
      "id": "1595271",
      "postDate": "11/25/2021 14:49:24",
      "content": "<p><a href=\"https://www.kaggle.com/gunesevitan\" target=\"_blank\">@gunesevitan</a> Try changing <code>cfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_WEIGHT</code> for better convergence. I've set it to 10</p>",
      "rawMarkdown": "gunesevitan Try changing `cfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_WEIGHT` for better convergence. I've set it to 10",
      "votes": null
    },
    {
      "id": "1595522",
      "postDate": "11/25/2021 18:48:40",
      "content": "<p>Hello <a href=\"https://www.kaggle.com/samfc10\" target=\"_blank\">@samfc10</a>. I'm very lucky to run into you. Did you get better results with ciou loss compared to l1 loss?</p>",
      "rawMarkdown": "Hello @samfc10. I'm very lucky to run into you. Did you get better results with ciou loss compared to l1 loss?",
      "votes": null
    },
    {
      "id": "1595832",
      "postDate": "11/26/2021 03:08:30",
      "content": "<p>I had tried both the losses very early in the competition. Didn't have my CV setup that time, these are the public LB scores for the submissions :</p>\n<pre><code>resnet50 new overlap method - 0.25\nresnet50 ciou new overlap - 0.258\n</code></pre>\n<p>3.2% improvement, seems consistent with the results reported in the paper.<br>\n<a href=\"https://ibb.co/DLH5ybz\" target=\"_blank\">https://ibb.co/DLH5ybz</a></p>",
      "rawMarkdown": "I had tried both the losses very early in the competition. Didn't have my CV setup that time, these are the public LB scores for the submissions :\n```\nresnet50 new overlap method - 0.25\nresnet50 ciou new overlap - 0.258\n```\n3.2% improvement, seems consistent with the results reported in the paper.\nhttps://ibb.co/DLH5ybz",
      "votes": null
    },
    {
      "id": "1615677",
      "postDate": "12/12/2021 14:40:53",
      "content": "<p><a href=\"https://www.kaggle.com/jaideepvalani\" target=\"_blank\">@jaideepvalani</a>  have you improved after using it?</p>",
      "rawMarkdown": "jaideepvalani  have you improved after using it?",
      "votes": null
    }
  ],
  "comments": [
    {
      "id": 1595238,
      "author_name": "jaideepvalani",
      "author_url": "",
      "post_date": "11/25/2021 14:15:33",
      "content": "<p><a href=\"https://www.kaggle.com/gunesevitan\" target=\"_blank\">@gunesevitan</a>  where u modified for changes..</p>",
      "votes": null,
      "replies": [
        {
          "id": 1595267,
          "author_name": "samfc10",
          "author_url": "",
          "post_date": "11/25/2021 14:47:36",
          "content": "<p>If you are using detectron2, modify these configs : </p>\n<pre><code>cfg.MODEL.RPN.BBOX_REG_LOSS_TYPE = \"ciou\"\ncfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_TYPE = \"ciou\"\n</code></pre>\n<p>By default, they are set to \"smooth_l1\" loss. I remember <a href=\"https://github.com/facebookresearch/detectron2/pull/3481\" target=\"_blank\">adding</a> these losses in detectron2 a few months ago, perfectly in time for the competition :)</p>",
          "votes": null,
          "replies": []
        },
        {
          "id": 1615677,
          "author_name": "zaopolearning",
          "author_url": "",
          "post_date": "12/12/2021 14:40:53",
          "content": "<p><a href=\"https://www.kaggle.com/jaideepvalani\" target=\"_blank\">@jaideepvalani</a>  have you improved after using it?</p>",
          "votes": null,
          "replies": []
        }
      ]
    },
    {
      "id": 1595271,
      "author_name": "samfc10",
      "author_url": "",
      "post_date": "11/25/2021 14:49:24",
      "content": "<p><a href=\"https://www.kaggle.com/gunesevitan\" target=\"_blank\">@gunesevitan</a> Try changing <code>cfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_WEIGHT</code> for better convergence. I've set it to 10</p>",
      "votes": null,
      "replies": [
        {
          "id": 1595522,
          "author_name": "gunesevitan",
          "author_url": "",
          "post_date": "11/25/2021 18:48:40",
          "content": "<p>Hello <a href=\"https://www.kaggle.com/samfc10\" target=\"_blank\">@samfc10</a>. I'm very lucky to run into you. Did you get better results with ciou loss compared to l1 loss?</p>",
          "votes": null,
          "replies": []
        },
        {
          "id": 1595832,
          "author_name": "samfc10",
          "author_url": "",
          "post_date": "11/26/2021 03:08:30",
          "content": "<p>I had tried both the losses very early in the competition. Didn't have my CV setup that time, these are the public LB scores for the submissions :</p>\n<pre><code>resnet50 new overlap method - 0.25\nresnet50 ciou new overlap - 0.258\n</code></pre>\n<p>3.2% improvement, seems consistent with the results reported in the paper.<br>\n<a href=\"https://ibb.co/DLH5ybz\" target=\"_blank\">https://ibb.co/DLH5ybz</a></p>",
          "votes": null,
          "replies": []
        }
      ]
    }
  ],
  "raw_markdown_by_id": {
    "1595201": "I read the papers below and decided to give a try to IoU-based loss functions for bounding box regression.\n\nhttps://giou.stanford.edu/GIoU.pdf\nhttps://arxiv.org/pdf/1911.08287.pdf\nhttps://arxiv.org/pdf/2005.03572.pdf\n\nMain motivation of proposing such loss functions is l1 and l2 losses are not strongly correlated with IoU. This problem is illustrated here.\n\n![l1](https://giou.stanford.edu/_nuxt/img/9369e27.jpg)\n\nIn papers, they obtained superior results in many benchmarks but it was the opposite in my case. I got slightly worse mAP and slow convergence. Does anyone see any improvement using them?",
    "1595238": "gunesevitan  where u modified for changes..",
    "1595267": "If you are using detectron2, modify these configs : \n```\ncfg.MODEL.RPN.BBOX_REG_LOSS_TYPE = \"ciou\"\ncfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_TYPE = \"ciou\"\n```\nBy default, they are set to \"smooth_l1\" loss. I remember [adding](https://github.com/facebookresearch/detectron2/pull/3481) these losses in detectron2 a few months ago, perfectly in time for the competition :)",
    "1595271": "gunesevitan Try changing `cfg.MODEL.ROI_BOX_HEAD.BBOX_REG_LOSS_WEIGHT` for better convergence. I've set it to 10",
    "1595522": "Hello @samfc10. I'm very lucky to run into you. Did you get better results with ciou loss compared to l1 loss?",
    "1595832": "I had tried both the losses very early in the competition. Didn't have my CV setup that time, these are the public LB scores for the submissions :\n```\nresnet50 new overlap method - 0.25\nresnet50 ciou new overlap - 0.258\n```\n3.2% improvement, seems consistent with the results reported in the paper.\nhttps://ibb.co/DLH5ybz",
    "1615677": "jaideepvalani  have you improved after using it?"
  },
  "source": "meta"
}