{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"What is Run-Length encoding(RLE)?
\nRun-length encoding (RLE) is a form of lossless data compression in which runs of data (sequences in which the same data value occurs in many consecutive data elements) are stored as a single data value and count, rather than as the original run.
\n\n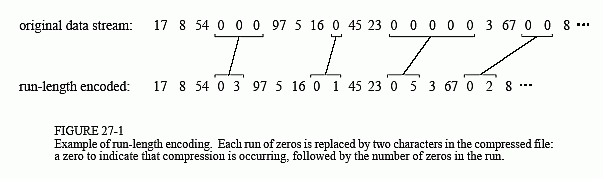 \n\n
Example
\nFor example, if the input string is “wwwwaaad”, then the function should return “w4a3d1”
Here w appears 4, a appears 3 times and d appears 1 time so we take each characters and then put their number of appearances after them
","metadata":{}},{"cell_type":"markdown","source":"Please don't forget to upvote
","metadata":{}},{"cell_type":"code","source":"import os\nimport cv2\nimport shutil\nimport numpy as np\nimport pandas as pd\nimport matplotlib.pyplot as plt\n\ntrain_fol = '../input/sartorius-cell-instance-segmentation/train'\ntest_fol = '../input/sartorius-cell-instance-segmentation/test'\ntrain = pd.read_csv('../input/sartorius-cell-instance-segmentation/train.csv')","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:06:31.945067Z","iopub.execute_input":"2021-10-20T10:06:31.945343Z","iopub.status.idle":"2021-10-20T10:06:32.314790Z","shell.execute_reply.started":"2021-10-20T10:06:31.945315Z","shell.execute_reply":"2021-10-20T10:06:32.313841Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#ref:https://www.kaggle.com/paulorzp/run-length-encode-and-decode.\ndef encode_mask_to_rle(mask):\n '''\n mask: numpy array binary mask \n 1 - mask \n 0 - background\n Returns encoded run length \n '''\n pixels = mask.flatten()\n pixels = np.concatenate([[0], pixels, [0]])\n runs = np.where(pixels[1:] != pixels[:-1])[0] + 1\n runs[1::2] -= runs[::2]\n return ' '.join(str(x) for x in runs)\n\nexample = np.array([1,1,1,1,0,0,0,1,0,1,1,0,0,0,1,1,1])\nrle_encoded = encode_mask_to_rle(example)\nprint(rle_encoded)","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:04:56.698982Z","iopub.execute_input":"2021-10-20T10:04:56.699261Z","iopub.status.idle":"2021-10-20T10:04:56.711847Z","shell.execute_reply.started":"2021-10-20T10:04:56.699221Z","shell.execute_reply":"2021-10-20T10:04:56.711109Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Here we encoded a example mask to run-length string. We tried to preserve the places of value 1.
\nSince it's a instance segmentation competition sothere is no class for segmented masks and all mask values will be 1 for stuff and 0 for background.\n
","metadata":{}},{"cell_type":"markdown","source":"Run-Length Decoding
\nIn this competition there are multiple rows for each image id and in each row there is a segmentation mask for each neuronal cell
","metadata":{}},{"cell_type":"code","source":"def decode_rle_to_mask(rle, height, width, viz=False):\n '''\n rle : run-length as string formated (start value, count)\n height : height of the mask \n width : width of the mask\n returns binary mask\n '''\n rle = np.array(rle.split(' ')).reshape(-1, 2)\n mask = np.zeros((height*width, 1, 3))\n if viz:\n color = np.random.rand(3)\n else:\n color = [1,1,1]\n for i in rle:\n mask[int(i[0]):int(i[0])+int(i[1]), :, :] = color\n\n return mask.reshape(height, width, 3)","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:04:56.713053Z","iopub.execute_input":"2021-10-20T10:04:56.713451Z","iopub.status.idle":"2021-10-20T10:04:56.721760Z","shell.execute_reply.started":"2021-10-20T10:04:56.713408Z","shell.execute_reply":"2021-10-20T10:04:56.720781Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Example
","metadata":{}},{"cell_type":"code","source":"example_id = '0030fd0e6378' # change the example id for different images\nimage = cv2.imread(os.path.join(train_fol, example_id)+'.png')\nimage = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)\nimage = (image-np.min(image))/(np.max(image)-np.min(image))\nprint(image.shape)\nprint(\"This is the image we are going to use, id:-\", example_id)\nplt.imshow(image)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:04:56.723866Z","iopub.execute_input":"2021-10-20T10:04:56.724129Z","iopub.status.idle":"2021-10-20T10:04:57.154842Z","shell.execute_reply.started":"2021-10-20T10:04:56.724090Z","shell.execute_reply":"2021-10-20T10:04:57.154113Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"lets try to convert one annotation to its respective mask
","metadata":{}},{"cell_type":"code","source":"example_annot = train[train.id==example_id].annotation.values[0]\nprint(\"The Annotation : \",example_annot)\nprint(\"Now let's convert it to mask and view it\")\nmask = decode_rle_to_mask(example_annot, image.shape[0], image.shape[1], viz=False)\nplt.imshow(mask)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:04:57.156048Z","iopub.execute_input":"2021-10-20T10:04:57.156662Z","iopub.status.idle":"2021-10-20T10:04:57.466206Z","shell.execute_reply.started":"2021-10-20T10:04:57.156606Z","shell.execute_reply":"2021-10-20T10:04:57.465150Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Lets try to do it on all the annotations of that id and then add them together!
","metadata":{}},{"cell_type":"code","source":"example_id_annotations = train[train.id==example_id].annotation.values\nmasks = np.zeros(image.shape)\nfor each_cell_annot in example_id_annotations:\n mask = decode_rle_to_mask(each_cell_annot, image.shape[0], image.shape[1], viz=True)\n masks+=mask\n\nplt.imshow(image)\nplt.show()\nplt.imshow(masks)\nplt.show()\nt = image+masks\nplt.imshow(t)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:04:57.467772Z","iopub.execute_input":"2021-10-20T10:04:57.468007Z","iopub.status.idle":"2021-10-20T10:04:59.607436Z","shell.execute_reply.started":"2021-10-20T10:04:57.467980Z","shell.execute_reply":"2021-10-20T10:04:59.606263Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Here we decoded run-length to mask and added them together to get a mask and applied it over the image
","metadata":{}},{"cell_type":"code","source":"example_id_annotations = train[train.id==example_id].annotation.values\nmasks = np.zeros(image.shape)\nfor each_cell_annot in example_id_annotations:\n mask = decode_rle_to_mask(each_cell_annot, image.shape[0], image.shape[1], viz=False)\n masks+=mask\n\nplt.imshow(image)\nplt.show()\nplt.imshow(masks)\nplt.show()\nt = image+masks\nplt.imshow(t)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:05:45.103586Z","iopub.execute_input":"2021-10-20T10:05:45.103884Z","iopub.status.idle":"2021-10-20T10:05:47.041437Z","shell.execute_reply.started":"2021-10-20T10:05:45.103854Z","shell.execute_reply":"2021-10-20T10:05:47.040622Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def show_img_mask(Id, motiv='train'):\n if motiv=='train':\n fol = train_fol\n if motiv=='test':\n fol = test_fol\n image = cv2.imread(os.path.join(fol, Id)+'.png')\n image = cv2.cvtColor(image, cv2.COLOR_BGR2RGB)\n image = (image-np.min(image))/(np.max(image)-np.min(image))\n print(\"Image id:-\", Id)\n plt.imshow(image)\n plt.show()\n example_id_annotations = train[train.id==example_id].annotation.values\n masks = np.zeros(image.shape)\n for each_cell_annot in example_id_annotations:\n mask = decode_rle_to_mask(each_cell_annot, image.shape[0], image.shape[1], viz=True)\n masks+=mask\n plt.imshow(masks)\n plt.show()","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:08:23.076550Z","iopub.execute_input":"2021-10-20T10:08:23.077359Z","iopub.status.idle":"2021-10-20T10:08:23.086097Z","shell.execute_reply.started":"2021-10-20T10:08:23.077319Z","shell.execute_reply":"2021-10-20T10:08:23.085001Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"show_img_mask('0030fd0e6378', motiv='train')","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:08:23.526778Z","iopub.execute_input":"2021-10-20T10:08:23.527561Z","iopub.status.idle":"2021-10-20T10:08:25.435200Z","shell.execute_reply.started":"2021-10-20T10:08:23.527520Z","shell.execute_reply":"2021-10-20T10:08:25.434203Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"show_img_mask('7ae19de7bc2a', motiv='test')","metadata":{"execution":{"iopub.status.busy":"2021-10-20T10:08:25.436799Z","iopub.execute_input":"2021-10-20T10:08:25.437047Z","iopub.status.idle":"2021-10-20T10:08:27.131109Z","shell.execute_reply.started":"2021-10-20T10:08:25.437019Z","shell.execute_reply":"2021-10-20T10:08:27.130215Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Hope You Liked it :D
","metadata":{}},{"cell_type":"code","source":"","metadata":{},"execution_count":null,"outputs":[]}]}