{"cells":[{"metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","trusted":true},"cell_type":"markdown","source":" \n\n
Riiid! Answer Correctness Prediction - EDA\n \n# 1. Introduction 🃏 \n\n\n"},{"metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","collapsed":true,"_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","trusted":false},"cell_type":"markdown","source":"In this competition, your challenge is to create algorithms for \"Knowledge Tracing,\" the modeling of student knowledge over time. The goal is to accurately predict how students will perform on future interactions. You will pair your machine learning skills using Riiid’s EdNet data.\n\n## 1.1 Metric: Area under the ROC curve\nSubmissions are evaluated on area under the ROC curve between the predicted probability and the observed target.\n\n- [Image link](http://arogozhnikov.github.io/2015/10/05/roc-curve.html)\n\n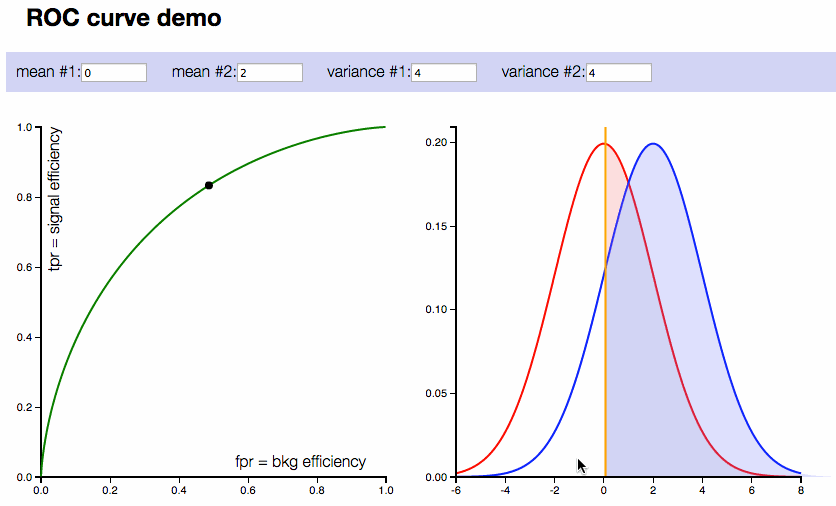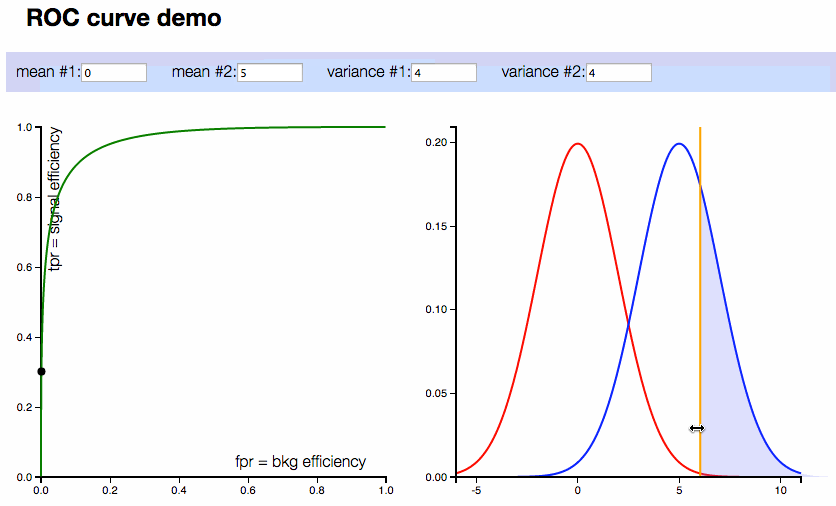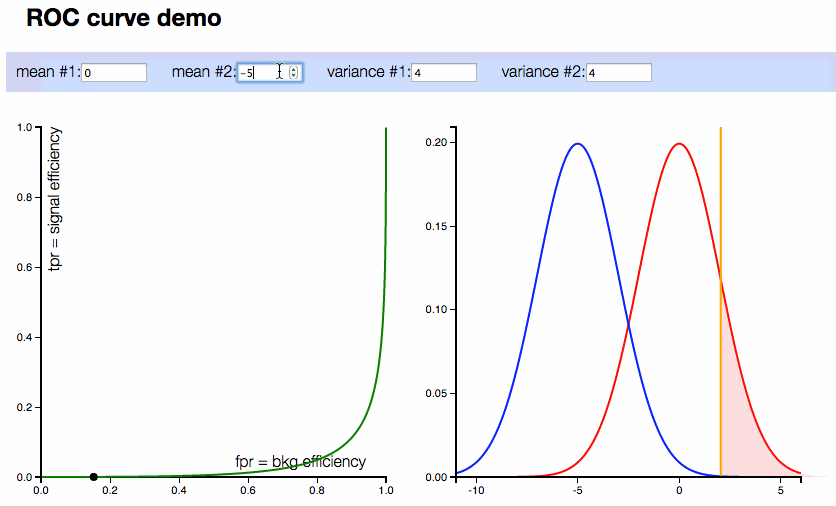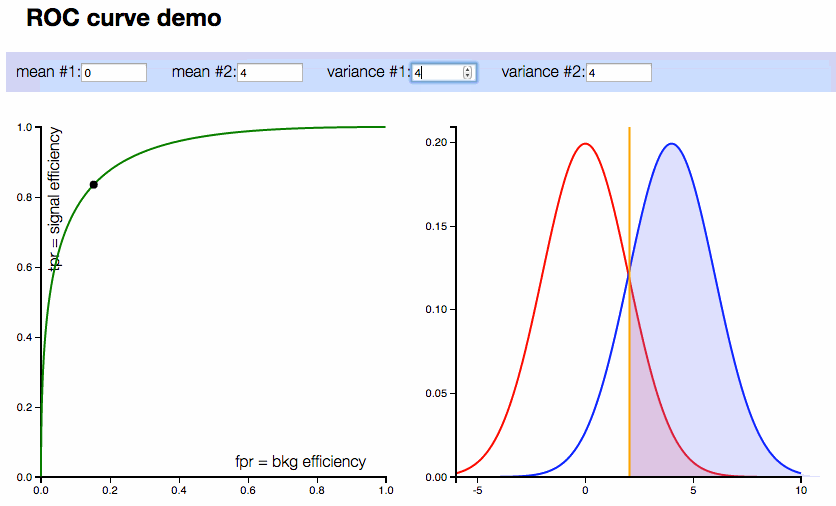 \n\n## 1.2. Important point\n\nThis is a time-series code competition, you will receive test set data and make predictions with Kaggle's time-series API. Please be sure to review the Time-series API Details section closely.\n\nyou will predict whether students are able to answer their next questions correctly."},{"metadata":{},"cell_type":"markdown","source":"please see basic kernels.\n- [Competition API Detailed Introduction](http://https://www.kaggle.com/sohier/competition-api-detailed-introduction)\n- [Quick Sample Submission](http://https://www.kaggle.com/sohier/quick-sample-submission)"},{"metadata":{},"cell_type":"markdown","source":"If you feel this was something new and fresh, and it added some value to you, \n# please consider upvoting, it motivates to keep writing good kernels. 😄"},{"metadata":{},"cell_type":"markdown","source":"## Contents \n\n\n\n* [Basic Exploratory Data Analysis](#1) \n * [Getting started - Importing libraries]()\n * [Reading the dataset]()\n \n \n* [Basic Data Exploration](#2) \n * [Check Train Info.]()\n * [Check Test Info.]()\n * [Check Metadata Info.]()\n\n* [Data Exploration in Details for Train DataFrame](#3) \n * [Distribution of columns]()\n * [Heatmap]()\n \n \n* [Pandas Profiling](#3) \n * [Pandas Profiling Report For Train Info.]()\n * [Pandas Profiling Report For Test Info.]()\n * [Pandas Profiling Report For Metadata Info.]()\n\n \n* [Etc. Sample Submission](#4)"},{"metadata":{},"cell_type":"markdown","source":"# 2. Importing the necessary libraries📗"},{"metadata":{"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true,"scrolled":false},"cell_type":"code","source":"# import libraries\nimport os\nimport pandas as pd\nimport numpy as np\n\nimport seaborn as sns\nimport matplotlib.pyplot as plt\n%matplotlib inline\n\n# datatable\n!pip install ../input/python-datatable/datatable-0.11.0-cp37-cp37m-manylinux2010_x86_64.whl\n\n#color\nfrom colorama import Fore, Back, Style\ny_ = Fore.YELLOW\nr_ = Fore.RED\ng_ = Fore.GREEN\nb_ = Fore.BLUE\nm_ = Fore.MAGENTA\nsr_ = Style.RESET_ALL\n\n#plotly\n#!pip install chart_studio\n!pip install ../input/chart-studio/chart_studio-1.0.0-py3-none-any.whl\nimport plotly.express as px\nimport chart_studio.plotly as py\nimport plotly.graph_objs as go\nfrom plotly.offline import iplot\nimport cufflinks\ncufflinks.go_offline()\ncufflinks.set_config_file(world_readable=True, theme='pearl')\n\n# Settings for pretty nice plots\nplt.style.use('fivethirtyeight')\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# 3. Reading the dataset 📚"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"# List files available\nprint(f'{y_}{list(os.listdir(\"../input/riiid-test-answer-prediction\"))}{r_}' )","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Train_df"},{"metadata":{},"cell_type":"markdown","source":"### Original Reading Train.csv"},{"metadata":{},"cell_type":"markdown","source":"It's larger than will fit in memory with default settings, so we'll specify more efficient datatypes and only load a subset of the data for now."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"%%time\n\ntrain_df = pd.read_csv('/kaggle/input/riiid-test-answer-prediction/train.csv', low_memory=False, nrows=10**5, \n dtype={'row_id': 'int64', 'timestamp': 'int64', 'user_id': 'int32', 'content_id': 'int16', 'content_type_id': 'int8',\n 'task_container_id': 'int16', 'user_answer': 'int8', 'answered_correctly': 'int8', 'prior_question_elapsed_time': 'float32', \n 'prior_question_had_explanation': 'boolean',\n }\n )\nprint(Fore.YELLOW + 'Training data shape: ',Style.RESET_ALL,train_df.shape)\ntrain_df","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"From this we can see that there are four continuous features: \n* `timestamp` which is the time between this user interaction and the first event from that user.\n* `content_id`: ID code for the user interaction \n* `task_container_id`: Id code for the batch of questions or lectures. \n* `prior_question_elapsed_time` which is how long it took a user to answer their previous question bundle.\n\nThere is one low cardinality integer feature:\n* `user_id`: the ID code for the user.\n\nThere are categorical features:\n* `user_answer`: the user's answer to the question, if any (read -1 as null), and answered_correctly if the user responded correctly (again, read -1 as null).\n\n* `content_type_id`: 0 if the event was a question being posed to the user, 1 if the event was the user watching a lecture"},{"metadata":{},"cell_type":"markdown","source":"### Reading Train data in jay format"},{"metadata":{},"cell_type":"markdown","source":"- https://www.kaggle.com/rohanrao/riiid-with-blazing-fast-rid/data?"},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"trusted":true,"scrolled":false},"cell_type":"code","source":"import gc\n\ndel train_df\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"%%time\n\n# reading the dataset from raw csv file\nimport datatable as dt\n\ndt.fread(\"../input/riiid-test-answer-prediction/train.csv\").to_jay(\"train.jay\")\n\ntrain_df = dt.fread(\"train.jay\").to_pandas()\n\nprint(Fore.YELLOW + 'Training data shape: ',Style.RESET_ALL,train_df.shape)\ntrain_df","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Test_df"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"import riiideducation\n\n# You can only call make_env() once, so don't lose it!\nenv = riiideducation.make_env()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"iter_test = env.iter_test()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"iteration = 0\ncount = 0\nfor (test_df, sample_prediction_df) in iter_test:\n test_df['answered_correctly'] = 0.5\n env.predict(test_df.loc[test_df['content_type_id'] == 0, ['row_id', 'answered_correctly']])\n print(f'{iteration} iteration !!!!')\n iteration += 1\n \n print(len(test_df))\n count += len(test_df)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"'''\nprint(Fore.YELLOW + 'Test data shape: ',Style.RESET_ALL,test_df.shape)\n\ntest_df.head()\n'''","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"print(f'{y_}Test data shape: {sr_}{test_df.shape}')\n\ntest_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"The format is largely the same as `train.csv`"},{"metadata":{},"cell_type":"markdown","source":"Some questions will appear in the hidden test set that have NOT been presented in the train set, emulating the challenge of quickly adapting to modeling newly introduced questions. Their metadata is still in question.csv as usual.\n - `prior_group_responses (string)`: all of the user_answer entries for previous group in a string representation of a list in the first row of the group. All other rows in each group are null. If you are using Python, you will likely want to call eval on the non-null rows. Some rows may be null, or empty lists.\n\n- `prior_group_answers_correct (string)` : all the answered_correctly field for previous group, with the same format and caveats as prior_group_responses. Some rows may be null, or empty lists."},{"metadata":{},"cell_type":"markdown","source":"There are two different rows that mirror what information the AI tutor actually has available at any given time, but with the user interactions grouped together for the sake of API performance rather than strictly showing information for a single user at a time. Some questions will appear in the hidden test set that have NOT been presented in the train set, emulating the challenge of quickly adapting to modeling newly introduced questions."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"count","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"`104` rows in Test_df\n* but, End of `row_id` number is `108`."},{"metadata":{},"cell_type":"markdown","source":"Let's see example_test.csv."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df = pd.read_csv('/kaggle/input/riiid-test-answer-prediction/example_test.csv')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df.iloc[[34, 35, 36]]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df.iloc[[51, 52, 53]]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df.iloc[[67, 68, 69]]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df.iloc[[78, 79, 80]]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"test_df.iloc[[80, 81, 82]]","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"Some `row_id`s are hidden.\n\n* `36`, `52`, `68`, `83`, `85`"},{"metadata":{},"cell_type":"markdown","source":"# Metadata - Questions.csv"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df = pd.read_csv('../input/riiid-test-answer-prediction/questions.csv')\n\nprint(f'{y_}Questions metadata shape: {sr_}{question_df.shape}')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"`question_id`: foreign key for the train/test content_id column, when the content type is question (0).\n\n`bundle_id`: code for which questions are served together.\n\n`correct_answer`: the answer to the question. Can be compared with the train user_answer column to check if the user was right.\n\n`part`: top level category code for the question.\n\n`tags`: one or more detailed tag codes for the question. The meaning of the tags will not be provided, but these codes are sufficient for clustering the questions together."},{"metadata":{},"cell_type":"markdown","source":"# Metadata - lectures.csv"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df = pd.read_csv('../input/riiid-test-answer-prediction/lectures.csv')\n\nprint(f'{y_}Lectures metadata shape: {sr_}{question_df.shape}')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"`lecture_id`: foreign key for the train/test content_id column, when the content type is lecture (1).\n\n`part`: top level category code for the lecture.\n\n`tag`: one tag codes for the lecture. The meaning of the tags will not be provided, but these codes are sufficient for clustering the lectures together.\n\n`type_of`: brief description of the core purpose of the lecture"},{"metadata":{},"cell_type":"markdown","source":"# 4. Basic Data Exploration 🏕️ "},{"metadata":{},"cell_type":"markdown","source":"### General Info"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"print(f'{y_}Train Set !!: {sr_}')\nprint(train_df.info())\nprint('-------------')\nprint(f'{y_}Question Set !!: {sr_}')\nprint(question_df.info())\nprint('-------------')\nprint(f'{y_}Lectures Set !!: {sr_}')\nprint(lectures_df.info())","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"print(f'Total row_id in Train set: {g_}{train_df[\"row_id\"].count()}{sr_}')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Missing Values"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df.isnull().sum()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.isnull().sum()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df.isnull().sum()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Unique User Id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"print(Fore.YELLOW + \"The total user ids are\",Style.RESET_ALL,f\"{train_df['user_id'].count()},\", Fore.BLUE + \"from those the unique ids are\", Style.RESET_ALL, f\"{train_df['user_id'].value_counts().shape[0]}.\")","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Value Counts"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['row_id'].value_counts().max()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['user_id'].value_counts().max()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['content_id'].value_counts().max()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['task_container_id'].value_counts().max()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# 5. Data Exploration in Details For Train Dataset 🎠 "},{"metadata":{},"cell_type":"markdown","source":"## Creating Individual User Id Dataframe for Train_df\nfor 349 unique user ids, we make new dataframe."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df = train_df[['user_id', 'row_id', 'timestamp', 'content_id', 'content_type_id', 'task_container_id', 'user_answer', 'answered_correctly', 'prior_question_elapsed_time', 'prior_question_had_explanation']].drop_duplicates()\ntrain_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Distribution of timestamp"},{"metadata":{},"cell_type":"markdown","source":"`timestamp`: the time between this user interaction and the first event from that user."},{"metadata":{"trusted":true,"scrolled":true},"cell_type":"code","source":"train_df['timestamp'].iplot(kind='hist',\n xTitle='timestamp', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the timestamp in the train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"https://www.kaggle.com/artgor/riiid-eda-feature-engineering-and-models"},{"metadata":{"trusted":true,"scrolled":true},"cell_type":"code","source":"train_df.groupby(['user_id'])['timestamp'].max().sort_values(ascending=False)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":true},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"user_id\", y=\"timestamp\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"We can see that some users have huge activity time."},{"metadata":{},"cell_type":"markdown","source":"### Distribution of content_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['content_id'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['content_id'].iplot(kind='hist',\n xTitle='content_id', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the content_id column in the Unique Train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"It need to check question.csv."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df.loc[train_df['content_id'] == 4120, 'user_answer'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.loc[question_df['question_id'] == 4120]","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Distribution content_id over Unique user_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"user_id\", y=\"content_id\", color='content_type_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"It means that `content_id` is low number, some users did not answer questions."},{"metadata":{},"cell_type":"markdown","source":"## Distribution of content_type_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['content_type_id'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['content_type_id'].value_counts().iplot(kind='bar',\n yTitle='Count', \n linecolor='black', \n opacity=0.7,\n color='blue',\n theme='pearl',\n bargap=0.8,\n gridcolor='white',\n title='Distribution of the Content_type_id column in Train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"`0` means some users not watched lectures because 0 if the event was a question being posed to the user."},{"metadata":{"trusted":true},"cell_type":"code","source":"# pull is given as a fraction of the pie radius\nfig = go.Figure(data=[go.Pie(labels=train_df['content_type_id'].value_counts().index, values=train_df['content_type_id'].value_counts(), pull=[0, 0.2])])\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"content_id\", y=\"user_id\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Distribution of task_container_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['task_container_id']","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['task_container_id'].iplot(kind='hist',\n xTitle='task_container_id', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the task_container_id in the train_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"task_container_id\", y=\"prior_question_elapsed_time\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"It is also need to check question.csv."},{"metadata":{},"cell_type":"markdown","source":"train_df.loc[train_df['content_id'] == 4120, 'user_answer'].value_counts()"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['task_container_id'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df.loc[train_df['task_container_id'] == 15, 'user_answer'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"`-1` means null for lectures."},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.loc[question_df['question_id'] == 15]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df.loc[train_df['task_container_id'] == 5283, 'user_answer'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.loc[question_df['question_id'] == 5283]","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Distribution of User_answer"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['user_answer'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['user_answer'].value_counts().iplot(kind='bar',\n yTitle='Count', \n linecolor='black', \n opacity=0.7,\n color='red',\n theme='pearl',\n bargap=0.8,\n gridcolor='white',\n title='Distribution of the user_answer column in Train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"- https://www.kaggle.com/dwchen/riiid-test-simpleeda-10m-data"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"ds = train_df['user_answer'].value_counts().reset_index()\nds.columns = ['user_answer', 'count']\nfig = px.pie(\n ds, \n values='count', \n names=\"user_answer\", \n title='user_answer bar chart', \n width=500, \n height=500\n)\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"user_answer\", y=\"content_type_id\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Answered_correctly Distribution of Unique user_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['answered_correctly'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['answered_correctly'].value_counts().iplot(kind='bar',\n yTitle='Count', \n linecolor='black', \n opacity=0.7,\n color='blue',\n theme='pearl',\n bargap=0.8,\n gridcolor='white',\n title='Distribution of the answered_correctly column in Train_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"plt.figure(figsize = (16,12))\n\na = sns.countplot(data=train_df, x='answered_correctly', hue='prior_question_had_explanation')\n\n\nfor p in a.patches:\n a.annotate(format(p.get_height(), ','), \n (p.get_x() + p.get_width() / 2., \n p.get_height()), ha = 'center', va = 'center', \n xytext = (0, 4), textcoords = 'offset points')\n\nplt.title('Answers result with and without explanations', fontsize=20)\nplt.xlabel('Answered_correctly', fontsize = 16)\nsns.despine(left=True, bottom=True);","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"plt.figure(figsize=(16,8))\nsns.countplot(train_df['user_answer'], hue=train_df['answered_correctly'],palette='Set1',**{'hatch':'-','linewidth':0.5})\nplt.title('User_Answer vs Correctness', fontsize = 20)\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"answered_correctly\", y=\"task_container_id\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Distribution of Prior_question_elapsed_time"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['prior_question_elapsed_time']","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['prior_question_elapsed_time'].iplot(kind='hist',\n xTitle='prior_question_elapsed_time', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the prior_question_elapsed_time column in the Unique Train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Content id vs prior_question_elapsed_time"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(train_df, x=\"content_id\", y=\"prior_question_elapsed_time\", color='user_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Prior_question_had_explanation Distribution of Unique user_id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['prior_question_had_explanation'].value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df['prior_question_had_explanation'].value_counts().iplot(kind='bar',\n yTitle='Count', \n linecolor='black', \n opacity=0.7,\n color='red',\n theme='pearl',\n bargap=0.8,\n gridcolor='white',\n title='Distribution of the prior_question_had_explanation column in Train_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Distribution of correct answers percentage by each user\n- https://www.kaggle.com/aykhanpy/riiid-answer-correctness-prediction-eda"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"temp_train = train_df.groupby('user_id').agg({'answered_correctly': 'sum', 'row_id':'count'})\nplt.figure(figsize = (16,8))\nsns.distplot((temp_train.answered_correctly * 100)/temp_train.row_id)\nplt.title('Distribution of correct answers percentage by each user', fontdict = {'size': 16})\nplt.xlabel('Percentage of correct answers', size = 12)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Heatmap for train_df"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"corrmat = train_df.corr() \nf, ax = plt.subplots(figsize =(9, 8)) \nsns.heatmap(corrmat, ax = ax, cmap = 'RdYlBu_r', linewidths = 0.5) ","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"Please compare with the previous visualization information. And we may compare to Pandas Profiling below."},{"metadata":{},"cell_type":"markdown","source":"# 6. Data Exploration in Details For Metadata-Question 🎠 "},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Bundle Id"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df['bundle_id'].iplot(kind='hist',\n xTitle='bundle_id', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the bundle_id in the question_df')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## correct_answer"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df['correct_answer'].iplot(kind='hist',\n xTitle='correct_answer', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#098060',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the correct_answer in the question_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(question_df, x=\"bundle_id\", y=\"correct_answer\", color='question_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"question_df['part'].iplot(kind='hist',\n xTitle='correct_answer', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the part in the question_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(question_df, x=\"correct_answer\", y=\"part\", color='part')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Heatmap for Question_df"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"corrmat = question_df.corr() \nf, ax = plt.subplots(figsize =(9, 8)) \nsns.heatmap(corrmat, ax = ax, cmap = 'RdYlBu_r', linewidths = 0.5) ","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# 7. Data Exploration in Details For Metadata-Lectures 🎠 "},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df['tag'].iplot(kind='hist',\n xTitle='tag', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the tag in the lectures_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df['part'].iplot(kind='hist',\n xTitle='part', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#098060',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the part in the lectures_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"lectures_df['type_of'].iplot(kind='hist',\n xTitle='part', \n yTitle='Counts',\n linecolor='black', \n opacity=0.7,\n color='#FB8072',\n theme='pearl',\n bargap=0.2,\n gridcolor='white',\n title='Distribution of the type_of in the lectures_df')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.scatter(lectures_df, x=\"type_of\", y=\"part\", color='lecture_id')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.bar(lectures_df, x='type_of', color=lectures_df['type_of'], labels={'value':'type_of'}, title='Type of lectures distribution Overall')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"https://www.kaggle.com/naim99/eda-riiid"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"fig = px.bar(lectures_df, x='type_of', color=lectures_df['type_of'], labels={'value':'type_of'}, title='Type of lectures distribution based on each part', facet_col='part')\nfig.show()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Heatmap for Lectures_df"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"corrmat = lectures_df.corr() \nf, ax = plt.subplots(figsize =(9, 8)) \nsns.heatmap(corrmat, ax = ax, cmap = 'RdYlBu_r', linewidths = 0.5) ","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# I'm working in progress."},{"metadata":{},"cell_type":"markdown","source":"# 8. Pandas Profiling "},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"import pandas_profiling as pdp","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"train_df = pd.read_csv('/kaggle/input/riiid-test-answer-prediction/train.csv', low_memory=False, nrows=10**5, \n dtype={'row_id': 'int64', 'timestamp': 'int64', 'user_id': 'int32', 'content_id': 'int16', 'content_type_id': 'int8',\n 'task_container_id': 'int16', 'user_answer': 'int8', 'answered_correctly': 'int8', 'prior_question_elapsed_time': 'float32', \n 'prior_question_had_explanation': 'boolean',\n }\n )\n\ntest_df = pd.read_csv('/kaggle/input/riiid-test-answer-prediction/example_test.csv')","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":true,"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_train_df = pdp.ProfileReport(train_df)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_train_df","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":true,"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_test_df = pdp.ProfileReport(test_df)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_test_df","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":true,"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_question_df = pdp.ProfileReport(question_df)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_question_df","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-output":true,"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_lectures_df = pdp.ProfileReport(lectures_df)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"profile_lectures_df","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# 7. Etc - Sample Submission"},{"metadata":{},"cell_type":"markdown","source":"- https://www.kaggle.com/sishihara/riiid-answered-correctly-benchmark"},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"content_acc = train_df.query('answered_correctly != -1').groupby('content_id')['answered_correctly'].mean().to_dict()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"scrolled":false},"cell_type":"code","source":"def add_content_acc(x):\n if x in content_acc.keys():\n return content_acc[x]\n else:\n return 0.5\n\n\nfor (test_df, sample_prediction_df) in iter_test:\n test_df['answered_correctly'] = test_df['content_id'].apply(add_content_acc).values\n env.predict(test_df.loc[test_df['content_type_id'] == 0, ['row_id', 'answered_correctly']])","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## If this kernel is useful, please upvote!\n- See you next time!"}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":4}