 \n* Backbone is pre-trained on ImageNet and first convolution is replaced with 6 input channel convolution\n* Neck: BN + FC + ReLU + BN + FC + BN\n* Head: FC
Thanks to Recursion and Kaggle for hosting such an interesting competition. It was really fun to participate.
\n\nUPDATE: source code is here: https://github.com/maciej-sypetkowski/kaggle-rcic-1st
\n\n\n* Backbone is pre-trained on ImageNet and first convolution is replaced with 6 input channel convolution\n* Neck: BN + FC + ReLU + BN + FC + BN\n* Head: FC
I found it important to not normalize input for the head, and that's the reason why the head and arc margin product are separate layers with different weights for fully connected layer (contrary to what bestfitting did in Human Protein Atlas Image Classification).
\n\nWith such configuration (training on all labeled part of the dataset -- no validation), I got 0.98997 private score and 0.95802 public score (single model).\nEnsembling it with models trained in the same or very similar way (most of them with train/val split 5:1) (3x DenseNet161, 2x DenseNet161 with mixup (instead of cutmix), 5x DenseNet201 also with mixup, 3x ResNeXt50 also with mixup) gave me 0.99540 private and 0.98262 public (between 3rd-4th place on private LB).
\n\nTo reach score of 0.997 private with single model I needed to add one more trick, which I would call:
\n\nIn all write-ups I've read so far, pseudo-labeling methods consist of iteratively training new model(s) and enlarging training set using them. In my method, small amount of most confident predictions is pseudo-labeled and added to the training set each epoch. Precisely, for each epoch:\n1. Predict all test and validation examples that weren't added to the training set yet (without TTA, only with combining over sites -- predicting with TTA could probably lead to a small improvement, but it would take more time to compute)\n2. For each prediction, mark as impossible:\n * control classes,\n * classes that can't be on the plate,\n * classes that are already assigned to any image for the plate in the training set.\n3. Select K most confident prediction (difference between greatest and second greatest class prediction)\n4. Add new examples to the training set. If at least two examples are on the same plate and have the same class pseudo-labeled, add to the training set only the most confident one (to preserve uniqueness of classes on the plate)
\n\nDuring class assignment, I use greedy-like approach instead of LSA. However, to generate final predictions, the same post-processing as earlier (without pseudo-labeling) is applied (and LSA there). Using LSA increases score because examples that were added later are more difficult and have smaller confidence (because network saw them fewer times, and learning rate was smaller (decreasing learning rate policy)).
\n\ngave me 0.99700 private and 0.99029 public, which already puts me on the 1st position.
\n\nEnsembling it with another model trained in the same way, but with train/val split 5:1, I got 0.99749 private and 0.99187 public. Adding one more model to the ensemble (also trained in the same way, but on the different split) gave me 0.99763 private and 0.99187 public, which matches my private score.
\n\nI noticed that around 120th epoch (30th epoch of pseudo-labeling -- 85% of test set already added) first pseudo-label misclassifications on validation set started to occur, hence I tried to fine-tune model even further (taking checkpoint from 120th epoch), starting with 80% of test set, and again incrementally adding new images for 30 epochs. And then again taking checkpoint 5 epochs before end, and starting from 95% for 20 epochs. However, by doing this I was able to classify correctly only one private example more (0.99707) and increase public score (i.e. probably only U2OS-04 experiment) to 0.99232.
\n\nMy final submission is an ensemble of 11 models (6x DenseNet161, 5x DenseNet201) (each of them with pseudo-labeling) with more TTA (also predicting on crop-resized images with scale 0.75 and 0.85), but it didn't give me any boost on the private test set (0.99763), but helped on the public test set (probably only on U2OS-04) (0.99480).
\n\nI want to share the approach I've tried, however it didn't give me any boost in the score, and I didn't use it in the final submission. But I think it's very valuable information, especially for the further research.\nMy idea was to instead of feeding to the head embedding only, feed also some information about any reference image from the same plate/experiment (e.g. its embedding and one-hot label).\nUsing only control images as a reference, would lead to overfitting. To tackle that problem, I used also non-control images as reference -- during training, control and non-control images are treated in the same way; during inference, only control images are used as reference (obviously, non-control images in the test set are not labeled).\nWe have 1139 classes per experiment (or 277 + 31 = 308 per plate), so the head would see each pair of classes after 1139 * 1139 = 1297321 images (once per 15 epochs) or 308 * 308 = 94864 (once per 1 epoch). To solve this, I ensure that in every batch there will be constant number of images from each of randomly chosen experiments/plates. For example, for batch size = 48, I can have 8(number of experiments/plates) x 6(number of images from given experiment/plate), and run the head on each pair among each experiment/plate in the batch. That gives 8 * 6 * 5 = 240 pairs in one batch (I forbid the image and the reference to be the same image), and doesn't increase training time (embedding of each image is calculated only once, and the head consists of few fully connected layers).
\n\nHowever, it didn't work any better than normal classification, and sometimes even worse. I tried to add or modify features for the head, for example:\n* concatenate difference between / multiplication of image and reference embedding,\n* concatenate corresponding vector from the arc margin product layer to the reference label,\n* normalize / not normalize embeddings,\n* detaching some of the features (not computing gradient through them).
\n\nI also tried:\n* add more layers to the head,\n* heavy-augment all images in a batch for the same experiment/plate in the same way -- all images in the batch belonging to the same experiment/plate would have the same brightness, contrast, gamma correction, the same scale applied, and so on -- the idea was to artificially simulate other cell types to direct model toward using references more effectively,\n* use mixup only within images from the same experiment/plate.
\n\nHowever, no luck.
\n\nWhat more, after training such model and feeding random noise as the reference, network still inferred very similar predictions with almost the same validation score (and not always worse). So, network didn't learn how to use the references properly.\nThat would imply that creating a model that performs well on different cell types (not seen during the training) using control images may be a very hard and challenging problem.
", "messages": [ { "id": 636168, "postDate": "2019-09-28T23:08:34.453Z", "content": "Thanks to Recursion and Kaggle for hosting such an interesting competition. It was really fun to participate.
\n\nUPDATE: source code is here: https://github.com/maciej-sypetkowski/kaggle-rcic-1st
\n\n\n* Backbone is pre-trained on ImageNet and first convolution is replaced with 6 input channel convolution\n* Neck: BN + FC + ReLU + BN + FC + BN\n* Head: FC
I found it important to not normalize input for the head, and that's the reason why the head and arc margin product are separate layers with different weights for fully connected layer (contrary to what bestfitting did in Human Protein Atlas Image Classification).
\n\nWith such configuration (training on all labeled part of the dataset -- no validation), I got 0.98997 private score and 0.95802 public score (single model).\nEnsembling it with models trained in the same or very similar way (most of them with train/val split 5:1) (3x DenseNet161, 2x DenseNet161 with mixup (instead of cutmix), 5x DenseNet201 also with mixup, 3x ResNeXt50 also with mixup) gave me 0.99540 private and 0.98262 public (between 3rd-4th place on private LB).
\n\nTo reach score of 0.997 private with single model I needed to add one more trick, which I would call:
\n\nIn all write-ups I've read so far, pseudo-labeling methods consist of iteratively training new model(s) and enlarging training set using them. In my method, small amount of most confident predictions is pseudo-labeled and added to the training set each epoch. Precisely, for each epoch:\n1. Predict all test and validation examples that weren't added to the training set yet (without TTA, only with combining over sites -- predicting with TTA could probably lead to a small improvement, but it would take more time to compute)\n2. For each prediction, mark as impossible:\n * control classes,\n * classes that can't be on the plate,\n * classes that are already assigned to any image for the plate in the training set.\n3. Select K most confident prediction (difference between greatest and second greatest class prediction)\n4. Add new examples to the training set. If at least two examples are on the same plate and have the same class pseudo-labeled, add to the training set only the most confident one (to preserve uniqueness of classes on the plate)
\n\nDuring class assignment, I use greedy-like approach instead of LSA. However, to generate final predictions, the same post-processing as earlier (without pseudo-labeling) is applied (and LSA there). Using LSA increases score because examples that were added later are more difficult and have smaller confidence (because network saw them fewer times, and learning rate was smaller (decreasing learning rate policy)).
\n\ngave me 0.99700 private and 0.99029 public, which already puts me on the 1st position.
\n\nEnsembling it with another model trained in the same way, but with train/val split 5:1, I got 0.99749 private and 0.99187 public. Adding one more model to the ensemble (also trained in the same way, but on the different split) gave me 0.99763 private and 0.99187 public, which matches my private score.
\n\nI noticed that around 120th epoch (30th epoch of pseudo-labeling -- 85% of test set already added) first pseudo-label misclassifications on validation set started to occur, hence I tried to fine-tune model even further (taking checkpoint from 120th epoch), starting with 80% of test set, and again incrementally adding new images for 30 epochs. And then again taking checkpoint 5 epochs before end, and starting from 95% for 20 epochs. However, by doing this I was able to classify correctly only one private example more (0.99707) and increase public score (i.e. probably only U2OS-04 experiment) to 0.99232.
\n\nMy final submission is an ensemble of 11 models (6x DenseNet161, 5x DenseNet201) (each of them with pseudo-labeling) with more TTA (also predicting on crop-resized images with scale 0.75 and 0.85), but it didn't give me any boost on the private test set (0.99763), but helped on the public test set (probably only on U2OS-04) (0.99480).
\n\nI want to share the approach I've tried, however it didn't give me any boost in the score, and I didn't use it in the final submission. But I think it's very valuable information, especially for the further research.\nMy idea was to instead of feeding to the head embedding only, feed also some information about any reference image from the same plate/experiment (e.g. its embedding and one-hot label).\nUsing only control images as a reference, would lead to overfitting. To tackle that problem, I used also non-control images as reference -- during training, control and non-control images are treated in the same way; during inference, only control images are used as reference (obviously, non-control images in the test set are not labeled).\nWe have 1139 classes per experiment (or 277 + 31 = 308 per plate), so the head would see each pair of classes after 1139 * 1139 = 1297321 images (once per 15 epochs) or 308 * 308 = 94864 (once per 1 epoch). To solve this, I ensure that in every batch there will be constant number of images from each of randomly chosen experiments/plates. For example, for batch size = 48, I can have 8(number of experiments/plates) x 6(number of images from given experiment/plate), and run the head on each pair among each experiment/plate in the batch. That gives 8 * 6 * 5 = 240 pairs in one batch (I forbid the image and the reference to be the same image), and doesn't increase training time (embedding of each image is calculated only once, and the head consists of few fully connected layers).
\n\nHowever, it didn't work any better than normal classification, and sometimes even worse. I tried to add or modify features for the head, for example:\n* concatenate difference between / multiplication of image and reference embedding,\n* concatenate corresponding vector from the arc margin product layer to the reference label,\n* normalize / not normalize embeddings,\n* detaching some of the features (not computing gradient through them).
\n\nI also tried:\n* add more layers to the head,\n* heavy-augment all images in a batch for the same experiment/plate in the same way -- all images in the batch belonging to the same experiment/plate would have the same brightness, contrast, gamma correction, the same scale applied, and so on -- the idea was to artificially simulate other cell types to direct model toward using references more effectively,\n* use mixup only within images from the same experiment/plate.
\n\nHowever, no luck.
\n\nWhat more, after training such model and feeding random noise as the reference, network still inferred very similar predictions with almost the same validation score (and not always worse). So, network didn't learn how to use the references properly.\nThat would imply that creating a model that performs well on different cell types (not seen during the training) using control images may be a very hard and challenging problem.
", "rawMarkdown": "Thanks to Recursion and Kaggle for hosting such an interesting competition. It was really fun to participate.\n\n**UPDATE: source code is here: [https://github.com/maciej-sypetkowski/kaggle-rcic-1st](https://github.com/maciej-sypetkowski/kaggle-rcic-1st)**\n\n## Data pre-processing & augmentation\n* Loading original images (512x512)\n* HUVEC-18 is moved to the training set (known leak)\n* For training, all control images (also these from the test set) are used in the same way as non-control images\n* Training augmentations\n * Random resized crop preserving aspect with scale ~ uniform(0.5, 1) using nearest-neighbor interpolation\n * Random horizontal and vertical flip, and 90 degrees rotation\n * Normalizing each image channel to N(0, 1)\n * For each channel: channel = channel * a + b, where a ~ N(1, 0.1), b ~ N(0, 0.1)\n* Test-time augmentations\n * Horizontal and vertical flip, and 90 degrees rotation\n\n## Model\n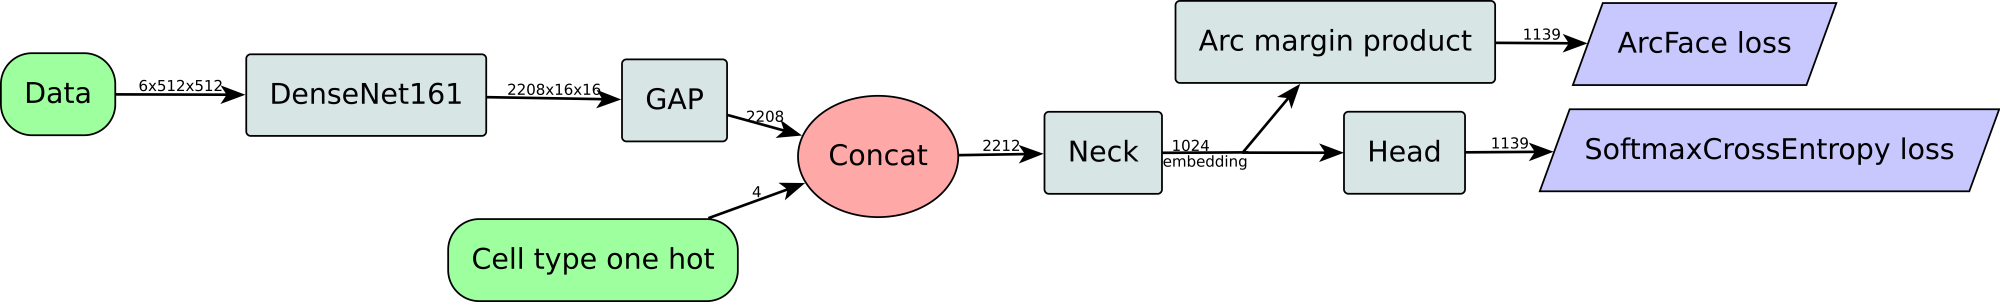\n* Backbone is pre-trained on ImageNet and first convolution is replaced with 6 input channel convolution\n* Neck: BN + FC + ReLU + BN + FC + BN\n* Head: FC\n\nI found it important to not normalize input for the head, and that's the reason why the head and arc margin product are separate layers with different weights for fully connected layer (contrary to [what bestfitting did in Human Protein Atlas Image Classification](https://www.kaggle.com/c/human-protein-atlas-image-classification/discussion/78109)).\n\n## Training\n* Batch size: 24 (48 with gradient accumulation)\n* Optimizer: Adam\n* Weight decay: 1e-5\n* [Cutmix](https://arxiv.org/abs/1905.04899)\n* Loss = ArcFaceLoss / 2 * 0.2 + SoftmaxCrossEntropyLoss * 0.8\n (ArcFaceLoss is divided by 2 to more or less preserve magnitude between losses)\n* 90 epochs\n* Learning rate: 1.5e-4 with cosine scheduling\n\n## Post-processing\n1. Predictions from different site images and different test-time augmentations are combined by taking mean of logits\n2. Predictions for control classes are ignored\n3. 831 classes that can't be on the given plate are marked as impossible\n4. Linear Sum Assignment (LSA) is applied\n\n\nWith such configuration (training on all labeled part of the dataset -- no validation), I got 0.98997 private score and 0.95802 public score (single model).\nEnsembling it with models trained in the same or very similar way (most of them with train/val split 5:1) (3x DenseNet161, 2x DenseNet161 with mixup (instead of cutmix), 5x DenseNet201 also with mixup, 3x ResNeXt50 also with mixup) gave me 0.99540 private and 0.98262 public (between 3rd-4th place on private LB).\n\n\nTo reach score of 0.997 private with single model I needed to add one more trick, which I would call:\n\n## Progressive pseudo-labeling\nIn all write-ups I've read so far, pseudo-labeling methods consist of iteratively training new model(s) and enlarging training set using them. In my method, small amount of most confident predictions is pseudo-labeled and added to the training set **each epoch**. Precisely, for each epoch:\n1. Predict all test and validation examples that weren't added to the training set yet (without TTA, only with combining over sites -- predicting with TTA could probably lead to a small improvement, but it would take more time to compute)\n2. For each prediction, mark as impossible:\n * control classes,\n * classes that can't be on the plate,\n * classes that are already assigned to any image for the plate in the training set.\n3. Select K most confident prediction (difference between greatest and second greatest class prediction)\n4. Add new examples to the training set. If at least two examples are on the same plate and have the same class pseudo-labeled, add to the training set only the most confident one (to preserve uniqueness of classes on the plate)\n\nDuring class assignment, I use greedy-like approach instead of LSA. However, to generate final predictions, the same post-processing as earlier (without pseudo-labeling) is applied (and LSA there). Using LSA increases score because examples that were added later are more difficult and have smaller confidence (because network saw them fewer times, and learning rate was smaller (decreasing learning rate policy)).\n\n## Training previous single model further\n* for additional 40 epochs,\n* pseudo-labeling 40% of the test set at the start, and then adding 1.5% each epoch,\n* cosine learning rate schedule with initial learning rate = 6e-5 scheduled for 60 epochs (i.e. at the end of training it is 1.5e-5),\n\ngave me 0.99700 private and 0.99029 public, which already puts me on the 1st position.\n\nEnsembling it with another model trained in the same way, but with train/val split 5:1, I got 0.99749 private and 0.99187 public. Adding one more model to the ensemble (also trained in the same way, but on the different split) gave me 0.99763 private and 0.99187 public, which matches my private score.\n\nI noticed that around 120th epoch (30th epoch of pseudo-labeling -- 85% of test set already added) first pseudo-label misclassifications on validation set started to occur, hence I tried to fine-tune model even further (taking checkpoint from 120th epoch), starting with 80% of test set, and again incrementally adding new images for 30 epochs. And then again taking checkpoint 5 epochs before end, and starting from 95% for 20 epochs. However, by doing this I was able to classify correctly only one private example more (0.99707) and increase public score (i.e. probably only U2OS-04 experiment) to 0.99232.\n\nMy final submission is an ensemble of 11 models (6x DenseNet161, 5x DenseNet201) (each of them with pseudo-labeling) with more TTA (also predicting on crop-resized images with scale 0.75 and 0.85), but it didn't give me any boost on the private test set (0.99763), but helped on the public test set (probably only on U2OS-04) (0.99480).\n\n\n\n## Other insights\n* Mixup performs a little better than cutmix on the part without pseudo-labeling, but it converges slower. On the contrary, with pseudo-labeling, cutmix was a little better (probably because of faster convergence)\n* Larger architecture is better: DenseNet121 < DenseNet169 < DenseNet201 < DenseNet161 -- for people without knowledge about DenseNets: DenseNet161 has less layers but more parameters than DenseNet201\n* EfficientNets and ResNeXts didn't work for me\n\n\n## Attempt to use control images in a smarter way\nI want to share the approach I've tried, however it didn't give me any boost in the score, and I didn't use it in the final submission. But I think it's very valuable information, especially for the further research.\nMy idea was to instead of feeding to the head embedding only, feed also some information about any reference image from the same plate/experiment (e.g. its embedding and one-hot label).\nUsing only control images as a reference, would lead to overfitting. To tackle that problem, I used also non-control images as reference -- during training, control and non-control images are treated in the same way; during inference, only control images are used as reference (obviously, non-control images in the test set are not labeled).\nWe have 1139 classes per experiment (or 277 + 31 = 308 per plate), so the head would see each pair of classes after 1139 * 1139 = 1297321 images (once per 15 epochs) or 308 * 308 = 94864 (once per 1 epoch). To solve this, I ensure that in every batch there will be constant number of images from each of randomly chosen experiments/plates. For example, for batch size = 48, I can have 8(number of experiments/plates) x 6(number of images from given experiment/plate), and run the head on each pair among each experiment/plate in the batch. That gives 8 * 6 * 5 = 240 pairs in one batch (I forbid the image and the reference to be the same image), and doesn't increase training time (embedding of each image is calculated only once, and the head consists of few fully connected layers).\n\nHowever, it didn't work any better than normal classification, and sometimes even worse. I tried to add or modify features for the head, for example:\n* concatenate difference between / multiplication of image and reference embedding,\n* concatenate corresponding vector from the arc margin product layer to the reference label,\n* normalize / not normalize embeddings,\n* detaching some of the features (not computing gradient through them).\n\nI also tried:\n* add more layers to the head,\n* heavy-augment all images in a batch for the same experiment/plate in the same way -- all images in the batch belonging to the same experiment/plate would have the same brightness, contrast, gamma correction, the same scale applied, and so on -- the idea was to artificially simulate other cell types to direct model toward using references more effectively,\n* use mixup only within images from the same experiment/plate.\n\nHowever, no luck.\n\nWhat more, after training such model and feeding random noise as the reference, network still inferred very similar predictions with almost the same validation score (and not always worse). So, network didn't learn how to use the references properly.\nThat would imply that creating a model that performs well on different cell types (not seen during the training) using control images may be a very hard and challenging problem.", "votes": 129 }, { "id": 752020, "postDate": "2020-02-20T17:50:05.120Z", "content": "Great
", "rawMarkdown": "Great", "votes": 13 }, { "id": 636297, "postDate": "2019-09-29T08:03:18.397Z", "content": "Congrats with the first place, very inspiring! You did a very solid work, but besides that, what do you think is the magic feature that gave you the lead? After reading your solution I can identify the following as more or less unique, - using mixup, adding randomness on normalization, progressive PL, training for relatively long time, using 5:1 split is higher than usual, using gamma=0.2 from bestfitting, adding zoom transform (I didn't remember anyone using zooming). What from your experience was the one that gave you the edge?
\n\nAdditionally, what hardware and frameworks have you used?
", "rawMarkdown": "Congrats with the first place, very inspiring! You did a very solid work, but besides that, what do you think is the magic feature that gave you the lead? After reading your solution I can identify the following as more or less unique, - using mixup, adding randomness on normalization, progressive PL, training for relatively long time, using 5:1 split is higher than usual, using gamma=0.2 [from bestfitting](https://www.kaggle.com/c/human-protein-atlas-image-classification/discussion/78109), adding zoom transform (I didn't remember anyone using zooming). What from your experience was the one that gave you the edge?\n\nAdditionally, what hardware and frameworks have you used?", "votes": 5, "replies": [ { "id": 636393, "postDate": "2019-09-29T12:50:27.397Z", "content": "To sum up, I think that advantage over others may be because of:\n1. zoom augmentation,\n2. cutmix / long training time, \n3. arc margin product / head approach, or\n4. concatenating cell type to the neck input.
\n\nI used 2x Titan V, PyTorch, and trained in mixed precision
", "rawMarkdown": "* zoom transform -- I observed significant boost in score when I introduced it, because back then I used only flips + 90 deg rotation, and didn't use mixup nor cutmix (it overfitted to the training set very fast). I don't know what difference it makes with mixup/cutmix\n* mixup, cutmix -- significant boost in score. Few teams stated that mixup didn't work for them -- probably they trained for too few epochs (mixup requires much more epochs to converge)\n* relatively long training time -- I suspect that for mixup it was a necessity, but for cutmix I could reduce training epochs maybe by ~30% (I didn't verify it)\n* randomness on normalization -- I think it didn't change anything at the end, as I didn't observe any change in score on local validation. I used it out of sentiment because it helped me realize that normalization over channels helps a lot\n* 5:1 split -- That was a stupid choice. Actually, I've never train full CV for any configuration. There were too many ideas to test, and larger models took much more time then I expected (more than 1 GPU hour per epoch). However, looking at validation results I had, and confidence on validation and test set, I estimated that I would have ~0.998 private which is not very distant from how I scored\n* progressive PL -- I don't think that was a key for the success. Without any PL I have very good public-private score ratio. For example:\n * single model 90 epochs: 0.98997 private (13 teams above it) and 0.95802 public (20 teams above it)\n * 2 model ensemble 90 epochs: 0.99199 private (11 teams) and 0.96795 public (15 teams)\n * ensemble of 90 epochs models: 0.99540 private (3 teams) and 0.98262 public (8 teams)\n* metric loss -- I used different approach than bestfitting's solution with gamma=0.2 (and also many gold solutions from this competition). The difference between my and bestfitting's solution is that bestfitting instead of using 2 layers (head and arc margin product) used only arc margin product. Difference between arc margin product and my head is that arc margin product normalizes embedding and my head doesn't -- it gave me better results when I had ~0.8 public score\n* What is also unique to other solutions, is concatenating cell type one hot to the GAP output -- after using this, fine-tuning model for each cell type stopped giving me any boost in the score (but I introduced it when I had ~0.6 public score IIRC)\n\nTo sum up, I think that advantage over others may be because of:\n1. zoom augmentation,\n2. cutmix / long training time, \n3. arc margin product / head approach, or\n4. concatenating cell type to the neck input.\n\nI used 2x Titan V, PyTorch, and trained in mixed precision", "votes": 9 } ] }, { "id": 750192, "postDate": "2020-02-19T07:24:32.547Z", "content": "Amazing work tq u for sharing your hardwork!
", "rawMarkdown": "Amazing work tq u for sharing your hardwork!", "votes": 3 }, { "id": 725193, "postDate": "2020-01-21T22:32:34.583Z", "content": "Hi @maciejsypetkowski ,\ncongrats on your victory!\nHowever I'm interested in the training performance of Your machine (\"more than 1 GPU hour per epoch\", \"I used 2x Titan V, PyTorch, and trained in mixed precision\" - So I assume it took 30 minutes per epoch for You.)\nYour computer seems stronger than mine (I have 2xRadeon7) but Your training time seems like 50-100% to long (I have a similar NN model and training of 1 epoch takes ~15-20 minuts in mixed_fp16 in TF with both GPUs).\nI was wondering if You didn't encounter some other bottlenecks like image reading/preprocessing. Did You check if the training time scales with the additional GPU (on top of the first one)? Did You check your CPU usage (if it's <100%)?
", "rawMarkdown": "Hi @maciejsypetkowski ,\ncongrats on your victory!\nHowever I'm interested in the training performance of Your machine (\"more than 1 GPU hour per epoch\", \"I used 2x Titan V, PyTorch, and trained in mixed precision\" - So I assume it took 30 minutes per epoch for You.)\nYour computer seems stronger than mine (I have 2xRadeon7) but Your training time seems like 50-100% to long (I have a similar NN model and training of 1 epoch takes ~15-20 minuts in mixed_fp16 in TF with both GPUs).\nI was wondering if You didn't encounter some other bottlenecks like image reading/preprocessing. Did You check if the training time scales with the additional GPU (on top of the first one)? Did You check your CPU usage (if it's <100%)?", "votes": 3, "replies": [ { "id": 726074, "postDate": "2020-01-22T19:27:29.030Z", "content": "I've looked at the logs again, and it seems like \"1 GPU hour per epoch\" is not entirely true (my bad...). I think I accidentally took the last epoch where training were performed on entire training + test set (pseudo-labeling), and then it took 1 hour. The described schedule (130 epoch) took 98 hours, where the first epoch (no pseudo-labeling) took 40 minutes.
\n\nI trained one job on one GPU, 2 jobs in parallel, so I didn't check how it scales on 2 GPUs.
\n\nThere may be few other things you're not considering:\n* Training is performed on entire training set together with HUVEC-18 (no validation)\n* Inferring remaining part of the test set while pseudo-labeling every epoch\n* Training on larger and larger set (pseudo-labeling)\n* Using deterministic CUDA kernels (to ensure reproducibility) which are slower\n* Memory-efficient implementation of DenseNet, which is slower but allows to train with larger batches.\n* PyTorch supports only NCHW tensor layout, but fastest FP16 CUDA convolution kernels takes NHWC input. If I'm not mistaken, in PyTorch, it is done by transposing the tensor before and after calling each FP16 convolution kernel. But we can hope it will be improved someday as part of torch.jit
I'm almost 100% sure I wasn't bottleneck on I/O and CPU.
\n\nTo give you more comparable performance metrics:\n* training speed -- 37 img/sec\n* inference speed (w/o TTA) -- 123 img/sec
", "rawMarkdown": "I've looked at the logs again, and it seems like \"1 GPU hour per epoch\" is not entirely true (my bad...). I think I accidentally took the last epoch where training were performed on entire training + test set (pseudo-labeling), and then it took 1 hour. The described schedule (130 epoch) took 98 hours, where the first epoch (no pseudo-labeling) took 40 minutes.\n\nI trained one job on one GPU, 2 jobs in parallel, so I didn't check how it scales on 2 GPUs.\n\nThere may be few other things you're not considering:\n* Training is performed on entire training set together with HUVEC-18 (no validation)\n* Inferring remaining part of the test set while pseudo-labeling every epoch\n* Training on larger and larger set (pseudo-labeling)\n* Using deterministic CUDA kernels (to ensure reproducibility) which are slower\n* Memory-efficient implementation of DenseNet, which is slower but allows to train with larger batches.\n* PyTorch supports only NCHW tensor layout, but fastest FP16 CUDA convolution kernels takes NHWC input. If I'm not mistaken, in PyTorch, it is done by transposing the tensor before and after calling each FP16 convolution kernel. But we can hope it will be improved someday as part of `torch.jit`\n\nI'm almost 100% sure I wasn't bottleneck on I/O and CPU. \n\nTo give you more comparable performance metrics:\n* training speed -- 37 img/sec\n* inference speed (w/o TTA) -- 123 img/sec", "votes": 1 }, { "id": 726142, "postDate": "2020-01-22T21:07:34.190Z", "content": "ok, thanks :)
", "rawMarkdown": "ok, thanks :)" } ] }, { "id": 647286, "postDate": "2019-10-12T11:26:52.177Z", "content": "Thank you very much for sharing your code. Your code looks very compact and clean!
\n\nI have some questions about how you approach such a project/competition:\nDo you write everything from scratch or do you reuse code you have written before?\nDo you have a special approach for testing?\nDo you know the LB score of your approach without progressive pseudo-labeling?\nDo you have some general (not so obvious) tipps for beginners?
\n\nThank you very much & keep up the great work! :-D
", "rawMarkdown": "Thank you very much for sharing your code. Your code looks very compact and clean!\n\nI have some questions about how you approach such a project/competition:\nDo you write everything from scratch or do you reuse code you have written before?\nDo you have a special approach for testing?\nDo you know the LB score of your approach without progressive pseudo-labeling?\nDo you have some general (not so obvious) tipps for beginners?\n\nThank you very much & keep up the great work! :-D", "votes": 1, "replies": [ { "id": 648051, "postDate": "2019-10-13T17:12:15.543Z", "content": "congrats!
", "rawMarkdown": "congrats!", "votes": 1 }, { "id": 636223, "postDate": "2019-09-29T03:56:05.210Z", "content": "congrats , very well written
", "rawMarkdown": "congrats , very well written ", "votes": 1 }, { "id": 814362, "postDate": "2020-04-20T15:53:51.137Z", "content": "Congrats on the 1st place!\nWhat's the reasoning for not using bias in the linear layers of the neck?\nhttps://github.com/maciej-sypetkowski/kaggle-rcic-1st/blob/master/model.py#L57
", "rawMarkdown": "Congrats on the 1st place!\nWhat's the reasoning for not using bias in the linear layers of the neck?\nhttps://github.com/maciej-sypetkowski/kaggle-rcic-1st/blob/master/model.py#L57", "replies": [ { "id": 820532, "postDate": "2020-04-25T14:13:23Z", "content": "Good catch! For the first linear layer there's no reason for it, just a typo. Probably it doesn't matter because it's the only such place in the entire model. For the second linear layer -- it's directly before the batch norm which would remove the bias.
", "rawMarkdown": "Good catch! For the first linear layer there's no reason for it, just a typo. Probably it doesn't matter because it's the only such place in the entire model. For the second linear layer -- it's directly before the batch norm which would remove the bias." } ] }, { "id": 772188, "postDate": "2020-03-15T06:16:40.227Z", "content": "Great insights and kudos for amazing work!
", "rawMarkdown": "Great insights and kudos for amazing work!" }, { "id": 752290, "postDate": "2020-02-20T20:52:28.193Z", "content": "Good
", "rawMarkdown": "Good " }, { "id": 752286, "postDate": "2020-02-20T20:46:19.307Z", "content": "good
", "rawMarkdown": "good" }, { "id": 719324, "postDate": "2020-01-15T11:30:01.843Z", "content": "Great work!!!\nThanks for sharing your code
", "rawMarkdown": "Great work!!!\nThanks for sharing your code" }, { "id": 644362, "postDate": "2019-10-08T17:25:12.340Z", "content": ":) !!!
", "rawMarkdown": ":) !!!" }, { "id": 642997, "postDate": "2019-10-06T23:02:41.290Z", "content": "Congrats!
", "rawMarkdown": "Congrats!" }, { "id": 637163, "postDate": "2019-09-30T17:59:32.850Z", "content": "Really well written
", "rawMarkdown": "Really well written" }, { "id": 637104, "postDate": "2019-09-30T16:57:40.200Z", "content": "Hard and worthy work.
", "rawMarkdown": "Hard and worthy work." }, { "id": 636674, "postDate": "2019-09-30T02:54:23.603Z", "content": "Great work!
", "rawMarkdown": "Great work!" }, { "id": 794390, "postDate": "2020-04-01T19:14:03.827Z", "rawMarkdown": "", "isDeleted": true, "replies": [ { "id": 794495, "postDate": "2020-04-01T21:19:32.020Z", "content": "Global Average Pooling
", "rawMarkdown": "Global Average Pooling" } ] }, { "id": 636214, "postDate": "2019-09-29T03:32:45.443Z", "rawMarkdown": "", "isDeleted": true }, { "id": 636738, "postDate": "2019-09-30T06:01:48.340Z", "content": "great write-up. Thank you for sharing.
", "rawMarkdown": "great write-up. Thank you for sharing. ", "votes": 3 }, { "id": 637352, "postDate": "2019-10-01T00:54:56.243Z", "content": "Awesome. Thank you for sharing.
", "rawMarkdown": "Awesome. Thank you for sharing." } ], "comments": [ { "id": 752020, "author_name": "", "author_url": "", "post_date": "2020-02-20T17:50:05.120000", "content": "Great
", "votes": 13, "replies": [] }, { "id": 636297, "author_name": "nosound", "author_url": "", "post_date": "2019-09-29T08:03:18.397000", "content": "Congrats with the first place, very inspiring! You did a very solid work, but besides that, what do you think is the magic feature that gave you the lead? After reading your solution I can identify the following as more or less unique, - using mixup, adding randomness on normalization, progressive PL, training for relatively long time, using 5:1 split is higher than usual, using gamma=0.2 from bestfitting, adding zoom transform (I didn't remember anyone using zooming). What from your experience was the one that gave you the edge?
\n\nAdditionally, what hardware and frameworks have you used?
", "votes": 5, "replies": [ { "id": 636393, "author_name": "Maciej Sypetkowski", "author_url": "", "post_date": "2019-09-29T12:50:27.397000", "content": "To sum up, I think that advantage over others may be because of:\n1. zoom augmentation,\n2. cutmix / long training time, \n3. arc margin product / head approach, or\n4. concatenating cell type to the neck input.
\n\nI used 2x Titan V, PyTorch, and trained in mixed precision
", "votes": 9, "replies": [] } ] }, { "id": 750192, "author_name": "", "author_url": "", "post_date": "2020-02-19T07:24:32.547000", "content": "Amazing work tq u for sharing your hardwork!
", "votes": 3, "replies": [] }, { "id": 725193, "author_name": "Witold Oleksiewicz", "author_url": "", "post_date": "2020-01-21T22:32:34.583000", "content": "Hi @maciejsypetkowski ,\ncongrats on your victory!\nHowever I'm interested in the training performance of Your machine (\"more than 1 GPU hour per epoch\", \"I used 2x Titan V, PyTorch, and trained in mixed precision\" - So I assume it took 30 minutes per epoch for You.)\nYour computer seems stronger than mine (I have 2xRadeon7) but Your training time seems like 50-100% to long (I have a similar NN model and training of 1 epoch takes ~15-20 minuts in mixed_fp16 in TF with both GPUs).\nI was wondering if You didn't encounter some other bottlenecks like image reading/preprocessing. Did You check if the training time scales with the additional GPU (on top of the first one)? Did You check your CPU usage (if it's <100%)?
", "votes": 3, "replies": [ { "id": 726074, "author_name": "Maciej Sypetkowski", "author_url": "", "post_date": "2020-01-22T19:27:29.030000", "content": "I've looked at the logs again, and it seems like \"1 GPU hour per epoch\" is not entirely true (my bad...). I think I accidentally took the last epoch where training were performed on entire training + test set (pseudo-labeling), and then it took 1 hour. The described schedule (130 epoch) took 98 hours, where the first epoch (no pseudo-labeling) took 40 minutes.
\n\nI trained one job on one GPU, 2 jobs in parallel, so I didn't check how it scales on 2 GPUs.
\n\nThere may be few other things you're not considering:\n* Training is performed on entire training set together with HUVEC-18 (no validation)\n* Inferring remaining part of the test set while pseudo-labeling every epoch\n* Training on larger and larger set (pseudo-labeling)\n* Using deterministic CUDA kernels (to ensure reproducibility) which are slower\n* Memory-efficient implementation of DenseNet, which is slower but allows to train with larger batches.\n* PyTorch supports only NCHW tensor layout, but fastest FP16 CUDA convolution kernels takes NHWC input. If I'm not mistaken, in PyTorch, it is done by transposing the tensor before and after calling each FP16 convolution kernel. But we can hope it will be improved someday as part of torch.jit
I'm almost 100% sure I wasn't bottleneck on I/O and CPU.
\n\nTo give you more comparable performance metrics:\n* training speed -- 37 img/sec\n* inference speed (w/o TTA) -- 123 img/sec
", "votes": 1, "replies": [] }, { "id": 726142, "author_name": "Witold Oleksiewicz", "author_url": "", "post_date": "2020-01-22T21:07:34.190000", "content": "ok, thanks :)
", "votes": 0, "replies": [] } ] }, { "id": 647286, "author_name": "Michael Pieler", "author_url": "", "post_date": "2019-10-12T11:26:52.177000", "content": "Thank you very much for sharing your code. Your code looks very compact and clean!
\n\nI have some questions about how you approach such a project/competition:\nDo you write everything from scratch or do you reuse code you have written before?\nDo you have a special approach for testing?\nDo you know the LB score of your approach without progressive pseudo-labeling?\nDo you have some general (not so obvious) tipps for beginners?
\n\nThank you very much & keep up the great work! :-D
", "votes": 1, "replies": [ { "id": 648051, "author_name": "Maciej Sypetkowski", "author_url": "", "post_date": "2019-10-13T17:12:15.543000", "content": "congrats!
", "votes": 1, "replies": [] }, { "id": 636223, "author_name": "santosh Bammidi", "author_url": "", "post_date": "2019-09-29T03:56:05.210000", "content": "congrats , very well written
", "votes": 1, "replies": [] }, { "id": 814362, "author_name": "Bernhard Schäfer", "author_url": "", "post_date": "2020-04-20T15:53:51.137000", "content": "Congrats on the 1st place!\nWhat's the reasoning for not using bias in the linear layers of the neck?\nhttps://github.com/maciej-sypetkowski/kaggle-rcic-1st/blob/master/model.py#L57
", "votes": 0, "replies": [ { "id": 820532, "author_name": "Maciej Sypetkowski", "author_url": "", "post_date": "2020-04-25T14:13:23", "content": "Good catch! For the first linear layer there's no reason for it, just a typo. Probably it doesn't matter because it's the only such place in the entire model. For the second linear layer -- it's directly before the batch norm which would remove the bias.
", "votes": 0, "replies": [] } ] }, { "id": 772188, "author_name": "Varun Yadav", "author_url": "", "post_date": "2020-03-15T06:16:40.227000", "content": "Great insights and kudos for amazing work!
", "votes": 0, "replies": [] }, { "id": 752290, "author_name": "", "author_url": "", "post_date": "2020-02-20T20:52:28.193000", "content": "Good
", "votes": 0, "replies": [] }, { "id": 752286, "author_name": "", "author_url": "", "post_date": "2020-02-20T20:46:19.307000", "content": "good
", "votes": 0, "replies": [] }, { "id": 719324, "author_name": "Manish Nayak", "author_url": "", "post_date": "2020-01-15T11:30:01.843000", "content": "Great work!!!\nThanks for sharing your code
", "votes": 0, "replies": [] }, { "id": 644362, "author_name": "Hadjallah Abdallah", "author_url": "", "post_date": "2019-10-08T17:25:12.340000", "content": ":) !!!
", "votes": 0, "replies": [] }, { "id": 642997, "author_name": "corochann", "author_url": "", "post_date": "2019-10-06T23:02:41.290000", "content": "Congrats!
", "votes": 0, "replies": [] }, { "id": 637163, "author_name": "David A", "author_url": "", "post_date": "2019-09-30T17:59:32.850000", "content": "Really well written
", "votes": 0, "replies": [] }, { "id": 637104, "author_name": "Marília Prata", "author_url": "", "post_date": "2019-09-30T16:57:40.200000", "content": "Hard and worthy work.
", "votes": 0, "replies": [] }, { "id": 636674, "author_name": "SAS", "author_url": "", "post_date": "2019-09-30T02:54:23.603000", "content": "Great work!
", "votes": 0, "replies": [] }, { "id": 794390, "author_name": "", "author_url": "", "post_date": "2020-04-01T19:14:03.827000", "content": "", "votes": 0, "replies": [ { "id": 794495, "author_name": "Dieter", "author_url": "", "post_date": "2020-04-01T21:19:32.020000", "content": "Global Average Pooling
", "votes": 0, "replies": [] } ] }, { "id": 636214, "author_name": "", "author_url": "", "post_date": "2019-09-29T03:32:45.443000", "content": "", "votes": 0, "replies": [] }, { "id": 636738, "author_name": "Dieter", "author_url": "", "post_date": "2019-09-30T06:01:48.340000", "content": "great write-up. Thank you for sharing.
", "votes": 3, "replies": [] }, { "id": 637352, "author_name": "Thai Phan", "author_url": "", "post_date": "2019-10-01T00:54:56.243000", "content": "Awesome. Thank you for sharing.
", "votes": 0, "replies": [] } ], "raw_markdown_by_id": { "636168": "Thanks to Recursion and Kaggle for hosting such an interesting competition. It was really fun to participate.\n\n**UPDATE: source code is here: [https://github.com/maciej-sypetkowski/kaggle-rcic-1st](https://github.com/maciej-sypetkowski/kaggle-rcic-1st)**\n\n## Data pre-processing & augmentation\n* Loading original images (512x512)\n* HUVEC-18 is moved to the training set (known leak)\n* For training, all control images (also these from the test set) are used in the same way as non-control images\n* Training augmentations\n * Random resized crop preserving aspect with scale ~ uniform(0.5, 1) using nearest-neighbor interpolation\n * Random horizontal and vertical flip, and 90 degrees rotation\n * Normalizing each image channel to N(0, 1)\n * For each channel: channel = channel * a + b, where a ~ N(1, 0.1), b ~ N(0, 0.1)\n* Test-time augmentations\n * Horizontal and vertical flip, and 90 degrees rotation\n\n## Model\n\n* Backbone is pre-trained on ImageNet and first convolution is replaced with 6 input channel convolution\n* Neck: BN + FC + ReLU + BN + FC + BN\n* Head: FC\n\nI found it important to not normalize input for the head, and that's the reason why the head and arc margin product are separate layers with different weights for fully connected layer (contrary to [what bestfitting did in Human Protein Atlas Image Classification](https://www.kaggle.com/c/human-protein-atlas-image-classification/discussion/78109)).\n\n## Training\n* Batch size: 24 (48 with gradient accumulation)\n* Optimizer: Adam\n* Weight decay: 1e-5\n* [Cutmix](https://arxiv.org/abs/1905.04899)\n* Loss = ArcFaceLoss / 2 * 0.2 + SoftmaxCrossEntropyLoss * 0.8\n (ArcFaceLoss is divided by 2 to more or less preserve magnitude between losses)\n* 90 epochs\n* Learning rate: 1.5e-4 with cosine scheduling\n\n## Post-processing\n1. Predictions from different site images and different test-time augmentations are combined by taking mean of logits\n2. Predictions for control classes are ignored\n3. 831 classes that can't be on the given plate are marked as impossible\n4. Linear Sum Assignment (LSA) is applied\n\n\nWith such configuration (training on all labeled part of the dataset -- no validation), I got 0.98997 private score and 0.95802 public score (single model).\nEnsembling it with models trained in the same or very similar way (most of them with train/val split 5:1) (3x DenseNet161, 2x DenseNet161 with mixup (instead of cutmix), 5x DenseNet201 also with mixup, 3x ResNeXt50 also with mixup) gave me 0.99540 private and 0.98262 public (between 3rd-4th place on private LB).\n\n\nTo reach score of 0.997 private with single model I needed to add one more trick, which I would call:\n\n## Progressive pseudo-labeling\nIn all write-ups I've read so far, pseudo-labeling methods consist of iteratively training new model(s) and enlarging training set using them. In my method, small amount of most confident predictions is pseudo-labeled and added to the training set **each epoch**. Precisely, for each epoch:\n1. Predict all test and validation examples that weren't added to the training set yet (without TTA, only with combining over sites -- predicting with TTA could probably lead to a small improvement, but it would take more time to compute)\n2. For each prediction, mark as impossible:\n * control classes,\n * classes that can't be on the plate,\n * classes that are already assigned to any image for the plate in the training set.\n3. Select K most confident prediction (difference between greatest and second greatest class prediction)\n4. Add new examples to the training set. If at least two examples are on the same plate and have the same class pseudo-labeled, add to the training set only the most confident one (to preserve uniqueness of classes on the plate)\n\nDuring class assignment, I use greedy-like approach instead of LSA. However, to generate final predictions, the same post-processing as earlier (without pseudo-labeling) is applied (and LSA there). Using LSA increases score because examples that were added later are more difficult and have smaller confidence (because network saw them fewer times, and learning rate was smaller (decreasing learning rate policy)).\n\n## Training previous single model further\n* for additional 40 epochs,\n* pseudo-labeling 40% of the test set at the start, and then adding 1.5% each epoch,\n* cosine learning rate schedule with initial learning rate = 6e-5 scheduled for 60 epochs (i.e. at the end of training it is 1.5e-5),\n\ngave me 0.99700 private and 0.99029 public, which already puts me on the 1st position.\n\nEnsembling it with another model trained in the same way, but with train/val split 5:1, I got 0.99749 private and 0.99187 public. Adding one more model to the ensemble (also trained in the same way, but on the different split) gave me 0.99763 private and 0.99187 public, which matches my private score.\n\nI noticed that around 120th epoch (30th epoch of pseudo-labeling -- 85% of test set already added) first pseudo-label misclassifications on validation set started to occur, hence I tried to fine-tune model even further (taking checkpoint from 120th epoch), starting with 80% of test set, and again incrementally adding new images for 30 epochs. And then again taking checkpoint 5 epochs before end, and starting from 95% for 20 epochs. However, by doing this I was able to classify correctly only one private example more (0.99707) and increase public score (i.e. probably only U2OS-04 experiment) to 0.99232.\n\nMy final submission is an ensemble of 11 models (6x DenseNet161, 5x DenseNet201) (each of them with pseudo-labeling) with more TTA (also predicting on crop-resized images with scale 0.75 and 0.85), but it didn't give me any boost on the private test set (0.99763), but helped on the public test set (probably only on U2OS-04) (0.99480).\n\n\n\n## Other insights\n* Mixup performs a little better than cutmix on the part without pseudo-labeling, but it converges slower. On the contrary, with pseudo-labeling, cutmix was a little better (probably because of faster convergence)\n* Larger architecture is better: DenseNet121 < DenseNet169 < DenseNet201 < DenseNet161 -- for people without knowledge about DenseNets: DenseNet161 has less layers but more parameters than DenseNet201\n* EfficientNets and ResNeXts didn't work for me\n\n\n## Attempt to use control images in a smarter way\nI want to share the approach I've tried, however it didn't give me any boost in the score, and I didn't use it in the final submission. But I think it's very valuable information, especially for the further research.\nMy idea was to instead of feeding to the head embedding only, feed also some information about any reference image from the same plate/experiment (e.g. its embedding and one-hot label).\nUsing only control images as a reference, would lead to overfitting. To tackle that problem, I used also non-control images as reference -- during training, control and non-control images are treated in the same way; during inference, only control images are used as reference (obviously, non-control images in the test set are not labeled).\nWe have 1139 classes per experiment (or 277 + 31 = 308 per plate), so the head would see each pair of classes after 1139 * 1139 = 1297321 images (once per 15 epochs) or 308 * 308 = 94864 (once per 1 epoch). To solve this, I ensure that in every batch there will be constant number of images from each of randomly chosen experiments/plates. For example, for batch size = 48, I can have 8(number of experiments/plates) x 6(number of images from given experiment/plate), and run the head on each pair among each experiment/plate in the batch. That gives 8 * 6 * 5 = 240 pairs in one batch (I forbid the image and the reference to be the same image), and doesn't increase training time (embedding of each image is calculated only once, and the head consists of few fully connected layers).\n\nHowever, it didn't work any better than normal classification, and sometimes even worse. I tried to add or modify features for the head, for example:\n* concatenate difference between / multiplication of image and reference embedding,\n* concatenate corresponding vector from the arc margin product layer to the reference label,\n* normalize / not normalize embeddings,\n* detaching some of the features (not computing gradient through them).\n\nI also tried:\n* add more layers to the head,\n* heavy-augment all images in a batch for the same experiment/plate in the same way -- all images in the batch belonging to the same experiment/plate would have the same brightness, contrast, gamma correction, the same scale applied, and so on -- the idea was to artificially simulate other cell types to direct model toward using references more effectively,\n* use mixup only within images from the same experiment/plate.\n\nHowever, no luck.\n\nWhat more, after training such model and feeding random noise as the reference, network still inferred very similar predictions with almost the same validation score (and not always worse). So, network didn't learn how to use the references properly.\nThat would imply that creating a model that performs well on different cell types (not seen during the training) using control images may be a very hard and challenging problem.", "752020": "Great", "636297": "Congrats with the first place, very inspiring! You did a very solid work, but besides that, what do you think is the magic feature that gave you the lead? After reading your solution I can identify the following as more or less unique, - using mixup, adding randomness on normalization, progressive PL, training for relatively long time, using 5:1 split is higher than usual, using gamma=0.2 [from bestfitting](https://www.kaggle.com/c/human-protein-atlas-image-classification/discussion/78109), adding zoom transform (I didn't remember anyone using zooming). What from your experience was the one that gave you the edge?\n\nAdditionally, what hardware and frameworks have you used?", "750192": "Amazing work tq u for sharing your hardwork!", "725193": "Hi @maciejsypetkowski ,\ncongrats on your victory!\nHowever I'm interested in the training performance of Your machine (\"more than 1 GPU hour per epoch\", \"I used 2x Titan V, PyTorch, and trained in mixed precision\" - So I assume it took 30 minutes per epoch for You.)\nYour computer seems stronger than mine (I have 2xRadeon7) but Your training time seems like 50-100% to long (I have a similar NN model and training of 1 epoch takes ~15-20 minuts in mixed_fp16 in TF with both GPUs).\nI was wondering if You didn't encounter some other bottlenecks like image reading/preprocessing. Did You check if the training time scales with the additional GPU (on top of the first one)? Did You check your CPU usage (if it's <100%)?", "647286": "Thank you very much for sharing your code. Your code looks very compact and clean!\n\nI have some questions about how you approach such a project/competition:\nDo you write everything from scratch or do you reuse code you have written before?\nDo you have a special approach for testing?\nDo you know the LB score of your approach without progressive pseudo-labeling?\nDo you have some general (not so obvious) tipps for beginners?\n\nThank you very much & keep up the great work! :-D", "644181": "congrats!", "636223": "congrats , very well written ", "814362": "Congrats on the 1st place!\nWhat's the reasoning for not using bias in the linear layers of the neck?\nhttps://github.com/maciej-sypetkowski/kaggle-rcic-1st/blob/master/model.py#L57", "772188": "Great insights and kudos for amazing work!", "752290": "Good ", "752286": "good", "719324": "Great work!!!\nThanks for sharing your code", "644362": ":) !!!", "642997": "Congrats!", "637163": "Really well written", "637104": "Hard and worthy work.", "636674": "Great work!", "794390": "", "636214": "", "636738": "great write-up. Thank you for sharing. ", "637352": "Awesome. Thank you for sharing." } }