{"cells":[{"metadata":{},"cell_type":"markdown","source":"References : \n [rxrx.ai](http://rxrx.ai) \n https://www.kaggle.com/jesucristo/quick-visualization-eda "},{"metadata":{},"cell_type":"markdown","source":"# Recursion Cellular Image Classification\n# CellSignal: Disentangling biological signal from experimental noise in cellular images\n\n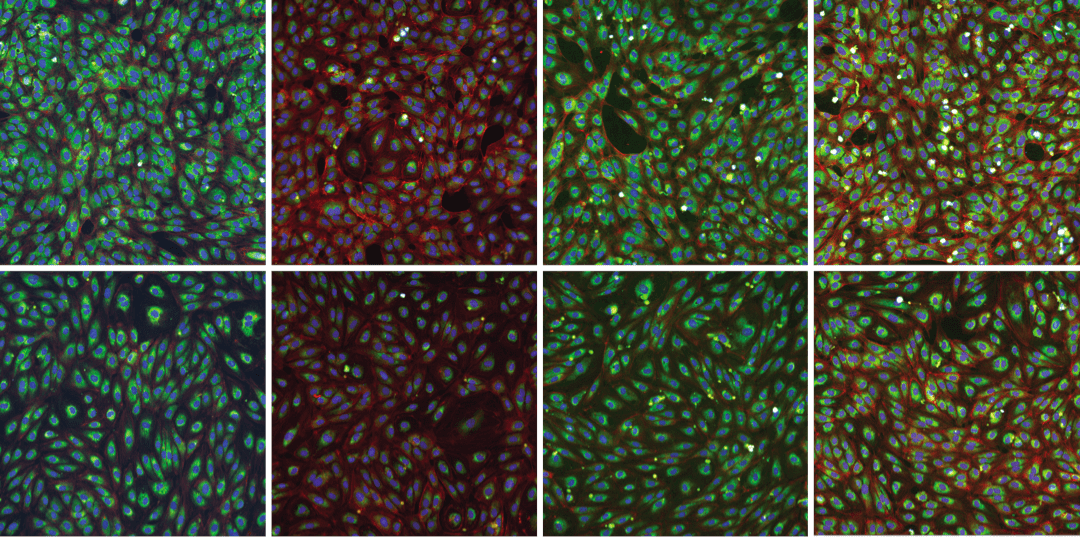"},{"metadata":{},"cell_type":"markdown","source":"# Experiment Structure\n\n"},{"metadata":{},"cell_type":"markdown","source":"\n\n\n# Images of two different genetic conditions (rows) in HUVEC cells across four experimental batches (columns)\n\n"},{"metadata":{},"cell_type":"markdown","source":"# Example of individual channels in U2OS fluorescent microscopy images\n\n"},{"metadata":{},"cell_type":"markdown","source":"## Let us begin!!"},{"metadata":{"trusted":true},"cell_type":"code","source":"import os, sys\nimport random\nimport numpy as np \nimport pandas as pd\n\nfrom PIL import Image\nfrom PIL import Image\n\nfrom datetime import datetime\nimport torch\nimport torch.nn as nn\nimport torch.utils.data as D\nimport torch.nn.functional as F\n\nimport torchvision\nfrom torchvision import transforms as T\n\nimport tqdm\n\nimport warnings\nwarnings.filterwarnings('ignore')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## View the file structure"},{"metadata":{"trusted":true},"cell_type":"code","source":"! ls -lahtr ../input/recursion-cellular-image-classification/","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Load our files"},{"metadata":{"trusted":true},"cell_type":"code","source":"batch_size = 64","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"path_data = '../input/recursion-cellular-image-classification/'\ntrnalldf = pd.read_csv(os.path.join(path_data, 'train.csv'))\ntstdf = pd.read_csv(os.path.join(path_data, 'test.csv'))\nstatsdf = pd.read_csv(os.path.join(path_data, 'pixel_stats.csv'))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Now lets view the file contents"},{"metadata":{"trusted":true},"cell_type":"code","source":"trnalldf.iloc[0]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# lets look at the samples per per experiments\ntstdf.experiment.value_counts().sort_index()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# Lets take the first 3 experiments as train, and the next 4 as val\nvaldf = trnalldf[trnalldf.experiment.str.contains('01')]\ntrndf = trnalldf[trnalldf.experiment.str.contains('02|03|04|05|06|07')]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"print('Train frame shape : rows {} cols {}'.format(*trndf.shape))\nprint('Val frame shape : rows {} cols {}'.format(*valdf.shape))\nprint('Test frame shape : rows {} cols {}'.format(*tstdf.shape))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Let's look at experiment batch impact"},{"metadata":{"trusted":true},"cell_type":"code","source":"statsdf.iloc[0]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"meanexpdf = statsdf.groupby(['experiment', 'channel'])['mean'].mean().unstack()\nstdexpdf = statsdf.groupby(['experiment', 'channel'])['mean'].mean().unstack()\nmeanexpdf[meanexpdf.index.str.contains('01|02')]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# We can see large differences by \nmeanexpdf.loc['HEPG2-01'].values","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## We will bring in some augmentations from Albumentations - check it out"},{"metadata":{},"cell_type":"markdown","source":"# Albumentations\n\n"},{"metadata":{"trusted":true},"cell_type":"code","source":"from albumentations import (Cutout, Compose, Normalize, RandomRotate90, HorizontalFlip,\n VerticalFlip, ShiftScaleRotate, Transpose, OneOf, IAAAdditiveGaussianNoise,\n GaussNoise, RandomGamma, RandomContrast, RandomBrightness, HueSaturationValue,\n RandomCrop, Lambda, NoOp, CenterCrop, Resize)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def aug(p=1.):\n return Compose([\n RandomRotate90(),\n HorizontalFlip(),\n VerticalFlip(),\n Transpose(),\n NoOp(),\n ], p=p)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Data loader - we make a class and use torch loader"},{"metadata":{"trusted":true},"cell_type":"code","source":"class ImagesDS(D.Dataset):\n def __init__(self, df, img_dir, size = 256, mode='train', meandf = meanexpdf, stddf = stdexpdf, channels=[1,2,3,4,5,6]):\n \n self.records = df.to_records(index=False)\n self.channels = channels\n self.site = random.randint(1,2) # load a random site from each well.\n self.mode = mode\n self.meandf = meanexpdf\n self.stddf = stdexpdf\n self.img_dir = img_dir\n self.len = df.shape[0]\n self.size = size\n self.augtransform = aug()\n \n @staticmethod\n def _load_img_as_tensor(file_name, size):\n with Image.open(file_name) as img:\n img = img.resize((size, size), resample=Image.BICUBIC)\n return img\n \n @staticmethod\n def torch_augment(img, transform, mean_, sd_):\n img = img.astype(np.float32)\n img = transform(image = img)['image']\n img = torch.from_numpy(np.moveaxis(img, -1, 0).astype(np.float32))\n img = T.Normalize([*list(mean_)], [*list(sd_)])(img)\n return img \n\n def _get_img_path(self, index, channel):\n experiment, well, plate = self.records[index].experiment, self.records[index].well, self.records[index].plate\n return '/'.join([self.img_dir,self.mode,experiment,f'Plate{plate}',f'{well}_s{self.site}_w{channel}.png'])\n \n def __getitem__(self, index):\n paths = [self._get_img_path(index, ch) for ch in self.channels]\n \n # Normalise values\n meanvals = self.meandf.loc[self.records[index].experiment].values\n stdvals = self.stddf.loc[self.records[index].experiment].values\n \n # Load image\n img = np.stack([self._load_img_as_tensor(img_path, self.size) for (img_path, m, s) in zip(paths, meanvals, stdvals)], -1)\n img = self.torch_augment(img, self.augtransform, meanvals, stdvals) \n \n if self.mode == 'train':\n return img, self.records[index].sirna\n else:\n return img, self.records[index].id_code\n\n def __len__(self):\n \"\"\"\n Total number of samples in the dataset\n \"\"\"\n return self.len","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"trnloader = D.DataLoader(ImagesDS(trndf, path_data, mode='train'), batch_size=batch_size, shuffle=True, num_workers=4)\nvalloader = D.DataLoader(ImagesDS(valdf, path_data, mode='train'), batch_size=batch_size*2, shuffle=False, num_workers=4)\ntstloader = D.DataLoader(ImagesDS(tstdf, path_data, mode='test'), batch_size=batch_size*2, shuffle=False, num_workers=4)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"X,y = next(iter(trnloader))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"X.mean(), X.std()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"print('Batch Shape : {}'.format(X.shape))\nprint('Label Shape : {}'.format(y.shape))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Let's set up our model..."},{"metadata":{},"cell_type":"markdown","source":"\n\n# Densenet121\n\n"},{"metadata":{"trusted":true},"cell_type":"code","source":"class DenseNet(nn.Module):\n def __init__(self, num_classes=1000, num_channels=6):\n super().__init__()\n preloaded = torchvision.models.densenet121(pretrained=True)\n self.features = preloaded.features\n self.features.conv0 = nn.Conv2d(num_channels, 64, 7, 2, 3)\n self.classifier = nn.Linear(1024, num_classes, bias=True)\n del preloaded\n \n def forward(self, x, emb=False):\n features = self.features(x)\n out = F.relu(features, inplace=True)\n out = F.adaptive_avg_pool2d(out, (1, 1)).view(features.size(0), -1)\n if emb:\n return out\n out = self.classifier(out)\n return out","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"%%capture\nmodel = DenseNet(num_classes=trndf.sirna.max()+1, num_channels = 6)\nmodel","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"dir(model)[-10:]","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# Look at the first 10 layers\n[(n, w.shape) for t, (n,w) in enumerate(model.named_parameters()) if t <10]","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"### Lets look at a single layer"},{"metadata":{"trusted":true},"cell_type":"code","source":"model.features.denseblock2.denselayer10.conv2.weight[:1]","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Mixed Precision Training\nWe saw apex in homework 6. This allows certain parts of the network to be stored in FP32 (32-bit floating point) and other parts to be stored in FP16\nWith a few small code changes we can half runtime... essential in the large networks outperforming today."},{"metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","trusted":true},"cell_type":"code","source":"%%capture\n# install NVIDIA Apex if needed to support mixed precision training\nuse_amp = True\nif use_amp:\n try:\n from apex import amp\n except ImportError:\n !pip install -v --no-cache-dir --global-option=\"--cpp_ext\" --global-option=\"--cuda_ext\" ../input/*/*/NVIDIA-apex*\n from apex import amp","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Use one cycle to get optimum LR"},{"metadata":{"trusted":true},"cell_type":"code","source":"device = 'cuda'\nmodel = DenseNet(num_classes=trndf.sirna.max()+1, num_channels = 6)\nmodel.to(device)\ncriterion = nn.CrossEntropyLoss()\noptimizer = torch.optim.Adam(model.parameters(), lr=0.001)\nmodel, optimizer = amp.initialize(model, optimizer, opt_level=\"O2\", keep_batchnorm_fp32=False, loss_scale=\"dynamic\")","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## [One Cycle Policy](https://sgugger.github.io/the-1cycle-policy.html#the-1cycle-policy)"},{"metadata":{"trusted":true},"cell_type":"code","source":"# One cycle policy https://sgugger.github.io/the-1cycle-policy.html#the-1cycle-policy\noptimizer.param_groups[0]['lr'] = .001 \nonecycdf = trnalldf\nonecycleloader = D.DataLoader(ImagesDS(onecycdf, path_data, mode='train'), batch_size=batch_size, shuffle=True, num_workers=8)\nprint('Total Step Count : {}'.format(len(onecycleloader)))\n","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"import math\ninit_value = 1e-5\nfinal_value=1.\nbeta = 0.98\navg_loss = 0.\nbatch_num = 0\nnumsteps = len(onecycleloader)-1\nmult = (final_value / init_value) ** (1/numsteps )\nlrvals = pd.Series([init_value*(mult**i) for i in range(numsteps+ 1)])\nlrvals.plot(title='LR per step')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"lossls = []\noptimizer.param_groups[0]['lr'] = init_value\nfor t, (x, y) in enumerate(onecycleloader): \n optimizer.zero_grad()\n x = x.to(device)#.half()\n y = y.cuda()\n xgrad = torch.autograd.Variable(x, requires_grad=True)#.half()\n ygrad = torch.autograd.Variable(y)\n out = model(xgrad)\n loss = criterion(out, ygrad)\n with amp.scale_loss(loss, optimizer) as scaled_loss:\n scaled_loss.backward()\n optimizer.step()\n optimizer.param_groups[0]['lr'] = init_value*(mult**t)\n \n ######One Cycle Policy##########>\n #Compute the smoothed loss\n batch_num += 1\n avg_loss = beta * avg_loss + (1-beta) *loss.item()\n smoothed_loss = avg_loss / (1 - beta**batch_num)\n lossls.append(smoothed_loss)\n\n if t%20==0:\n print('Step {} lr {:.6f} smoothed loss {:.5f} time {}'.format(t, init_value*(mult**t), smoothed_loss, datetime.now()))\n del loss, out, y, x# , target","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"pd.Series(lossls, index=np.log10(lrvals)).plot(title='Smoothed loss per LR (log10)', ylim=(6.9,7.3), figsize = (10,4))","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Lets get a Learning Rate scheduler"},{"metadata":{"trusted":true},"cell_type":"code","source":"%%capture\n!pip install https://github.com/ceshine/pytorch_helper_bot/archive/0.0.5.zip\nfrom helperbot import GradualWarmupScheduler\nfrom torch.optim.lr_scheduler import _LRScheduler\nfrom torch.optim.lr_scheduler import ReduceLROnPlateau","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"EPOCHS=8\nlrmult=10\nlr = 3e-2/lrmult\ncriterion = nn.CrossEntropyLoss()\noptimizer = torch.optim.Adam(model.parameters(), lr=lr)\nscheduler_cosine = torch.optim.lr_scheduler.CosineAnnealingLR(optimizer, EPOCHS)\nscheduler_warmup = GradualWarmupScheduler(optimizer, multiplier=lrmult, total_epoch=2, after_scheduler=scheduler_cosine)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"lrls = []\nfor e in range(EPOCHS):\n scheduler_warmup.step()\n lrls.append(scheduler_warmup.get_lr()[0])\npd.Series(lrls).plot(title='Learning Rate by epoch')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Now we train the model"},{"metadata":{"trusted":true},"cell_type":"code","source":"model = DenseNet(num_classes=trndf.sirna.max()+1, num_channels = 6)\nmodel.to(device)\nmodel, optimizer = amp.initialize(model, optimizer, opt_level=\"O2\", keep_batchnorm_fp32=False, loss_scale=\"dynamic\")\nscheduler_cosine = torch.optim.lr_scheduler.CosineAnnealingLR(optimizer, EPOCHS)\nscheduler_warmup = GradualWarmupScheduler(optimizer, multiplier=lrmult, total_epoch=2, after_scheduler=scheduler_cosine)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"@torch.no_grad()\ndef prediction(model, loader):\n probs = []\n for x, _ in tqdm.tqdm(loader):\n x = x.to(device)\n output = model(x)\n outmat = torch.sigmoid(output.cpu()).numpy()\n probs.append(outmat)\n probs = np.concatenate(probs, 0)\n return probs","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"for epoch in range(EPOCHS):\n tloss = 0.\n model.train()\n scheduler_warmup.step()\n for t, (x, y) in tqdm.tqdm(enumerate(trnloader)): \n optimizer.zero_grad()\n x = x.to(device)#.half()\n y = y.cuda()\n xgrad = torch.autograd.Variable(x, requires_grad=True)#.half()\n ygrad = torch.autograd.Variable(y)\n out = model(xgrad)\n loss = criterion(out, ygrad) \n with amp.scale_loss(loss, optimizer) as scaled_loss:\n scaled_loss.backward()\n optimizer.step()\n tloss += loss.item() \n del loss, out, y, x\n print('Epoch {} -> Train Loss: {:.4f} -> LR: {:.5f} -> Time {}'.format(epoch+1, tloss/len(trnloader), scheduler_warmup.get_lr()[0], datetime.now()))\n \n model.eval()\n preds = prediction(model, valloader)\n val_accuracy = (valdf.sirna.values == preds.argmax(1)).mean()\n print('Epoch {} -> Val Acc: {:.4f} -> Time {}'.format(epoch+1, val_accuracy, datetime.now()))\n","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Save model to disk"},{"metadata":{"trusted":true},"cell_type":"code","source":"output_model_file = \"recursion_model.bin\"\ntorch.save(model.state_dict(), output_model_file)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Now please implement test time augmentation to make predictions"},{"metadata":{"trusted":true},"cell_type":"code","source":"## Load up the model\n# model.load_state_dict(torch.load(os.path.join(path_data, \"recursion_model.bin\")))\n# model.to(device)\n# for param in model.parameters():\n# param.requires_grad = False\n# model.eval()\n# ....","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":1}