{"cells":[{"metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","trusted":true},"cell_type":"code","source":"# This Python 3 environment comes with many helpful analytics libraries installed\n# It is defined by the kaggle/python docker image: https://github.com/kaggle/docker-python\n# For example, here's several helpful packages to load in \n\nimport numpy as np # linear algebra\nimport pandas as pd # data processing, CSV file I/O (e.g. pd.read_csv)\n\n# Input data files are available in the \"../input/\" directory.\n# For example, running this (by clicking run or pressing Shift+Enter) will list the files in the input directory\n\nimport os\nprint(os.listdir(\"../input\"))\n\n# Any results you write to the current directory are saved as output.","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"728bd91490442ad7f5e2ddacf74b3a5bd2c2ac7c"},"cell_type":"markdown","source":"### ULMFit\n\nThis kernel is the initial version of using universal language model for text classification, which is currently the state of the art method for text classification. To put this thing in this shape, it took a lot of effort in configuration, Finally I figured out the way to use it kaggle kernel.\n\nMajority of the code is taken from FastAI course. I extend my Sincere gratitude to Jeremey Howard and Sebastian Ruder who are contributing amazing stuff in NLP.\n\n\n**Understanding ULMFit**\n\nTransfer learning has greatly impacted computer vision, but existing approaches in NLP still require task-specific modifications and training from scratch. We propose an effective transfer learning method that can be applied to any task in NLP, and introduce techniques that are key for fine-tuning a language model. Our method significantly outperforms the state-of-the-art on six text classification tasks, reducing the error by 18-24% on the majority of datasets. Furthermore, with only 100 labeled examples, it matches the performance of training from scratch on 100x more data.\n\nAt first we train a language model with the given text and use it for classification....\n\n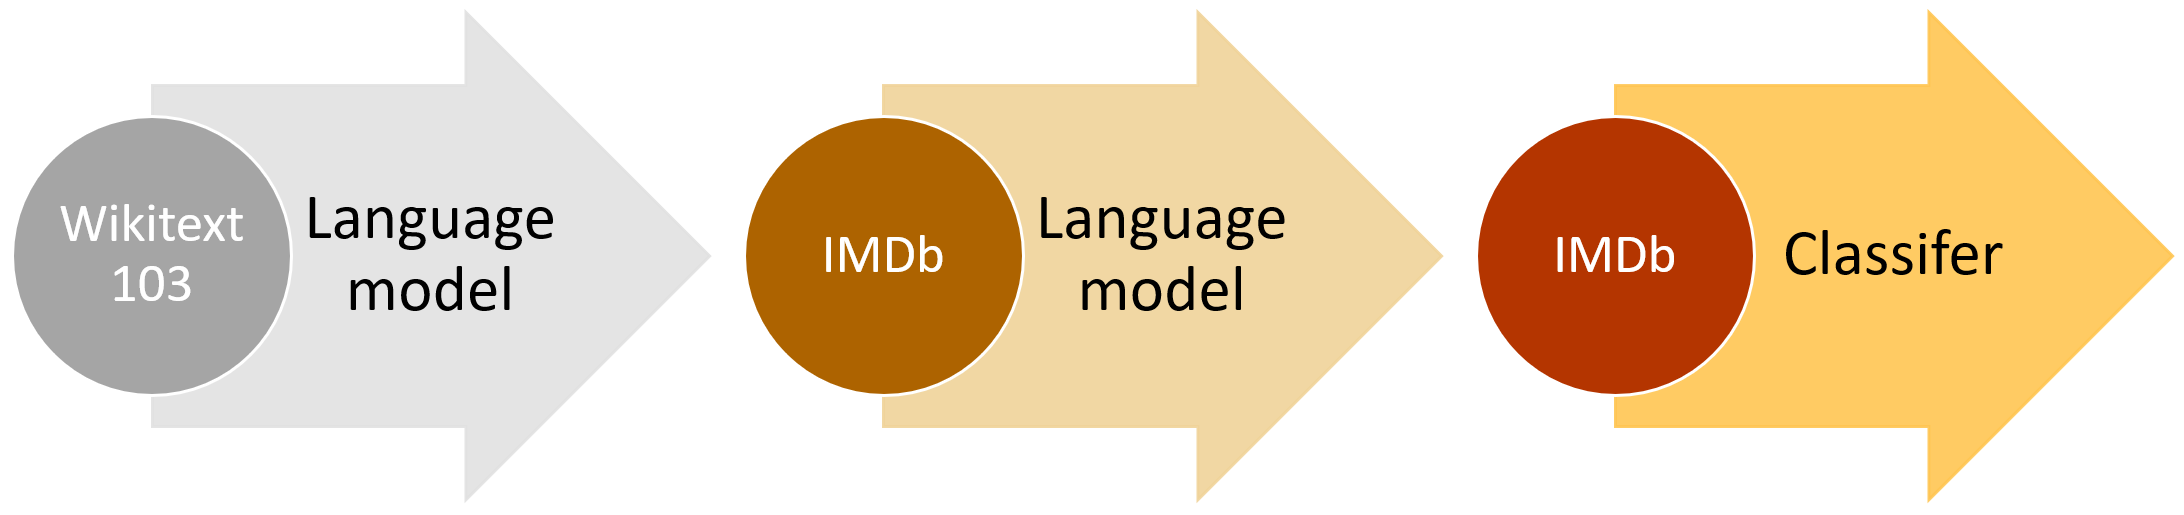\n\n**Tasks done in this notebook**\n\n1) Training a language model.\n\n2) Using Language model encoder for classification\n\n**TODO**\n\n1) Predictions on test data.\n\n2) Blending both forward and backward trained language model for classification.\n"},{"metadata":{"_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","trusted":true},"cell_type":"code","source":"!pip uninstall -y torch","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"107d0dc8d7138faacec16b57500f7725a337929c"},"cell_type":"code","source":"!conda install -y pytorch=0.3.1.0 cuda80 -c soumith","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"f4fb6d9e7e5cb09e0a3a96a8ae2e984ab0c0316e"},"cell_type":"code","source":"import torch\ntorch.__version__","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"eb642b6c874506ae92a0209747fd088710301336"},"cell_type":"code","source":"!pip install fastai==0.7.0\n!pip uninstall -y torchtext\n!pip install torchtext==0.2.3\n\nfrom fastai.text import *\nimport html","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"0a311cbda7b13b103a6a54f121772d41d907f58b"},"cell_type":"code","source":"train_df=pd.read_csv('../input/train.csv')\ntest_df=pd.read_csv('../input/test.csv')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"9311f1b4a0665e9e578c0fb2197a505fcb94f34c"},"cell_type":"code","source":"trn_df,val_df = sklearn.model_selection.train_test_split(train_df, test_size=0.1)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"c2d82bb6a21254873f858b1d7fcaa2ab6477befc"},"cell_type":"code","source":"trn_texts = trn_df['question_text']\nval_texts = val_df['question_text']\n\ntrn_labels = trn_df['target']\nval_labels = val_df['target']","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"9d38d0d91ec213ce70b2e259e1b5b1e9d022d4f6"},"cell_type":"code","source":"trn_labels.value_counts()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"1de967b9551f156cd36161b225bb830618c44c83"},"cell_type":"code","source":"col_names = ['labels','text']","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"f072350e0e7c0696a02ddcda03bab4c4ab9c4bc4"},"cell_type":"code","source":"BOS = 'xbos' # beginning-of-sentence tag\nFLD = 'xfld' # data field tag","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"1951e4ef3c98ae3914e9ea02c689200dfbe7a73d"},"cell_type":"markdown","source":"#### Speeding up the tokenization:\n\n\n\nFor Speeding up the tokenization process we are breaking frame into chunks"},{"metadata":{"trusted":true,"_uuid":"e657597c2e578e7ae5e25f582c5f18fa7e911649"},"cell_type":"code","source":"df_trn = pd.DataFrame({'text':trn_texts, 'labels':trn_labels}, columns=col_names)\ndf_val = pd.DataFrame({'text':val_texts, 'labels':val_labels}, columns=col_names)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"ac1d823533dc394de4752a4f9507cd600a09d7a1"},"cell_type":"code","source":"!mkdir ../updated","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"ee1a6d8ddb5c8ab5a59f872d9e8241df32dd6b57"},"cell_type":"code","source":"!ls -lart ../","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"5249a76bf409b46c723111578a2e66b900e4e801"},"cell_type":"code","source":"df_trn.to_csv('../updated/train.csv', header=False, index=False)\ndf_val.to_csv('../updated/test.csv', header=False, index=False)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"2e495407b2780ea83850b0b88969be59b2abe019"},"cell_type":"code","source":"chunksize=24000","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"e7d0708991575e54199892d7ee51024da07ee0fc"},"cell_type":"code","source":"re1 = re.compile(r' +')\n\ndef fixup(x):\n x = x.replace('#39;', \"'\").replace('amp;', '&').replace('#146;', \"'\").replace(\n 'nbsp;', ' ').replace('#36;', '$').replace('\\\\n', \"\\n\").replace('quot;', \"'\").replace(\n '
', \"\\n\").replace('\\\\\"', '\"').replace('','u_n').replace(' @.@ ','.').replace(\n ' @-@ ','-').replace('\\\\', ' \\\\ ')\n return re1.sub(' ', html.unescape(x))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"8b5f93935e82fc391c7402af4005a64ea4adf321"},"cell_type":"code","source":"def get_texts(df, n_lbls=1):\n labels = df.iloc[:,range(n_lbls)].values.astype(np.int64)\n texts = f'\\n{BOS} {FLD} 1 ' + df[n_lbls].astype(str)\n for i in range(n_lbls+1, len(df.columns)): texts += f' {FLD} {i-n_lbls} ' + df[i].astype(str)\n texts = list(texts.apply(fixup).values)\n\n tok = Tokenizer().proc_all_mp(partition_by_cores(texts))\n return tok, list(labels)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"a7442dd4f415a753ed3b9331457beea377f9f0d9"},"cell_type":"code","source":"def get_all(df, n_lbls):\n tok, labels = [], []\n for i, r in enumerate(df):\n print(i)\n tok_, labels_ = get_texts(r, n_lbls)\n tok += tok_;\n labels += labels_\n return tok, labels","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"f91882be490335a025f9795e8fd40da55705b3f8"},"cell_type":"code","source":"df_trn = pd.read_csv('../updated/train.csv', header=None, chunksize=chunksize)\ndf_val = pd.read_csv('../updated/test.csv', header=None, chunksize=chunksize)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"4e7ee4483460dcfdc53e999b80f0ca20a5294b21"},"cell_type":"code","source":"tok_trn, trn_labels = get_all(df_trn, 1)\ntok_val, val_labels = get_all(df_val, 1)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"c266890a792000b1e51ebab1906fc2150b7e5862"},"cell_type":"code","source":"np.save('../updated/tok_trn.npy', tok_trn)\nnp.save('../updated/tok_val.npy', tok_val)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"2e37f1f497f2f56a2eaccb6c198987629468c357"},"cell_type":"code","source":"tok_trn = np.load('../updated/tok_trn.npy')\ntok_val = np.load('../updated/tok_val.npy')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"3c4fbc80481af17ae81d98a5a3a158574615147b"},"cell_type":"code","source":"freq = Counter(p for o in tok_trn for p in o)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"e07b6187e0f27b2bdf715e50b9fdb9cee9e07d6a"},"cell_type":"code","source":"max_vocab = 60000\nmin_freq = 2","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"c57f9df8f6a7e56ae25d4ee3a68e8f61a591fa95"},"cell_type":"code","source":"itos = [o for o,c in freq.most_common(max_vocab) if c>min_freq]\nitos.insert(0, '_pad_')\nitos.insert(0, '_unk_')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"ef3f11eaca92e5c23c7fa6025a915ee2a6268d68"},"cell_type":"code","source":"stoi = collections.defaultdict(lambda:0, {v:k for k,v in enumerate(itos)})\nlen(itos)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"71b25e95ed7d27d35d4d73831efbeefcf35cebdf"},"cell_type":"code","source":"trn_lm = np.array([[stoi[o] for o in p] for p in tok_trn])\nval_lm = np.array([[stoi[o] for o in p] for p in tok_val])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"825d0833c58396ea1e9f0ddac4a18fe0f58a492a"},"cell_type":"code","source":"np.save('../updated/trn_ids.npy', trn_lm)\nnp.save('../updated/val_ids.npy', val_lm)\npickle.dump(itos, open('../updated/itos.pkl', 'wb'))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"5fac21596c6aeca5903d4d244ad6363ff312a259"},"cell_type":"code","source":"trn_lm = np.load('../updated/trn_ids.npy')\nval_lm = np.load('../updated/val_ids.npy')\nitos = pickle.load(open('../updated/itos.pkl', 'rb'))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"5e84493085ad246af9e53c20460fd36dfc099a64"},"cell_type":"code","source":"vs=len(itos)\nvs,len(trn_lm)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"637853f44857a71598056b0b6350ee2a3a3f7df9"},"cell_type":"markdown","source":"#### Getting the wikipedia language model"},{"metadata":{"trusted":true,"_uuid":"fb5a2e4cf0d0f56ec98634bee1da41a8de8f8828"},"cell_type":"code","source":"!wget -P ../updated/ http://files.fast.ai/models/wt103/fwd_wt103.h5 ","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"2ca927cf3cbb0467ee7bc381807f722759b2c102"},"cell_type":"code","source":"wgts = torch.load('../updated/fwd_wt103.h5', map_location=lambda storage, loc: storage)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"25e4fd69f24813a8e6b47ff04a0a3f73752c47ee"},"cell_type":"code","source":"enc_wgts = to_np(wgts['0.encoder.weight'])\nrow_m = enc_wgts.mean(0)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"19892bd0b9d3ff59ec418b11b8cbf861d7c1fdfd"},"cell_type":"code","source":"PATH=Path('../updated')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"66d12dd2ff8efc4f30236f7f46d16cd37fa96783"},"cell_type":"code","source":"!wget -P ../updated/ http://files.fast.ai/models/wt103/itos_wt103.pkl \nitos2 = pickle.load((PATH/'itos_wt103.pkl').open('rb'))\nstoi2 = collections.defaultdict(lambda:-1, {v:k for k,v in enumerate(itos2)})","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"acb0892a03c3df44d0fea5f7749cf21bee94e9a9"},"cell_type":"code","source":"em_sz,nh,nl = 400,1150,3","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"a313cc731abf09ea3045d28c47031171503e9a9b"},"cell_type":"code","source":"new_w = np.zeros((vs, em_sz), dtype=np.float32)\nfor i,w in enumerate(itos):\n r = stoi2[w]\n new_w[i] = enc_wgts[r] if r>=0 else row_m","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"e87273d7f1cfa598ef9b78de5146f63bdcce238f"},"cell_type":"markdown","source":"#### Set the map with our inputs"},{"metadata":{"trusted":true,"_uuid":"7a1a90eda1d093cf885f6483cd3a66013d87ba74"},"cell_type":"code","source":"wgts['0.encoder.weight'] = T(new_w)\nwgts['0.encoder_with_dropout.embed.weight'] = T(np.copy(new_w))\nwgts['1.decoder.weight'] = T(np.copy(new_w))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"cc15ea041f80e17ed46fa0a740771fb09a12d19a"},"cell_type":"code","source":"import gc\ngc.enable()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"f45c16b6509538fba919f5ed27398d70ad412a9e"},"cell_type":"code","source":"gc.collect()","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"0acc7eae0a8eb694c7687dc9a7b7a670c4984731"},"cell_type":"markdown","source":"### Language model in action....."},{"metadata":{"trusted":true,"_uuid":"5fb86c24ab54d26da28912d93ab3ccf0a27f6923"},"cell_type":"code","source":"wd=1e-7\nbptt=70\nbs=52\nopt_fn = partial(optim.Adam, betas=(0.8, 0.99))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"207fb7ca28d744be69240e357878a9b794313be1"},"cell_type":"code","source":"trn_dl = LanguageModelLoader(np.concatenate(trn_lm), bs, bptt)\nval_dl = LanguageModelLoader(np.concatenate(val_lm), bs, bptt)\nmd = LanguageModelData(PATH, 1, vs, trn_dl, val_dl, bs=bs, bptt=bptt)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"6d1a6c20a00859cae9d3d2fb1dc325874fece15f"},"cell_type":"code","source":"drops = np.array([0.25, 0.1, 0.2, 0.02, 0.15])*0.7","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"999d27cb07a408ae736184f6a496073076d9dfaf"},"cell_type":"code","source":"learner= md.get_model(opt_fn, em_sz, nh, nl, \n dropouti=drops[0], dropout=drops[1], wdrop=drops[2], dropoute=drops[3], dropouth=drops[4])\n\nlearner.metrics = [accuracy]\nlearner.freeze_to(-1)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"64595b9bd52bad2dae505628d6ed60bdcf575328"},"cell_type":"code","source":"learner.model.load_state_dict(wgts)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"9af11be6929848097f5ed227092e53e5bfe2481b"},"cell_type":"code","source":"lr=1e-2\nlrs = lr","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"f8b5676a7313b301dae13310f1a29f312aff2ed9"},"cell_type":"code","source":"learner","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"8bcc0cd18beb1154036863a675da49ecc0064adf"},"cell_type":"code","source":"### Taking too long to train as per the kernel requirement I couldn't commit it\n\n#learner.fit(lrs, 1, wds=wd, use_clr=(32,2), cycle_len=1)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"fd3e139a0f12f884cd53c0df40238e4d8b5193a2"},"cell_type":"markdown","source":"**Stay tune to be continued**"},{"metadata":{"trusted":true,"_uuid":"68c5c32b3f432e8d6543034a1b9b7f29f1c09532"},"cell_type":"code","source":"","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"display_name":"Python 3","language":"python","name":"python3"},"language_info":{"name":"python","version":"3.6.6","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"}},"nbformat":4,"nbformat_minor":1}