{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# **Báo cáo bài tập lớn môn Học máy: Quora Insincere Questions Classification**\n**Sinh viên:** Phan Hải Anh
\n**MSSV:** 19021213
","metadata":{"execution":{"iopub.status.busy":"2022-01-08T10:30:44.884177Z","iopub.execute_input":"2022-01-08T10:30:44.885439Z","iopub.status.idle":"2022-01-08T10:30:44.892156Z","shell.execute_reply.started":"2022-01-08T10:30:44.885368Z","shell.execute_reply":"2022-01-08T10:30:44.890937Z"}}},{"cell_type":"markdown","source":"# **Mô tả bài toán**\n\n**Quora Insincere Question Classification** là một bài toán của **Quora** đặt ra, sử dụng sự trợ giúp từ cộng đồng, giúp họ phân loại những câu hỏi không chân thành. Nhiệm vụ của bài toán là sử dụng tập dữ liệu mà **Quora** cung cấp để phân loại ra những câu hỏi mang hàm ý không chân thành, mang nội dung xấu độc, gây hiểu lầm.\n\n- **Đầu vào**: Câu hỏi dưới dạng văn bản (plain text)\n- **Đầu ra**: Yes/No (insincere (1) or not (0))\n\n- Tiền xử lý bộ dữ liệu\n - Bỏ đi các biểu thức toán học và các đường dẫn liên kết\n - Bỏ đi các ký tự đặc biệt, các chữ số\n - Sửa những từ sai chính tả và extend các từ viết tắt\n - Bỏ đi stop_words trong câu\n - Lemming các từ có trong câu (có thể hiểu là chuyển các từ về dạng nguyên thể)\n \n> **Mục đích**: Loại bỏ đi các từ gây nhiễu cho bộ dữ liệu và mở rộng độ bao phủ của tập Vocab với bộ dữ liệu\n- Xây dựng tập vocab: \n - Sử dụng các file trong embeddings.zip mà quora cung cấp để xây dựng tập vocab \n - Các file embeddings có dạng text, mỗi dòng chứa 1 word và đi kèm đó là vector của nó đã được pretrained\n - Xây tập vocab từ các word có trong từ điển và vector đi kèm với chúng\n - Kiểm tra độ phủ của vocab xây dựng dựa trên tập embeddings với dữ liệu được cho\n- Xây dựng ma trận embeddings:\n - Sử dụng file pretrained để tạo ra ma trận embeddings dựa vào các từ có trong tập vocab\n - Lấy các từ để lookup vector descriptor của các từ đó và xây ma trận\n- Tạo model và huấn luyện dự đoán\n- Kết hợp kết quả của nhiều model với các ma trận embeddings đã xây dựng và cho ra kết quả tốt nhất","metadata":{}},{"cell_type":"markdown","source":"# **1. Khảo sát dữ liệu**","metadata":{}},{"cell_type":"markdown","source":"Xác định các tập ```train```, ```test``` và khởi tạo một tập chứa dữ liệu của cả 2 để về sau check độ bao phủ của vocab với tập dữ liệu đã sinh\n\n**Tập ```train```: **\nỞ trong bộ dữ liệu có 3 trường, và khả năng dữ liệu train nằm ở trường **```question_text```**
\nVậy ta sẽ thử khảo sát dữ liệu trong trường **```question_text```**\nCó thể thấy rằng tập train có 3 trường dữ liệu\n- **```qid```**: định danh id cho câu hỏi\n- **```question_text```**: nội dung câu hỏi\n- **```target```**: phân lớp câu hỏi\n - 0: câu hỏi mang tính chất chân thành (sincere)\n - 1: câu hỏi không mang tính chất chân thành (insincere)\n \nKhá may mắn khi tập dữ liệu **Quora** cung cấp không có bất kì trường dữ liệu nào có giá trị bất thường (```null```, ```none```, ```missing```)\n \nTập dữ liệu train bao gồm **1306122** dòng dữ liệu, gần **1.31 triệu dòng**, khá lớn. \n\nCó thể thấy trong trường target có 2 giá trị là ```0``` và ```1```
\nDự đoán thì những câu hỏi đánh dấu ```0``` là những câu hỏi sincere, tương tự ```1``` là insincere
\nVậy có thể xem như đây là bài toán phân lớp nhị phân
\nNhưng vẫn cần phải có đánh giá sâu hơn về bộ dữ liệu này, nhìn nhanh qua có thể thấy bộ dữ liệu train được cho khá là mất cân bằng\n\nQua biểu đồ có thể dễ dàng nhận thấy tập dữ liệu train bị mất cân bằng nhiều:\n- Lớp câu hỏi sincere có **1225312** (chiếm **93.81%**) số lượng dữ liệu\n- Lớp câu hỏi insincere có **80810** (chiếm **6.19%**) số lượng dữ liệu\n\nCó thể thấy tập dữ liệu bị lệch nhiều (lên tới **15 lần**) cho nên cần phải sử dụng metrics f1_score để đánh giá độ hiệu quả của mô hình hơn là so **accuracy**
\nDo **f1_score** quan tâm đến phân bố của dữ liệu nên trong bài này nó sẽ mang nhiều ý nghĩa hơn là **accuracy**.
\nVà trong cuộc thi **Kaggle** cũng bảo là sử dụng **f1_score** thay vì **accuracy**\n\n**Tập ```test```**:\nỞ trong bộ dữ liệu test thì chỉ có 2 trường dữ liệu là qid đại diện cho id của câu hỏi\nVà question_text đại diện cho dữ liệu test\nCũng may mắn khi mà ở trong tập df_test lại không có dữ liệu kì lạ nào cả (null, none, missing)\n\nMỗi lần shuffle lại cho ra một kết quả khác, nhưng nhìn chung qua vài lần thực nghiệm quan sát, em nhận thấy trong tập dữ liệu ở trên:\n\nCó nhiều câu mà các từ trong đó viết sai chính tả, lẫn lộn giữa tiếng Anh-Anh và tiếng Anh-Mỹ\nNhiều câu sử dụng các từ viết tắt: He's mà đáng nhẽ nên là He is.\nCó một số từ viết tắt cho tên các tổ chức, hay các chuẩn mã hoá kiểu RSA, DES/3DES, ...\nNhiều câu sử dụng các ký tự đặc biệt cho nên sẽ gây ảnh hưởng lớn tới mô hình dự đoán\nVề mặt nội dung hàm ý thì có thể không ảnh hưởng nhưng sẽ ảnh hưởng khi xâp tập từ điển, cùng một ý nghĩa nhưng các từ lại được tính nhiều lần giá trị\n\nThấy rằng, bộ dữ liệu đã cho có khá nhiều nhiễu => cần loại bỏ nhiều nhiều nhất có thể\n\nCách xử lý\n\nLoại bỏ stopwords có trong câu\nStem các từ có trong câu (driver, driving, driven, drove -> drive)\nChuẩn hoá các từ về dạng lowercase\nLoại bỏ các ký tự đặc biệt\nLoại bỏ các đường dẫn liên kết, loại bỏ các công thức toán học, ...\n\n### **Nhận xét**\nNhưng có thể thấy một điều là bộ dữ liệu **train** và **test** dữ liệu đầu vào đều ở dạng plain text và mô hình của chúng ta sẽ không thể hiểu nổi
\nVậy hướng giải quyết ở đây em nghĩ là là sử dụng mã hoá **one_hot** đưa dữ liệu về dạng binary để cho mô hình có thể hiểu được","metadata":{}},{"cell_type":"markdown","source":"","metadata":{}},{"cell_type":"code","source":"import pandas as pd \nimport seaborn as sns\nimport re\nimport gc\nimport os\nimport numpy as np\nimport operator\nfrom wordcloud import WordCloud, STOPWORDS\nfrom tqdm import tqdm\nimport matplotlib.pyplot as plt\npd_ctx = pd.option_context('display.max_colwidth', 100)\n\nimport nltk\nfrom nltk.stem import PorterStemmer, SnowballStemmer, WordNetLemmatizer\n\nfrom gensim.models import KeyedVectors\n\nimport tensorflow as tf\n\nfrom sklearn.model_selection import train_test_split\nimport sklearn.metrics as metrics\nfrom tensorflow.keras import optimizers\nfrom tensorflow.keras.layers import Dense, Input, LSTM, Embedding, Dropout, Activation, Conv1D,GRU\nfrom tensorflow.keras.layers import Bidirectional, GlobalMaxPool1D, SpatialDropout1D, GlobalMaxPooling1D, Concatenate\nfrom tensorflow.keras.models import Model,load_model\nfrom tensorflow.keras.utils import plot_model\nfrom tensorflow.keras.models import Sequential\nfrom tensorflow.keras.callbacks import ModelCheckpoint,EarlyStopping\nfrom tensorflow.keras.optimizers import Adam\nfrom tensorflow.keras.preprocessing.sequence import pad_sequences\n\ndf_train = pd.read_csv('/kaggle/input/quora-insincere-questions-classification/train.csv')\ndf_test = pd.read_csv('/kaggle/input/quora-insincere-questions-classification/test.csv')\nquora_data = df_train['question_text'].append(df_test['question_text'])\n\n# KHẢO SÁT DỮ LIỆU TRONG TẬP TRAIN\n\nprint(\"\\033[1mTrain set info\\033[0m\")\nprint(df_train.info())\n\n# Kiểm tra các trường dữ liệu của câu hỏi được đánh sincere\nprint(\"\\033[1mSincere Questions: \\033[0m\")\ndisplay(df_train[df_train['target']==0].head())\n# Kiểm tra các trường dữ liệu của câu hỏi được đánh sincere\nprint(\"\\033[1mInsincere Questions: \\033[0m\")\ndisplay(df_train[df_train['target']==1].head())\n\ndf_train.target.value_counts()\n\npos_len = len(df_train[df_train['target'] == 1])\nneg_len = len(df_train[df_train['target'] == 0])\ntotal = len(df_train)\nprint(\"\\033[1mTotal = \\033[0m\", total)\nprint(\"\\033[1mSincere questions:\\033[0m {neg} ({percent: .2f}% )\".format(neg = neg_len, percent = neg_len / total * 100))\nprint(\"\\033[1mInsincere questions:\\033[0m {pos} ({percent: .2f}% )\".format(pos = pos_len, percent = pos_len / total * 100))\nfig = plt.figure()\nax = fig.add_axes([0,0,1,1])\nax.bar(['sincere', 'insincere'], df_train.target.value_counts())\nplt.show()\n\n#KHẢO SÁT DỮ LIỆU TRONG TẬP TEST\n\ndf_test.info()\n# Shuffle tập train để kiểm tra những giá trị ngẫu nhiên\ntrain = df_train.sample(frac=1).reset_index(drop=True)\ndisplay(train.sample(n=10, random_state=344))","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:05:55.868981Z","iopub.execute_input":"2022-01-08T15:05:55.86933Z","iopub.status.idle":"2022-01-08T15:06:10.619621Z","shell.execute_reply.started":"2022-01-08T15:05:55.869244Z","shell.execute_reply":"2022-01-08T15:06:10.618613Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **2. Tiền xử lý dữ liệu**","metadata":{}},{"cell_type":"markdown","source":"Với bài toán liên quan đến ngôn ngữ thì hiệu quả của mô hình phụ thuộc lớn vào việc tiền xử lý dữ liệu, tức loại bỏ đi nhiễu ở trong bộ dữ liệu.
\nVà phương pháp phổ biến đối với các bài toán liên quan đến ngôn ngữ được trình bày ở dưới như sau\n\n**Cách làm:**
\nSử dụng thư viện xử lý ngôn ngữ tự nhiên nltk trong việc preprocess data
\nỞ đây yêu cần phải sử dụng wordnet, một thư viện từ đồng nghĩa, trái nghĩa, nltk punkt được yêu cầu để tokenize words
\n- Bước 1: ```clean_tag()```: loại bỏ đi các biểu thức toán học, các địa chỉ liên kết\n- Bước 2: ```clean_puncts()```: loại bỏ đi các ký tự đặc biệt có trong câu\n- Bước 3: ```correct_misspell()```: trong bộ dữ liệu của **Quora** do đây là các câu hỏi của người dùng nên không tránh khỏi việc gõ sai, hay là có những từ không chuẩn ví dụ là lẫn lộn giữa tiếng Anh-Anh với tiếng Anh-Mỹ cho nên cần phải fix những từ này và đưa nó về dạng chuẩn\n- Bước 4: ```remove_stopwords()```: loại bỏ đi các stopwords có trong câu( những từ, chữ dạng *'do'*, *'does'*, *'did'*, *'should'*, ...)\n- Bước 5: ```clean_contractions()```: chuyển những từ viết tắt về dạng đầy đủ vốn có\n- Bước 6: ```lemming_words()```: lemming các từ về dạng nguyên bản của nó\n\n\n**Vấn đề:**
\nTuy nhiên đời không như là mơ, cuộc thi này của **Quora** không cho phép sử dụng Internet nên việc lemming word bằng cách lookup từ điển này sẽ không hoạt động
\n**Giải pháp:**
\nCần tìm ra một phương pháp lemming words mới","metadata":{}},{"cell_type":"code","source":"# CÁC HÀM XỬ LÝ\n\ndef clean_tag(x):\n if '[math]' in x:\n x = re.sub('\\[math\\].*?math\\]', 'MATH EQUATION', x) #replacing with [MATH EQUATION]\n \n if 'http' in x or 'www' in x:\n x = re.sub('(?:(?:https?|ftp):\\/\\/)?[\\w/\\-?=%.]+\\.[\\w/\\-?=%.]+', 'URL', x) #replacing with [url]\n return x\n\npuncts = [',', '.', '\"', ':', ')', '(', '-', '!', '?', '|', ';', \"'\", '$', '&', '/', '[', ']', '>', '%', '=', '#', '*', '+', '\\\\', '•', '~', '@', '£', '·', '_', '{', '}', '©', '^', '®', '`', '<', '→', '°', '€', '™', '›', '♥', '←', '×', '§', '″', '′', '█', '…', '“', '★', '”', '–', '●', '►', '−', '¢', '¬', '░', '¡', '¶', '↑', '±', '¿', '▾', '═', '¦', '║', '―', '¥', '▓', '—', '‹', '─', '▒', ':', '⊕', '▼', '▪', '†', '■', '’', '▀', '¨', '▄', '♫', '☆', '¯', '♦', '¤', '▲', '¸', '⋅', '‘', '∞', '∙', ')', '↓', '、', '│', '(', '»', ',', '♪', '╩', '╚', '・', '╦', '╣', '╔', '╗', '▬', '❤', '≤', '‡', '√', '◄', '━', '⇒', '▶', '≥', '╝', '♡', '◊', '。', '✈', '≡', '☺', '✔', '↵', '≈', '✓', '♣', '☎', '℃', '◦', '└', '‟', '~', '!', '○', '◆', '№', '♠', '▌', '✿', '▸', '⁄', '□', '❖', '✦', '.', '÷', '|', '┃', '/', '¥', '╠', '↩', '✭', '▐', '☼', '☻', '┐', '├', '«', '∼', '┌', '℉', '☮', '฿', '≦', '♬', '✧', '〉', '-', '⌂', '✖', '・', '◕', '※', '‖', '◀', '‰', '\\x97', '↺', '∆', '┘', '┬', '╬', '،', '⌘', '⊂', '>', '〈', '⎙', '?', '☠', '⇐', '▫', '∗', '∈', '≠', '♀', '♔', '˚', '℗', '┗', '*', '┼', '❀', '&', '∩', '♂', '‿', '∑', '‣', '➜', '┛', '⇓', '☯', '⊖', '☀', '┳', ';', '∇', '⇑', '✰', '◇', '♯', '☞', '´', '↔', '┏', '。', '◘', '∂', '✌', '♭', '┣', '┴', '┓', '✨', '\\xa0', '˜', '❥', '┫', '℠', '✒', '[', '∫', '\\x93', '≧', ']', '\\x94', '∀', '♛', '\\x96', '∨', '◎', '↻', '⇩', '<', '≫', '✩', '✪', '♕', '؟', '₤', '☛', '╮', '␊', '+', '┈', '%', '╋', '▽', '⇨', '┻', '⊗', '£', '।', '▂', '✯', '▇', '_', '➤', '✞', '=', '▷', '△', '◙', '▅', '✝', '∧', '␉', '☭', '┊', '╯', '☾', '➔', '∴', '\\x92', '▃', '↳', '^', '׳', '➢', '╭', '➡', '@', '⊙', '☢', '˝', '∏', '„', '∥', '❝', '☐', '▆', '╱', '⋙', '๏', '☁', '⇔', '▔', '\\x91', '➚', '◡', '╰', '\\x85', '♢', '˙', '۞', '✘', '✮', '☑', '⋆', 'ⓘ', '❒', '☣', '✉', '⌊', '➠', '∣', '❑', '◢', 'ⓒ', '\\x80', '〒', '∕', '▮', '⦿', '✫', '✚', '⋯', '♩', '☂', '❞', '‗', '܂', '☜','‾', '✜', '╲', '∘', '⟩', '\', '⟨', '·', '✗', '♚', '∅', 'ⓔ', '◣', '͡', '‛', '❦', '◠', '✄', '❄', '∃', '␣', '≪', '「', '≅', '◯', '☽', '∎', '」', '❧', '̅', 'ⓐ', '↘', '⚓', '▣', '˘', '∪', '⇢', '✍', '⊥', '#', '⎯', '↠', '۩', '☰', '◥', '⊆', '✽', '⚡', '↪', '❁', '☹', '◼', '☃', '◤', '❏', 'ⓢ', '⊱', '➝', '̣', '✡', '∠', '`', '▴', '┤', '∝', '♏', 'ⓐ', '✎', ';', '', ''', '❣', '✂', '✤', 'ⓞ', '☪', '✴', '⌒', '˛', '♒', '$', '✶', '▻', 'ⓔ', '◌', '◈', '❚', '❂', '₩', '◉', '╜', '̃', '✱', '╖', '❉', 'ⓡ', '↗', 'ⓣ', '♻', '➽', '׀', '✲', '✬', '☉', '▉', '≒', '☥', '⌐', '♨', '✕', 'ⓝ', '⊰', '❘', '"', '⇧', '̵', '➪', '▁', '▏', '⊃', 'ⓛ', '‚', '♰', '́', '✏', '⏑', '̶', 'ⓢ', '⩾', '¢', '❍', '≃', '⋰', '♋', '、', '̂', '❋', '✳', 'ⓤ', '╤', '▕', '⌣', '✸', '℮', '⁺', '▨', '╨', 'ⓥ', '♈', '❃', '☝', '✻', '⊇', '≻', '♘', '♞', '◂', '✟', '⌠', '✠', '☚', '✥', '❊', 'ⓒ', '⌈', '❅', 'ⓡ', '♧', 'ⓞ', '▭', '❱', 'ⓣ', '∟', '☕', '♺', '∵', '⍝', 'ⓑ', '✵', '✣', '٭', '♆', 'ⓘ', '∶', '⚜', '◞', '்', '✹', '➥', '↕', '̳', '∷', '✋', '➧', '∋', '̿', 'ͧ', '┅', '⥤', '⬆', '⋱', '☄', '↖', '⋮', '۔', '♌', 'ⓛ', '╕', '♓', '❯', '♍', '▋', '✺', '⭐', '✾', '♊', '➣', '▿', 'ⓑ', '♉', '⏠', '◾', '▹', '⩽', '↦', '╥', '⍵', '⌋', '։', '➨', '∮', '⇥', 'ⓗ', 'ⓓ', '⁻', '⎝', '⌥', '⌉', '◔', '◑', '✼', '♎', '♐', '╪', '⊚', '☒', '⇤', 'ⓜ', '⎠', '◐', '⚠', '╞', '◗', '⎕', 'ⓨ', '☟', 'ⓟ', '♟', '❈', '↬', 'ⓓ', '◻', '♮', '❙', '♤', '∉', '؛', '⁂', 'ⓝ', '־', '♑', '╫', '╓', '╳', '⬅', '☔', '☸', '┄', '╧', '׃', '⎢', '❆', '⋄', '⚫', '̏', '☏', '➞', '͂', '␙', 'ⓤ', '◟', '̊', '⚐', '✙', '↙', '̾', '℘', '✷', '⍺', '❌', '⊢', '▵', '✅', 'ⓖ', '☨', '▰', '╡', 'ⓜ', '☤', '∽', '╘', '˹', '↨', '♙', '⬇', '♱', '⌡', '⠀', '╛', '❕', '┉', 'ⓟ', '̀', '♖', 'ⓚ', '┆', '⎜', '◜', '⚾', '⤴', '✇', '╟', '⎛', '☩', '➲', '➟', 'ⓥ', 'ⓗ', '⏝', '◃', '╢', '↯', '✆', '˃', '⍴', '❇', '⚽', '╒', '̸', '♜', '☓', '➳', '⇄', '☬', '⚑', '✐', '⌃', '◅', '▢', '❐', '∊', '☈', '॥', '⎮', '▩', 'ு', '⊹', '‵', '␔', '☊', '➸', '̌', '☿', '⇉', '⊳', '╙', 'ⓦ', '⇣', '{', '̄', '↝', '⎟', '▍', '❗', '״', '΄', '▞', '◁', '⛄', '⇝', '⎪', '♁', '⇠', '☇', '✊', 'ி', '}', '⭕', '➘', '⁀', '☙', '❛', '❓', '⟲', '⇀', '≲', 'ⓕ', '⎥', '\\u06dd', 'ͤ', '₋', '̱', '̎', '♝', '≳', '▙', '➭', '܀', 'ⓖ', '⇛', '▊', '⇗', '̷', '⇱', '℅', 'ⓧ', '⚛', '̐', '̕', '⇌', '␀', '≌', 'ⓦ', '⊤', '̓', '☦', 'ⓕ', '▜', '➙', 'ⓨ', '⌨', '◮', '☷', '◍', 'ⓚ', '≔', '⏩', '⍳', '℞', '┋', '˻', '▚', '≺', 'ْ', '▟', '➻', '̪', '⏪', '̉', '⎞', '┇', '⍟', '⇪', '▎', '⇦', '␝', '⤷', '≖', '⟶', '♗', '̴', '♄', 'ͨ', '̈', '❜', '̡', '▛', '✁', '➩', 'ா', '˂', '↥', '⏎', '⎷', '̲', '➖', '↲', '⩵', '̗', '❢', \n '≎', '⚔', '⇇', '̑', '⊿', '̖', '☍', '➹', '⥊', '⁁', '✢']\n\ndef clean_punct(x):\n x = str(x)\n for punct in puncts:\n if punct in x:\n x = x.replace(punct, ' ')\n return x\n\nmispell_dict = {'colour': 'color', 'centre': 'center', 'favourite': 'favorite', 'travelling': 'traveling', 'counselling': 'counseling', 'theatre': 'theater', 'cancelled': 'canceled', 'labour': 'labor', 'organisation': 'organization', 'wwii': 'world war 2', 'citicise': 'criticize', 'youtu ': 'youtube ', 'Qoura': 'Quora', 'sallary': 'salary', 'Whta': 'What', 'narcisist': 'narcissist', 'howdo': 'how do', 'whatare': 'what are', 'howcan': 'how can', 'howmuch': 'how much', 'howmany': 'how many', 'whydo': 'why do', 'doI': 'do I', 'theBest': 'the best', 'howdoes': 'how does', 'mastrubation': 'masturbation', 'mastrubate': 'masturbate', \"mastrubating\": 'masturbating', 'pennis': 'penis', 'Etherium': 'bitcoin', 'narcissit': 'narcissist', 'bigdata': 'big data', '2k17': '2017', '2k18': '2018', 'qouta': 'quota', 'exboyfriend': 'ex boyfriend', 'airhostess': 'air hostess', \"whst\": 'what', 'watsapp': 'whatsapp', 'demonitisation': 'demonetization', 'demonitization': 'demonetization', 'demonetisation': 'demonetization', \n 'electroneum':'bitcoin','nanodegree':'degree','hotstar':'star','dream11':'dream','ftre':'fire','tensorflow':'framework','unocoin':'bitcoin',\n 'lnmiit':'limit','unacademy':'academy','altcoin':'bitcoin','altcoins':'bitcoin','litecoin':'bitcoin','coinbase':'bitcoin','cryptocurency':'cryptocurrency',\n 'simpliv':'simple','quoras':'quora','schizoids':'psychopath','remainers':'remainder','twinflame':'soulmate','quorans':'quora','brexit':'demonetized', 'iiest':'institute','dceu':'comics','pessat':'exam','uceed':'college','bhakts':'devotee','boruto':'anime','cryptocoin':'bitcoin','blockchains':'blockchain','fiancee':'fiance','redmi':'smartphone','oneplus':'smartphone','qoura':'quora','deepmind':'framework','ryzen':'cpu','whattsapp':'whatsapp',\n 'undertale':'adventure','zenfone':'smartphone','cryptocurencies':'cryptocurrencies','koinex':'bitcoin','zebpay':'bitcoin','binance':'bitcoin','whtsapp':'whatsapp',\n 'reactjs':'framework','bittrex':'bitcoin','bitconnect':'bitcoin','bitfinex':'bitcoin','yourquote':'your quote','whyis':'why is','jiophone':'smartphone',\n 'dogecoin':'bitcoin','onecoin':'bitcoin','poloniex':'bitcoin','7700k':'cpu','angular2':'framework','segwit2x':'bitcoin','hashflare':'bitcoin','940mx':'gpu',\n 'openai':'framework','hashflare':'bitcoin','1050ti':'gpu','nearbuy':'near buy','freebitco':'bitcoin','antminer':'bitcoin','filecoin':'bitcoin','whatapp':'whatsapp',\n 'empowr':'empower','1080ti':'gpu','crytocurrency':'cryptocurrency','8700k':'cpu','whatsaap':'whatsapp','g4560':'cpu','payymoney':'pay money',\n 'fuckboys':'fuck boys','intenship':'internship','zcash':'bitcoin','demonatisation':'demonetization','narcicist':'narcissist','mastuburation':'masturbation',\n 'trignometric':'trigonometric','cryptocurreny':'cryptocurrency','howdid':'how did','crytocurrencies':'cryptocurrencies','phycopath':'psychopath',\n 'bytecoin':'bitcoin','possesiveness':'possessiveness','scollege':'college','humanties':'humanities','altacoin':'bitcoin','demonitised':'demonetized',\n 'brasília':'brazilia','accolite':'accolyte','econimics':'economics','varrier':'warrier','quroa':'quora','statergy':'strategy','langague':'language','splatoon':'game','7600k':'cpu','gate2018':'gate 2018','in2018':'in 2018','narcassist':'narcissist','jiocoin':'bitcoin','hnlu':'hulu','7300hq':'cpu','weatern':'western','interledger':'blockchain','deplation':'deflation', 'cryptocurrencies':'cryptocurrency', 'bitcoin':'blockchain cryptocurrency',}\n\ndef correct_mispell(x):\n words = x.split()\n for i in range(0, len(words)):\n if mispell_dict.get(words[i]) is not None:\n words[i] = mispell_dict.get(words[i])\n elif mispell_dict.get(words[i].lower()) is not None:\n words[i] = mispell_dict.get(words[i].lower())\n \n words = \" \".join(words)\n return words\n\ndef remove_stopwords(x):\n x = [word for word in x.split() if word not in STOPWORDS]\n x = ' '.join(x)\n return x\n\ncontraction_mapping = {\n \"I'm\": 'I am', \"I'm'a\": 'I am about to', \"I'm'o\": 'I am going to',\"I've\": 'I have', \"I'll\": 'I will', \"I'll've\": 'I will have', \"I'd\": 'I would', \"I'd've\": 'I would have', \"i'm\": 'i am', \"i'm'a\": 'i am about to', \"i'm'o\": 'i am going to', \"i've\": 'i have', \"i'll\": 'i will', \"i'll've\": 'i will have', \"i'd\": 'i would', \"i'd've\": 'i would have', 'Whatcha': 'What are you', 'whatcha': 'what are you', \"amn't\": 'am not', \"ain't\": 'are not', \"aren't\": 'are not', \"'cause\": 'because', \"can't\": 'can not', \"can't've\": 'can not have', \"could've\": 'could have', \"couldn't\": 'could not', \"couldn't've\": 'could not have', \"daren't\": 'dare not', \"daresn't\": 'dare not', \"dasn't\": 'dare not', \"didn't\": 'did not', 'didn’t': 'did not', \"don't\": 'do not', 'don’t': 'do not', \"doesn't\": 'does not', \"e'er\": 'ever', \"everyone's\": 'everyone is', 'finna': 'fixing to', 'gimme': 'give me', \"gon't\": 'go not', 'gonna': 'going to', 'gotta': 'got to', \"hadn't\": 'had not', \"hadn't've\": 'had not have', \"hasn't\": 'has not', \"haven't\": 'have not', \"he've\": 'he have', \"he's\": 'he is', \"he'll\": 'he will', \"he'll've\": 'he will have', \"he'd\": 'he would', \"he'd've\": 'he would have', \"here's\": 'here is', \"how're\": 'how are', \"how'd\": 'how did', \"how'd'y\": 'how do you', \"how's\": 'how is', \"how'll\": 'how will', \"isn't\": 'is not', \"it's\": 'it is', \"'tis\": 'it is', \"'twas\": 'it was', \"it'll\": 'it will', \"it'll've\": 'it will have', \"it'd\": 'it would', \"it'd've\": 'it would have', 'kinda': 'kind of', \"let's\": 'let us', 'luv': 'love', \"ma'am\": 'madam', \"may've\": 'may have', \"mayn't\": 'may not', \"might've\": 'might have', \"mightn't\": 'might not', \"mightn't've\": 'might not have', \"must've\": 'must have', \"mustn't\": 'must not', \"mustn't've\": 'must not have', \"needn't\": 'need not', \"needn't've\": 'need not have', \"ne'er\": 'never', \"o'\": 'of', \"o'clock\": 'of the clock', \"ol'\": 'old', \"oughtn't\": 'ought not', \"oughtn't've\": 'ought not have', \"o'er\": 'over', \"shan't\": 'shall not', \"sha'n't\": 'shall not', \"shalln't\": 'shall not', \"shan't've\": 'shall not have', \"she's\": 'she is', \"she'll\": 'she will', \"she'd\": 'she would', \"she'd've\": 'she would have', \"should've\": 'should have', \"shouldn't\": 'should not', \"shouldn't've\": 'should not have', \"so've\": 'so have', \"so's\": 'so is', \"somebody's\": 'somebody is', \"someone's\": 'someone is', \"something's\": 'something is', 'sux': 'sucks', \"that're\": 'that are', \"that's\": 'that is', \"that'll\": 'that will', \"that'd\": 'that would', \"that'd've\": 'that would have', 'em': 'them', \"there're\": 'there are', \"there's\": 'there is', \"there'll\": 'there will', \"there'd\": 'there would', \"there'd've\": 'there would have', \"these're\": 'these are', \"they're\": 'they are', \"they've\": 'they have', \"they'll\": 'they will', \"they'll've\": 'they will have', \"they'd\": 'they would', \"they'd've\": 'they would have', \"this's\": 'this is', \"those're\": 'those are', \"to've\": 'to have', 'wanna': 'want to', \"wasn't\": 'was not', \"we're\": 'we are', \"we've\": 'we have', \"we'll\": 'we will', \"we'll've\": 'we will have', \"we'd\": 'we would', \"we'd've\": 'we would have', \"weren't\": 'were not', \"what're\": 'what are', \"what'd\": 'what did', \"what've\": 'what have', \"what's\": 'what is', \"what'll\": 'what will', \"what'll've\": 'what will have', \"when've\": 'when have', \"when's\": 'when is', \"where're\": 'where are', \"where'd\": 'where did', \"where've\": 'where have', \"where's\": 'where is', \"which's\": 'which is', \"who're\": 'who are', \"who've\": 'who have', \"who's\": 'who is', \"who'll\": 'who will', \"who'll've\": 'who will have', \"who'd\": 'who would', \"who'd've\": 'who would have', \"why're\": 'why are', \"why'd\": 'why did', \"why've\": 'why have', \"why's\": 'why is', \"will've\": 'will have', \"won't\": 'will not', \"won't've\": 'will not have', \"would've\": 'would have', \"wouldn't\": 'would not', \"wouldn't've\": 'would not have',\n \"y'all\": 'you all', \"y'all're\": 'you all are', \"y'all've\": 'you all have', \"y'all'd\": 'you all would', \"y'all'd've\": 'you all would have', \"you're\": 'you are', \"you've\": 'you have', \"you'll've\": 'you shall have', \"you'll\": 'you will', \"you'd\": 'you would', \"you'd've\": 'you would have', 'jan.': 'january', 'feb.': 'february', 'mar.': 'march', 'apr.': 'april', 'jun.': 'june', 'jul.': 'july', 'aug.': 'august', 'sep.': 'september', 'oct.': 'october', 'nov.': 'november', 'dec.': 'december', 'I’m': 'I am', 'I’m’a': 'I am about to', 'I’m’o': 'I am going to', 'I’ve': 'I have', 'I’ll': 'I will', 'I’ll’ve': 'I will have', 'I’d': 'I would', 'I’d’ve': 'I would have', 'i’m': 'i am', 'i’m’a': 'i am about to', 'i’m’o': 'i am going to', 'i’ve': 'i have', 'i’ll': 'i will', 'i’ll’ve': 'i will have', 'i’d': 'i would', 'i’d’ve': 'i would have', 'amn’t': 'am not', 'ain’t': 'are not','aren’t': 'are not','’cause': 'because','can’t': 'can not','can’t’ve': 'can not have','could’ve': 'could have','couldn’t': 'could not','couldn’t’ve': 'could not have','daren’t': 'dare not','daresn’t': 'dare not','dasn’t': 'dare not','doesn’t': 'does not','e’er': 'ever','everyone’s': 'everyone is','gon’t': 'go not','hadn’t': 'had not','hadn’t’ve': 'had not have','hasn’t': 'has not','haven’t': 'have not','he’ve': 'he have','he’s': 'he is','he’ll': 'he will','he’ll’ve': 'he will have','he’d': 'he would','he’d’ve': 'he would have','here’s': 'here is','how’re': 'how are','how’d': 'how did','how’d’y': 'how do you','how’s': 'how is','how’ll': 'how will',\n 'isn’t': 'is not','it’s': 'it is','’tis': 'it is','’twas': 'it was','it’ll': 'it will','it’ll’ve': 'it will have','it’d': 'it would','it’d’ve': 'it would have','let’s': 'let us','ma’am': 'madam','may’ve': 'may have','mayn’t': 'may not','might’ve': 'might have','mightn’t': 'might not','mightn’t’ve': 'might not have','must’ve': 'must have','mustn’t': 'must not','mustn’t’ve': 'must not have','needn’t': 'need not','needn’t’ve': 'need not have','ne’er': 'never','o’': 'of','o’clock': 'of the clock','ol’': 'old','oughtn’t': 'ought not','oughtn’t’ve': 'ought not have','o’er': 'over',\n 'shan’t': 'shall not','sha’n’t': 'shall not','shalln’t': 'shall not','shan’t’ve': 'shall not have','she’s': 'she is','she’ll': 'she will','she’d': 'she would','she’d’ve': 'she would have','should’ve': 'should have','shouldn’t': 'should not','shouldn’t’ve': 'should not have','so’ve': 'so have','so’s': 'so is','somebody’s': 'somebody is','someone’s': 'someone is','something’s': 'something is','that’re': 'that are','that’s': 'that is','that’ll': 'that will','that’d': 'that would','that’d’ve': 'that would have','there’re': 'there are','there’s': 'there is','there’ll': 'there will','there’d': 'there would','there’d’ve': 'there would have','these’re': 'these are','they’re': 'they are','they’ve': 'they have','they’ll': 'they will','they’ll’ve': 'they will have','they’d': 'they would','they’d’ve': 'they would have','this’s': 'this is','those’re': 'those are','to’ve': 'to have','wasn’t': 'was not','we’re': 'we are','we’ve': 'we have','we’ll': 'we will','we’ll’ve': 'we will have','we’d': 'we would','we’d’ve': 'we would have','weren’t': 'were not','what’re': 'what are','what’d': 'what did','what’ve': 'what have','what’s': 'what is','what’ll': 'what will','what’ll’ve': 'what will have','when’ve': 'when have','when’s': 'when is','where’re': 'where are','where’d': 'where did','where’ve': 'where have','where’s': 'where is','which’s': 'which is','who’re': 'who are','who’ve': 'who have','who’s': 'who is','who’ll': 'who will','who’ll’ve': 'who will have','who’d': 'who would','who’d’ve': 'who would have','why’re': 'why are','why’d': 'why did','why’ve': 'why have','why’s': 'why is','will’ve': 'will have','won’t': 'will not','won’t’ve': 'will not have','would’ve': 'would have','wouldn’t': 'would not','wouldn’t’ve': 'would not have','y’all': 'you all','y’all’re': 'you all are','y’all’ve': 'you all have','y’all’d': 'you all would','y’all’d’ve': 'you all would have','you’re': 'you are','you’ve': 'you have','you’ll’ve': 'you shall have','you’ll': 'you will','you’d': 'you would','you’d’ve': 'you would have'}\n\ndef clean_contractions(text):\n# text = text.lower()\n specials = [\"’\", \"‘\", \"´\", \"`\"]\n for s in specials:\n text = text.replace(s, \"'\")\n \n text = ' '.join([contraction_mapping[t] if t in contraction_mapping else t for t in text.split(\" \")])\n return text\n\nlemmatizer = WordNetLemmatizer()\ndef lemma_text(x):\n x = x.split()\n x = [lemmatizer.lemmatize(word) for word in x]\n x = ' '.join(x)\n return x\n\ndef data_cleaning(x):\n x = clean_tag(x)\n x = clean_punct(x)\n x = correct_mispell(x)\n x = remove_stopwords(x)\n x = clean_contractions(x)\n x = lemma_text(x)\n return x\n\ndef Preprocess(doc):\n corpus=[]\n for text in tqdm(doc):\n text=clean_contractions(text)\n text=correct_mispell(text)\n text=re.sub(r'[^a-z0-9A-Z]',\" \",text)\n text=re.sub(r'[0-9]{1}',\"#\",text)\n text=re.sub(r'[0-9]{2}','##',text)\n text=re.sub(r'[0-9]{3}','###',text)\n text=re.sub(r'[0-9]{4}','####',text)\n text=re.sub(r'[0-9]{5,}','#####',text)\n corpus.append(text)\n return corpus\n","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:06:10.62163Z","iopub.execute_input":"2022-01-08T15:06:10.621857Z","iopub.status.idle":"2022-01-08T15:06:10.726471Z","shell.execute_reply.started":"2022-01-08T15:06:10.621831Z","shell.execute_reply":"2022-01-08T15:06:10.725577Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"","metadata":{}},{"cell_type":"code","source":"# TIỀN XỬ LÝ CÁC TẬP DỮ LIỆU\n\ntqdm.pandas(desc=\"progress-bar\")\ndf_test['question_text_cleaned'] = df_test['question_text'].progress_map(lambda x: data_cleaning(x))\ndf_train['question_text_cleaned'] = df_train['question_text'].progress_map(lambda x: data_cleaning(x))\n\ndf_train.head(5)","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:06:10.727576Z","iopub.execute_input":"2022-01-08T15:06:10.727831Z","iopub.status.idle":"2022-01-08T15:07:59.206147Z","shell.execute_reply.started":"2022-01-08T15:06:10.727794Z","shell.execute_reply":"2022-01-08T15:07:59.205307Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **3. Build tập vocab**","metadata":{}},{"cell_type":"markdown","source":"Ở đây em sẽ cố định sử dụng thằng **Google News** làm tiêu chuẩn
\nKiểm tra word embeddings đã giải nén với **Google News** đính kèm trong file embeddings.zip
\nĐịnh nghĩa các hàm để build vocab từ file **Google News** và hàm kiểm tra độ bao phủ của vocab đối với tập dữ liệu đã được preprocess
\n
\nTrong bài này, em sẽ giải nén tệp embedding để sử dụng tập các vector với các từ cho sẵn
\nCác từ trong file embeddings đều đính kèm một vector, và em sẽ xây ma trận embeddings dựa vào file embeddings đó\n\nFile **Google News** có kích thước khá nhỏ: ```3.4G``` nhưng nó lại ở dạng binary của word embeddings nên đã có thư viện KeyedVector hỗ trợ và việc load khá nhanh nên em sẽ sử dụng thằng **Google News** này làm tham chiếu cho các embeddings khác trong tương lai
\nỞ dưới em sẽ định nghĩa các hàm build ```vocab``` và check độ phủ
\nDo embeddings là file có word đính kèm vector mô tả cho nó nên em sẽ lookup các từ có trong câu với file embeddings và tìm vector của chúng\n\nXây dựng tập vocab và kiểm tra độ bao phủ của tập vocab với tập vocab của pretrained model từ Google News
\nTrong block code này em sẽ xây tập vocab dựa trên bộ dữ liệu được xử lý với hàm preprocess thứ nhất là ```data_clean()```\n\nVới hàm preprocess thứ nhất là ```data_clean()``` thì thầy có thể thấy kết quả độ bao phủ đạt **81.04%**, hơi thấp một chút dù dữ liệu đã được xử lý từ trước
\nNhưng tệ hại là tập vocab chỉ bao phủ **25.40%** corpus
\n**Nhận xét:**
\nCó thể là do việc đụng chạm tới nhiều từ trong câu khi loại bỏ nó, và sửa lỗi sai chính tả. Điều này đã khiến giảm đi đáng kể số lượng các từ được tìm thấy trong file pretrained\\\n**Giải pháp:**
\nSử dụng một hàm Preprocess mới mà ít đụng chạm tới các từ, chỉ xử lý một cách đơn giản các câu\n\nTrong block code này, em sẽ sử dụng hàm Preprocess thứ 2 (hàm process đơn giản hơn)\nNhư thầy có thể thấy hiệu quả được cải thiện một cách rõ rệt:\n- Độ phủ của vocab với corpus tăng gấp **2.5 lần** lên **61.37%**\n- Độ phủ tăng lên **90.81%**, một con số khá ấn tượng\n\nNếu như chuyển các từ về dạng ```lowercase``` thì 2 con số tương đương là **38.85%** với corpus và **89.47%** với vocab.
\nNgười Anh đặt cái tôi của họ rất cao, nên trong tất cả các câu văn của họ thì từ 'I' (chỉ bản thân người nói) luôn được đặt ở trạng thái in hoa ```uppercase```nên nếu chúng ta chuẩn hoá các từ về ```lowercase``` thì sẽ không lookup được từ đó trong file pretrained embeddings và sẽ gây ra hiện tượng thiếu sót trong ma trận embeddings mà chúng ta chuẩn bị xây dựng\n\nTập pretrained **Google News** dù độ phủ khá cao nhưng số lượng từ nằm ngoài tập embeddings khá là lớn khi lên tới 99931 từ
\nVà cần phải có sự cải thiện về số lượng từ ```out_of_vocab``` nếu không thì hiệu quả của model sẽ kém.","metadata":{}},{"cell_type":"code","source":"### unzipping all the pretrained embeddings\n!unzip ../input/quora-insincere-questions-classification/embeddings.zip\n\n!du -h ./\n\n### Loading tập Google News Pretrained Embeddings vào bộ nhớ\nfile_name=\"./GoogleNews-vectors-negative300/GoogleNews-vectors-negative300.bin\"\nmodel_embed=KeyedVectors.load_word2vec_format(file_name,binary=True)\n# model_embed = load_embed1('./glove.840B.300d/glove.840B.300d.txt')\n\n### Xây dựng tập từ vựng dựa trên dữ liệu của tập Google News\ndef vocab_build(corpus):\n vocab={}\n for text in tqdm(corpus):\n for word in text.split():\n try:\n vocab[word]+=1\n except KeyError:\n vocab[word]=1\n return vocab\n\n\n### Kiểm tra tập Vocabulary xem tập vocab đó bao phủ bao nhiêu phần trăm tập dữ liệu của mình\ndef check_voc(vocab,model):\n embed_words=[]\n out_vocab={}\n total_words=0\n total_text=0\n for i in tqdm(vocab):\n try:\n vec=model[i]\n embed_words.append(vec)\n total_words+=vocab[i]\n except KeyError:\n out_vocab[i]=vocab[i]\n total_text+=vocab[i]\n print(\"The {:.2f}% of vocabularies have Covered of corpus\".format(100*len(embed_words)/len(vocab)))\n print(\"The {:.2f}% of total text had coverded \".format((100*total_words/(total_words+total_text))))\n return out_vocab\n\n### xây tập vocab và kiểm tra độ phủ của tập vocab với dữ liệu đã được xử lý\ntotal_text=pd.concat([df_train.question_text_cleaned,df_test.question_text_cleaned])\nvocabulary=vocab_build(total_text)\noov=check_voc(vocabulary,model_embed) #oov: out of vocab\n\ndf_test['question_text_cleaned_2'] = Preprocess(df_test['question_text'])\ndf_train['question_text_cleaned_2'] = Preprocess(df_train['question_text'])\ntotal_text_2=pd.concat([df_train.question_text_cleaned_2,df_test.question_text_cleaned_2])\nvocabulary2=vocab_build(total_text_2)\noov2=check_voc(vocabulary2, model_embed)\n\nsort_oov=dict(sorted(oov2.items(), key=operator.itemgetter(1),reverse=True))\ndict(list(sort_oov.items())[:50])\n\ndel oov, oov2,sort_oov,total_text,total_text_2\ngc.collect()\n\ndef get_word_index(vocab):\n word_index=dict((w,i+1) for i,w in enumerate(vocab.keys()))\n return word_index\ndef fit_one_hot(word_index,corpus):\n sent=[]\n for text in tqdm(corpus):\n li=[]\n for word in text.split():\n try:\n li.append(word_index[word])\n except KeyError:\n li.append(0)\n sent.append(li)\n return sent\n\ntrain,val=train_test_split(df_train,test_size=0.2,stratify=df_train.target,random_state=123)\nvocab_size=len(vocabulary2)+1\nmax_len=40\n\nword_index=get_word_index(vocabulary2)\n### Chuẩn bị dữ liệu đã được xử lý\ntrain_text=train['question_text_cleaned_2']\nval_text=val['question_text_cleaned_2']\ntest_text=df_test['question_text_cleaned_2']\n\n### mã hóa câu trong tập train sang dạng onehot cho dễ xử lý\nencodes=fit_one_hot(word_index,train_text)\ntrain_padded=pad_sequences(encodes,maxlen=max_len,padding=\"post\")\n\n### mã hóa câu trong tập validation sang dạng onehot cho dễ xử lý\nencodes_=fit_one_hot(word_index,val_text)\nval_padded=pad_sequences(encodes_,maxlen=max_len,padding=\"post\")\n\n### mã hóa câu trong tập test sang dạng onehot cho dễ xử lý\nencodes__=fit_one_hot(word_index,test_text)\ntest_padded=pad_sequences(encodes__,maxlen=max_len,padding=\"post\")\n\ncount=0\n\nembedding_mat=np.zeros((vocab_size,300))\nfor word,i in tqdm(word_index.items()):\n try:\n vec=model_embed[word]\n embedding_mat[i]=vec\n except KeyError:\n count+=1\n continue\n\nprint(\"Number of Out of Vocabulary\",count)\n","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:07:59.208147Z","iopub.execute_input":"2022-01-08T15:07:59.208391Z","iopub.status.idle":"2022-01-08T15:14:52.481391Z","shell.execute_reply.started":"2022-01-08T15:07:59.208365Z","shell.execute_reply":"2022-01-08T15:14:52.48037Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **4. Chuẩn bị Model**","metadata":{}},{"cell_type":"markdown","source":"**Mô hình LSTM**\n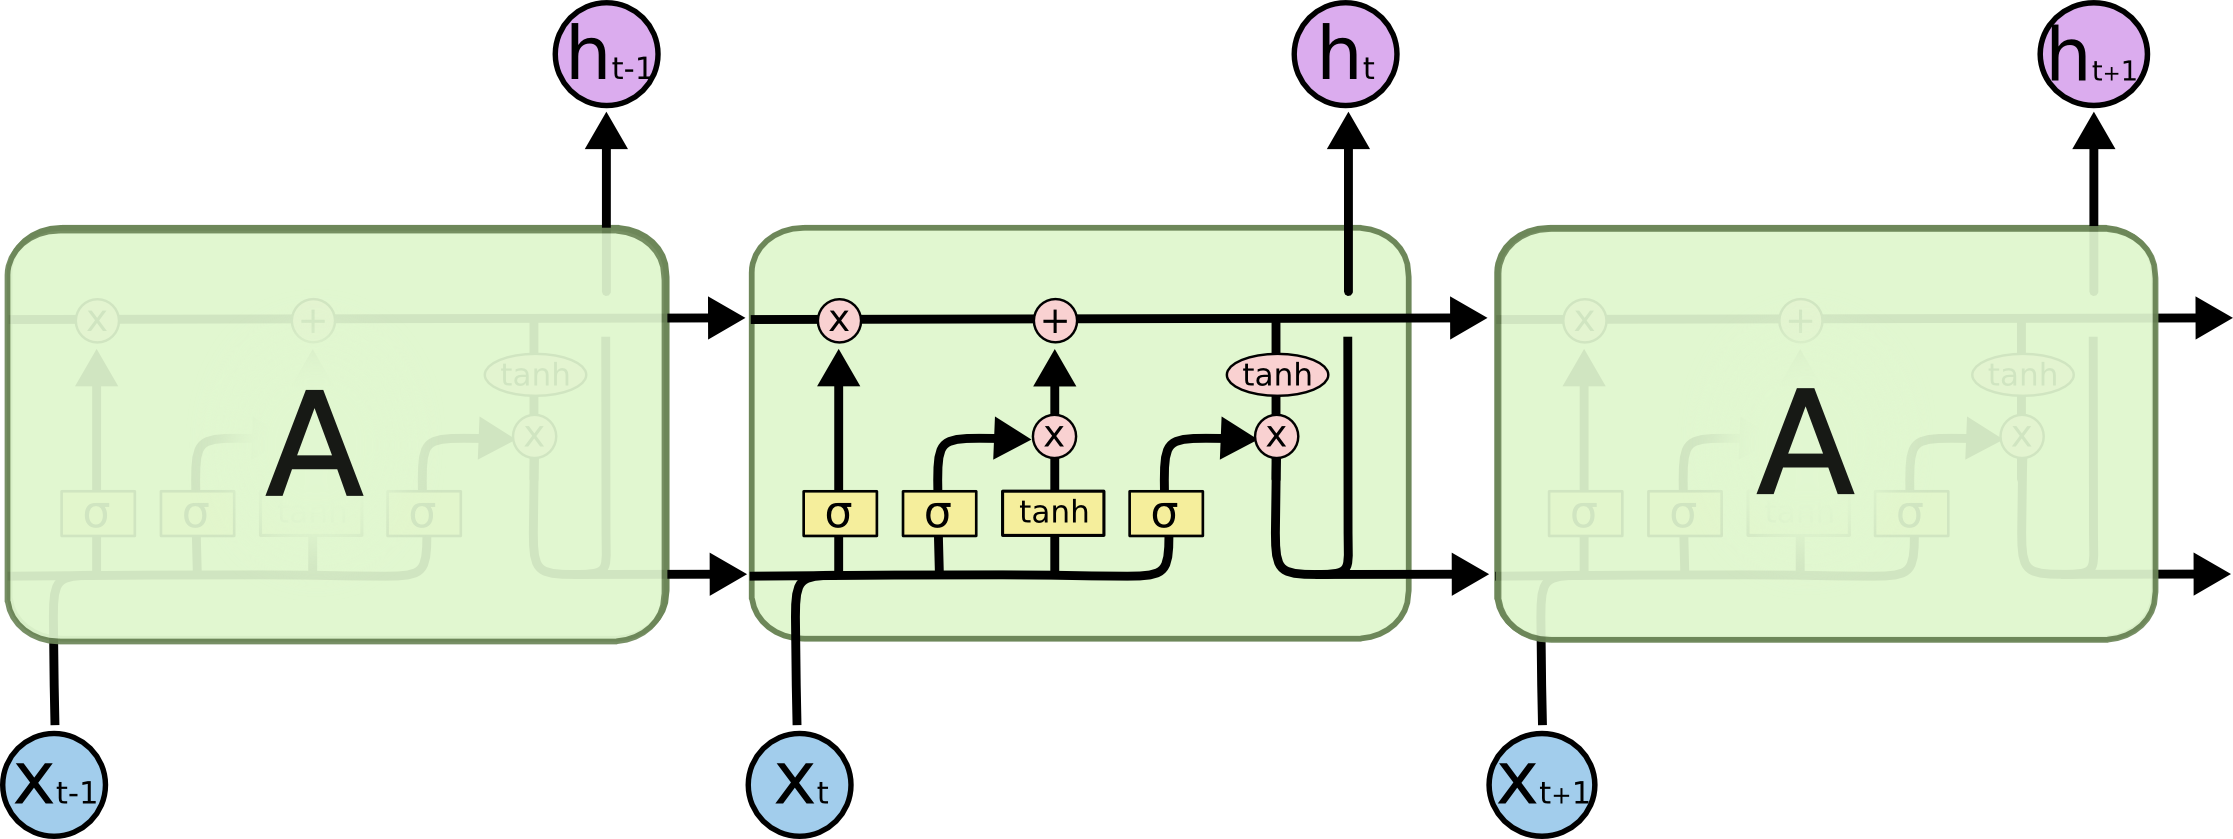\n\n> LSTM cũng có kiến trúc dạng chuỗi như vậy, nhưng các mô-đun trong nó có cấu trúc khác với mạng RNN chuẩn. Thay vì chỉ có một tầng mạng nơ-ron, chúng có tới 4 tầng tương tác với nhau một cách rất đặc biệt\n\nSử dụng embedding layer, mục đích là để embedding sang một không gian mới có chiều nhỏ hơn, giảm chiều dữ liệu
\nBidirectional(LSTM) để xây model LSTM
\nLSTM cũng là mạng CNN nên cần qua 2 lớp là Convo1D và Pool1D (convolution và pooling)","metadata":{}},{"cell_type":"code","source":"def get_model_origin(matrix):\n inp = Input(shape=(max_len,))\n x = Embedding(vocab_size,300,weights=[matrix],input_length=max_len,trainable=False)(inp)\n x = Bidirectional(LSTM(128, return_sequences=True))(x)\n x = Conv1D(64,3,activation=\"relu\")(x)\n x = GlobalMaxPool1D()(x)\n x = Dense(128, activation=\"relu\")(x)\n x = Dropout(0.2)(x)\n x = Dense(1, activation=\"sigmoid\")(x)\n model = Model(inputs=inp, outputs=x)\n return model\n\nopt=Adam(learning_rate=0.001)\nBATCH_SIZE = 1024\nbin_loss=tf.keras.losses.BinaryCrossentropy(from_logits=False, label_smoothing=0, name='binary_crossentropy')\n\n### Xác định điểm callback để giảm learning rate, và restore lại trọng số tốt nhất kề trước \nearly_stopping=tf.keras.callbacks.EarlyStopping(monitor=\"val_loss\",patience=3,mode=\"min\",restore_best_weights=True)\n\n### Giảm learning rate khi model không được cải thiên (càng học càng ngu)\nreduce_lr=tf.keras.callbacks.ReduceLROnPlateau( monitor=\"val_loss\", factor=0.2, patience=2, verbose=1, mode=\"auto\")\n\nmy_callbacks=[early_stopping,reduce_lr]\n\nstrategy = None\n\ntry:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver.connect() # TPU detection\n strategy = tf.distribute.TPUStrategy(tpu)\n print('Use TPU')\nexcept ValueError:\n if len(tf.config.list_physical_devices('GPU')) > 0:\n strategy = tf.distribute.MirroredStrategy()\n print('Use GPU')\n else:\n strategy = tf.distribute.get_strategy()\n print('Use CPU')","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:14:52.482601Z","iopub.execute_input":"2022-01-08T15:14:52.48282Z","iopub.status.idle":"2022-01-08T15:14:57.926973Z","shell.execute_reply.started":"2022-01-08T15:14:52.482794Z","shell.execute_reply":"2022-01-08T15:14:57.926062Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **5. Huấn luyện và Dự đoán**","metadata":{}},{"cell_type":"markdown","source":"### **a. Thử nghiệm model 1**\nCompile model với 30 epoch cho máu, batch_size để ở mức cao để tận dụng sức mạnh tính toán của TPU và sử dụng với tập validation để validate dữ liệu, truyền vào tham số callback để mô hình càng học càng khôn chứ không được ngu đi
\nMột phần do em có cậu bạn cũng train với bọn Keras nhưng khi f1 score đạt được tốt rồi thì nó bắt đầu triệu chứng ngu đi khi mà loss tằng (overfitting)\n\nIn ra f1 score, ```f1_score``` tốt nhất ở đây là ```0.673``` tức ```67.3%``` ứng với hàm Preprocess thứ 2 tức là không đụng chạm nhiều đến câu hỏi
\nTương ứng là f1_score = ```0.633``` tức ```63.3%``` đối với hàm Preprocess đầu tiên khi loại bỏ ```stop_words```, ```lemma_words```, ...\nNhận xét:\n- Với cách tiếp cận dựa trên pretrained thì việc tiền xử lý dữ liệu quá nhiều thực sự có ảnh hưởng lớn tới hiệu năng của model khi mà nó làm mất đi phần nhiều ý nghĩa các các từ có trong câu hỏi\n- Có thể do cách cài đặt khác nhau nhưng về cơ bản với cách tiếp cận dựa vào pretrained thì ta không nên xử lý nhiễu của dữ liệu nhiều, có chăng là loại bỏ đi các digits, các công thức toán và các đường dẫn liên kết \n\nCó thể thấy được rằng mô hình hoạt động khá hiệu quả với tập **```train```** khi mà ```loss``` giảm đều và ```accuracy``` tăng đều qua các epoch
\nTuy nhiên thì với tập **```test```** lại hoạt động không được hiệu quả khi ```loss``` và ```accuracy``` có hình dạng trồi sụt nhìn như sóng biển. Và tệ hơn là với tập **```test```** thì ```loss``` về các epoch cuối lại tăng khá cao.
\nVậy thì có thể kết luận là do **model** đã xây dựng **hoạt động chưa hiệu quả**, cần phải xem xét lại
","metadata":{}},{"cell_type":"code","source":"# THỬ NGHIỆM MODEL 1\n\nwith strategy.scope():\n google_model = get_model_origin(embedding_mat)\n google_model.compile(loss=bin_loss, optimizer=opt, metrics=['accuracy'])\nhistory=google_model.fit(train_padded, train.target, batch_size=BATCH_SIZE, epochs=30, validation_data=(val_padded, val.target),callbacks=my_callbacks)\n\n# summarize history for loss\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 1)\nplt.plot(history.history['loss'])\nplt.plot(history.history['val_loss'])\nplt.title('model loss')\nplt.ylabel('loss')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\n# plt.show()\n# summarize history for accuracy\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 2)\nplt.plot(history.history['accuracy'])\nplt.plot(history.history['val_accuracy'])\nplt.title('model accuracy')\nplt.ylabel('accuracy')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\nplt.show()\n\ngoogle_y_pre=google_model.predict(val_padded, verbose=1)\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(google_y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(google_y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(google_y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\ndel model_embed, history, best_score, best_thresh, google_model, google_y_pre\ngc.collect()","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:14:57.928989Z","iopub.execute_input":"2022-01-08T15:14:57.929326Z","iopub.status.idle":"2022-01-08T15:19:28.494233Z","shell.execute_reply.started":"2022-01-08T15:14:57.929284Z","shell.execute_reply":"2022-01-08T15:19:28.493377Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# THỬ NGHIỆM MODEL 2\n\ndef get_model(matrix):\n inp = Input(shape=(max_len,))\n x = Embedding(vocab_size, 300, weights=[matrix], trainable=False)(inp)\n x = SpatialDropout1D(0.3)(x)\n x1 = Bidirectional(LSTM(256, return_sequences=True))(x)\n x2 = Bidirectional(GRU(128, return_sequences=True))(x1)\n max_pool1 = GlobalMaxPooling1D()(x1)\n max_pool2 = GlobalMaxPooling1D()(x2)\n conc = Concatenate()([max_pool1, max_pool2])\n predictions = Dense(1, activation='sigmoid')(conc)\n model = Model(inputs=inp, outputs=predictions)\n adam = optimizers.Adam(lr=0.001)\n model.compile(optimizer=adam, loss='binary_crossentropy', metrics=['accuracy'])\n return model\n\nstrategy = None\n\ntry:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver.connect() # TPU detection\n strategy = tf.distribute.TPUStrategy(tpu)\n print('Use TPU')\nexcept ValueError:\n if len(tf.config.list_physical_devices('GPU')) > 0:\n strategy = tf.distribute.MirroredStrategy()\n print('Use GPU')\n else:\n strategy = tf.distribute.get_strategy()\n print('Use CPU')\n \nwith strategy.scope():\n google_model = get_model(embedding_mat)\n google_model.compile(loss=bin_loss, optimizer=Adam(lr=0.001), metrics=['accuracy'])\nhistory=google_model.fit(train_padded, train.target, batch_size=BATCH_SIZE, epochs=30, validation_data=(val_padded, val.target),callbacks=my_callbacks)\n\n# summarize history for loss\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 1)\nplt.plot(history.history['loss'])\nplt.plot(history.history['val_loss'])\nplt.title('model loss')\nplt.ylabel('loss')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\n# plt.show()\n# summarize history for accuracy\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 2)\nplt.plot(history.history['accuracy'])\nplt.plot(history.history['val_accuracy'])\nplt.title('model accuracy')\nplt.ylabel('accuracy')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\nplt.show()\n\ngoogle_y_pre=google_model.predict(val_padded, verbose=1)\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(google_y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(google_y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(google_y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\nthreshold=best_thresh\ngoogle_y_test_pre=google_model.predict(test_padded, batch_size=BATCH_SIZE, verbose=1)\ngoogle_y_test_pre=(google_y_test_pre>thresh).astype(int)\n\ndel embedding_mat, history, best_score, best_thresh\ngc.collect()","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:19:28.495371Z","iopub.execute_input":"2022-01-08T15:19:28.495576Z","iopub.status.idle":"2022-01-08T15:26:29.331583Z","shell.execute_reply.started":"2022-01-08T15:19:28.495553Z","shell.execute_reply":"2022-01-08T15:26:29.330486Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# **6. So sánh, mở rộng**\nDo sử dụng 1 pretrained là **Google News** nên kết quả thu được ở mức là **```0.68x``` (x<=3)** f1_score
\n
\nBởi vì 3 thằng còn lại (không phải **Google News**) đều không ở dạng binary và không phải ở dạng chuẩn word_vector nên không đọc được bằng KeyedVectors, em sẽ định nghĩa một hàm để đọc các file embeddings còn lại
\nTuy nhiên do tự định nghĩa nên thời gian load dữ liệu vào biến khá là lâu","metadata":{}},{"cell_type":"code","source":"def load_embed(file):\n def get_coefs(word,*arr):\n return word, np.asarray(arr, dtype='float32')\n\n if file == '../input/embeddings/wiki-news-300d-1M/wiki-news-300d-1M.vec':\n embeddings_index = dict(get_coefs(*o.split(\" \")) for o in open(file) if len(o)>100)\n else:\n embeddings_index = dict(get_coefs(*o.split(\" \")) for o in open(file, encoding='latin'))\n\n return embeddings_index\n\n!tree -h ./\n\nglove_path = './glove.840B.300d/glove.840B.300d.txt'\nparagram_path = './paragram_300_sl999/paragram_300_sl999.txt'\nwiki_path = './wiki-news-300d-1M/wiki-news-300d-1M.vec'\n\nglove_embed = load_embed(glove_path)\nprint(\"\\033[1mGlove Coverage: \\033[0m]\")\noov_glove = check_voc(vocabulary2, glove_embed)","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:26:29.333359Z","iopub.execute_input":"2022-01-08T15:26:29.334255Z","iopub.status.idle":"2022-01-08T15:31:15.665178Z","shell.execute_reply.started":"2022-01-08T15:26:29.334214Z","shell.execute_reply":"2022-01-08T15:31:15.664269Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# GLOVE\n\nstrategy = None\n\ntry:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver.connect() # TPU detection\n strategy = tf.distribute.TPUStrategy(tpu)\n print('Use TPU')\nexcept ValueError:\n if len(tf.config.list_physical_devices('GPU')) > 0:\n strategy = tf.distribute.MirroredStrategy()\n print('Use GPU')\n else:\n strategy = tf.distribute.get_strategy()\n print('Use CPU')\n \ncount=0\nglove_embedding_mat=np.zeros((vocab_size,300))\nfor word,i in tqdm(word_index.items()):\n try:\n vec=glove_embed[word]\n glove_embedding_mat[i]=vec\n except KeyError:\n count+=1\n continue\n\nprint(\"Number of Out of Vocabulary\",count)\n\nwith strategy.scope():\n glove_model = get_model(glove_embedding_mat)\n glove_model.compile(loss=bin_loss, optimizer=Adam(lr=0.001), metrics=['accuracy'])\nglove_history=glove_model.fit(train_padded, train.target, batch_size=BATCH_SIZE, epochs=30, validation_data=(val_padded, val.target),callbacks=my_callbacks)\n\n# summarize history for loss\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 1)\nplt.plot(glove_history.history['loss'])\nplt.plot(glove_history.history['val_loss'])\nplt.title('model loss')\nplt.ylabel('loss')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\n# plt.show()\n# summarize history for accuracy\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 2)\nplt.plot(glove_history.history['accuracy'])\nplt.plot(glove_history.history['val_accuracy'])\nplt.title('model accuracy')\nplt.ylabel('accuracy')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\nplt.show()\n\nglove_y_pre=glove_model.predict(val_padded, verbose=1)\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(glove_y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(glove_y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(glove_y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\nthreshold=best_thresh\nglove_y_test_pre=glove_model.predict(test_padded, batch_size=BATCH_SIZE, verbose=1)\nglove_y_test_pre=(glove_y_test_pre>thresh).astype(int)\n\ndel glove_embed, glove_embedding_mat, glove_history, best_score, best_thresh\ngc.collect()","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:31:15.666986Z","iopub.execute_input":"2022-01-08T15:31:15.667256Z","iopub.status.idle":"2022-01-08T15:36:52.212538Z","shell.execute_reply.started":"2022-01-08T15:31:15.667226Z","shell.execute_reply":"2022-01-08T15:36:52.211905Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# PARAGRAM\nstrategy = None\n\ntry:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver.connect() # TPU detection\n strategy = tf.distribute.TPUStrategy(tpu)\n print('Use TPU')\nexcept ValueError:\n if len(tf.config.list_physical_devices('GPU')) > 0:\n strategy = tf.distribute.MirroredStrategy()\n print('Use GPU')\n else:\n strategy = tf.distribute.get_strategy()\n print('Use CPU')\n \n\nparagram_embed = load_embed(paragram_path)\nprint(\"\\033[1mParagram Coverage: \\033[0m]\")\noov_paragram = check_voc(vocabulary2, paragram_embed)\n\ncount=0\npara_embedding_mat=np.zeros((vocab_size,300))\nfor word,i in tqdm(word_index.items()):\n try:\n vec=paragram_embed[word.lower()]\n para_embedding_mat[i]=vec\n except KeyError:\n count+=1\n continue\n\nprint(\"Number of Out of Vocabulary\",count)\n\nwith strategy.scope():\n para_model = get_model(para_embedding_mat)\n para_model.compile(loss=bin_loss, optimizer=Adam(lr=0.001), metrics=['accuracy'])\npara_history=para_model.fit(train_padded, train.target, batch_size=BATCH_SIZE, epochs=30, validation_data=(val_padded, val.target),callbacks=my_callbacks)\n\n# summarize history for loss\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 1)\nplt.plot(para_history.history['loss'])\nplt.plot(para_history.history['val_loss'])\nplt.title('model loss')\nplt.ylabel('loss')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\n# plt.show()\n# summarize history for accuracy\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 2)\nplt.plot(para_history.history['accuracy'])\nplt.plot(para_history.history['val_accuracy'])\nplt.title('model accuracy')\nplt.ylabel('accuracy')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\nplt.show()\n\npara_y_pre=para_model.predict(val_padded, verbose=1)\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(para_y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(para_y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(para_y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\nthreshold=best_thresh\npara_y_test_pre=para_model.predict(test_padded, batch_size=BATCH_SIZE, verbose=1)\npara_y_test_pre=(para_y_test_pre>thresh).astype(int)\n\ndel paragram_embed, para_embedding_mat, para_history, best_score, best_thresh\ngc.collect()","metadata":{"execution":{"iopub.status.busy":"2022-01-08T15:38:31.047377Z","iopub.execute_input":"2022-01-08T15:38:31.047719Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# WIKI \nstrategy = None\n\ntry:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver.connect() # TPU detection\n strategy = tf.distribute.TPUStrategy(tpu)\n print('Use TPU')\nexcept ValueError:\n if len(tf.config.list_physical_devices('GPU')) > 0:\n strategy = tf.distribute.MirroredStrategy()\n print('Use GPU')\n else:\n strategy = tf.distribute.get_strategy()\n print('Use CPU')\n \n\nwiki_embed = load_embed(wiki_path)\nprint(\"\\033[1mWiki Coverage: \\033[0m]\")\noov_wiki = check_voc(vocabulary2, wiki_embed)\n\ncount=0\nwiki_embedding_mat=np.zeros((vocab_size,300))\nfor word,i in tqdm(word_index.items()):\n try:\n vec=wiki_embed[word]\n wiki_embedding_mat[i]=vec\n except KeyError:\n count+=1\n continue\n\nprint(\"Number of Out of Vocabulary\",count)\n\nwith strategy.scope():\n wiki_model = get_model(wiki_embedding_mat)\n wiki_model.compile(loss=bin_loss, optimizer=Adam(lr=0.001), metrics=['accuracy'])\nwiki_history=wiki_model.fit(train_padded, train.target, batch_size=BATCH_SIZE, epochs=30, validation_data=(val_padded, val.target),callbacks=my_callbacks)\n\n# summarize history for loss\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 1)\nplt.plot(wiki_history.history['loss'])\nplt.plot(wiki_history.history['val_loss'])\nplt.title('model loss')\nplt.ylabel('loss')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\n# plt.show()\n# summarize history for accuracy\nplt.figure(figsize=(15, 5)).add_subplot(1, 2, 2)\nplt.plot(wiki_history.history['accuracy'])\nplt.plot(wiki_history.history['val_accuracy'])\nplt.title('model accuracy')\nplt.ylabel('accuracy')\nplt.xlabel('epoch')\nplt.legend(['train', 'test'], loc='upper left')\nplt.show()\n\nwiki_y_pre=wiki_model.predict(val_padded, verbose=1)\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(wiki_y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(wiki_y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(wiki_y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\nthreshold=best_thresh\nwiki_y_test_pre=wiki_model.predict(test_padded, batch_size=BATCH_SIZE, verbose=1)\nwiki_y_test_pre=(wiki_y_test_pre>thresh).astype(int)\n\ndel wiki_embed, wiki_embedding_mat, wiki_history, best_score, best_thresh\ngc.collect()\n\ny_pre=0.25*(google_y_pre + glove_y_pre + para_y_pre + wiki_y_pre)\n# y_pre=0.20*google_y_pre + 0.35*glove_y_pre + 0.15*para_y_pre + 0.30*wiki_y_pre\nbest_score = 0\nbest_thresh = 0\nfor thresh in np.arange(0.1,0.5,0.01):\n if(best_score < metrics.f1_score(val.target,(y_pre>thresh).astype(int))):\n best_score = metrics.f1_score(val.target,(y_pre>thresh))\n best_thresh = round(thresh, 2)\n print(\"threshold {0:2.2f} f1 score:{1:2.3f}\".format(thresh,metrics.f1_score(val.target,(y_pre>thresh).astype(int))))\nprint(\"\\033[1mBest result {0:2.3f} in thresh_hold {1:2.2f}\\033[0m\".format(best_score, best_thresh))\n\n# y_test_pre = 0.25 * (google_y_test_pre + glove_y_test_pre + para_y_test_pre + wiki_y_test_pre)\ny_test_pre = 0.2*google_y_test_pre + 0.3*glove_y_test_pre + 0.2*para_y_test_pre + 0.3*wiki_y_test_pre\ny_test_pre=(y_test_pre>thresh).astype(int)\n### Tạo File submission\nsubmit=pd.DataFrame()\nsubmit[\"qid\"]=df_test.qid\nsubmit[\"prediction\"]=y_test_pre\nsubmit.to_csv(\"submission.csv\",index=False)\nprint(\"ok\")","metadata":{"trusted":true},"execution_count":null,"outputs":[]}]}