{"cells":[{"metadata":{},"cell_type":"markdown","source":"# Intro\n\n\n#### This is a *work in progress*. Please upvote the kernel to keep this going.\n\nI have tried several public notebooks to find the best way for ensemble. Until now, this was the best outcome.\n\n- The first notebook: https://www.kaggle.com/thebigd8ta/higher-lb-score-by-tuning-mloss-upgrade-1696e2\n- The second notebook: https://www.kaggle.com/zhangxianjue/train-age?scriptVersionId=43259472\n\nNote1: It is important to blend the best of each notebook. So I selected the best version of each notebook.\n\nNote2: I will not be upgrading the code until the end of competition.\n"},{"metadata":{},"cell_type":"markdown","source":"## Ensemble learning\n\nEnsemble learning is the process by which multiple models, such as classifiers or experts, are strategically generated and combined to solve a particular computational intelligence problem. Ensemble learning is primarily used to improve the (classification, prediction, function approximation, etc.)\n\nhe motivation for using ensemble models is to reduce the generalization error of the prediction. As long as the base models are diverse and independent, the prediction error of the model decreases when the ensemble approach is used. The approach seeks the wisdom of crowds in making a prediction. Even though the ensemble model has multiple base models within the model, it acts and performs as a single model. Most of the practical data mining solutions utilize ensemble modeling techniques. \n\n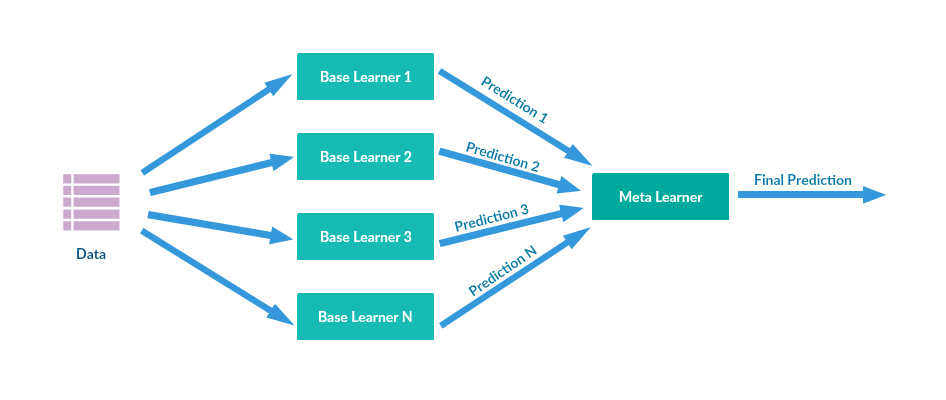"},{"metadata":{},"cell_type":"markdown","source":"# Notebook 1"},{"metadata":{},"cell_type":"markdown","source":"https://www.kaggle.com/thebigd8ta/higher-lb-score-by-tuning-mloss-upgrade-1696e2"},{"metadata":{"_kg_hide-output":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:08.360355Z","iopub.status.busy":"2020-09-12T12:28:08.359543Z","iopub.status.idle":"2020-09-12T12:28:27.81399Z","shell.execute_reply":"2020-09-12T12:28:27.813344Z"},"papermill":{"duration":19.522356,"end_time":"2020-09-12T12:28:27.814105","exception":false,"start_time":"2020-09-12T12:28:08.291749","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"!pip install ../input/kerasapplications/keras-team-keras-applications-3b180cb -f ./ --no-index\n!pip install ../input/efficientnet/efficientnet-1.1.0/ -f ./ --no-index","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:27.960634Z","iopub.status.busy":"2020-09-12T12:28:27.957808Z","iopub.status.idle":"2020-09-12T12:28:34.721077Z","shell.execute_reply":"2020-09-12T12:28:34.722146Z"},"papermill":{"duration":6.839874,"end_time":"2020-09-12T12:28:34.722363","exception":false,"start_time":"2020-09-12T12:28:27.882489","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"import os\nimport cv2\nimport pydicom\nimport pandas as pd\nimport numpy as np \nimport tensorflow as tf \nimport matplotlib.pyplot as plt \nimport random\nfrom tqdm.notebook import tqdm \nfrom sklearn.model_selection import train_test_split, KFold\nfrom sklearn.metrics import mean_absolute_error\nfrom tensorflow_addons.optimizers import RectifiedAdam\nfrom tensorflow.keras import Model\nimport tensorflow.keras.backend as K\nimport tensorflow.keras.layers as L\nimport tensorflow.keras.models as M\nfrom tensorflow.keras.optimizers import Nadam\nimport seaborn as sns\nimport plotly.express as px\nimport plotly.graph_objects as go\nfrom PIL import Image","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:34.940269Z","iopub.status.busy":"2020-09-12T12:28:34.939422Z","iopub.status.idle":"2020-09-12T12:28:34.946161Z","shell.execute_reply":"2020-09-12T12:28:34.947474Z"},"papermill":{"duration":0.127971,"end_time":"2020-09-12T12:28:34.947709","exception":false,"start_time":"2020-09-12T12:28:34.819738","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"def seed_everything(seed=2020):\n random.seed(seed)\n os.environ['PYTHONHASHSEED'] = str(seed)\n np.random.seed(seed)\n tf.random.set_seed(seed)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:35.14144Z","iopub.status.busy":"2020-09-12T12:28:35.140548Z","iopub.status.idle":"2020-09-12T12:28:35.144493Z","shell.execute_reply":"2020-09-12T12:28:35.145146Z"},"papermill":{"duration":0.103193,"end_time":"2020-09-12T12:28:35.145352","exception":false,"start_time":"2020-09-12T12:28:35.042159","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"seed_everything(42)","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:35.320974Z","iopub.status.busy":"2020-09-12T12:28:35.320095Z","iopub.status.idle":"2020-09-12T12:28:38.080919Z","shell.execute_reply":"2020-09-12T12:28:38.08143Z"},"papermill":{"duration":2.859578,"end_time":"2020-09-12T12:28:38.081578","exception":false,"start_time":"2020-09-12T12:28:35.222","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"config = tf.compat.v1.ConfigProto()\nconfig.gpu_options.allow_growth = True\nsession = tf.compat.v1.Session(config=config)","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.068158,"end_time":"2020-09-12T12:28:38.355887","exception":false,"start_time":"2020-09-12T12:28:38.287729","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 2.1. Commit now \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:38.499683Z","iopub.status.busy":"2020-09-12T12:28:38.497886Z","iopub.status.idle":"2020-09-12T12:28:38.500403Z","shell.execute_reply":"2020-09-12T12:28:38.500885Z"},"papermill":{"duration":0.078124,"end_time":"2020-09-12T12:28:38.501006","exception":false,"start_time":"2020-09-12T12:28:38.422882","status":"completed"},"tags":[],"trusted":true},"cell_type":"code","source":"Dropout_model = 0.3856\nFVC_weight = 0.2\nConfidence_weight = 0.2","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.071979,"end_time":"2020-09-12T12:28:46.198548","exception":false,"start_time":"2020-09-12T12:28:46.126569","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 3. Download data, auxiliary functions and model tuning \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:46.360068Z","iopub.status.busy":"2020-09-12T12:28:46.3591Z","iopub.status.idle":"2020-09-12T12:28:46.412005Z","shell.execute_reply":"2020-09-12T12:28:46.411281Z"},"papermill":{"duration":0.140766,"end_time":"2020-09-12T12:28:46.41213","exception":false,"start_time":"2020-09-12T12:28:46.271364","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"train = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/train.csv') ","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:46.568985Z","iopub.status.busy":"2020-09-12T12:28:46.568196Z","iopub.status.idle":"2020-09-12T12:28:46.572137Z","shell.execute_reply":"2020-09-12T12:28:46.571673Z"},"papermill":{"duration":0.087464,"end_time":"2020-09-12T12:28:46.572243","exception":false,"start_time":"2020-09-12T12:28:46.484779","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"def get_tab(df):\n vector = [(df.Age.values[0] - 30) / 30] \n \n if df.Sex.values[0] == 'male':\n vector.append(0)\n else:\n vector.append(1)\n \n if df.SmokingStatus.values[0] == 'Never smoked':\n vector.extend([0,0])\n elif df.SmokingStatus.values[0] == 'Ex-smoker':\n vector.extend([1,1])\n elif df.SmokingStatus.values[0] == 'Currently smokes':\n vector.extend([0,1])\n else:\n vector.extend([1,0])\n return np.array(vector) ","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:46.727139Z","iopub.status.busy":"2020-09-12T12:28:46.726207Z","iopub.status.idle":"2020-09-12T12:28:47.119826Z","shell.execute_reply":"2020-09-12T12:28:47.112652Z"},"papermill":{"duration":0.475289,"end_time":"2020-09-12T12:28:47.119966","exception":false,"start_time":"2020-09-12T12:28:46.644677","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"A = {} \nTAB = {} \nP = [] \nfor i, p in tqdm(enumerate(train.Patient.unique())):\n sub = train.loc[train.Patient == p, :] \n fvc = sub.FVC.values\n weeks = sub.Weeks.values\n c = np.vstack([weeks, np.ones(len(weeks))]).T\n a, b = np.linalg.lstsq(c, fvc)[0]\n \n A[p] = a\n TAB[p] = get_tab(sub)\n P.append(p)","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:47.282492Z","iopub.status.busy":"2020-09-12T12:28:47.28185Z","iopub.status.idle":"2020-09-12T12:28:47.286202Z","shell.execute_reply":"2020-09-12T12:28:47.285731Z"},"papermill":{"duration":0.084567,"end_time":"2020-09-12T12:28:47.286306","exception":false,"start_time":"2020-09-12T12:28:47.201739","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"def get_img(path):\n d = pydicom.dcmread(path)\n return cv2.resize(d.pixel_array / 2**11, (512, 512))","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"execution":{"iopub.execute_input":"2020-09-12T12:28:47.452214Z","iopub.status.busy":"2020-09-12T12:28:47.451276Z","iopub.status.idle":"2020-09-12T12:28:47.454539Z","shell.execute_reply":"2020-09-12T12:28:47.453826Z"},"papermill":{"duration":0.092521,"end_time":"2020-09-12T12:28:47.454652","exception":false,"start_time":"2020-09-12T12:28:47.362131","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"from tensorflow.keras.utils import Sequence\n\nclass IGenerator(Sequence):\n BAD_ID = ['ID00011637202177653955184', 'ID00052637202186188008618']\n def __init__(self, keys, a, tab, batch_size=32):\n self.keys = [k for k in keys if k not in self.BAD_ID]\n self.a = a\n self.tab = tab\n self.batch_size = batch_size\n \n self.train_data = {}\n for p in train.Patient.values:\n self.train_data[p] = os.listdir(f'../input/osic-pulmonary-fibrosis-progression/train/{p}/')\n \n def __len__(self):\n return 1000\n \n def __getitem__(self, idx):\n x = []\n a, tab = [], [] \n keys = np.random.choice(self.keys, size = self.batch_size)\n for k in keys:\n try:\n i = np.random.choice(self.train_data[k], size=1)[0]\n img = get_img(f'../input/osic-pulmonary-fibrosis-progression/train/{k}/{i}')\n x.append(img)\n a.append(self.a[k])\n tab.append(self.tab[k])\n except:\n print(k, i)\n \n x,a,tab = np.array(x), np.array(a), np.array(tab)\n x = np.expand_dims(x, axis=-1)\n return [x, tab] , a","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:28:47.626224Z","iopub.status.busy":"2020-09-12T12:28:47.625218Z","iopub.status.idle":"2020-09-12T12:29:48.4691Z","shell.execute_reply":"2020-09-12T12:29:48.469848Z"},"papermill":{"duration":60.938886,"end_time":"2020-09-12T12:29:48.470055","exception":false,"start_time":"2020-09-12T12:28:47.531169","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"from tensorflow.keras.layers import (\n Dense, Dropout, Activation, Flatten, Input, BatchNormalization, GlobalAveragePooling2D, Add, Conv2D, AveragePooling2D, \n LeakyReLU, Concatenate \n)\nimport efficientnet.tfkeras as efn\n\ndef get_efficientnet(model, shape):\n models_dict = {\n 'b0': efn.EfficientNetB0(input_shape=shape,weights=None,include_top=False),\n 'b1': efn.EfficientNetB1(input_shape=shape,weights=None,include_top=False),\n 'b2': efn.EfficientNetB2(input_shape=shape,weights=None,include_top=False),\n 'b3': efn.EfficientNetB3(input_shape=shape,weights=None,include_top=False),\n 'b4': efn.EfficientNetB4(input_shape=shape,weights=None,include_top=False),\n 'b5': efn.EfficientNetB5(input_shape=shape,weights=None,include_top=False),\n 'b6': efn.EfficientNetB6(input_shape=shape,weights=None,include_top=False),\n 'b7': efn.EfficientNetB7(input_shape=shape,weights=None,include_top=False)\n }\n return models_dict[model]\n\ndef build_model(shape=(512, 512, 1), model_class=None):\n inp = Input(shape=shape)\n base = get_efficientnet(model_class, shape)\n x = base(inp)\n x = GlobalAveragePooling2D()(x)\n inp2 = Input(shape=(4,))\n x2 = tf.keras.layers.GaussianNoise(0.2)(inp2)\n x = Concatenate()([x, x2]) \n x = Dropout(Dropout_model)(x)\n x = Dense(1)(x)\n model = Model([inp, inp2] , x)\n \n weights = [w for w in os.listdir('../input/osic-model-weights') if model_class in w][0]\n model.load_weights('../input/osic-model-weights/' + weights)\n return model\n\nmodel_classes = ['b5'] #['b0','b1','b2','b3',b4','b5','b6','b7']\nmodels = [build_model(shape=(512, 512, 1), model_class=m) for m in model_classes]\nprint('Number of models: ' + str(len(models)))","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:29:48.630722Z","iopub.status.busy":"2020-09-12T12:29:48.628863Z","iopub.status.idle":"2020-09-12T12:29:48.631432Z","shell.execute_reply":"2020-09-12T12:29:48.631934Z"},"papermill":{"duration":0.085723,"end_time":"2020-09-12T12:29:48.632064","exception":false,"start_time":"2020-09-12T12:29:48.546341","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"tr_p, vl_p = train_test_split(P, shuffle=True, train_size = 0.9) ","execution_count":null,"outputs":[]},{"metadata":{"_kg_hide-input":true,"execution":{"iopub.execute_input":"2020-09-12T12:29:48.792372Z","iopub.status.busy":"2020-09-12T12:29:48.791575Z","iopub.status.idle":"2020-09-12T12:29:48.794068Z","shell.execute_reply":"2020-09-12T12:29:48.794556Z"},"papermill":{"duration":0.085692,"end_time":"2020-09-12T12:29:48.794686","exception":false,"start_time":"2020-09-12T12:29:48.708994","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"def score(fvc_true, fvc_pred, sigma):\n sigma_clip = np.maximum(sigma, 69) # changed from 70, trie 66.7 too\n delta = np.abs(fvc_true - fvc_pred)\n delta = np.minimum(delta, 1000)\n sq2 = np.sqrt(2)\n metric = (delta / sigma_clip)*sq2 + np.log(sigma_clip* sq2)\n return np.mean(metric)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:29:48.97801Z","iopub.status.busy":"2020-09-12T12:29:48.970454Z","iopub.status.idle":"2020-09-12T12:47:51.95426Z","shell.execute_reply":"2020-09-12T12:47:51.953478Z"},"papermill":{"duration":1083.083415,"end_time":"2020-09-12T12:47:51.954404","exception":false,"start_time":"2020-09-12T12:29:48.870989","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"subs = []\nfor model in models:\n metric = []\n for q in tqdm(range(1, 10)):\n m = []\n for p in vl_p:\n x = [] \n tab = [] \n\n if p in ['ID00011637202177653955184', 'ID00052637202186188008618']:\n continue\n\n ldir = os.listdir(f'../input/osic-pulmonary-fibrosis-progression/train/{p}/')\n for i in ldir:\n if int(i[:-4]) / len(ldir) < 0.8 and int(i[:-4]) / len(ldir) > 0.15:\n x.append(get_img(f'../input/osic-pulmonary-fibrosis-progression/train/{p}/{i}')) \n tab.append(get_tab(train.loc[train.Patient == p, :])) \n if len(x) < 1:\n continue\n tab = np.array(tab) \n\n x = np.expand_dims(x, axis=-1) \n _a = model.predict([x, tab]) \n a = np.quantile(_a, q / 10)\n\n percent_true = train.Percent.values[train.Patient == p]\n fvc_true = train.FVC.values[train.Patient == p]\n weeks_true = train.Weeks.values[train.Patient == p]\n\n fvc = a * (weeks_true - weeks_true[0]) + fvc_true[0]\n percent = percent_true[0] - a * abs(weeks_true - weeks_true[0])\n m.append(score(fvc_true, fvc, percent))\n print(np.mean(m))\n metric.append(np.mean(m))\n\n q = (np.argmin(metric) + 1)/ 10\n\n sub = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/sample_submission.csv') \n test = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/test.csv') \n A_test, B_test, P_test,W, FVC= {}, {}, {},{},{} \n STD, WEEK = {}, {} \n for p in test.Patient.unique():\n x = [] \n tab = [] \n ldir = os.listdir(f'../input/osic-pulmonary-fibrosis-progression/test/{p}/')\n for i in ldir:\n if int(i[:-4]) / len(ldir) < 0.8 and int(i[:-4]) / len(ldir) > 0.15:\n x.append(get_img(f'../input/osic-pulmonary-fibrosis-progression/test/{p}/{i}')) \n tab.append(get_tab(test.loc[test.Patient == p, :])) \n if len(x) <= 1:\n continue\n tab = np.array(tab) \n\n x = np.expand_dims(x, axis=-1) \n _a = model.predict([x, tab]) \n a = np.quantile(_a, q)\n A_test[p] = a\n B_test[p] = test.FVC.values[test.Patient == p] - a*test.Weeks.values[test.Patient == p]\n P_test[p] = test.Percent.values[test.Patient == p] \n WEEK[p] = test.Weeks.values[test.Patient == p]\n\n for k in sub.Patient_Week.values:\n p, w = k.split('_')\n w = int(w) \n\n fvc = A_test[p] * w + B_test[p]\n sub.loc[sub.Patient_Week == k, 'FVC'] = fvc\n sub.loc[sub.Patient_Week == k, 'Confidence'] = (\n P_test[p] - A_test[p] * abs(WEEK[p] - w) \n ) \n\n _sub = sub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()\n subs.append(_sub)","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.079863,"end_time":"2020-09-12T12:47:52.114959","exception":false,"start_time":"2020-09-12T12:47:52.035096","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 4. Prediction and submission \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"papermill":{"duration":0.080678,"end_time":"2020-09-12T12:47:52.276161","exception":false,"start_time":"2020-09-12T12:47:52.195483","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 4.1 Average prediction \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:52.448178Z","iopub.status.busy":"2020-09-12T12:47:52.44721Z","iopub.status.idle":"2020-09-12T12:47:52.467146Z","shell.execute_reply":"2020-09-12T12:47:52.466194Z"},"papermill":{"duration":0.109202,"end_time":"2020-09-12T12:47:52.467252","exception":false,"start_time":"2020-09-12T12:47:52.35805","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"N = len(subs)\nsub = subs[0].copy() # ref\nsub[\"FVC\"] = 0\nsub[\"Confidence\"] = 0\nfor i in range(N):\n sub[\"FVC\"] += subs[0][\"FVC\"] * (1/N)\n sub[\"Confidence\"] += subs[0][\"Confidence\"] * (1/N)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:52.641614Z","iopub.status.busy":"2020-09-12T12:47:52.639966Z","iopub.status.idle":"2020-09-12T12:47:52.644367Z","shell.execute_reply":"2020-09-12T12:47:52.644941Z"},"papermill":{"duration":0.097753,"end_time":"2020-09-12T12:47:52.645073","exception":false,"start_time":"2020-09-12T12:47:52.54732","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"sub.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:52.823739Z","iopub.status.busy":"2020-09-12T12:47:52.822874Z","iopub.status.idle":"2020-09-12T12:47:52.920526Z","shell.execute_reply":"2020-09-12T12:47:52.919526Z"},"papermill":{"duration":0.184393,"end_time":"2020-09-12T12:47:52.92065","exception":false,"start_time":"2020-09-12T12:47:52.736257","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"sub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].to_csv(\"submission_img.csv\", index=False)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:53.146292Z","iopub.status.busy":"2020-09-12T12:47:53.145444Z","iopub.status.idle":"2020-09-12T12:47:53.15011Z","shell.execute_reply":"2020-09-12T12:47:53.150736Z"},"papermill":{"duration":0.143125,"end_time":"2020-09-12T12:47:53.150908","exception":false,"start_time":"2020-09-12T12:47:53.007783","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"img_sub = sub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.125345,"end_time":"2020-09-12T12:47:53.389035","exception":false,"start_time":"2020-09-12T12:47:53.26369","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 4.2 Osic-Multiple-Quantile-Regression \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:53.582012Z","iopub.status.busy":"2020-09-12T12:47:53.581146Z","iopub.status.idle":"2020-09-12T12:47:53.624256Z","shell.execute_reply":"2020-09-12T12:47:53.623227Z"},"papermill":{"duration":0.135762,"end_time":"2020-09-12T12:47:53.624364","exception":false,"start_time":"2020-09-12T12:47:53.488602","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"ROOT = \"../input/osic-pulmonary-fibrosis-progression\"\nBATCH_SIZE=128\n\ntr = pd.read_csv(f\"{ROOT}/train.csv\")\ntr.drop_duplicates(keep=False, inplace=True, subset=['Patient','Weeks'])\nchunk = pd.read_csv(f\"{ROOT}/test.csv\")\n\nprint(\"add infos\")\nsub = pd.read_csv(f\"{ROOT}/sample_submission.csv\")\nsub['Patient'] = sub['Patient_Week'].apply(lambda x:x.split('_')[0])\nsub['Weeks'] = sub['Patient_Week'].apply(lambda x: int(x.split('_')[-1]))\nsub = sub[['Patient','Weeks','Confidence','Patient_Week']]\nsub = sub.merge(chunk.drop('Weeks', axis=1), on=\"Patient\")","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:53.80252Z","iopub.status.busy":"2020-09-12T12:47:53.795615Z","iopub.status.idle":"2020-09-12T12:47:53.805682Z","shell.execute_reply":"2020-09-12T12:47:53.805122Z"},"papermill":{"duration":0.100374,"end_time":"2020-09-12T12:47:53.805789","exception":false,"start_time":"2020-09-12T12:47:53.705415","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"tr['WHERE'] = 'train'\nchunk['WHERE'] = 'val'\nsub['WHERE'] = 'test'\ndata = tr.append([chunk, sub])","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:53.976303Z","iopub.status.busy":"2020-09-12T12:47:53.975314Z","iopub.status.idle":"2020-09-12T12:47:53.984264Z","shell.execute_reply":"2020-09-12T12:47:53.983643Z"},"papermill":{"duration":0.096105,"end_time":"2020-09-12T12:47:53.984415","exception":false,"start_time":"2020-09-12T12:47:53.88831","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"print(tr.shape, chunk.shape, sub.shape, data.shape)\nprint(tr.Patient.nunique(), chunk.Patient.nunique(), sub.Patient.nunique(), \n data.Patient.nunique())","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:54.158841Z","iopub.status.busy":"2020-09-12T12:47:54.157615Z","iopub.status.idle":"2020-09-12T12:47:54.172277Z","shell.execute_reply":"2020-09-12T12:47:54.171703Z"},"papermill":{"duration":0.1056,"end_time":"2020-09-12T12:47:54.172419","exception":false,"start_time":"2020-09-12T12:47:54.066819","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"data['min_week'] = data['Weeks']\ndata.loc[data.WHERE=='test','min_week'] = np.nan\ndata['min_week'] = data.groupby('Patient')['min_week'].transform('min')","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:54.357574Z","iopub.status.busy":"2020-09-12T12:47:54.356829Z","iopub.status.idle":"2020-09-12T12:47:54.35984Z","shell.execute_reply":"2020-09-12T12:47:54.360277Z"},"papermill":{"duration":0.104379,"end_time":"2020-09-12T12:47:54.360467","exception":false,"start_time":"2020-09-12T12:47:54.256088","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"base = data.loc[data.Weeks == data.min_week]\nbase = base[['Patient','FVC']].copy()\nbase.columns = ['Patient','min_FVC']\nbase['nb'] = 1\nbase['nb'] = base.groupby('Patient')['nb'].transform('cumsum')\nbase = base[base.nb==1]\nbase.drop('nb', axis=1, inplace=True)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:54.5356Z","iopub.status.busy":"2020-09-12T12:47:54.533543Z","iopub.status.idle":"2020-09-12T12:47:54.544498Z","shell.execute_reply":"2020-09-12T12:47:54.543947Z"},"papermill":{"duration":0.100549,"end_time":"2020-09-12T12:47:54.544606","exception":false,"start_time":"2020-09-12T12:47:54.444057","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"data = data.merge(base, on='Patient', how='left')\ndata['base_week'] = data['Weeks'] - data['min_week']\ndel base","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:54.718512Z","iopub.status.busy":"2020-09-12T12:47:54.717571Z","iopub.status.idle":"2020-09-12T12:47:54.724901Z","shell.execute_reply":"2020-09-12T12:47:54.724326Z"},"papermill":{"duration":0.098606,"end_time":"2020-09-12T12:47:54.725009","exception":false,"start_time":"2020-09-12T12:47:54.626403","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"COLS = ['Sex','SmokingStatus'] #,'Age'\nFE = []\nfor col in COLS:\n for mod in data[col].unique():\n FE.append(mod)\n data[mod] = (data[col] == mod).astype(int)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:54.906857Z","iopub.status.busy":"2020-09-12T12:47:54.905941Z","iopub.status.idle":"2020-09-12T12:47:54.908552Z","shell.execute_reply":"2020-09-12T12:47:54.909026Z"},"papermill":{"duration":0.101648,"end_time":"2020-09-12T12:47:54.909161","exception":false,"start_time":"2020-09-12T12:47:54.807513","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"#\ndata['age'] = (data['Age'] - data['Age'].min() ) / ( data['Age'].max() - data['Age'].min() )\ndata['BASE'] = (data['min_FVC'] - data['min_FVC'].min() ) / ( data['min_FVC'].max() - data['min_FVC'].min() )\ndata['week'] = (data['base_week'] - data['base_week'].min() ) / ( data['base_week'].max() - data['base_week'].min() )\ndata['percent'] = (data['Percent'] - data['Percent'].min() ) / ( data['Percent'].max() - data['Percent'].min() )\nFE += ['age','percent','week','BASE']","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:55.087321Z","iopub.status.busy":"2020-09-12T12:47:55.086406Z","iopub.status.idle":"2020-09-12T12:47:55.093187Z","shell.execute_reply":"2020-09-12T12:47:55.093688Z"},"papermill":{"duration":0.100544,"end_time":"2020-09-12T12:47:55.093811","exception":false,"start_time":"2020-09-12T12:47:54.993267","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"tr = data.loc[data.WHERE=='train']\nchunk = data.loc[data.WHERE=='val']\nsub = data.loc[data.WHERE=='test']\ndel data","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:55.266259Z","iopub.status.busy":"2020-09-12T12:47:55.265348Z","iopub.status.idle":"2020-09-12T12:47:55.272003Z","shell.execute_reply":"2020-09-12T12:47:55.271237Z"},"papermill":{"duration":0.095212,"end_time":"2020-09-12T12:47:55.272118","exception":false,"start_time":"2020-09-12T12:47:55.176906","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"tr.shape, chunk.shape, sub.shape","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.08543,"end_time":"2020-09-12T12:47:55.442154","exception":false,"start_time":"2020-09-12T12:47:55.356724","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 4.3 The change of mloss \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:55.631996Z","iopub.status.busy":"2020-09-12T12:47:55.630132Z","iopub.status.idle":"2020-09-12T12:47:55.632704Z","shell.execute_reply":"2020-09-12T12:47:55.633164Z"},"papermill":{"duration":0.108573,"end_time":"2020-09-12T12:47:55.633289","exception":false,"start_time":"2020-09-12T12:47:55.524716","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"C1, C2 = tf.constant(70, dtype='float32'), tf.constant(1000, dtype=\"float32\")\n\ndef score(y_true, y_pred):\n tf.dtypes.cast(y_true, tf.float32)\n tf.dtypes.cast(y_pred, tf.float32)\n sigma = y_pred[:, 2] - y_pred[:, 0]\n fvc_pred = y_pred[:, 1]\n \n #sigma_clip = sigma + C1\n sigma_clip = tf.maximum(sigma, C1)\n delta = tf.abs(y_true[:, 0] - fvc_pred)\n delta = tf.minimum(delta, C2)\n sq2 = tf.sqrt( tf.dtypes.cast(2, dtype=tf.float32) )\n metric = (delta / sigma_clip)*sq2 + tf.math.log(sigma_clip* sq2)\n return K.mean(metric)\n\ndef qloss(y_true, y_pred):\n # Pinball loss for multiple quantiles\n qs = [0.2, 0.50, 0.8]\n q = tf.constant(np.array([qs]), dtype=tf.float32)\n e = y_true - y_pred\n v = tf.maximum(q*e, (q-1)*e)\n return K.mean(v)\n\ndef mloss(_lambda):\n def loss(y_true, y_pred):\n return _lambda * qloss(y_true, y_pred) + (1 - _lambda)*score(y_true, y_pred)\n return loss\n\ndef make_model(nh):\n z = L.Input((nh,), name=\"Patient\")\n x = L.Dense(100, activation=\"relu\", name=\"d1\")(z)\n x = L.Dense(100, activation=\"relu\", name=\"d2\")(x)\n p1 = L.Dense(3, activation=\"linear\", name=\"p1\")(x)\n p2 = L.Dense(3, activation=\"relu\", name=\"p2\")(x)\n preds = L.Lambda(lambda x: x[0] + tf.cumsum(x[1], axis=1), \n name=\"preds\")([p1, p2])\n \n model = M.Model(z, preds, name=\"CNN\")\n model.compile(loss=mloss(0.65), optimizer=tf.keras.optimizers.Adam(lr=0.1, beta_1=0.9, beta_2=0.999, epsilon=None, decay=0.01, amsgrad=False), metrics=[score])\n return model","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:55.814234Z","iopub.status.busy":"2020-09-12T12:47:55.813336Z","iopub.status.idle":"2020-09-12T12:47:55.815747Z","shell.execute_reply":"2020-09-12T12:47:55.816322Z"},"papermill":{"duration":0.097322,"end_time":"2020-09-12T12:47:55.81648","exception":false,"start_time":"2020-09-12T12:47:55.719158","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"y = tr['FVC'].values\nz = tr[FE].values\nze = sub[FE].values\nnh = z.shape[1]\npe = np.zeros((ze.shape[0], 3))\npred = np.zeros((z.shape[0], 3))","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:55.99082Z","iopub.status.busy":"2020-09-12T12:47:55.98984Z","iopub.status.idle":"2020-09-12T12:47:56.084726Z","shell.execute_reply":"2020-09-12T12:47:56.08595Z"},"papermill":{"duration":0.185857,"end_time":"2020-09-12T12:47:56.086154","exception":false,"start_time":"2020-09-12T12:47:55.900297","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"net = make_model(nh)\nprint(net.summary())\nprint(net.count_params())","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:56.263315Z","iopub.status.busy":"2020-09-12T12:47:56.262672Z","iopub.status.idle":"2020-09-12T12:47:56.266979Z","shell.execute_reply":"2020-09-12T12:47:56.266371Z"},"papermill":{"duration":0.093911,"end_time":"2020-09-12T12:47:56.267087","exception":false,"start_time":"2020-09-12T12:47:56.173176","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"NFOLD = 5 # originally 5\nkf = KFold(n_splits=NFOLD)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:47:56.450507Z","iopub.status.busy":"2020-09-12T12:47:56.449843Z","iopub.status.idle":"2020-09-12T12:52:13.239533Z","shell.execute_reply":"2020-09-12T12:52:13.240327Z"},"papermill":{"duration":256.888527,"end_time":"2020-09-12T12:52:13.240506","exception":false,"start_time":"2020-09-12T12:47:56.351979","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"%%time\ncnt = 0\nEPOCHS = 855\nfor tr_idx, val_idx in kf.split(z):\n cnt += 1\n print(f\"FOLD {cnt}\")\n net = make_model(nh)\n net.fit(z[tr_idx], y[tr_idx], batch_size=BATCH_SIZE, epochs=EPOCHS, \n validation_data=(z[val_idx], y[val_idx]), verbose=0) #\n print(\"train\", net.evaluate(z[tr_idx], y[tr_idx], verbose=0, batch_size=BATCH_SIZE))\n print(\"val\", net.evaluate(z[val_idx], y[val_idx], verbose=0, batch_size=BATCH_SIZE))\n print(\"predict val...\")\n pred[val_idx] = net.predict(z[val_idx], batch_size=BATCH_SIZE, verbose=0)\n print(\"predict test...\")\n pe += net.predict(ze, batch_size=BATCH_SIZE, verbose=0) / NFOLD","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:13.454301Z","iopub.status.busy":"2020-09-12T12:52:13.453283Z","iopub.status.idle":"2020-09-12T12:52:13.458791Z","shell.execute_reply":"2020-09-12T12:52:13.459529Z"},"papermill":{"duration":0.121038,"end_time":"2020-09-12T12:52:13.459721","exception":false,"start_time":"2020-09-12T12:52:13.338683","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"sigma_opt = mean_absolute_error(y, pred[:, 1])\nunc = pred[:,2] - pred[:, 0]\nsigma_mean = np.mean(unc)\nprint(sigma_opt, sigma_mean)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:13.724337Z","iopub.status.busy":"2020-09-12T12:52:13.723447Z","iopub.status.idle":"2020-09-12T12:52:14.111516Z","shell.execute_reply":"2020-09-12T12:52:14.112285Z"},"papermill":{"duration":0.550892,"end_time":"2020-09-12T12:52:14.112508","exception":false,"start_time":"2020-09-12T12:52:13.561616","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"idxs = np.random.randint(0, y.shape[0], 100)\nplt.plot(y[idxs], label=\"ground truth\")\nplt.plot(pred[idxs, 0], label=\"q25\")\nplt.plot(pred[idxs, 1], label=\"q50\")\nplt.plot(pred[idxs, 2], label=\"q75\")\nplt.legend(loc=\"best\")\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:14.353361Z","iopub.status.busy":"2020-09-12T12:52:14.352235Z","iopub.status.idle":"2020-09-12T12:52:14.358402Z","shell.execute_reply":"2020-09-12T12:52:14.359267Z"},"papermill":{"duration":0.113133,"end_time":"2020-09-12T12:52:14.359466","exception":false,"start_time":"2020-09-12T12:52:14.246333","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"print(unc.min(), unc.mean(), unc.max(), (unc>=0).mean())","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:14.572232Z","iopub.status.busy":"2020-09-12T12:52:14.57105Z","iopub.status.idle":"2020-09-12T12:52:14.749603Z","shell.execute_reply":"2020-09-12T12:52:14.750167Z"},"papermill":{"duration":0.292658,"end_time":"2020-09-12T12:52:14.750313","exception":false,"start_time":"2020-09-12T12:52:14.457655","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"plt.hist(unc)\nplt.title(\"uncertainty in prediction\")\nplt.show()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:14.985262Z","iopub.status.busy":"2020-09-12T12:52:14.980425Z","iopub.status.idle":"2020-09-12T12:52:15.001873Z","shell.execute_reply":"2020-09-12T12:52:15.002425Z"},"papermill":{"duration":0.143993,"end_time":"2020-09-12T12:52:15.002569","exception":false,"start_time":"2020-09-12T12:52:14.858576","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"sub.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:15.217929Z","iopub.status.busy":"2020-09-12T12:52:15.216762Z","iopub.status.idle":"2020-09-12T12:52:15.23643Z","shell.execute_reply":"2020-09-12T12:52:15.235659Z"},"papermill":{"duration":0.127785,"end_time":"2020-09-12T12:52:15.236557","exception":false,"start_time":"2020-09-12T12:52:15.108772","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"# PREDICTION\nsub['FVC1'] = 1.*pe[:, 1]\nsub['Confidence1'] = pe[:, 2] - pe[:, 0]\nsubm = sub[['Patient_Week','FVC','Confidence','FVC1','Confidence1']].copy()\nsubm.loc[~subm.FVC1.isnull()].head(10)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:15.454484Z","iopub.status.busy":"2020-09-12T12:52:15.452753Z","iopub.status.idle":"2020-09-12T12:52:15.455984Z","shell.execute_reply":"2020-09-12T12:52:15.456662Z"},"papermill":{"duration":0.123505,"end_time":"2020-09-12T12:52:15.456805","exception":false,"start_time":"2020-09-12T12:52:15.3333","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"subm.loc[~subm.FVC1.isnull(),'FVC'] = subm.loc[~subm.FVC1.isnull(),'FVC1']\nif sigma_mean<70:\n subm['Confidence'] = sigma_opt\nelse:\n subm.loc[~subm.FVC1.isnull(),'Confidence'] = subm.loc[~subm.FVC1.isnull(),'Confidence1']","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:15.665319Z","iopub.status.busy":"2020-09-12T12:52:15.664083Z","iopub.status.idle":"2020-09-12T12:52:15.669267Z","shell.execute_reply":"2020-09-12T12:52:15.668685Z"},"papermill":{"duration":0.116449,"end_time":"2020-09-12T12:52:15.669413","exception":false,"start_time":"2020-09-12T12:52:15.552964","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"subm.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:15.892182Z","iopub.status.busy":"2020-09-12T12:52:15.889669Z","iopub.status.idle":"2020-09-12T12:52:15.915157Z","shell.execute_reply":"2020-09-12T12:52:15.914073Z"},"papermill":{"duration":0.136465,"end_time":"2020-09-12T12:52:15.915279","exception":false,"start_time":"2020-09-12T12:52:15.778814","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"subm.describe().T","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:16.162124Z","iopub.status.busy":"2020-09-12T12:52:16.154099Z","iopub.status.idle":"2020-09-12T12:52:16.173785Z","shell.execute_reply":"2020-09-12T12:52:16.173152Z"},"papermill":{"duration":0.149122,"end_time":"2020-09-12T12:52:16.1739","exception":false,"start_time":"2020-09-12T12:52:16.024778","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"otest = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/test.csv')\nfor i in range(len(otest)):\n subm.loc[subm['Patient_Week']==otest.Patient[i]+'_'+str(otest.Weeks[i]), 'FVC'] = otest.FVC[i]\n subm.loc[subm['Patient_Week']==otest.Patient[i]+'_'+str(otest.Weeks[i]), 'Confidence'] = 0.1","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:16.380345Z","iopub.status.busy":"2020-09-12T12:52:16.37975Z","iopub.status.idle":"2020-09-12T12:52:16.390116Z","shell.execute_reply":"2020-09-12T12:52:16.389469Z"},"papermill":{"duration":0.116206,"end_time":"2020-09-12T12:52:16.390244","exception":false,"start_time":"2020-09-12T12:52:16.274038","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"subm[[\"Patient_Week\",\"FVC\",\"Confidence\"]].to_csv(\"submission_regression.csv\", index=False)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:16.596169Z","iopub.status.busy":"2020-09-12T12:52:16.595292Z","iopub.status.idle":"2020-09-12T12:52:16.599737Z","shell.execute_reply":"2020-09-12T12:52:16.598985Z"},"papermill":{"duration":0.109855,"end_time":"2020-09-12T12:52:16.59985","exception":false,"start_time":"2020-09-12T12:52:16.489995","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"reg_sub = subm[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()","execution_count":null,"outputs":[]},{"metadata":{"papermill":{"duration":0.10142,"end_time":"2020-09-12T12:52:16.80591","exception":false,"start_time":"2020-09-12T12:52:16.70449","status":"completed"},"tags":[]},"cell_type":"markdown","source":"## 4.4 Ensemble and blending \n\n[Back to Table of Contents](#0.1)"},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:17.016579Z","iopub.status.busy":"2020-09-12T12:52:17.015063Z","iopub.status.idle":"2020-09-12T12:52:17.020396Z","shell.execute_reply":"2020-09-12T12:52:17.019576Z"},"papermill":{"duration":0.115266,"end_time":"2020-09-12T12:52:17.020513","exception":false,"start_time":"2020-09-12T12:52:16.905247","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"df1 = img_sub.sort_values(by=['Patient_Week'], ascending=True).reset_index(drop=True)\ndf2 = reg_sub.sort_values(by=['Patient_Week'], ascending=True).reset_index(drop=True)","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:17.238577Z","iopub.status.busy":"2020-09-12T12:52:17.23789Z","iopub.status.idle":"2020-09-12T12:52:17.243976Z","shell.execute_reply":"2020-09-12T12:52:17.243059Z"},"papermill":{"duration":0.1238,"end_time":"2020-09-12T12:52:17.244079","exception":false,"start_time":"2020-09-12T12:52:17.120279","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"df = df1[['Patient_Week']].copy()\ndf['FVC'] = FVC_weight*df1['FVC'] + (1-FVC_weight)*df2['FVC']\ndf['Confidence'] = Confidence_weight*df1['Confidence'] + (1-Confidence_weight)*df2['Confidence']\ndf.head()","execution_count":null,"outputs":[]},{"metadata":{"execution":{"iopub.execute_input":"2020-09-12T12:52:17.450967Z","iopub.status.busy":"2020-09-12T12:52:17.449661Z","iopub.status.idle":"2020-09-12T12:52:17.456669Z","shell.execute_reply":"2020-09-12T12:52:17.45605Z"},"papermill":{"duration":0.114726,"end_time":"2020-09-12T12:52:17.456777","exception":false,"start_time":"2020-09-12T12:52:17.342051","status":"completed"},"tags":[],"trusted":false},"cell_type":"code","source":"df.to_csv('submission.csv', index=False)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"df_issa1 = df.copy()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# 2. Second notebook\n\nhttps://www.kaggle.com/zhangxianjue/train-age\n\n"},{"metadata":{"trusted":true,"_kg_hide-output":true},"cell_type":"code","source":"Dropout_model = 0.3856\nFVC_weight = 0.2\nConfidence_weight = 0\n!pip install ../input/kerasapplications/keras-team-keras-applications-3b180cb -f ./ --no-index\n!pip install ../input/efficientnet/efficientnet-1.1.0/ -f ./ --no-index\nimport os\nimport cv2\nimport pydicom\nimport pandas as pd\nimport numpy as np \nimport tensorflow as tf \nimport matplotlib.pyplot as plt \nimport random\nfrom tqdm.notebook import tqdm \nfrom sklearn.model_selection import train_test_split, KFold\nfrom sklearn.metrics import mean_absolute_error\nfrom tensorflow_addons.optimizers import RectifiedAdam\nfrom tensorflow.keras import Model\nimport tensorflow.keras.backend as K\nimport tensorflow.keras.layers as L\nimport tensorflow.keras.models as M\nfrom tensorflow.keras.optimizers import Nadam\nimport seaborn as sns\nfrom PIL import Image","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def seed_everything(seed=2020):\n random.seed(seed)\n os.environ['PYTHONHASHSEED'] = str(seed)\n np.random.seed(seed)\n tf.random.set_seed(seed)\n \nseed_everything(42)\nconfig = tf.compat.v1.ConfigProto()\nconfig.gpu_options.allow_growth = True\nsession = tf.compat.v1.Session(config=config)\ntrain = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/train.csv') ","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"tr_age_max = train.Age.values.max()\ntr_age_min = train.Age.values.min()\ntr_age_mean = train.Age.values.mean()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def expandFVC_Percent(DS):\n DS['FVC_Percent'] = DS['FVC'] / DS['Percent']\n return DS","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def expandFE(data_set):\n data_set['MinWeeks'] = data_set.groupby('Patient')['Weeks'].transform('min')\n sub_tr = data_set.loc[data_set['Weeks']==data_set['MinWeeks']]\n\n sub_tr['MinFVC'] = sub_tr['FVC']\n\n sub_tr = sub_tr[['Patient', 'MinFVC']]\n\n merged = data_set.merge(sub_tr, on='Patient', how='outer')\n\n\n data_set=merged\n \n data_set['MinFVC'] = (data_set['MinFVC'] - data_set['MinFVC'].min())/(data_set['MinFVC'].max()-data_set['MinFVC'].min())\n print(data_set.sample(5))\n return data_set","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train = expandFE(train)\n# train = expandFVC_Percent(train)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"print(train.head())\nprint(train.sample(10))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def get_tab(df):\n # df: data frame\n # [age, male/female[0/1], SmokingStatus[00/11/01], BaseFvc] (5,)\n vector = [(df.Age.values[0] - tr_age_min) / (tr_age_max-tr_age_min)] \n \n if df.Sex.values[0] == 'male':\n vector.append(0)\n else:\n vector.append(1)\n \n if df.SmokingStatus.values[0] == 'Never smoked':\n vector.extend([0,0])\n elif df.SmokingStatus.values[0] == 'Ex-smoker':\n vector.extend([1,1])\n elif df.SmokingStatus.values[0] == 'Currently smokes':\n vector.extend([0,1])\n else:\n vector.extend([1,0])\n vector.extend([df['MinFVC'].values[0]])\n# vector.extend([df['FVC_Percent'].values[0]])\n return np.array(vector) ","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"A = {} \nTAB = {} \nP = [] \nfor i, p in tqdm(enumerate(train.Patient.unique())):\n sub = train.loc[train.Patient == p, :] \n fvc = sub.FVC.values\n weeks = sub.Weeks.values\n c = np.vstack([weeks, np.ones(len(weeks))]).T\n a, b = np.linalg.lstsq(c, fvc)[0]\n \n A[p] = a\n TAB[p] = get_tab(sub)\n P.append(p)\n\ndef get_img(path):\n d = pydicom.dcmread(path)\n return cv2.resize(d.pixel_array / 2**11, (512, 512))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"from tensorflow.keras.utils import Sequence\nimport math\n\nclass IGenerator(Sequence):\n BAD_ID = ['ID00011637202177653955184', 'ID00052637202186188008618']\n def __init__(self, keys, a, tab, batch_size=8):\n self.keys = [k for k in keys if k not in self.BAD_ID]\n self.a = a\n self.tab = tab\n self.batch_size = batch_size\n \n self.train_data = {} # imgs for each person; self.trian_data[pi] = [img1, img2, ..., imgn]\n for p in train.Patient.values:\n # filenames in \"~/train/personid/\"\n self.train_data[p] = os.listdir(f'../input/osic-pulmonary-fibrosis-progression/train/{p}/')\n \n def __len__(self):\n# return 1000\n return math.ceil(len(self.keys) / float(self.batch_size)) \n \n def __getitem__(self, idx):\n x = []\n a, tab = [], [] \n keys = np.random.choice(self.keys, size = self.batch_size) # persons in batch size\n for k in keys:\n # chose a {[img, tab], a}for each person (only 1 img)\n try:\n self.train_data[k].sort()\n mx_len = len(self.train_data[k])\n i = np.random.choice(self.train_data[k][mx_len//3:mx_len//3*2], size=1)[0]\n# i = self.train_data[k][max_len//2]\n img = get_img(f'../input/osic-pulmonary-fibrosis-progression/train/{k}/{i}')\n x.append(img)\n a.append(self.a[k])\n tab.append(self.tab[k])\n except:\n print(k, i)\n \n x, a, tab = np.array(x), np.array(a), np.array(tab)\n x = np.expand_dims(x, axis=-1)\n return [x, tab] , a","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"from tensorflow.keras.layers import (\n Dense, Dropout, Activation, Flatten, Input, BatchNormalization, GlobalAveragePooling2D, Add, Conv2D, AveragePooling2D, \n LeakyReLU, Concatenate \n)\nimport efficientnet.tfkeras as efn\n\ndef get_efficientnet(model, shape):\n models_dict = {\n 'b0': efn.EfficientNetB0(input_shape=shape,weights=None,include_top=False),\n 'b1': efn.EfficientNetB1(input_shape=shape,weights=None,include_top=False),\n 'b2': efn.EfficientNetB2(input_shape=shape,weights=None,include_top=False),\n 'b3': efn.EfficientNetB3(input_shape=shape,weights=None,include_top=False),\n 'b4': efn.EfficientNetB4(input_shape=shape,weights=None,include_top=False),\n 'b5': efn.EfficientNetB5(input_shape=shape,weights=None,include_top=False),\n 'b6': efn.EfficientNetB6(input_shape=shape,weights=None,include_top=False),\n 'b7': efn.EfficientNetB7(input_shape=shape,weights=None,include_top=False)\n }\n return models_dict[model]\n\ndef build_model(shape=(512, 512, 1), model_class=None):\n inp = Input(shape=shape)\n base = get_efficientnet(model_class, shape)\n x = base(inp)\n x = GlobalAveragePooling2D()(x)\n# inp2 = Input(shape=(4,)) # original is 4\n inp2 = Input(shape=(5,)) # add the feature of MinFVC\n x2 = tf.keras.layers.GaussianNoise(0.2)(inp2)\n x = Concatenate()([x, x2]) \n x = Dropout(Dropout_model)(x)\n x = Dense(1)(x)\n model = Model([inp, inp2] , x)\n \n# weights = [w for w in os.listdir('../input/osic-model-weights') if model_class in w][0]\n# model.load_weights('../input/osic-model-weights/' + weights)\n return model","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"model_classes = ['b5'] #['b0','b1','b2','b3',b4','b5','b6','b7']\nmodels = [build_model(shape=(512, 512, 1), model_class=m) for m in model_classes]\nprint('Number of models: ' + str(len(models)))\n\nmodel = models[0]\n\n# model = get_model()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"# efn_path = \"../input/trainefn/efn.ckpt\"\n# model.load_weights(efn_path)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"model.summary()\n# model.compile(optimizer=tf.keras.optimizers.Adam(learning_rate=0.01), loss='mae') # original is lr=0.001","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def score(fvc_true, fvc_pred, sigma):\n sigma_clip = np.maximum(sigma, 70) # changed from 70, trie 66.7 too\n delta = np.abs(fvc_true - fvc_pred)\n delta = np.minimum(delta, 1000)\n sq2 = np.sqrt(2)\n metric = (delta / sigma_clip)*sq2 + np.log(sigma_clip* sq2)\n return np.mean(metric)\nsubs = []\nq = -1","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"q = -1\n# with open('../input/trainefn/q.txt', 'r') as f:\n# q=float(f.readlines()[0].strip())\nprint(q)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"sub = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/sample_submission.csv') \ntest = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/test.csv') \nA_test, B_test, P_test,W, FVC= {}, {}, {},{},{} \nSTD, WEEK = {}, {} ","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"test = expandFE(test)\n# test = expandFVC_Percent(test)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"for p in test.Patient.unique():\n x = [] \n tab = [] \n ldir = os.listdir(f'../input/osic-pulmonary-fibrosis-progression/test/{p}/')\n for i in ldir:\n if int(i[:-4]) / len(ldir) < 0.8 and int(i[:-4]) / len(ldir) > 0.15:\n x.append(get_img(f'../input/osic-pulmonary-fibrosis-progression/test/{p}/{i}')) \n tab.append(get_tab(test.loc[test.Patient == p, :])) \n if len(x) <= 1:\n continue\n tab = np.array(tab) \n\n x = np.expand_dims(x, axis=-1) \n _a = model.predict([x, tab]) \n a = np.quantile(_a, q)\n A_test[p] = a\n B_test[p] = test.FVC.values[test.Patient == p] - a*test.Weeks.values[test.Patient == p]\n P_test[p] = test.Percent.values[test.Patient == p] \n WEEK[p] = test.Weeks.values[test.Patient == p]\n\n\nfor k in sub.Patient_Week.values:\n p, w = k.split('_')\n w = int(w) \n\n fvc = A_test[p] * w + B_test[p]\n sub.loc[sub.Patient_Week == k, 'FVC'] = fvc\n sub.loc[sub.Patient_Week == k, 'Confidence'] = (\n P_test[p] - A_test[p] * abs(WEEK[p] - w) \n) \n\n_sub = sub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()\nsubs.append(_sub)\nprint(subs)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"N = len(subs)\nprint(N)\nsub = subs[0].copy() # ref\nsub[\"FVC\"] = 0\nsub[\"Confidence\"] = 0\nfor i in range(N):\n sub[\"FVC\"] += subs[0][\"FVC\"] * (1/N)\n sub[\"Confidence\"] += subs[0][\"Confidence\"] * (1/N)\nsub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].to_csv(\"submission_img.csv\", index=False)\nimg_sub = sub[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()\nprint(img_sub.sample(5))","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"ROOT = \"../input/osic-pulmonary-fibrosis-progression\"\nBATCH_SIZE=128\n\ntr = pd.read_csv(f\"{ROOT}/train.csv\")\ntr.drop_duplicates(keep=False, inplace=True, subset=['Patient','Weeks'])\nchunk = pd.read_csv(f\"{ROOT}/test.csv\")\n\nprint(\"add infos\")\nsub = pd.read_csv(f\"{ROOT}/sample_submission.csv\")\nsub['Patient'] = sub['Patient_Week'].apply(lambda x:x.split('_')[0])\nsub['Weeks'] = sub['Patient_Week'].apply(lambda x: int(x.split('_')[-1]))\nsub = sub[['Patient','Weeks','Confidence','Patient_Week']]\nsub = sub.merge(chunk.drop('Weeks', axis=1), on=\"Patient\")\ntr['WHERE'] = 'train'\nchunk['WHERE'] = 'val'\nsub['WHERE'] = 'test'\ndata = tr.append([chunk, sub])\nprint(tr.shape, chunk.shape, sub.shape, data.shape)\nprint(tr.Patient.nunique(), chunk.Patient.nunique(), sub.Patient.nunique(), \n data.Patient.nunique())","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"data['min_week'] = data['Weeks']\ndata.loc[data.WHERE=='test','min_week'] = np.nan\ndata['min_week'] = data.groupby('Patient')['min_week'].transform('min')\nbase = data.loc[data.Weeks == data.min_week]\nbase = base[['Patient','FVC']].copy()\nbase.columns = ['Patient','min_FVC']\nbase['nb'] = 1\nbase['nb'] = base.groupby('Patient')['nb'].transform('cumsum')\nbase = base[base.nb==1]\nbase.drop('nb', axis=1, inplace=True)\ndata = data.merge(base, on='Patient', how='left')\ndata['base_week'] = data['Weeks'] - data['min_week']\ndel base\nCOLS = ['Sex','SmokingStatus'] #,'Age'\nFE = []\nfor col in COLS:\n for mod in data[col].unique():\n FE.append(mod)\n data[mod] = (data[col] == mod).astype(int)\n#\ndata['age'] = (data['Age'] - data['Age'].min() ) / ( data['Age'].max() - data['Age'].min() )\ndata['BASE'] = (data['min_FVC'] - data['min_FVC'].min() ) / ( data['min_FVC'].max() - data['min_FVC'].min() )\ndata['week'] = (data['base_week'] - data['base_week'].min() ) / ( data['base_week'].max() - data['base_week'].min() )\ndata['percent'] = (data['Percent'] - data['Percent'].min() ) / ( data['Percent'].max() - data['Percent'].min() )\ndata['FVC_Percent'] = data['FVC'] / data['Percent']\n# FE += ['age','percent','week','BASE', 'FVC_Percent']\nFE += ['age','percent','week','BASE']\ntr = data.loc[data.WHERE=='train']\nchunk = data.loc[data.WHERE=='val']\nsub = data.loc[data.WHERE=='test']\ndel data\nC1, C2 = tf.constant(70, dtype='float32'), tf.constant(1000, dtype=\"float32\")\ndef score(y_true, y_pred):\n tf.dtypes.cast(y_true, tf.float32)\n tf.dtypes.cast(y_pred, tf.float32)\n sigma = y_pred[:, 2] - y_pred[:, 0]\n fvc_pred = y_pred[:, 1]\n \n #sigma_clip = sigma + C1\n sigma_clip = tf.maximum(sigma, C1)\n delta = tf.abs(y_true[:, 0] - fvc_pred)\n delta = tf.minimum(delta, C2)\n sq2 = tf.sqrt( tf.dtypes.cast(2, dtype=tf.float32) )\n metric = (delta / sigma_clip)*sq2 + tf.math.log(sigma_clip* sq2)\n return K.mean(metric)\n\ndef qloss(y_true, y_pred):\n # Pinball loss for multiple quantiles\n qs = [0.2, 0.50, 0.8]\n q = tf.constant(np.array([qs]), dtype=tf.float32)\n e = y_true - y_pred\n v = tf.maximum(q*e, (q-1)*e)\n return K.mean(v)\n\ndef mloss(_lambda):\n def loss(y_true, y_pred):\n return _lambda * qloss(y_true, y_pred) + (1 - _lambda)*score(y_true, y_pred)\n return loss\n\n\ndef make_model(nh):\n z = L.Input((nh,), name=\"Patient\")\n x = L.Dense(100, activation=\"relu\", name=\"d1\")(z)\n x = L.Dense(100, activation=\"relu\", name=\"d2\")(x)\n p1 = L.Dense(3, activation=\"linear\", name=\"p1\")(x)\n p2 = L.Dense(3, activation=\"relu\", name=\"p2\")(x)\n preds = L.Lambda(lambda x: x[0] + tf.cumsum(x[1], axis=1), \n name=\"preds\")([p1, p2])\n \n model = M.Model(z, preds, name=\"CNN\")\n model.compile(loss=mloss(0.65), optimizer=tf.keras.optimizers.Adam(lr=0.1, beta_1=0.9, beta_2=0.999, epsilon=None, decay=0.01, amsgrad=False), metrics=[score])\n return model\nprint(FE)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"y = tr['FVC'].values # train target\nz = tr[FE].values # fetures (1535, 9)\nprint(z.shape)\nze = sub[FE].values # fetures of submission (730, 9) e: estimate\nprint(ze.shape) \nnh = z.shape[1] \nprint(nh) # feature numbers (9,)\npe = np.zeros((ze.shape[0], 3)) #estimate of prediction\npred = np.zeros((z.shape[0], 3)) # prediction of truth ground\nnet = make_model(nh)\nprint(net.summary())\nprint(net.count_params())\nNFOLD = 5 # originally 5\nkf = KFold(n_splits=NFOLD)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"cnt = 0\nEPOCHS = 800\ny = y.astype(np.float32)\nfor tr_idx, val_idx in kf.split(z):\n cnt += 1\n print(f\"FOLD {cnt}\")\n net = make_model(nh)\n net.fit(z[tr_idx], y[tr_idx], batch_size=BATCH_SIZE, epochs=EPOCHS, \n validation_data=(z[val_idx], y[val_idx]), verbose=0) #\n print(\"train\", net.evaluate(z[tr_idx], y[tr_idx], verbose=0, batch_size=BATCH_SIZE))\n print(\"val\", net.evaluate(z[val_idx], y[val_idx], verbose=0, batch_size=BATCH_SIZE))\n print(\"predict val...\")\n pred[val_idx] = net.predict(z[val_idx], batch_size=BATCH_SIZE, verbose=0)\n print(\"predict test...\")\n pe += net.predict(ze, batch_size=BATCH_SIZE, verbose=0) / NFOLD","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"sigma_opt = mean_absolute_error(y, pred[:, 1])\nunc = pred[:,2] - pred[:, 0]\nsigma_mean = np.mean(unc)\nprint(sigma_opt, sigma_mean)\nidxs = np.random.randint(0, y.shape[0], 100)\nplt.plot(y[idxs], label=\"ground truth\")\nplt.plot(pred[idxs, 0], label=\"q25\")\nplt.plot(pred[idxs, 1], label=\"q50\")\nplt.plot(pred[idxs, 2], label=\"q75\")\nplt.legend(loc=\"best\")\nplt.show()\nprint(unc.min(), unc.mean(), unc.max(), (unc>=0).mean())\nplt.hist(unc)\nplt.title(\"uncertainty in prediction\")\nplt.show()\nsub.head()\n# PREDICTION\nsub['FVC1'] = 1.*pe[:, 1]\nsub['Confidence1'] = pe[:, 2] - pe[:, 0]\nsubm = sub[['Patient_Week','FVC','Confidence','FVC1','Confidence1']].copy()\nsubm.loc[~subm.FVC1.isnull()].head(10)\nsubm.loc[~subm.FVC1.isnull(),'FVC'] = subm.loc[~subm.FVC1.isnull(),'FVC1']\nif sigma_mean<70:\n subm['Confidence'] = sigma_opt\nelse:\n subm.loc[~subm.FVC1.isnull(),'Confidence'] = subm.loc[~subm.FVC1.isnull(),'Confidence1']\nsubm.head()\nsubm.describe().T\notest = pd.read_csv('../input/osic-pulmonary-fibrosis-progression/test.csv')\nfor i in range(len(otest)):\n subm.loc[subm['Patient_Week']==otest.Patient[i]+'_'+str(otest.Weeks[i]), 'FVC'] = otest.FVC[i]\n subm.loc[subm['Patient_Week']==otest.Patient[i]+'_'+str(otest.Weeks[i]), 'Confidence'] = 0.1\nsubm[[\"Patient_Week\",\"FVC\",\"Confidence\"]].to_csv(\"submission_regression.csv\", index=False)\nreg_sub = subm[[\"Patient_Week\",\"FVC\",\"Confidence\"]].copy()\ndf1 = img_sub.sort_values(by=['Patient_Week'], ascending=True).reset_index(drop=True)\ndf2 = reg_sub.sort_values(by=['Patient_Week'], ascending=True).reset_index(drop=True)\ndf = df1[['Patient_Week']].copy()\ndf['FVC'] = FVC_weight*df1['FVC'] + (1-FVC_weight)*df2['FVC']\ndf['Confidence'] = Confidence_weight*df1['Confidence'] + (1-Confidence_weight)*df2['Confidence']\ndf.head();\ndf.to_csv('submission.csv', index=False)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"df_issa2 = df.copy()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# Save submission"},{"metadata":{"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true},"cell_type":"code","source":"\ndf_issa1.to_csv('df_issa1.csv', index=False)\ndf_issa2.to_csv('df_issa2.csv', index=False)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true,"_kg_hide-input":true,"_kg_hide-output":true},"cell_type":"code","source":"x = 0.6\ndf = df_issa1.copy()\ndf['FVC'] = x*df_issa1['FVC'] + (1-x)*df_issa2['FVC']\ndf['Confidence'] = x*df_issa1['Confidence'] + (1-x)*df_issa2['Confidence']\ndf.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"df.to_csv('submission.csv', index=False)","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":4}