{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# MLB Player Digital Engagement Forecasting #","metadata":{"execution":{"iopub.status.busy":"2021-06-08T23:38:55.536027Z","iopub.execute_input":"2021-06-08T23:38:55.536369Z","iopub.status.idle":"2021-06-08T23:38:55.540097Z","shell.execute_reply.started":"2021-06-08T23:38:55.536341Z","shell.execute_reply":"2021-06-08T23:38:55.53902Z"}}},{"cell_type":"markdown","source":"This notebook builds upon the starter notebook provided by the competition organisers [here](https://www.kaggle.com/ryanholbrook/getting-started-with-mlb-player-digital-engagement)\n\nTable of Contents \n* [Introduction](#intro)\n* [Initial Questions on Data](#que)\n* [Importing the Datasets](#import)\n* [Exploratory Analysis](#exp)\n* [Feature Engineering](#feature)\n* [Model Development & Hyperparameter Tuning](#model)\n* [Final Submission](#submit)\n\n\n## Introduction\nThe aim of this competition is to understand the factors that lead to rise & fall in supporter engagement for players. We've been provided with a number of datasets around match score statistics, player records, awards & events within a season. In this notebook we'll be looking to understand the datasets provided and try and understand how different factors like scores, teams, time of the year contribute to variations in player Engagement. \n\nIf you like me don't have lot of domain knowledge about baseball then this discussion [thread](https://www.kaggle.com/c/mlb-player-digital-engagement-forecasting/discussion/245457) will be a good place to understand the format of the tournament as well as rules for the game & the statistics measured in baseball.\n\n\n## Datasets Provided\n* **train.csv** - Dataset at a playerId, date level. Contains nested JSONs for following - ```games, rosters, playerBoxScores, teamBoxScores, awards, events, playerEngagement etc.``` etc. The 4 playerEngagement variables are - ```target1, target2, target3, target4``` target1-target4 are each daily indexes of digital engagement on a 0-100 scale. Data is provided from 2018 - 2021.\n* **teams.csv** - Dataset containing info for teams like ```teamName, location, league & division``` that they play in.\n* **seasons.csv** - Contains dates for various phases of a season - ``preSeason, regularSeason, playoffs, postseason`` etc. from 2017-2021\n* **players.csv** - Dataset containing info for players - ```DOB, birthcountry,mlbDebutDate, position``` etc. \n\n\n## Initial Questions on Data\n\n* How do the four target engagement variables vary from one year to the other and how are they related to each other?\n* How does engagament score decay with time after a baseball game?\n* How are engagement score values autocorrelated with each other?\n* How do engagement scores vary with time of the year & progress of the season? Is there seasonality associated with these scores?\n* Does successful teams enjoy higher engagement scores compared to remaining teams? Do higher ranked teams see more engagement from fans?\n* How does starting position of a player play a role in driving engagement scores? Are players in certain positions likely to drive higher engagement?\n* How does a player's demographic attributes play a role in determining their engagement scores?\n* How do run scoring & pitching stats impact engagement scores? Does good & bad performance both lead to higher engagement from fans?\n\n## Importing the datasets\n\nThis section below has been borrowed from the notebook provided by the competition organizers. The section of code below unpacks the JSON for various columns in the ```train.csv``` and creates a nice tabular dataset for us to run further analyses.\n\n\n","metadata":{}},{"cell_type":"code","source":"#!pip install raceplotly","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:42.180500Z","iopub.execute_input":"2021-07-03T16:48:42.180908Z","iopub.status.idle":"2021-07-03T16:48:42.185727Z","shell.execute_reply.started":"2021-07-03T16:48:42.180825Z","shell.execute_reply":"2021-07-03T16:48:42.184362Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#Importing packages\nimport gc\nimport sys\nimport warnings\nfrom pathlib import Path\n\nimport ipywidgets as widgets\nimport matplotlib.pyplot as plt\nimport numpy as np\nimport pandas as pd\nimport seaborn as sns\nfrom sklearn.model_selection import train_test_split\nfrom statsmodels.tsa.deterministic import (CalendarFourier,\n CalendarSeasonality,\n CalendarTimeTrend,\n DeterministicProcess)\n\nimport tensorflow as tf\nfrom tensorflow import keras\nfrom tensorflow.keras import layers\n\n#from raceplotly.plots import barplot\n\nwarnings.simplefilter(\"ignore\")\n\n# Set Matplotlib defaults\nplt.style.use(\"seaborn-whitegrid\")\nplt.rc(\"figure\", autolayout=True, figsize=(11, 5))\nplt.rc(\n \"axes\",\n labelweight=\"bold\",\n labelsize=\"large\",\n titleweight=\"bold\",\n titlesize=14,\n titlepad=10,\n)\nplot_params = dict(\n color=\"0.75\",\n style=\".-\",\n markeredgecolor=\"0.25\",\n markerfacecolor=\"0.25\",\n legend=False,\n)","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:42.360930Z","iopub.execute_input":"2021-07-03T16:48:42.361261Z","iopub.status.idle":"2021-07-03T16:48:47.808800Z","shell.execute_reply.started":"2021-07-03T16:48:42.361230Z","shell.execute_reply":"2021-07-03T16:48:47.807909Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Load and Join Data #","metadata":{}},{"cell_type":"code","source":"data_dir = Path('../input/mlb-player-digital-engagement-forecasting/')\n#training = pd.read_csv(data_dir / 'train.csv')\nplayers = pd.read_csv(data_dir / 'players.csv')\n\n\n# Convert training data date field to datetime type\n#training['date'] = pd.to_datetime(training['date'], format=\"%Y%m%d\")\n\n#display(training.info())","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:47.812339Z","iopub.execute_input":"2021-07-03T16:48:47.812602Z","iopub.status.idle":"2021-07-03T16:48:47.836065Z","shell.execute_reply.started":"2021-07-03T16:48:47.812575Z","shell.execute_reply":"2021-07-03T16:48:47.835299Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"There are in addition a number of supplementary files. See the [data documentation](https://www.kaggle.com/c/mlb-player-digital-engagement-forecasting/data) on the competition page for more information.","metadata":{}},{"cell_type":"code","source":"#### Look at data from each of the input dfs read in ####\ndf_names = ['seasons', 'teams', 'players', 'awards']\n\nfor name in df_names:\n globals()[name] = pd.read_csv(data_dir / f\"{name}.csv\")\n\nkaggle_data_tabs = widgets.Tab()\n# Add Output widgets for each pandas DF as tabs' children\nkaggle_data_tabs.children = list([widgets.Output() for df_name in df_names])\n\nfor index in range(0, len(df_names)):\n # Rename tab bar titles to df names\n kaggle_data_tabs.set_title(index, df_names[index])\n \n # Display corresponding table output for this tab name\n with kaggle_data_tabs.children[index]:\n display(eval(df_names[index]))\n\ndisplay(kaggle_data_tabs)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:47.838599Z","iopub.execute_input":"2021-07-03T16:48:47.838956Z","iopub.status.idle":"2021-07-03T16:48:48.028021Z","shell.execute_reply.started":"2021-07-03T16:48:47.838928Z","shell.execute_reply":"2021-07-03T16:48:48.027019Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# # Helper function to unpack json found in daily data\n# def unpack_json(json_str):\n# return np.nan if pd.isna(json_str) else pd.read_json(json_str)\n\n# ### Unnest various nested data within training (daily) data ####\n# daily_data_unnested_dfs = pd.DataFrame(data = {\n# 'dfName': training.drop('date', axis = 1).columns.values.tolist()\n# })\n\n# daily_data_unnested_dfs['df'] = [pd.DataFrame() for row in \n# daily_data_unnested_dfs.iterrows()]\n\n# for df_index, df_row in daily_data_unnested_dfs.iterrows():\n# nestedTableName = str(df_row['dfName'])\n \n# date_nested_table = training[['date', nestedTableName]]\n \n# date_nested_table = (date_nested_table[\n# ~pd.isna(date_nested_table[nestedTableName])\n# ].\n# reset_index(drop = True)\n# )\n \n# daily_dfs_collection = []\n \n# for date_index, date_row in date_nested_table.iterrows():\n# daily_df = unpack_json(date_row[nestedTableName])\n \n# daily_df['dailyDataDate'] = date_row['date']\n \n# daily_dfs_collection = daily_dfs_collection + [daily_df]\n\n# unnested_table = pd.concat(daily_dfs_collection,\n# ignore_index = True).set_index('dailyDataDate').reset_index()\n\n# # Creates 1 pandas df per unnested df from daily data read in, with same name\n# globals()[df_row['dfName']] = unnested_table \n \n# daily_data_unnested_dfs['df'][df_index] = unnested_table\n\n# del training\n# gc.collect()\n\n\n\n# #### Get some information on each date in daily data (using season dates of interest) ####\n# dates = pd.DataFrame(data = \n# {'dailyDataDate': nextDayPlayerEngagement['dailyDataDate'].unique()})\n\n# dates['date'] = pd.to_datetime(dates['dailyDataDate'].astype(str))\n\n# dates['year'] = dates['date'].dt.year\n# dates['month'] = dates['date'].dt.month\n\n# dates_with_info = pd.merge(\n# dates,\n# seasons,\n# left_on = 'year',\n# right_on = 'seasonId'\n# )\n\n# dates_with_info['inSeason'] = (\n# dates_with_info['date'].between(\n# dates_with_info['regularSeasonStartDate'],\n# dates_with_info['postSeasonEndDate'],\n# inclusive = True\n# )\n# )\n\n# dates_with_info['seasonPart'] = np.select(\n# [\n# dates_with_info['date'] < dates_with_info['preSeasonStartDate'], \n# dates_with_info['date'] < dates_with_info['regularSeasonStartDate'],\n# dates_with_info['date'] <= dates_with_info['lastDate1stHalf'],\n# dates_with_info['date'] < dates_with_info['firstDate2ndHalf'],\n# dates_with_info['date'] <= dates_with_info['regularSeasonEndDate'],\n# dates_with_info['date'] < dates_with_info['postSeasonStartDate'],\n# dates_with_info['date'] <= dates_with_info['postSeasonEndDate'],\n# dates_with_info['date'] > dates_with_info['postSeasonEndDate']\n# ], \n# [\n# 'Offseason',\n# 'Preseason',\n# 'Reg Season 1st Half',\n# 'All-Star Break',\n# 'Reg Season 2nd Half',\n# 'Between Reg and Postseason',\n# 'Postseason',\n# 'Offseason'\n# ], \n# default = np.nan\n# )\n\n# #### Add some pitching stats/pieces of info to player game level stats ####\n\n# player_game_stats = (playerBoxScores.copy().\n# # Change team Id/name to reflect these come from player game, not roster\n# rename(columns = {'teamId': 'gameTeamId', 'teamName': 'gameTeamName'})\n# )\n\n# # Adds in field for innings pitched as fraction (better for aggregation)\n# player_game_stats['inningsPitchedAsFrac'] = np.where(\n# pd.isna(player_game_stats['inningsPitched']),\n# np.nan,\n# np.floor(player_game_stats['inningsPitched']) +\n# (player_game_stats['inningsPitched'] -\n# np.floor(player_game_stats['inningsPitched'])) * 10/3\n# )\n\n# # Add in Tom Tango pitching game score (https://www.mlb.com/glossary/advanced-stats/game-score)\n# player_game_stats['pitchingGameScore'] = (40\n# # + 2 * player_game_stats['outs']\n# + 1 * player_game_stats['strikeOutsPitching']\n# - 2 * player_game_stats['baseOnBallsPitching']\n# - 2 * player_game_stats['hitsPitching']\n# - 3 * player_game_stats['runsPitching']\n# - 6 * player_game_stats['homeRunsPitching']\n# )\n\n# # Add in criteria for no-hitter by pitcher (individual, not multiple pitchers)\n# player_game_stats['noHitter'] = np.where(\n# (player_game_stats['gamesStartedPitching'] == 1) &\n# (player_game_stats['inningsPitched'] >= 9) &\n# (player_game_stats['hitsPitching'] == 0),\n# 1, 0\n# )\n\n# player_date_stats_agg = pd.merge(\n# (player_game_stats.\n# groupby(['dailyDataDate', 'playerId'], as_index = False).\n# # Some aggregations that are not simple sums\n# agg(\n# numGames = ('gamePk', 'nunique'),\n# # Should be 1 team per player per day, but adding here for 1 exception:\n# # playerId 518617 (Jake Diekman) had 2 games for different teams marked\n# # as played on 5/19/19, due to resumption of game after he was traded\n# numTeams = ('gameTeamId', 'nunique'),\n# # Should be only 1 team for almost all player-dates, taking min to simplify\n# gameTeamId = ('gameTeamId', 'min')\n# )\n# ),\n# # Merge with a bunch of player stats that can be summed at date/player level\n# (player_game_stats.\n# groupby(['dailyDataDate', 'playerId'], as_index = False)\n# [['runsScored', 'homeRuns', 'strikeOuts', 'baseOnBalls', 'hits',\n# 'hitByPitch', 'atBats', 'caughtStealing', 'stolenBases',\n# 'groundIntoDoublePlay', 'groundIntoTriplePlay', 'plateAppearances',\n# 'totalBases', 'rbi', 'leftOnBase', 'sacBunts', 'sacFlies',\n# 'gamesStartedPitching', 'runsPitching', 'homeRunsPitching', \n# 'strikeOutsPitching', 'baseOnBallsPitching', 'hitsPitching',\n# 'inningsPitchedAsFrac', 'earnedRuns', \n# 'battersFaced','saves', 'blownSaves', 'pitchingGameScore', \n# 'noHitter'\n# ]].\n# sum()\n# ),\n# on = ['dailyDataDate', 'playerId'],\n# how = 'inner'\n# )\n\n# #### Turn games table into 1 row per team-game, then merge with team box scores ####\n# # Filter to regular or Postseason games w/ valid scores for this part\n# games_for_stats = games[\n# np.isin(games['gameType'], ['R', 'F', 'D', 'L', 'W', 'C', 'P']) &\n# ~pd.isna(games['homeScore']) &\n# ~pd.isna(games['awayScore'])\n# ]\n\n# # Get games table from home team perspective\n# games_home_perspective = games_for_stats.copy()\n\n# # Change column names so that \"team\" is \"home\", \"opp\" is \"away\"\n# games_home_perspective.columns = [\n# col_value.replace('home', 'team').replace('away', 'opp') for \n# col_value in games_home_perspective.columns.values]\n\n# games_home_perspective['isHomeTeam'] = 1\n\n# # Get games table from away team perspective\n# games_away_perspective = games_for_stats.copy()\n\n# # Change column names so that \"opp\" is \"home\", \"team\" is \"away\"\n# games_away_perspective.columns = [\n# col_value.replace('home', 'opp').replace('away', 'team') for \n# col_value in games_away_perspective.columns.values]\n\n# games_away_perspective['isHomeTeam'] = 0\n\n# # Put together games from home/away perspective to get df w/ 1 row per team game\n# team_games = (pd.concat([\n# games_home_perspective,\n# games_away_perspective\n# ],\n# ignore_index = True)\n# )\n\n# # Copy over team box scores data to modify\n# team_game_stats = teamBoxScores.copy()\n\n# # Change column names to reflect these are all \"team\" stats - helps \n# # to differentiate from individual player stats if/when joining later\n# team_game_stats.columns = [\n# (col_value + 'Team') \n# if (col_value not in ['dailyDataDate', 'home', 'teamId', 'gamePk',\n# 'gameDate', 'gameTimeUTC'])\n# else col_value\n# for col_value in team_game_stats.columns.values\n# ]\n\n# # Merge games table with team game stats\n# team_games_with_stats = pd.merge(\n# team_games,\n# team_game_stats.\n# # Drop some fields that are already present in team_games table\n# drop(['home', 'gameDate', 'gameTimeUTC'], axis = 1),\n# on = ['dailyDataDate', 'gamePk', 'teamId'],\n# # Doing this as 'inner' join excludes spring training games, postponed games,\n# # etc. from original games table, but this may be fine for purposes here \n# how = 'inner'\n# )\n\n# team_date_stats_agg = (team_games_with_stats.\n# groupby(['dailyDataDate', 'teamId', 'gameType', 'oppId', 'oppName'], \n# as_index = False).\n# agg(\n# numGamesTeam = ('gamePk', 'nunique'),\n# winsTeam = ('teamWinner', 'sum'),\n# lossesTeam = ('oppWinner', 'sum'),\n# runsScoredTeam = ('teamScore', 'sum'),\n# runsAllowedTeam = ('oppScore', 'sum')\n# )\n# )\n\n# # Prepare standings table for merge w/ player digital engagement data\n# # Pick only certain fields of interest from standings for merge\n# standings_selected_fields = (standings[['dailyDataDate', 'teamId', \n# 'streakCode', 'divisionRank', 'leagueRank', 'wildCardRank', 'pct'\n# ]].\n# rename(columns = {'pct': 'winPct'})\n# )\n\n# # Change column names to reflect these are all \"team\" standings - helps \n# # to differentiate from player-related fields if/when joining later\n# standings_selected_fields.columns = [\n# (col_value + 'Team') \n# if (col_value not in ['dailyDataDate', 'teamId'])\n# else col_value\n# for col_value in standings_selected_fields.columns.values\n# ]\n\n# standings_selected_fields['streakLengthTeam'] = (\n# standings_selected_fields['streakCodeTeam'].\n# str.replace('W', '').\n# str.replace('L', '').\n# astype(float)\n# )\n\n# # Add fields to separate winning and losing streak from streak code\n# standings_selected_fields['winStreakTeam'] = np.where(\n# standings_selected_fields['streakCodeTeam'].str[0] == 'W',\n# standings_selected_fields['streakLengthTeam'],\n# np.nan\n# )\n\n# standings_selected_fields['lossStreakTeam'] = np.where(\n# standings_selected_fields['streakCodeTeam'].str[0] == 'L',\n# standings_selected_fields['streakLengthTeam'],\n# np.nan\n# )\n\n# standings_for_digital_engagement_merge = (pd.merge(\n# standings_selected_fields,\n# dates_with_info[['dailyDataDate', 'inSeason']],\n# on = ['dailyDataDate'],\n# how = 'left'\n# ).\n# # Limit down standings to only in season version\n# query(\"inSeason\").\n# # Drop fields no longer necessary (in derived values, etc.)\n# drop(['streakCodeTeam', 'streakLengthTeam', 'inSeason'], axis = 1).\n# reset_index(drop = True)\n# )\n\n# #### Merge together various data frames to add date, player, roster, and team info ####\n# # Copy over player engagement df to add various pieces to it\n# player_engagement_with_info = nextDayPlayerEngagement.copy()\n\n# # Take \"row mean\" across targets to add (helps with studying all 4 targets at once)\n# player_engagement_with_info['targetAvg'] = np.mean(\n# player_engagement_with_info[['target1', 'target2', 'target3', 'target4']],\n# axis = 1)\n\n# # Merge in date information\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# dates_with_info[['dailyDataDate', 'date', 'year', 'month', 'inSeason',\n# 'seasonPart']],\n# on = ['dailyDataDate'],\n# how = 'left'\n# )\n\n# # Merge in some player information\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# players[['playerId', 'playerName', 'DOB', 'mlbDebutDate', 'birthCity',\n# 'birthStateProvince', 'birthCountry', 'primaryPositionName']],\n# on = ['playerId'],\n# how = 'left'\n# )\n\n# # Merge in some player roster information by date\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# (rosters[['dailyDataDate', 'playerId', 'statusCode', 'status', 'teamId']].\n# rename(columns = {\n# 'statusCode': 'rosterStatusCode',\n# 'status': 'rosterStatus',\n# 'teamId': 'rosterTeamId'\n# })\n# ),\n# on = ['dailyDataDate', 'playerId'],\n# how = 'left'\n# )\n \n# # Merge in team name from player's roster team\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# (teams[['id', 'teamName']].\n# rename(columns = {\n# 'id': 'rosterTeamId',\n# 'teamName': 'rosterTeamName'\n# })\n# ),\n# on = ['rosterTeamId'],\n# how = 'left'\n# )\n\n# # Merge in some player game stats (previously aggregated) from that date\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# player_date_stats_agg,\n# on = ['dailyDataDate', 'playerId'],\n# how = 'left'\n# )\n\n# # Merge in team name from player's game team\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# (teams[['id', 'teamName']].\n# rename(columns = {\n# 'id': 'gameTeamId',\n# 'teamName': 'gameTeamName'\n# })\n# ),\n# on = ['gameTeamId'],\n# how = 'left'\n# )\n\n# # Merge in some team game stats/results (previously aggregated) from that date\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# team_date_stats_agg.rename(columns = {'teamId': 'gameTeamId'}),\n# on = ['dailyDataDate', 'gameTeamId'],\n# how = 'left'\n# )\n\n# # Merge in player transactions of note on that date\n \n# # Merge in some pieces of team standings (previously filter/processed) from that date\n# player_engagement_with_info = pd.merge(\n# player_engagement_with_info,\n# standings_for_digital_engagement_merge.\n# rename(columns = {'teamId': 'gameTeamId'}),\n# on = ['dailyDataDate', 'gameTeamId'],\n# how = 'left'\n# )\n\n# #display(player_engagement_with_info)\n# player_engagement_with_info.head(5)\n","metadata":{"_kg_hide-input":true,"_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:48.029926Z","iopub.execute_input":"2021-07-03T16:48:48.030276Z","iopub.status.idle":"2021-07-03T16:48:48.043020Z","shell.execute_reply.started":"2021-07-03T16:48:48.030239Z","shell.execute_reply":"2021-07-03T16:48:48.042159Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Exploratory Analysis\n\nAs you can see above, the starter code converts the initial ```train.csv``` dataset with 1216 rows & several packed JSONs into a dataset with 2.5M+ rows. THe processed dataframe ```player_engagement_with_info``` contains data in a much more simpler format for data analysis. Let's start exploring the dataset and start answering the questions highlighted at the start of the notebook. \n\n","metadata":{}},{"cell_type":"code","source":"import pickle\n\n# Pkl_Filename = \"player_engagaement_with_info.pkl\" \n\n#player_engagement_with_info.to_pickle('player_engagement_with_info.pkl')\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:48:48.044556Z","iopub.execute_input":"2021-07-03T16:48:48.045119Z","iopub.status.idle":"2021-07-03T16:48:48.056240Z","shell.execute_reply.started":"2021-07-03T16:48:48.045083Z","shell.execute_reply":"2021-07-03T16:48:48.055351Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"\nplayer_engagement_with_info = pd.read_pickle(\"../input/mlb-player-digital-engagement-merged-data/player_engagement_with_info.pkl\")","metadata":{"_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-07-03T16:48:48.057946Z","iopub.execute_input":"2021-07-03T16:48:48.058553Z","iopub.status.idle":"2021-07-03T16:49:01.993617Z","shell.execute_reply.started":"2021-07-03T16:48:48.058505Z","shell.execute_reply":"2021-07-03T16:49:01.992811Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_engagement_with_info","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:01.994918Z","iopub.execute_input":"2021-07-03T16:49:01.995235Z","iopub.status.idle":"2021-07-03T16:49:03.219737Z","shell.execute_reply.started":"2021-07-03T16:49:01.995202Z","shell.execute_reply":"2021-07-03T16:49:03.218723Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Some of the columns present in the dataset above are - \n\n### Player Info - \n* DOB\n* MLB Debut Date\n* Birth Country\n* Position \n* Roster Status\n\n#### Player Batting Scores - \n* Runs Scored\n* Home Runs\n* Strike Outs \n* RBI - Runs Batted In\n\n#### Player Pitching Scores - \n* Runs Pitching\n* Strike Outs Pitching\n* Hits Pitching\n\n#### Team Stats - \n* Team & Opposition Info\n* Runs Scored & Allowed\n* Wins & Loss Record\n\n#### Target Columns - Target1 - Target 4\n\nLet's first start by taking a look at Target Columns - \n\n### Target Columns \n","metadata":{}},{"cell_type":"markdown","source":"\n\n\n","metadata":{}},{"cell_type":"code","source":"import plotly.express as px\ntime_target_gp=player_engagement_with_info.groupby(['dailyDataDate']).agg({'target1':'mean','target2':'mean','target3':'mean','target4':'mean','targetAvg':'mean'}).reset_index()\n\nfrom plotly.subplots import make_subplots\nimport plotly.graph_objects as go\n\nfig = make_subplots(rows=3, cols=2)\n\nfig.add_trace(\n go.Scatter(x=time_target_gp['dailyDataDate'], y=time_target_gp['target1'],name='Target1'),\n row=1, col=1\n)\n\nfig.add_trace(\n go.Scatter(x=time_target_gp['dailyDataDate'], y=time_target_gp['target2'],name='Target2'),\n row=1, col=2\n)\nfig.add_trace(\n go.Scatter(x=time_target_gp['dailyDataDate'], y=time_target_gp['target3'],name='Target3'),\n row=2, col=1\n)\nfig.add_trace(\n go.Scatter(x=time_target_gp['dailyDataDate'], y=time_target_gp['target4'],name='Target4'),\n row=2, col=2\n)\nfig.add_trace(\n go.Scatter(x=time_target_gp['dailyDataDate'], y=time_target_gp['targetAvg'],name='targetAvg'),\n row=3, col=1\n)\n\n\nfig.update_layout(height=600, width=800, title_text=\"Daily Average Target Variable Values\")\nfig.show()\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:03.222440Z","iopub.execute_input":"2021-07-03T16:49:03.222803Z","iopub.status.idle":"2021-07-03T16:49:06.101644Z","shell.execute_reply.started":"2021-07-03T16:49:03.222759Z","shell.execute_reply":"2021-07-03T16:49:06.100879Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_engagement_with_info['quarter']=player_engagement_with_info['dailyDataDate'].dt.quarter\nplayer_engagement_with_info['month']=player_engagement_with_info['dailyDataDate'].dt.month\nplayer_engagement_with_info['year']=player_engagement_with_info['dailyDataDate'].dt.year\n\nplayer_engagement_with_info\n\nmonth_gp=player_engagement_with_info.groupby('month').agg({'target1':'mean','target2':'mean','target3':'mean','target4':'mean'}).reset_index()\n\nfig=go.Figure()\n\nfig.add_trace(go.Scatter(x=month_gp['month'], y=month_gp['target1'],\n mode='lines',\n name='target1'))\nfig.add_trace(go.Scatter(x=month_gp['month'], y=month_gp['target2'],\n mode='lines',\n name='target2'))\nfig.add_trace(go.Scatter(x=month_gp['month'], y=month_gp['target3'],\n mode='lines',\n name='target3'))\n\nfig.add_trace(go.Scatter(x=month_gp['month'], y=month_gp['target4'],\n mode='lines',\n name='target4'))\n\nfig.update_layout(title='Variation in Average Target Values with Month')\nfig.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:06.103267Z","iopub.execute_input":"2021-07-03T16:49:06.103555Z","iopub.status.idle":"2021-07-03T16:49:06.771399Z","shell.execute_reply.started":"2021-07-03T16:49:06.103525Z","shell.execute_reply":"2021-07-03T16:49:06.770456Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#Time Series Correlation\nimport seaborn as sns\ncorr=time_target_gp.corr()\ncorr","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:06.772805Z","iopub.execute_input":"2021-07-03T16:49:06.773139Z","iopub.status.idle":"2021-07-03T16:49:06.788584Z","shell.execute_reply.started":"2021-07-03T16:49:06.773104Z","shell.execute_reply":"2021-07-03T16:49:06.787860Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"daily=player_engagement_with_info.groupby('dailyDataDate').agg({'target1':'mean','target2':'mean','target3':'mean','target4':'mean'}).reset_index()\n\nfig = make_subplots(\n rows=3, cols=3,shared_yaxes=True,\n subplot_titles=(\"Target1 vs Target2\", \"Target1 vs Target3\", \"Target1 vs Target4\",\"Target2 vs Target3\", \"Target2 vs Target4\",\"\", \"Target3 vs Target4\"))\nfig.add_trace(\n go.Scatter(y=daily['target2'], x=daily['target1'],mode='markers'),\n row=1, col=1\n )\nfig.add_trace(\n go.Scatter(y=daily['target3'], x=daily['target1'],mode='markers'),\n row=1, col=2\n )\nfig.add_trace(\n go.Scatter(y=daily['target4'], x=daily['target1'],mode='markers'),\n row=1, col=3\n )\nfig.add_trace(\n go.Scatter(y=daily['target3'], x=daily['target2'],mode='markers'),\n row=2, col=1\n )\nfig.add_trace(\n go.Scatter(y=daily['target4'], x=daily['target2'],mode='markers'),\n row=2, col=2\n )\nfig.add_trace(\n go.Scatter(y=daily['target4'], x=daily['target3'],mode='markers'),\n row=3, col=1\n )\nfig.update_layout(showlegend=False)\n\nfig.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:06.789822Z","iopub.execute_input":"2021-07-03T16:49:06.790167Z","iopub.status.idle":"2021-07-03T16:49:06.994071Z","shell.execute_reply.started":"2021-07-03T16:49:06.790133Z","shell.execute_reply":"2021-07-03T16:49:06.993175Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_mean=player_engagement_with_info.groupby('playerId').agg({'target1':'mean','target2':'mean','target3':'mean','target4':'mean'}).reset_index()\nplayer_mean\n\n\nfig=go.Figure()\n# fig.add_trace(go.Histogram(x=player_mean['target1'],histnorm='probability',name='Target1'))\n# fig.add_trace(go.Histogram(x=player_mean['target2'],histnorm='probability',name='Target2'))\n# fig.add_trace(go.Histogram(x=player_mean['target3'],histnorm='probability',name='Target3'))\n# fig.add_trace(go.Histogram(x=player_mean['target4'],histnorm='probability',name='Target4'))\n# fig.update_layout(barmode='overlay',title='Distribution of Average Player Target Scores')\n# fig.update_traces(opacity=0.75)\n\nfig.add_trace(go.Violin(y=player_mean['target1'],name='Target1',box_visible=True,meanline_visible=True))\nfig.add_trace(go.Violin(y=player_mean['target2'],name='Target2',box_visible=True,meanline_visible=True))\nfig.add_trace(go.Violin(y=player_mean['target3'],name='Target3',box_visible=True,meanline_visible=True))\nfig.add_trace(go.Violin(y=player_mean['target4'],name='Target4',box_visible=True,meanline_visible=True))\nfig.update_layout(title='Distribution of Average Player Target Scores')\n# fig.update_traces(opacity=0.75)\n\nfig.show()\n\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:06.995535Z","iopub.execute_input":"2021-07-03T16:49:06.995892Z","iopub.status.idle":"2021-07-03T16:49:07.107829Z","shell.execute_reply.started":"2021-07-03T16:49:06.995857Z","shell.execute_reply":"2021-07-03T16:49:07.106901Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Some of the things that are visible from the charts above - \n* Target variables seem to be cyclical in nature with same pattern repeating every year\n* **The Target variables don't seem to have significant Pearson's correlation with each other**. However some combinations do seem to be related to each other - for ex. Target 2 doesn't have any relation with Target 3 but seems to vary along with Target 4\n* Monthwise plot for the average of Target variables shows significant seasonality. **Target Values seem to peak in the month of March & then dip during the month of October**. Similar trend is observable in all the target variables\n* The mean target values for Players above shows that the **mean value for Target2 is much higher than other target variables**. \n* Each of these target variables have a high number of outlier values - showing that a smaller group of players tend to outperform the vast majority\n\nIf we also look at the sample records for the ```player_engagement_with_info``` table we can see a lot of blank values for game stats. It is because we are required to predict engagement for players even on days that they are not playing. Therefore on non game days these values will appear as blank. Let's take a look at the breakdown of gamedays vs non gamedays in the dataset and also the average values for engagement on game days and non game days - ","metadata":{}},{"cell_type":"code","source":"#create a flag for gamedays and non-gamedays for players\nplayer_engagement_with_info['gameday']=~player_engagement_with_info.gameTeamId.isna()\nplayer_engagement_with_info['flag']=0\nplayer_engagement_with_info.loc[player_engagement_with_info.gameTeamId.isna(),'flag']=-1\n\nplayer_engagement_with_info.gameday.value_counts()\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:07.109218Z","iopub.execute_input":"2021-07-03T16:49:07.109571Z","iopub.status.idle":"2021-07-03T16:49:08.980199Z","shell.execute_reply.started":"2021-07-03T16:49:07.109526Z","shell.execute_reply":"2021-07-03T16:49:08.979202Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"gameday_gp=player_engagement_with_info.groupby(['gameday']).agg({'targetAvg':'mean'}).reset_index()\npx.bar(gameday_gp,x='gameday',y='targetAvg',title='Difference between targetAvg on MatchDays vs non MatchDays')","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:08.981584Z","iopub.execute_input":"2021-07-03T16:49:08.981951Z","iopub.status.idle":"2021-07-03T16:49:09.900756Z","shell.execute_reply.started":"2021-07-03T16:49:08.981914Z","shell.execute_reply":"2021-07-03T16:49:09.899834Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"As we can see above, the number of non gameday records in the dataset are almost 10x higher than gameday records. Also as expected, the engagement scores are much higher on game days compared to non gamedays. Let's now take a deeper look at the data to try and understand how does engagement score decay on non-playing days. \n","metadata":{}},{"cell_type":"code","source":"player_engagement_with_info.sort_values(by=['playerId','dailyDataDate'],inplace=True,ascending=True)\nplayer_engagement_with_info=player_engagement_with_info.reset_index(drop=True)\n#player_engagement_with_info.loc[player_engagement_with_info['gameday']==True,'daysSinceLastGame']=0\n\nplayer_engagement_with_info['daysSinceLastGame']=0\n\n# chk=player_engagement_with_info.head(10000)\n# chk.to_csv('chk.csv')","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:09.902170Z","iopub.execute_input":"2021-07-03T16:49:09.902545Z","iopub.status.idle":"2021-07-03T16:49:17.956650Z","shell.execute_reply.started":"2021-07-03T16:49:09.902500Z","shell.execute_reply":"2021-07-03T16:49:17.955835Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_engagement_with_info.sort_values(by=['playerId','dailyDataDate'],inplace=True,ascending=True)","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:17.957872Z","iopub.execute_input":"2021-07-03T16:49:17.958196Z","iopub.status.idle":"2021-07-03T16:49:19.959797Z","shell.execute_reply.started":"2021-07-03T16:49:17.958162Z","shell.execute_reply":"2021-07-03T16:49:19.958925Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def count_consecutive_items_n_cols(df, col_name_list, output_col):\n cum_sum_list = [\n (df[col_name] != df[col_name].shift(1)).cumsum().tolist() for col_name in col_name_list\n ]\n df[output_col] = df.groupby(\n [\"_\".join(map(str, x)) for x in zip(*cum_sum_list)]\n ).cumcount() + 1\n return df\n\nplayer_engagement_with_info=count_consecutive_items_n_cols(player_engagement_with_info,['playerId','gameday'],'daysSinceLastGame')\nplayer_engagement_with_info.loc[player_engagement_with_info['gameday']==True,'daysSinceLastGame']=0\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:19.961000Z","iopub.execute_input":"2021-07-03T16:49:19.961330Z","iopub.status.idle":"2021-07-03T16:49:25.161709Z","shell.execute_reply.started":"2021-07-03T16:49:19.961297Z","shell.execute_reply":"2021-07-03T16:49:25.160862Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#Calculate Days Since Last Game\nlag_gp=player_engagement_with_info.groupby(['daysSinceLastGame']).agg({'targetAvg':'mean','playerId':'nunique'}).reset_index()\npx.bar(lag_gp,x='daysSinceLastGame',y='targetAvg',title='Variation in targetAvg with daysSinceLastGame')\n\nfig1 = make_subplots(specs=[[{\"secondary_y\": True}]])\n\n# Add traces\nfig1.add_trace(\n go.Bar(x=lag_gp['daysSinceLastGame'], y=lag_gp['targetAvg'], name=\"targetAvg\"),\n secondary_y=True,\n)\n\nfig1.add_trace(\n go.Scatter(x=lag_gp['daysSinceLastGame'], y=lag_gp['playerId'], name=\"No. of Players\"),\n secondary_y=False,\n)\nfig1.update_layout(title='Variation in targetAvg by daysSinceLastGame',xaxis_title='daysSinceLastGame')\nfig1.show()\n\nimmediate_drop=player_engagement_with_info.loc[player_engagement_with_info['daysSinceLastGame']<=10]\nimmediate_drop\n\nlag_gp=immediate_drop.groupby(['daysSinceLastGame']).agg({'targetAvg':'mean','playerId':'nunique'}).reset_index()\nlag_gp\n\nfig2=px.line(lag_gp,x='daysSinceLastGame',y='targetAvg',title='Drop in targetAvg in immediate days after a game')\nfig2.show()","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:25.163064Z","iopub.execute_input":"2021-07-03T16:49:25.163398Z","iopub.status.idle":"2021-07-03T16:49:25.756643Z","shell.execute_reply.started":"2021-07-03T16:49:25.163363Z","shell.execute_reply":"2021-07-03T16:49:25.755707Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"high_target=player_engagement_with_info.loc[player_engagement_with_info['daysSinceLastGame']>=1000]\nhigh_target.loc[high_target.rosterTeamName.isna(),'rosterTeamName']='No Team'\n\nhigh_target_players=high_target.groupby(['playerName']).agg({'targetAvg':'mean'}).reset_index()\n\nhigh_target_players=high_target_players.sort_values(by='targetAvg',ascending=False).head(10)\npx.bar(high_target_players,x='playerName',y='targetAvg',title='Non-Active players with highest targetAvg')\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:25.757988Z","iopub.execute_input":"2021-07-03T16:49:25.758318Z","iopub.status.idle":"2021-07-03T16:49:25.841606Z","shell.execute_reply.started":"2021-07-03T16:49:25.758282Z","shell.execute_reply":"2021-07-03T16:49:25.840676Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"We calculated a column ```daysSinceLastGame``` that keeps a track of number of days since player last played a game. Some of these players have been inactive for upto 2-3 years before they even played a game. We can see the following things above -\n* The target engagement is higher immediately on game day but then significantly declines with time\n* The drop in target engagement is not steady. There are several peaks observable around 200, 800 and 1000 day period. \n* We looked at the drop in engagement immediately after the game and observed it initially goes down but then picks up again around 3-5 day period and then goes down again\n* The rise in target engagement for players after remaining inactive for 1000 days was a bit perplexing. Therefore we filtered the data for these players and identified such players. 22 year old Brailyn Marquez & 23 year old Alex Kiriloff had the highest engagement scores\n* A quick Google search revealed that some of the reasons for high engagement are player transfers & players returning from injury after a long break, leading to an increase in engagement. ","metadata":{}},{"cell_type":"code","source":"avg_gp_between_games=immediate_drop.groupby(['daysSinceLastGame']).agg({'playerId':'count'}).reset_index()\n#avg_gp_between_games","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:25.843001Z","iopub.execute_input":"2021-07-03T16:49:25.843346Z","iopub.status.idle":"2021-07-03T16:49:25.857449Z","shell.execute_reply.started":"2021-07-03T16:49:25.843310Z","shell.execute_reply":"2021-07-03T16:49:25.856746Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# team_gp=player_engagement_with_info.groupby('year').rosterTeamName.nunique()\n# team_gp","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:25.858669Z","iopub.execute_input":"2021-07-03T16:49:25.859062Z","iopub.status.idle":"2021-07-03T16:49:25.863028Z","shell.execute_reply.started":"2021-07-03T16:49:25.859025Z","shell.execute_reply":"2021-07-03T16:49:25.861835Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Top Players\n\nLet's try to understand who the most successful players are in the MLB over the years 2018-2021 and which positions they occupy on the field. ","metadata":{}},{"cell_type":"code","source":"player_high=player_engagement_with_info.groupby('playerId').agg({'targetAvg':'mean'}).reset_index()\nplayer_high.sort_values(by='targetAvg',inplace=True,ascending=False)\nplayer_high3=player_high.head(3)\nplayer_high3\n\ntop3_players=player_engagement_with_info.loc[player_engagement_with_info['playerId'].isin(player_high3.playerId)]\ntop3_players=top3_players.groupby(['playerId','year','month']).agg({'targetAvg':'mean'}).reset_index()\ntop3_players['month_year'] = top3_players.year.astype(str) + '_'+top3_players.month.astype(str)\n\nplayers_info=players[['playerId','playerName','primaryPositionName']]\n\ntop3_players=pd.merge(left=top3_players,right=players_info,left_on='playerId',right_on='playerId',how='inner')\n\n\npx.line(top3_players,x='month_year',y='targetAvg',color='playerName',title='targetAvg Engagement patterns for Top 3 Players')","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:25.864559Z","iopub.execute_input":"2021-07-03T16:49:25.864940Z","iopub.status.idle":"2021-07-03T16:49:25.987709Z","shell.execute_reply.started":"2021-07-03T16:49:25.864901Z","shell.execute_reply":"2021-07-03T16:49:25.986801Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_high100=player_high.head(100)\n\ntop100_players=pd.merge(left=player_high100,right=players_info,left_on='playerId',right_on='playerId',how='inner')\ntop100_players\n\nfig=px.scatter(top100_players,y='targetAvg',color='primaryPositionName',title='targetAvg scores for top 100 players')\nfig.show()\n\nfig1 = px.pie(top100_players, values='targetAvg', names='primaryPositionName', title='Breakdown of top 100 players by position')\n\nfig1.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:25.992583Z","iopub.execute_input":"2021-07-03T16:49:25.992849Z","iopub.status.idle":"2021-07-03T16:49:26.132218Z","shell.execute_reply.started":"2021-07-03T16:49:25.992824Z","shell.execute_reply":"2021-07-03T16:49:26.131300Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Findings from the charts above - \n* **Mike Trout, Bryce Harper & Aaron Judge stand out as the top 3 players during the period of 2018-2021**. Each of them had a really outstanding year where their targetAvg values was much higher than other years. \n* As we noticed in the overall monthly targetAvg values chart, the targetAvg values for these top players stayed highest in March & then dipped to its lowest in October. \n* I also took a look at the top 100 players with highest targetAvg values. **Top 4 players all turn out to be Designated Hitters**. Designated Hitter is a player who bats in place of a pitcher. The targetAvg values for these top 4 players are significantly higher than rest of the group\n* I also looked at the breakdown of top 100 players by position. **30% of these players were Designated Hitters & approx another 30% were pitchers**, which shows that these players are much likelier to score higher than rest of the team players on engagement score metric. \n\nHaving taken a look at the top 100 players, let's take a look at all the players in the dataset and average scores by position. The image below shows positioning of different players on the baseball field - \n\n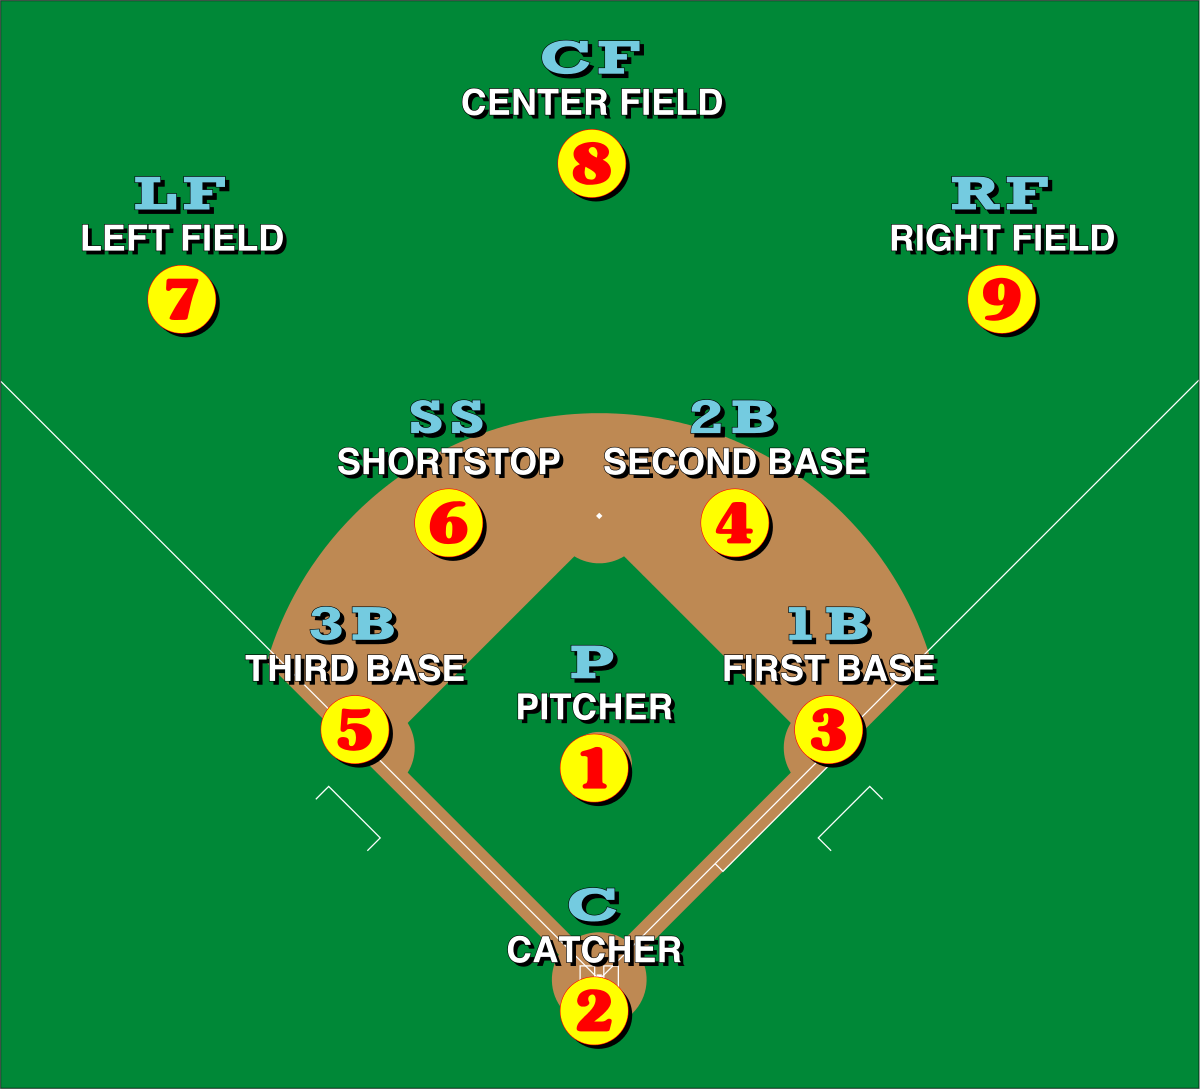","metadata":{}},{"cell_type":"code","source":"position_avg=player_engagement_with_info.groupby(['primaryPositionName']).agg({'targetAvg':'mean','playerId':'nunique'}).reset_index()\nposition_avg.sort_values(by='targetAvg',inplace=True,ascending=False)\n\nfig=px.bar(position_avg,x='primaryPositionName',y='targetAvg',title='Target Avg values by Position')\nfig.show()\nposition_avg.sort_values(by='playerId',inplace=True,ascending=False)\n\nfig1=px.bar(position_avg,x='primaryPositionName',y='playerId',title='Count of Players by Position')\nfig1.show()\n\n\nplayer_high_join=pd.merge(left=player_high,right=players,how='inner')\n#player_high_join=player_high_join.loc[player_high_join['primaryPositionName']=='Pitcher']\nplayer_high_join\n\npx.violin(player_high_join,y='targetAvg',box=True,x='primaryPositionName',title='Distribution of targetAvg by primaryPosition')","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:26.135024Z","iopub.execute_input":"2021-07-03T16:49:26.135371Z","iopub.status.idle":"2021-07-03T16:49:26.607668Z","shell.execute_reply.started":"2021-07-03T16:49:26.135333Z","shell.execute_reply":"2021-07-03T16:49:26.606726Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Here again we see that the average target scores for **Designated Hitters are higher than rest of the positions**. One thing though that comes across as a surprise is that average scores for pitchers is quite low and much behind several other positions. This shows that **while some pitchers are likely to be among the best, there are several pitchers who don't do so well over the season, bringing down the average of the entire group**. \n\nAlso we see that the overall distribution of players in the dataset seems to be heavily skewed towards pitchers, which does look a bit odd. The violin plot above shows that though there are lot of outliers in the pitchers group, the overall average for the group is quite low. \n\n### Player Demographics\n\n","metadata":{}},{"cell_type":"code","source":"player_data=player_engagement_with_info[['playerId','dailyDataDate','targetAvg']]\n#player_data\n\nplayer_demog_data=pd.merge(left=player_data,right=players,left_on='playerId',right_on='playerId',how='inner')\n\nplayer_demog_data['DOB'] = pd.to_datetime(player_demog_data['DOB'], format=\"%Y-%m-%d\")\nplayer_demog_data['mlbDebutDate'] = pd.to_datetime(player_demog_data['mlbDebutDate'], format=\"%Y-%m-%d\")\n\nplayer_demog_data['age'] = (player_demog_data['dailyDataDate'] - player_demog_data['DOB']).dt.days\nplayer_demog_data['age']=(player_demog_data['age']/365).astype(int)\n\nplayer_demog_data['yearsSinceDebut'] = (player_demog_data['dailyDataDate'] - player_demog_data['mlbDebutDate']).dt.days\nplayer_demog_data['yearsSinceDebut']=player_demog_data['yearsSinceDebut']/365\nplayer_demog_data['yearsSinceDebut']=player_demog_data['yearsSinceDebut'].fillna(-1)\nplayer_demog_data['yearsSinceDebut']=player_demog_data['yearsSinceDebut'].astype(int)\n#player_demog_data\n\ndef plot_viz(colnames):\n j=1\n k=1\n leng=len(colnames)\n tup=('yearsSinceDebut vs targetAvg','Country of Birth vs targetAvg','Age vs targetAvg','Weight vs targetAvg')\n fig = make_subplots(rows=2, cols=2,subplot_titles=tup)\n for i in range(leng):\n gp=player_demog_data.groupby(colnames[i]).agg({'targetAvg':'mean'}).reset_index()\n # print(i,j,k)\n fig.add_trace(go.Bar(x=gp.iloc[:,0],y=gp.iloc[:,1]),row=j,col=k)\n\n if(i==1):\n k=k+1\n if(j==2):\n j=1\n else :\n j=j+1\n fig.update_layout(showlegend=False)\n fig.show()\n # fig.show()\n \n \ncolnames=['yearsSinceDebut','age','birthCountry','weight']\nplot_viz(colnames)\n\n\n#gp=player_demog_data.groupby(colnames[0]).agg({'targetAvg':'mean'}).reset_index()\n#gp.iloc[:,0]","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:26.609068Z","iopub.execute_input":"2021-07-03T16:49:26.609395Z","iopub.status.idle":"2021-07-03T16:49:29.210450Z","shell.execute_reply.started":"2021-07-03T16:49:26.609360Z","shell.execute_reply":"2021-07-03T16:49:29.209686Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"* Players performance generally tends to get better with age in MLB, which is a bit odd when you compare this to other sports. Players above 40 have a very high engagement scores, it could also be due to a small number of players in the group driving the average up\n* New & young players generally don't do as well compared to their new counterparts. The average engagement scores tend to increase with levels of experience among players. \n* Overseas players generally tend to better than American players on average. This could be due to the fact that as an overseas player, someone has to be really good to become a pro MLB player, whereas in USA it might be a bit easier to get notived and also due to the high volume of players the average gets lowered. \n* There is no clear relation between player's weight & their targetAvg score performance\n\n\n### Team Performances\nLet's now look at the average scores for the teams involved over the years. ","metadata":{}},{"cell_type":"code","source":"team_gp=player_engagement_with_info.groupby(['rosterTeamName','year']).agg({'targetAvg':'mean','winsTeam':'sum','numGamesTeam':'sum'}).reset_index()\nteam_gp['pct_wins']=team_gp['winsTeam']/team_gp['numGamesTeam']\nteam_gp['year'] = team_gp['year'].apply(str)\n\nteam_gp.sort_values(by='targetAvg',inplace=True,ascending=False)\nteam_gp[\"team_year\"] = team_gp[\"rosterTeamName\"].astype(str) + '_'+team_gp[\"year\"].astype(str)\n\n#team_gp","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:29.211677Z","iopub.execute_input":"2021-07-03T16:49:29.212054Z","iopub.status.idle":"2021-07-03T16:49:29.607611Z","shell.execute_reply.started":"2021-07-03T16:49:29.212017Z","shell.execute_reply":"2021-07-03T16:49:29.606819Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"px.scatter(team_gp,x='pct_wins',y='targetAvg',text='team_year',title='Variation of targetAvg with Team WinPercent over Seasons')","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:29.608983Z","iopub.execute_input":"2021-07-03T16:49:29.609431Z","iopub.status.idle":"2021-07-03T16:49:29.669641Z","shell.execute_reply.started":"2021-07-03T16:49:29.609386Z","shell.execute_reply":"2021-07-03T16:49:29.668726Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"team_month_yr_gp=player_engagement_with_info.groupby(['rosterTeamName','year','month']).agg({'targetAvg':'mean'}).reset_index()\nteam_month_yr_gp=team_month_yr_gp.sort_values(by=['year','month'],ascending=True)\nteam_month_yr_gp['month_yr']=team_month_yr_gp['month'].astype(str)+\"_\"+team_month_yr_gp['year'].astype(str)\nteam_month_yr_gp['month_yr1'] = pd.to_datetime(team_month_yr_gp[['year', 'month']].assign(DAY=1))\n\nteam_month_yr_gp\n\n# my_raceplot = barplot(team_month_yr_gp, item_column='rosterTeamName', value_column='targetAvg', time_column='month_yr')\n# my_raceplot.plot(item_label = 'team name', value_label = 'number of followers', frame_duration = 800,title=\"Top 10 teams with highest targetAvg score from 2018-2021\")\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:29.671102Z","iopub.execute_input":"2021-07-03T16:49:29.671474Z","iopub.status.idle":"2021-07-03T16:49:30.090263Z","shell.execute_reply.started":"2021-07-03T16:49:29.671438Z","shell.execute_reply":"2021-07-03T16:49:30.089321Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# my_raceplot = barplot(team_month_yr_gp, item_column='rosterTeamName', value_column='targetAvg', time_column='month_yr1')\n# my_raceplot.plot(item_label = 'team name', value_label = 'targetAvgScore', frame_duration = 800,title=\"Top 10 teams with highest targetAvg score from 2018-2021\")\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:30.091767Z","iopub.execute_input":"2021-07-03T16:49:30.092134Z","iopub.status.idle":"2021-07-03T16:49:30.095819Z","shell.execute_reply.started":"2021-07-03T16:49:30.092097Z","shell.execute_reply":"2021-07-03T16:49:30.094914Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"rankscores=player_engagement_with_info.groupby('divisionRankTeam').agg({'targetAvg':'mean'}).reset_index()\nrankscores\n\nleaguerankscores=player_engagement_with_info.groupby('leagueRankTeam').agg({'targetAvg':'mean'}).reset_index()\nleaguerankscores\n\npx.line(leaguerankscores,x='leagueRankTeam',y='targetAvg',title='Variation in TargetAvg with League Rank for Team')","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:30.097160Z","iopub.execute_input":"2021-07-03T16:49:30.097607Z","iopub.status.idle":"2021-07-03T16:49:30.198445Z","shell.execute_reply.started":"2021-07-03T16:49:30.097568Z","shell.execute_reply":"2021-07-03T16:49:30.197704Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"team_player_gp=player_engagement_with_info.groupby(['rosterTeamName','playerName']).agg({'targetAvg':'mean'}).reset_index()\n#team_player_gp.sort_values(['rosterTeamName','targetAvg'],ascending=['True','False'], inplace=True)\n\nteam_player_sum=team_player_gp.groupby('rosterTeamName').agg({'targetAvg':'sum'}).reset_index()\nteam_player_sum.columns=['rosterTeamName','targetAvgSum']\n\nteam_player_gp[\"rank\"] = team_player_gp.groupby(['rosterTeamName'])[\"targetAvg\"].rank(\"dense\", ascending=False)\nteam_player_gp\n\nteam_player_gp_rank=pd.merge(left=team_player_gp,right=team_player_sum,how='inner')\nteam_player_gp_rank10=team_player_gp_rank.loc[team_player_gp_rank['rank']<=10]\nteam_player_gp_rank10.sort_values(by=['rosterTeamName','rank'],inplace=True)\n\nteam_player_gp_rank10['top10score']=team_player_gp_rank10.groupby(['rosterTeamName'])['targetAvg'].apply(lambda x: x.cumsum())\nteam_player_gp_rank10\n\nteam_player_gp_rank10_contribution=team_player_gp_rank10.loc[team_player_gp_rank10['rank']==10]\nteam_player_gp_rank10_contribution\nteam_player_gp_rank10_contribution['pct_contribution_top10']=team_player_gp_rank10_contribution['top10score']/team_player_gp_rank10_contribution['targetAvgSum']\nteam_player_gp_rank10_contribution.sort_values(by='pct_contribution_top10',ascending=False,inplace=True)\n\nteam_avg=player_engagement_with_info.groupby(['rosterTeamName']).agg({'targetAvg':'mean'}).reset_index()\n\n\nteam_player_gp_rank10_contribution=pd.merge(left=team_player_gp_rank10_contribution,right=team_avg,how='inner',on='rosterTeamName')\n\npx.scatter(team_player_gp_rank10_contribution,y='pct_contribution_top10',x='targetAvgSum',size='targetAvg_y',text='rosterTeamName',title='Contribution of Top10 Players towards sum of team targetAvg scores' )\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:30.199604Z","iopub.execute_input":"2021-07-03T16:49:30.199965Z","iopub.status.idle":"2021-07-03T16:49:31.130186Z","shell.execute_reply.started":"2021-07-03T16:49:30.199923Z","shell.execute_reply":"2021-07-03T16:49:31.129247Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"* Each point in the first scatter plot shows average values for target scores during a particular season. **Familiar team names like Yankees, Red Sox & Dodgers show up at the top, which shows that teams that have a high win percentage generally tend to have higher targetAvg as well**\n* Yankees in 2018 has been the most engaged team\n* Looking at the raceplot above, the list of top 10 teams has been fairly constant over time\n* I also looked at the variation of targetAvg scores by leagueRankTeam. **Teams that have a better rank tend to have higher targetAvg scores as well.**\n* We then looked at contribution of top 10 players towards the sum of targetAvg of all players in the team. Yankees clearly stand out here - they have the highest sum of targetAvg by a fair margin and only 30% of their total comes in from top10 players\n* Less successful teams like Astros, Cardinals & Rockies are much more dependent on their top 10 players\n\nLet's also quickly take a look at variation of targetAvg scores by game types as well ","metadata":{}},{"cell_type":"code","source":"gametype=player_engagement_with_info.groupby('gameType').agg({'targetAvg':'mean'}).reset_index()\npx.bar(gametype,x='gameType',y='targetAvg',title='Variation of targetAvg with GameType')","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:31.131568Z","iopub.execute_input":"2021-07-03T16:49:31.131929Z","iopub.status.idle":"2021-07-03T16:49:31.612731Z","shell.execute_reply.started":"2021-07-03T16:49:31.131892Z","shell.execute_reply":"2021-07-03T16:49:31.611828Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"seasontype=player_engagement_with_info.groupby('seasonPart').agg({'targetAvg':'mean'}).reset_index()\npx.bar(seasontype,x='seasonPart',y='targetAvg',title='Variation of targetAvg with seasonPart')","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:31.614038Z","iopub.execute_input":"2021-07-03T16:49:31.614549Z","iopub.status.idle":"2021-07-03T16:49:31.873155Z","shell.execute_reply.started":"2021-07-03T16:49:31.614504Z","shell.execute_reply":"2021-07-03T16:49:31.872217Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Preseason period tends to have the highest engagement score & postseason has the lowest targetAvg. The targetAvg scores tends to remain high during the Regular Season. Let's now take a look at pitching & batting stats to see how they impact targetAvg scores. \n\n### Pitching & Batting Stats \n\nThere are lots of detailed stats around batting & pitching that are available in the dataset. Let's try to see how good & bad performances lead to engagement. ","metadata":{}},{"cell_type":"code","source":"player_engagement_with_info.sort_values(by=['playerId','dailyDataDate'],inplace=True)\n#player_engagement_with_info","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:31.874582Z","iopub.execute_input":"2021-07-03T16:49:31.874944Z","iopub.status.idle":"2021-07-03T16:49:33.779163Z","shell.execute_reply.started":"2021-07-03T16:49:31.874907Z","shell.execute_reply":"2021-07-03T16:49:33.778277Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"pitching_stats=player_engagement_with_info.groupby(['pitchingGameScore']).agg({'targetAvg':'mean','playerId':'count'}).reset_index()\npitching_stats\n\npx.scatter(pitching_stats,x='pitchingGameScore',y='targetAvg',title='Variation in targetAvg scores with Tom Tango pitchingGameScore')\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:33.780432Z","iopub.execute_input":"2021-07-03T16:49:33.780846Z","iopub.status.idle":"2021-07-03T16:49:33.862885Z","shell.execute_reply.started":"2021-07-03T16:49:33.780803Z","shell.execute_reply":"2021-07-03T16:49:33.861964Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"In the JSON unpacking code provided by competition organizers, we see them calculating an aggregate pitching statistic, Tom Tango's pitchingGameScore, which gives us an impression of pitcher's performance. Here is how it was calculated - \nPitchingGameScore = 40 + 2 * outs + 1 * strikeOutsPitching - 2 * baseOnBallsPitching - 2 * player_game_stats - 3 * runsPitching - 6 * homeRunsPitching\n\nAs we can see above, Engagement scores are high for both poor & great pitching performances. However there is a cluster of scores in the 60-85 range where targetAvg values are lower. Since this doesn't show a very clear pattern in targetAvg, maybe we need to individually look at pitcher statistics. ","metadata":{}},{"cell_type":"code","source":"run_stats=player_engagement_with_info.groupby(['runsScored','homeRuns']).agg({'targetAvg':'mean','target1':'count'}).reset_index()\nrun_stats['homeRuns']=run_stats['homeRuns'].apply(str)\nrun_stats.columns=['runsScored','homeRuns','targetAvg','Innings']\n\nteam_run_stats=player_engagement_with_info.groupby(['runsScoredTeam']).agg({'targetAvg':'mean','target1':'count'}).reset_index()\nteam_run_stats.columns=['runsScoredTeam','targetAvg','Innings']\n#team_run_stats\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:33.864176Z","iopub.execute_input":"2021-07-03T16:49:33.864573Z","iopub.status.idle":"2021-07-03T16:49:33.983226Z","shell.execute_reply.started":"2021-07-03T16:49:33.864537Z","shell.execute_reply":"2021-07-03T16:49:33.982292Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"fig = px.bar(run_stats, x=\"runsScored\", y=\"targetAvg\",\n color='homeRuns', barmode='group',\n height=400)\nfig.update_layout(title='Variation of targetAvg with Player runsScored & homeRuns scored in Match')\nfig.show()\n\nrbi_stats=player_engagement_with_info.groupby(['rbi']).agg({'targetAvg':'mean'}).reset_index()\n\nfig=px.line(rbi_stats,x='rbi',y='targetAvg',title='Variation in targetAvg values with RunsBattedIn by Player')\nfig.show()\n\nfig1 = make_subplots(specs=[[{\"secondary_y\": True}]])\n\n# Add traces\nfig1.add_trace(\n go.Scatter(x=team_run_stats['runsScoredTeam'], y=team_run_stats['targetAvg'], name=\"targetAvg\"),\n secondary_y=True,\n)\n\nfig1.add_trace(\n go.Scatter(x=team_run_stats['runsScoredTeam'], y=team_run_stats['Innings'], name=\"Innings\"),\n secondary_y=False,\n)\nfig1.update_layout(title='Variation of Runs Scored by a Team vs targetAvg')\nfig1.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:33.984574Z","iopub.execute_input":"2021-07-03T16:49:33.984996Z","iopub.status.idle":"2021-07-03T16:49:34.147838Z","shell.execute_reply.started":"2021-07-03T16:49:33.984950Z","shell.execute_reply":"2021-07-03T16:49:34.146912Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Let's now take a look at the impact of batting stats on targetAvg values - \n* **General rule seems to be that players who score higher runs in the match tend to have higher engagement**. Baseball is a low scoring game and scoring a run is a big event in the game. Therefore more runs generally means more engagment.\n* **Home Runs are also a rare event in the sport of Baseball. Greater the number of Home Runs scored in the game, higher the engagement.**\n* Another statistic for batter performance is RBI - Runs Batted In. It shows that the number of runs scored by a team where a player was involved in. This also shows that higher the RBI number, greater the engagement for a player\n* Also the **team as a whole tends to have higher engagement levels when the runsScored are higher**.\n\nSince this is essentially a time series dataset, we should also look at autocorrelations for target variables - autocorrelation measures correlation of a time series value at any point with its previous values. For every player, we will calculate autocorrelation at various lags and look at the distribution of autocorrelation for different lag values. ","metadata":{}},{"cell_type":"code","source":"# out_stats=player_engagement_with_info.groupby(['strikeOuts']).agg({'targetAvg':'mean','target1':'count'}).reset_index()\n# out_stats.columns=['strikeOuts','targetAvg','Num_Days']\n# #px.line(out_stats,x='strikeOuts',y='targetAvg')\n\n# fig = make_subplots(specs=[[{\"secondary_y\": True}]])\n\n# # Add traces\n# fig.add_trace(\n# go.Scatter(x=out_stats['strikeOuts'], y=out_stats['targetAvg'], name=\"targetAvg\"),\n# secondary_y=True,\n# )\n\n# fig.add_trace(\n# go.Scatter(x=out_stats['strikeOuts'], y=out_stats['Num_Days'], name=\"Num_Days\"),\n# secondary_y=False,\n# )\n# fig.update_layout(xaxis_title='Count of Strike Outs',title='StrikeOuts in a Game vs Target Score')\n# fig.show()\n\n# pitch_run_stats=player_engagement_with_info.groupby(['runsPitching']).agg({'targetAvg':'mean','target1':'count'}).reset_index()\n# pitch_run_stats.columns=['runsPitching','targetAvg','Num_Days']\n\n# fig = make_subplots(specs=[[{\"secondary_y\": True}]])\n\n# # Add traces\n# fig.add_trace(\n# go.Scatter(x=pitch_run_stats['runsPitching'], y=pitch_run_stats['targetAvg'], name=\"targetAvg\"),\n# secondary_y=True,\n# )\n\n# fig.add_trace(\n# go.Scatter(x=pitch_run_stats['runsPitching'], y=pitch_run_stats['Num_Days'], name=\"Num_Days\"),\n# secondary_y=False,\n# )\n# fig.update_layout(xaxis_title='Count of Runs Allowed',title='Runs Allowed in a Game vs targetAvg')\n# fig.show()\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:34.149202Z","iopub.execute_input":"2021-07-03T16:49:34.149546Z","iopub.status.idle":"2021-07-03T16:49:34.153819Z","shell.execute_reply.started":"2021-07-03T16:49:34.149509Z","shell.execute_reply":"2021-07-03T16:49:34.152938Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"### group by year?\nplayer_avg = player_engagement_with_info.groupby([\"playerId\"])[[\"target1\",\"target2\",\"target3\",\"target4\"]].mean().reset_index()\nplayer_median = player_engagement_with_info.groupby([\"playerId\"])[[\"target1\",\"target2\",\"target3\",\"target4\"]].median().reset_index()\nplayer_mean=pd.concat([player_avg, player_median], axis=1).groupby(axis=1, level=0).mean()\nplayer_mean[\"target1\"] = .85 * player_mean[\"target1\"]\nplayer_mean[\"target2\"] = .85 * player_mean[\"target2\"]\nplayer_mean[\"target3\"] = .85 * player_mean[\"target3\"]\nplayer_mean[\"target4\"] = .85 * player_mean[\"target4\"]\ngc.collect()\nprint(player_mean.shape)\nplayer_mean","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:34.155230Z","iopub.execute_input":"2021-07-03T16:49:34.155764Z","iopub.status.idle":"2021-07-03T16:49:34.641930Z","shell.execute_reply.started":"2021-07-03T16:49:34.155727Z","shell.execute_reply":"2021-07-03T16:49:34.640979Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"#player_engagement_with_info.columns","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:49:34.643211Z","iopub.execute_input":"2021-07-03T16:49:34.643554Z","iopub.status.idle":"2021-07-03T16:49:34.647540Z","shell.execute_reply.started":"2021-07-03T16:49:34.643518Z","shell.execute_reply":"2021-07-03T16:49:34.646548Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"data=player_engagement_with_info[['dailyDataDate','playerId','target1','target2','target3','target4','targetAvg','quarter','gameday']]","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:34.648977Z","iopub.execute_input":"2021-07-03T16:49:34.649510Z","iopub.status.idle":"2021-07-03T16:49:34.706150Z","shell.execute_reply.started":"2021-07-03T16:49:34.649471Z","shell.execute_reply":"2021-07-03T16:49:34.705168Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"autocorrel_list=list()\nfor i in range(31):\n ser=data.groupby('playerId')['targetAvg'].apply(lambda x: x.autocorr(lag=i))\n df=ser.to_frame().reset_index()\n df['lag']=i\n autocorrel_list.append(df)\nauto_frame=pd.concat(autocorrel_list).reset_index(drop=True)\n\n#autocorrel_list","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:49:34.707472Z","iopub.execute_input":"2021-07-03T16:49:34.707837Z","iopub.status.idle":"2021-07-03T16:50:03.621278Z","shell.execute_reply.started":"2021-07-03T16:49:34.707801Z","shell.execute_reply":"2021-07-03T16:50:03.620465Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"lst=list()\n\nfor i in range(1,31):\n lst.append(str('lag_'+str(i)))\ntup=tuple(lst)\n\nfig = make_subplots(\n rows=5, cols=6,shared_yaxes=True,\n subplot_titles=tup)\nk=1\nj=1\n\nfor i in range(1,31):\n lag_frame=auto_frame.loc[auto_frame['lag']==i]\n # print(k,j)\n fig.add_trace(\n go.Histogram(x=lag_frame['targetAvg'],name=i),\n row=k, col=j\n )\n# k=k%8\n j=j%6\n j=j+1\n \n# k=k+1\n if(i%6==0):\n k=k+1\n # j=j+1\n\n \nfig.update_layout(height=1000,title_text=\"Autocorrelation Plots for player targetAvg for various lags\",showlegend=False)\nfig.show()","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:03.622431Z","iopub.execute_input":"2021-07-03T16:50:03.622765Z","iopub.status.idle":"2021-07-03T16:50:04.157623Z","shell.execute_reply.started":"2021-07-03T16:50:03.622732Z","shell.execute_reply":"2021-07-03T16:50:04.156339Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"lag_gp=auto_frame.groupby('lag').agg({'targetAvg':['mean','median']}).reset_index()\nlag_gp.columns=['lag','mean','median']\nfig=go.Figure()\nfig.add_trace(go.Scatter(x=lag_gp['lag'],y=lag_gp['mean'],mode='lines',name='mean'))\nfig.add_trace(go.Scatter(x=lag_gp['lag'],y=lag_gp['median'],mode='lines',name='median'))\nfig.update_layout(title='Mean & Median of player Autocorrelation distributions across various lag periods',xaxis_title='lag')\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:04.159107Z","iopub.execute_input":"2021-07-03T16:50:04.159457Z","iopub.status.idle":"2021-07-03T16:50:04.189943Z","shell.execute_reply.started":"2021-07-03T16:50:04.159420Z","shell.execute_reply":"2021-07-03T16:50:04.188936Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"* **The autocorrelation distributions seem to become more left skewed with increase in lag values**\n* Autocorrelation lag means are reasonably high till lag 5 but then reduces significantly afterwards. This information will be important for us at the Feature Engineering stage since we would be looking to incorporate lag values as features in the model.\n\n## Feature Engineering\nSome of the exploratory analysis we did helped us gain a better understanding of the data. Now we would be looking to convert some of that information into features and utilize that to fit a model on the data to generate predictions. \n\nThese are the features we would go with for starters - \n\n### Player Features \n* Number of Runs Scored\n* Home Runs\n* Birth Country\n* Starting Position\n* Roster Status\n\n### Target Features \n* Mean of Target Variables\n* Min of Target Variables\n* Max of Target Variables\n* Std. Dev of Target Variables\n\nThese features should help us generate a good baseline model. We will now prepare the datasets with these features generated. \n","metadata":{}},{"cell_type":"code","source":"player_engagement_with_info.columns","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:04.191320Z","iopub.execute_input":"2021-07-03T16:50:04.191682Z","iopub.status.idle":"2021-07-03T16:50:04.199249Z","shell.execute_reply.started":"2021-07-03T16:50:04.191638Z","shell.execute_reply":"2021-07-03T16:50:04.198090Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"data=player_engagement_with_info[['dailyDataDate','playerId','target1','target2','target3','target4','quarter','year','month','runsScored', 'homeRuns','gamesStartedPitching','birthCountry','primaryPositionName','rosterTeamName','rosterStatus']]","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:04.201319Z","iopub.execute_input":"2021-07-03T16:50:04.201729Z","iopub.status.idle":"2021-07-03T16:50:04.461091Z","shell.execute_reply.started":"2021-07-03T16:50:04.201686Z","shell.execute_reply":"2021-07-03T16:50:04.460010Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"data_avg=player_engagement_with_info.loc[player_engagement_with_info['engagementMetricsDate']<'2021-04-01']\ndata_avg\n\nplayer_target_stats=data_avg.groupby('playerId').agg({'target1':['min','max','mean','std'],'target2':['min','max','mean','std'],'target3':['min','max','mean','std'],'target4':['min','max','mean','std']}).reset_index()\nplayer_target_stats.columns=['playerId','target1_min','target1_max','target1_mean','target1_std','target2_min','target2_max','target2_mean','target2_std','target3_min','target3_max','target3_mean','target3_std','target4_min','target4_max','target4_mean','target4_std']\nplayer_target_stats\n\nplayer_score_stats=data_avg.groupby('playerId').agg({'runsScored':'sum','homeRuns':'sum'}).reset_index()\nplayer_score_stats","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:04.463499Z","iopub.execute_input":"2021-07-03T16:50:04.463810Z","iopub.status.idle":"2021-07-03T16:50:06.452191Z","shell.execute_reply.started":"2021-07-03T16:50:04.463759Z","shell.execute_reply":"2021-07-03T16:50:06.451393Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import gc\ndel data_avg\ngc.collect()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:06.453487Z","iopub.execute_input":"2021-07-03T16:50:06.453871Z","iopub.status.idle":"2021-07-03T16:50:06.989487Z","shell.execute_reply.started":"2021-07-03T16:50:06.453831Z","shell.execute_reply":"2021-07-03T16:50:06.988502Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player=player_engagement_with_info[['engagementMetricsDate','playerId','birthCountry','primaryPositionName','rosterTeamId','rosterStatus','target1','target2','target3','target4']]\n# label encoding\ncountry2num = {c: i for i, c in enumerate(player['birthCountry'].unique())}\nposition2num = {c: i for i, c in enumerate(player['primaryPositionName'].unique())}\nteamid2num = {c: i for i, c in enumerate(player['rosterTeamId'].unique())}\nstatus2num = {c: i for i, c in enumerate(player['rosterStatus'].unique())}\nplayer['label_country_id'] = player['birthCountry'].map(country2num).fillna(-1)\nplayer['label_position_id'] = player['primaryPositionName'].map(position2num).fillna(-1)\nplayer['label_team_id'] = player['rosterTeamId'].map(teamid2num).fillna(-1)\nplayer['label_status_id'] = player['rosterStatus'].map(status2num).fillna(-1)\n\nplayer_info=player[['playerId','label_country_id','label_position_id']]\nplayer_info\n#player\n\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:06.991105Z","iopub.execute_input":"2021-07-03T16:50:06.991454Z","iopub.status.idle":"2021-07-03T16:50:09.497742Z","shell.execute_reply.started":"2021-07-03T16:50:06.991414Z","shell.execute_reply":"2021-07-03T16:50:09.496819Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_target=pd.merge(left=player,right=player_target_stats,on='playerId',how='inner')\ndel player\ngc.collect()\nplayer_score_stats1=pd.merge(left=player_target,right=player_score_stats,on='playerId',how='inner')\nplayer_score_stats1","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:09.499070Z","iopub.execute_input":"2021-07-03T16:50:09.499420Z","iopub.status.idle":"2021-07-03T16:50:16.452258Z","shell.execute_reply.started":"2021-07-03T16:50:09.499383Z","shell.execute_reply":"2021-07-03T16:50:16.451444Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"del data\ndel player_engagement_with_info\ngc.collect()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:16.453502Z","iopub.execute_input":"2021-07-03T16:50:16.453852Z","iopub.status.idle":"2021-07-03T16:50:17.088393Z","shell.execute_reply.started":"2021-07-03T16:50:16.453815Z","shell.execute_reply":"2021-07-03T16:50:17.087386Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_score_stats1.columns","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:17.089775Z","iopub.execute_input":"2021-07-03T16:50:17.090141Z","iopub.status.idle":"2021-07-03T16:50:17.099840Z","shell.execute_reply.started":"2021-07-03T16:50:17.090101Z","shell.execute_reply":"2021-07-03T16:50:17.098809Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"feature_cols=['engagementMetricsDate', 'playerId', 'target1_min', 'target1_max',\n 'label_country_id','label_position_id', 'label_team_id', 'label_status_id',\n 'target1_mean', 'target1_std', 'target2_min', 'target2_max',\n 'target2_mean', 'target2_std', 'target3_min', 'target3_max',\n 'target3_mean', 'target3_std', 'target4_min', 'target4_max',\n 'target4_mean', 'target4_std', 'runsScored', 'homeRuns']\ntarget_cols=['target1','target2', 'target3', 'target4']\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:17.101350Z","iopub.execute_input":"2021-07-03T16:50:17.101899Z","iopub.status.idle":"2021-07-03T16:50:17.110294Z","shell.execute_reply.started":"2021-07-03T16:50:17.101861Z","shell.execute_reply":"2021-07-03T16:50:17.109505Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"index=player_score_stats1['engagementMetricsDate']<'2021-04-01'\nX_train=player_score_stats1.loc[index,feature_cols]\nY_train=player_score_stats1.loc[index,target_cols]\n\nX_test=player_score_stats1.loc[~index,feature_cols]\nY_test=player_score_stats1.loc[~index,target_cols]\n\ndel X_train['engagementMetricsDate']\ndel X_test['engagementMetricsDate']\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:17.111599Z","iopub.execute_input":"2021-07-03T16:50:17.111966Z","iopub.status.idle":"2021-07-03T16:50:20.272217Z","shell.execute_reply.started":"2021-07-03T16:50:17.111930Z","shell.execute_reply":"2021-07-03T16:50:20.271345Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# from skmultilearn.model_selection import iterative_train_test_split\n# from sklearn.multioutput import MultiOutputClassifier\n# from sklearn.ensemble import RandomForestRegressor\n\n# model = RandomForestRegressor(n_estimators=200,max_depth=10, random_state=0,min_samples_split=10)\n# model.fit(X_train, Y_train)\n\n# # #Generating predictions from Random Fores Models\n# # pred_rf=model.predict(X_test)\n# # pred_rf_proba=model.predict_proba(X_test)\n\n# # feat_importances = pd.Series(model.feature_importances_, index=feature_list)\n# # feat_importances=feat_importances.sort_values()\n# # feat_importances.plot(kind='barh',figsize=(16,16))#Plotting feature importance\n\n# print('Model Accuracy')\n# #print(model.score(X_test,Y_test))\n\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:20.276402Z","iopub.execute_input":"2021-07-03T16:50:20.278489Z","iopub.status.idle":"2021-07-03T16:50:20.284109Z","shell.execute_reply.started":"2021-07-03T16:50:20.278448Z","shell.execute_reply":"2021-07-03T16:50:20.283379Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Model Development & Hyperparameter Tuning\n\n* We will use LightGBM as a model for prediction. \n* We will be training four different models to predict each of the target variables\n* Since this is a time series competition, we need to be very careful about leakage of features. Therefore we will be using data till 31 March 2021 as training data and will use the April 2021 data for validation\n* We generated optimal parameters through Hyperparameter Tuning with Optuna\n* This model is then used to generate predictions on the final data\n","metadata":{}},{"cell_type":"code","source":"import lightgbm as lgbm\nfrom sklearn.metrics import mean_absolute_error\n#https://www.kaggle.com/columbia2131/mlb-lightgbm-starter-dataset-code-en-ja\n \ndef fit_lgbm(x_train, y_train, x_valid, y_valid, params: dict=None, verbose=100):\n oof_pred = np.zeros(len(y_valid), dtype=np.float32)\n model = lgbm.LGBMRegressor(**params)\n model.fit(x_train, y_train, \n eval_set=[(x_valid, y_valid)], \n early_stopping_rounds=verbose, \n verbose=verbose)\n oof_pred = model.predict(x_valid)\n score = mean_absolute_error(oof_pred, y_valid)\n print('mae:', score)\n return oof_pred, model, score\n\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:20.288174Z","iopub.execute_input":"2021-07-03T16:50:20.290563Z","iopub.status.idle":"2021-07-03T16:50:20.583165Z","shell.execute_reply.started":"2021-07-03T16:50:20.290502Z","shell.execute_reply":"2021-07-03T16:50:20.582347Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"##Hyperparameter Optimization using Optuna\n\n# import optuna\n\n# # 1. Define an objective function to be maximized.\n# def objective1(trial):\n# ...\n\n# # 2. Suggest values of the hyperparameters using a trial object.\n# param = {\n# 'objective': 'regression',\n# 'metric': 'mae',\n# 'verbosity': -1,\n# 'boosting_type': 'gbdt',\n# 'lambda_l1': trial.suggest_loguniform('lambda_l1', 1e-8, 10.0),\n# 'lambda_l2': trial.suggest_loguniform('lambda_l2', 1e-8, 10.0),\n# 'num_leaves': trial.suggest_int('num_leaves', 2, 256),\n# 'feature_fraction': trial.suggest_uniform('feature_fraction', 0.4, 1.0),\n# 'bagging_fraction': trial.suggest_uniform('bagging_fraction', 0.4, 1.0),\n# 'bagging_freq': trial.suggest_int('bagging_freq', 1, 7),\n# 'min_child_samples': trial.suggest_int('min_child_samples', 10, 100),\n# 'n_estimators': 100,\n# 'feature_pre_filter':False\n# }\n\n# gbm = lgbm.train(param, train_data1)\n# preds = gbm.predict(X_test)\n# score = mean_absolute_error(preds, Y_test['target1'])\n\n# ...\n# return score\n# def objective2(trial):\n# ...\n\n# # 2. Suggest values of the hyperparameters using a trial object.\n# param = {\n# 'objective': 'regression',\n# 'metric': 'mae',\n# 'verbosity': -1,\n# 'boosting_type': 'gbdt',\n# 'lambda_l1': trial.suggest_loguniform('lambda_l1', 1e-8, 10.0),\n# 'lambda_l2': trial.suggest_loguniform('lambda_l2', 1e-8, 10.0),\n# 'num_leaves': trial.suggest_int('num_leaves', 2, 256),\n# 'feature_fraction': trial.suggest_uniform('feature_fraction', 0.4, 1.0),\n# 'bagging_fraction': trial.suggest_uniform('bagging_fraction', 0.4, 1.0),\n# 'bagging_freq': trial.suggest_int('bagging_freq', 1, 7),\n# 'min_child_samples': trial.suggest_int('min_child_samples', 10, 100),\n# 'n_estimators': 100,\n# 'feature_pre_filter':False\n# }\n\n# gbm = lgbm.train(param, train_data2)\n# preds = gbm.predict(X_test)\n# score = mean_absolute_error(preds, Y_test['target2'])\n\n# ...\n# return score\n# def objective3(trial):\n# ...\n\n# # 2. Suggest values of the hyperparameters using a trial object.\n# param = {\n# 'objective': 'regression',\n# 'metric': 'mae',\n# 'verbosity': -1,\n# 'boosting_type': 'gbdt',\n# 'lambda_l1': trial.suggest_loguniform('lambda_l1', 1e-8, 10.0),\n# 'lambda_l2': trial.suggest_loguniform('lambda_l2', 1e-8, 10.0),\n# 'num_leaves': trial.suggest_int('num_leaves', 2, 256),\n# 'feature_fraction': trial.suggest_uniform('feature_fraction', 0.4, 1.0),\n# 'bagging_fraction': trial.suggest_uniform('bagging_fraction', 0.4, 1.0),\n# 'bagging_freq': trial.suggest_int('bagging_freq', 1, 7),\n# 'min_child_samples': trial.suggest_int('min_child_samples', 10, 100),\n# 'n_estimators': 100,\n# 'feature_pre_filter':False\n# }\n\n# gbm = lgbm.train(param, train_data3)\n# preds = gbm.predict(X_test)\n# score = mean_absolute_error(preds, Y_test['target3'])\n\n# ...\n# return score\n# def objective4(trial):\n# ...\n\n# # 2. Suggest values of the hyperparameters using a trial object.\n# param = {\n# 'objective': 'regression',\n# 'metric': 'mae',\n# 'verbosity': -1,\n# 'boosting_type': 'gbdt',\n# 'lambda_l1': trial.suggest_loguniform('lambda_l1', 1e-8, 10.0),\n# 'lambda_l2': trial.suggest_loguniform('lambda_l2', 1e-8, 10.0),\n# 'num_leaves': trial.suggest_int('num_leaves', 2, 256),\n# 'feature_fraction': trial.suggest_uniform('feature_fraction', 0.4, 1.0),\n# 'bagging_fraction': trial.suggest_uniform('bagging_fraction', 0.4, 1.0),\n# 'bagging_freq': trial.suggest_int('bagging_freq', 1, 7),\n# 'min_child_samples': trial.suggest_int('min_child_samples', 10, 100),\n# 'n_estimators': 100,\n# 'feature_pre_filter':False\n# }\n\n# gbm = lgbm.train(param, train_data4)\n# preds = gbm.predict(X_test)\n# score = mean_absolute_error(preds, Y_test['target4'])\n\n# ...\n# return score\n\n\n# train_data1 = lgbm.Dataset(X_train, label=Y_train['target1'])\n# train_data2 = lgbm.Dataset(X_train, label=Y_train['target2'])\n# train_data3 = lgbm.Dataset(X_train, label=Y_train['target3'])\n# train_data4 = lgbm.Dataset(X_train, label=Y_train['target4'])\n\n\n# # 3. Create a study object and optimize the objective function.\n# study1 = optuna.create_study(direction='minimize')\n# study1.optimize(objective1, n_trials=5,gc_after_trial=True,n_jobs=-1)\n\n# study2 = optuna.create_study(direction='minimize')\n# study2.optimize(objective2, n_trials=5,gc_after_trial=True,n_jobs=-1)\n\n# study3 = optuna.create_study(direction='minimize')\n# study3.optimize(objective3, n_trials=5,gc_after_trial=True,n_jobs=-1)\n\n# study4 = optuna.create_study(direction='minimize')\n# study4.optimize(objective4, n_trials=5,gc_after_trial=True,n_jobs=-1)\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:20.586252Z","iopub.execute_input":"2021-07-03T16:50:20.586505Z","iopub.status.idle":"2021-07-03T16:50:20.591590Z","shell.execute_reply.started":"2021-07-03T16:50:20.586479Z","shell.execute_reply":"2021-07-03T16:50:20.590749Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# params1=study1.best_params\n# optuna.visualization.plot_param_importances(study1)\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:20.592661Z","iopub.execute_input":"2021-07-03T16:50:20.593392Z","iopub.status.idle":"2021-07-03T16:50:20.607071Z","shell.execute_reply.started":"2021-07-03T16:50:20.593351Z","shell.execute_reply":"2021-07-03T16:50:20.606270Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# fig = optuna.visualization.plot_optimization_history(study1)\n# fig.show()","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:20.608377Z","iopub.execute_input":"2021-07-03T16:50:20.608730Z","iopub.status.idle":"2021-07-03T16:50:20.617001Z","shell.execute_reply.started":"2021-07-03T16:50:20.608692Z","shell.execute_reply":"2021-07-03T16:50:20.616228Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# params1=study1.best_params\n# params2=study2.best_params\n# params3=study3.best_params\n# params4=study4.best_params\n\n# with open('params1.pickle', 'wb') as handle:\n# pickle.dump(params1, handle, protocol=pickle.HIGHEST_PROTOCOL)\n# with open('params2.pickle', 'wb') as handle:\n# pickle.dump(params2, handle, protocol=pickle.HIGHEST_PROTOCOL)\n# with open('params3.pickle', 'wb') as handle:\n# pickle.dump(params3, handle, protocol=pickle.HIGHEST_PROTOCOL)\n# with open('params4.pickle', 'wb') as handle:\n# pickle.dump(params4, handle, protocol=pickle.HIGHEST_PROTOCOL)\n \n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:20.618310Z","iopub.execute_input":"2021-07-03T16:50:20.618672Z","iopub.status.idle":"2021-07-03T16:50:20.625560Z","shell.execute_reply.started":"2021-07-03T16:50:20.618636Z","shell.execute_reply":"2021-07-03T16:50:20.624721Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# with open('params1.pickle', 'rb') as handle:\n# params1 = pickle.load(handle)\n# with open('params2.pickle', 'rb') as handle:\n# params2 = pickle.load(handle)\n# with open('params3.pickle', 'rb') as handle:\n# params3 = pickle.load(handle)\n# with open('params4.pickle', 'rb') as handle:\n# params4 = pickle.load(handle)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:50:20.628160Z","iopub.execute_input":"2021-07-03T16:50:20.628452Z","iopub.status.idle":"2021-07-03T16:50:20.638493Z","shell.execute_reply.started":"2021-07-03T16:50:20.628426Z","shell.execute_reply":"2021-07-03T16:50:20.637622Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"params1={'objective':'mae','lambda_l1': 2.4720578317437477e-05,\n 'lambda_l2': 1.3527755261208504e-06,\n 'num_leaves': 40,\n 'feature_fraction': 0.7554047245795381,\n 'bagging_fraction': 0.5080066015078072,\n 'bagging_freq': 3,\n 'min_child_samples': 100}\nparams2={'objective':'mae','lambda_l1': 0.0014725905491640504,\n 'lambda_l2': 5.713092762240107,\n 'num_leaves': 47,\n 'feature_fraction': 0.462021949863225,\n 'bagging_fraction': 0.4500482872517192,\n 'bagging_freq': 4,\n 'min_child_samples': 24}\nparams3={'objective':'mae','lambda_l1': 1.646629475621938e-07,\n 'lambda_l2': 0.00020089914770634004,\n 'num_leaves': 42,\n 'feature_fraction': 0.6792583947012405,\n 'bagging_fraction': 0.4772814797729401,\n 'bagging_freq': 4,\n 'min_child_samples': 99}\nparams4={'objective':'mae','lambda_l1': 0.007010740786027014,\n 'lambda_l2': 8.864818411173501e-08,\n 'num_leaves': 46,\n 'feature_fraction': 0.6146671105020214,\n 'bagging_fraction': 0.7314001423885812,\n 'bagging_freq': 2,\n 'min_child_samples': 75}\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:20.639688Z","iopub.execute_input":"2021-07-03T16:50:20.640055Z","iopub.status.idle":"2021-07-03T16:50:20.648543Z","shell.execute_reply.started":"2021-07-03T16:50:20.640020Z","shell.execute_reply":"2021-07-03T16:50:20.647549Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"\noof1, model1, score1 = fit_lgbm(\n X_train, Y_train['target1'],\n X_test, Y_test['target1'],\n params1\n)\n\noof2, model2, score2 = fit_lgbm(\n X_train, Y_train['target2'],\n X_test, Y_test['target2'],\n params2\n)\noof3, model3, score3 = fit_lgbm(\n X_train, Y_train['target3'],\n X_test, Y_test['target3'],\n params3\n)\noof4, model4, score4 = fit_lgbm(\n X_train, Y_train['target4'],\n X_test, Y_test['target4'],\n params4\n)\n\nscore = (score1+score2+score3+score4) / 4\nprint(f'score: {score}')\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:50:20.649772Z","iopub.execute_input":"2021-07-03T16:50:20.650128Z","iopub.status.idle":"2021-07-03T16:52:06.822497Z","shell.execute_reply.started":"2021-07-03T16:50:20.650093Z","shell.execute_reply":"2021-07-03T16:52:06.821812Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"lgbm.plot_importance(model1)","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:06.825753Z","iopub.execute_input":"2021-07-03T16:52:06.827391Z","iopub.status.idle":"2021-07-03T16:52:07.359915Z","shell.execute_reply.started":"2021-07-03T16:52:06.827323Z","shell.execute_reply":"2021-07-03T16:52:07.359108Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Final Submission\n\nWe will use the competition API to get access to the hidden test set and make predictions. ","metadata":{}},{"cell_type":"code","source":"import mlb\nenv = mlb.make_env() # initialize the environment\niter_test = env.iter_test() # iterator which loops over each date in test set\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:07.361194Z","iopub.execute_input":"2021-07-03T16:52:07.361531Z","iopub.status.idle":"2021-07-03T16:52:07.394658Z","shell.execute_reply.started":"2021-07-03T16:52:07.361494Z","shell.execute_reply":"2021-07-03T16:52:07.393866Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"rosters_cols = ['playerId','gameDate','teamId','statusCode','status']\nplayer_info=player_info.reset_index(drop=True)\nplayer_info=player_info.drop_duplicates(subset=['playerId'], keep='first')\n","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:07.397727Z","iopub.execute_input":"2021-07-03T16:52:07.398020Z","iopub.status.idle":"2021-07-03T16:52:07.451223Z","shell.execute_reply.started":"2021-07-03T16:52:07.397994Z","shell.execute_reply":"2021-07-03T16:52:07.450388Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"for (test_df, sample_prediction_df) in iter_test:\n \n# test_df=test_df.reset_index(drop=True)\n# if test_df['rosters'].iloc[0] == test_df['rosters'].iloc[0]:\n# test_rosters = pd.DataFrame(eval(test_df['rosters'].iloc[0]))\n# else:\n# test_rosters = pd.DataFrame({'playerId': sample_prediction_df['playerId']})\n \n# for col in rosters_cols:\n# if col == 'playerId': continue\n# test_rosters[col] = np.nan\n# test_rosters['label_team_id'] = test_rosters['teamId'].map(teamid2num).fillna(-1)\n# test_rosters['label_status_id'] = test_rosters['status'].map(status2num).fillna(-1)\n \n# player_rosters=test_rosters[['playerId','label_team_id','label_status_id']]\n# player_rosters=player_rosters.drop_duplicates(subset=['playerId'],keep='first')\n \n sample_prediction_df = sample_prediction_df.reset_index(drop=True)\n \n sample_prediction_df['playerId'] = sample_prediction_df['date_playerId']\\\n .map(lambda x: int(x.split('_')[1])) \n \n sample_prediction_df_info=pd.merge(left=sample_prediction_df,right=player_info,on='playerId',how='left')\n # sample_prediction_df_rosters=pd.merge(left=sample_prediction_df_info,right=player_rosters,on='playerId',how='left')\n \n sample_prediction_df_info['label_team_id']=0\n sample_prediction_df_info['label_status_id']=0\n \n \n sample_prediction_df_tgt=pd.merge(left=sample_prediction_df_info,right=player_target_stats,on='playerId',how='left')\n sample_prediction_df_tgt_stats=pd.merge(left=sample_prediction_df_tgt,right=player_score_stats,on='playerId',how='left')\n sample_prediction_df_tgt_stats['engagementMetricsDate']='2020-04-01'\n test_X = sample_prediction_df_tgt_stats[feature_cols]\n del test_X['engagementMetricsDate']\n test_X=test_X.fillna(-1)\n\n \n # predict\n pred1 = model1.predict(test_X)\n pred2 = model2.predict(test_X)\n pred3 = model3.predict(test_X)\n pred4 = model4.predict(test_X)\n \n # merge submission\n sample_prediction_df['target1'] = np.clip(pred1, 0, 100)\n sample_prediction_df['target2'] = np.clip(pred2, 0, 100)\n sample_prediction_df['target3'] = np.clip(pred3, 0, 100)\n sample_prediction_df['target4'] = np.clip(pred4, 0, 100)\n sample_prediction_df = sample_prediction_df.fillna(0.)\n del sample_prediction_df['playerId']\n # del sample_prediction_df['date']\n \n env.predict(sample_prediction_df)\n \n #env.predict(sample_prediction_df)","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:07.452596Z","iopub.execute_input":"2021-07-03T16:52:07.452978Z","iopub.status.idle":"2021-07-03T16:52:09.129900Z","shell.execute_reply.started":"2021-07-03T16:52:07.452942Z","shell.execute_reply":"2021-07-03T16:52:09.129036Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"X_test.isna().sum()","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:09.135485Z","iopub.execute_input":"2021-07-03T16:52:09.135755Z","iopub.status.idle":"2021-07-03T16:52:09.146518Z","shell.execute_reply.started":"2021-07-03T16:52:09.135729Z","shell.execute_reply":"2021-07-03T16:52:09.145554Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# if test_df['rosters'].iloc[0] == test_df['rosters'].iloc[0]:\n# test_rosters = pd.DataFrame(eval(test_df['rosters'].iloc[0]))\n# else:\n# test_rosters = pd.DataFrame({'playerId': sample_prediction_df['playerId']})\n# for col in rosters.columns:\n# if col == 'playerId': continue\n# test_rosters[col] = np.nan\n# test_rosters\n# player_rosters=test_rosters[['playerId','teamId','status']]\n# test_rosters","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:09.148166Z","iopub.execute_input":"2021-07-03T16:52:09.148714Z","iopub.status.idle":"2021-07-03T16:52:09.152913Z","shell.execute_reply.started":"2021-07-03T16:52:09.148676Z","shell.execute_reply":"2021-07-03T16:52:09.151974Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"","metadata":{},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# test_df=test_df.reset_index(drop=True)\n# if test_df['rosters'].iloc[0] == test_df['rosters'].iloc[0]:\n# test_rosters = pd.DataFrame(eval(test_df['rosters'].iloc[0]))\n# else:\n# test_rosters = pd.DataFrame({'playerId': sample_prediction_df['playerId']})\n# for col in rosters_cols:\n# if col == 'playerId': continue\n# test_rosters[col] = np.nan\n \n# test_rosters['label_team_id'] = test_rosters['teamId'].map(teamid2num).fillna(-1)\n# test_rosters['label_status_id'] = test_rosters['status'].map(status2num).fillna(-1)\n \n# player_rosters=test_rosters[['playerId','label_team_id','label_status_id']]\n \n# sample_prediction_df = sample_prediction_df.reset_index(drop=True)\n \n# sample_prediction_df['playerId'] = sample_prediction_df['date_playerId']\\\n# .map(lambda x: int(x.split('_')[1])) \n# player_info=player_info.drop_duplicates(subset=['playerId'], keep='first')\n \n# sample_prediction_df_info=pd.merge(left=sample_prediction_df,right=player_info,on='playerId',how='left')\n# sample_prediction_df_rosters=pd.merge(left=sample_prediction_df_info,right=player_rosters,on='playerId',how='left')\n \n# sample_prediction_df_tgt=pd.merge(left=sample_prediction_df_rosters,right=player_target_stats,on='playerId',how='left')\n# sample_prediction_df_tgt_stats=pd.merge(left=sample_prediction_df_tgt,right=player_score_stats,on='playerId',how='left')\n# sample_prediction_df_tgt_stats['engagementMetricsDate']='2020-04-01'\n# test_X = sample_prediction_df_tgt_stats[feature_cols]\n# del test_X['engagementMetricsDate']\n# test_X=test_X.fillna(-1)\n\n \n# # predict\n# pred1 = model1.predict(test_X)\n# pred2 = model2.predict(test_X)\n# pred3 = model3.predict(test_X)\n# pred4 = model4.predict(test_X)\n \n# # merge submission\n# sample_prediction_df['target1'] = np.clip(pred1, 0, 100)\n# sample_prediction_df['target2'] = np.clip(pred2, 0, 100)\n# sample_prediction_df['target3'] = np.clip(pred3, 0, 100)\n# sample_prediction_df['target4'] = np.clip(pred4, 0, 100)\n# sample_prediction_df = sample_prediction_df.fillna(0.)\n# del sample_prediction_df['playerId']\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-03T16:52:09.154335Z","iopub.execute_input":"2021-07-03T16:52:09.154681Z","iopub.status.idle":"2021-07-03T16:52:09.161410Z","shell.execute_reply.started":"2021-07-03T16:52:09.154645Z","shell.execute_reply":"2021-07-03T16:52:09.160452Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"sample_prediction_df","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:09.162673Z","iopub.execute_input":"2021-07-03T16:52:09.163058Z","iopub.status.idle":"2021-07-03T16:52:09.184473Z","shell.execute_reply.started":"2021-07-03T16:52:09.163014Z","shell.execute_reply":"2021-07-03T16:52:09.183422Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"player_info","metadata":{"execution":{"iopub.status.busy":"2021-07-03T16:52:09.185812Z","iopub.execute_input":"2021-07-03T16:52:09.186185Z","iopub.status.idle":"2021-07-03T16:52:09.200429Z","shell.execute_reply.started":"2021-07-03T16:52:09.186148Z","shell.execute_reply":"2021-07-03T16:52:09.199570Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\nI love doing projects around Sports Analytics, if you want to check out some of my other work around sports analytics do check this out - https://arpitsolanki.github.io/blog/\n\n### Next Steps \n* Run further analysis to gain better understanding of data - impact of player origins, average age, fluctuation in forms etc. on engagement scores\n* Bring in additional datasets like FiveThirtyEight ELO ratings to understand how competitiveness of games impacts engagement scores\n* Convert results of analysis into meaningful features for prediction\n* Create a prediction model to predict engagment scores for test dataset\n\nTo be continued...\n\n","metadata":{}}]}