{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"\nAbout this notebook\n\n\n\nJigsaw Multilingual Toxic Comment Classification is the 3rd annual competition organized by the Jigsaw team. It follows Toxic Comment Classification Challenge, the original 2018 competition, and Jigsaw Unintended Bias in Toxicity Classification, which required the competitors to consider biased ML predictions in their new models. This year, the goal is to use english only training data to run toxicity predictions on many different languages, which can be done using multilingual models, and speed up using TPUs.\n\n\n\n**The focus of this notebook is to:**\n\n- Expirement with different model architectures for finetuning bert.\n- Add translated data to validation set.\n- Do k fold cross validation on the data.I didn't see any public kernel doing k-fold cross validation with the data.But I'm pretty sure that it's done by LB toppers.\n- How to improve CV vs LB corrrelation\n\n\n### If you like this work,Please leave an upvote ⬆️","metadata":{}},{"cell_type":"markdown","source":"## Loading Required Libraries","metadata":{}},{"cell_type":"code","source":"!pip install tensorflow_addons","metadata":{"execution":{"iopub.status.busy":"2021-06-27T02:46:47.975419Z","iopub.execute_input":"2021-06-27T02:46:47.97587Z","iopub.status.idle":"2021-06-27T02:46:56.81781Z","shell.execute_reply.started":"2021-06-27T02:46:47.975784Z","shell.execute_reply":"2021-06-27T02:46:56.816374Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"from tensorflow.keras.layers import Input, Dense, Embedding, SpatialDropout1D, Dropout, add, concatenate\nfrom tensorflow.keras.layers import Bidirectional, GlobalMaxPooling1D, GlobalAveragePooling1D,Average\nfrom tokenizers import Tokenizer, models, pre_tokenizers, decoders, processors\nfrom tensorflow.keras.callbacks import ModelCheckpoint\nfrom transformers import TFAutoModel, AutoTokenizer\nfrom sklearn.model_selection import StratifiedKFold\nfrom tensorflow.keras.layers import Dense, Input\nfrom tensorflow.keras.optimizers import Adam\nfrom kaggle_datasets import KaggleDatasets\nfrom tensorflow.keras.models import Model\nimport plotly.graph_objects as go\nfrom sklearn.utils import shuffle\nimport tensorflow_addons as tfa\nfrom tqdm.notebook import tqdm\nfrom textblob import TextBlob\nimport plotly.offline as py\nimport tensorflow as tf\nimport pandas as pd\nimport transformers\nimport numpy as np\nimport warnings\nimport os\n\n\nwarnings.filterwarnings(\"ignore\")\npy.init_notebook_mode(connected=True)\n","metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","_kg_hide-input":false,"execution":{"iopub.status.busy":"2021-06-27T02:46:56.82079Z","iopub.execute_input":"2021-06-27T02:46:56.821094Z","iopub.status.idle":"2021-06-27T02:47:07.173254Z","shell.execute_reply.started":"2021-06-27T02:46:56.821062Z","shell.execute_reply":"2021-06-27T02:47:07.171738Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Helper function\n","metadata":{}},{"cell_type":"code","source":"\ndef regular_encode(texts, tokenizer, maxlen=512):\n enc_di = tokenizer.batch_encode_plus(\n texts, \n return_attention_masks=False, \n return_token_type_ids=False,\n pad_to_max_length=True,\n max_length=maxlen\n )\n \n return np.array(enc_di['input_ids'])\n\n","metadata":{"execution":{"iopub.status.busy":"2021-06-27T02:47:07.182932Z","iopub.execute_input":"2021-06-27T02:47:07.183254Z","iopub.status.idle":"2021-06-27T02:47:07.189349Z","shell.execute_reply.started":"2021-06-27T02:47:07.183224Z","shell.execute_reply":"2021-06-27T02:47:07.188342Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Multi Sample dropout Network\n\n\n\nMulti-Sample Dropout introduced in the paper [Multi-Sample Dropout for Accelearted Training and Better Generalization](https://arxiv.org/abs/1905.09788) is a new way to expand the traditional Dropout by using multiple dropout masks for the same mini-batch.","metadata":{}},{"cell_type":"code","source":"def build_model(transformer, max_len=220):\n \n input_word_ids = Input(shape=(max_len,), dtype=tf.int32, name=\"input_word_ids\")\n seq_out = transformer(input_word_ids)[0]\n pool= GlobalAveragePooling1D()(seq_out)\n \n\n dense=[]\n FC = Dense(32,activation='relu')\n for p in np.linspace(0.2,0.5,3):\n x=Dropout(p)(pool)\n x=FC(x)\n x=Dense(1,activation='sigmoid')(x)\n dense.append(x)\n \n out = Average()(dense)\n \n model = Model(inputs=input_word_ids, outputs=out)\n optimizer=tfa.optimizers.RectifiedAdam(learning_rate=2e-5,min_lr=1e-6,total_steps=6000)\n model.compile(optimizer, loss=focal_loss(), metrics=[tf.keras.metrics.AUC()])\n \n return model\n","metadata":{"execution":{"iopub.status.busy":"2021-06-27T02:47:07.190658Z","iopub.execute_input":"2021-06-27T02:47:07.190931Z","iopub.status.idle":"2021-06-27T02:47:07.203357Z","shell.execute_reply.started":"2021-06-27T02:47:07.190905Z","shell.execute_reply":"2021-06-27T02:47:07.202067Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Using [CLS] token \n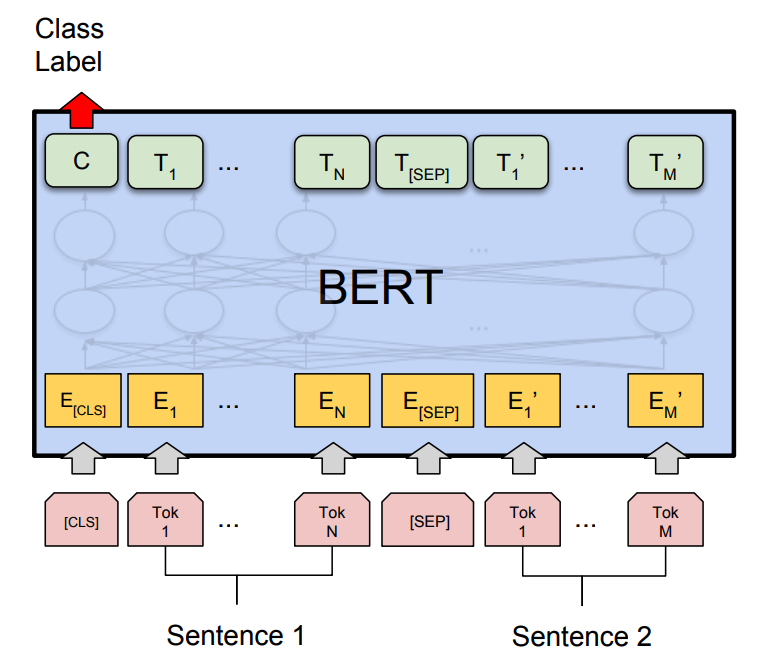\n\nFor sentence classification, we’re only only interested in BERT’s output for the [CLS] token,this is the easiest way to get ouput from bert for classification","metadata":{}},{"cell_type":"code","source":"def build_model(transformer, max_len=220):\n \n input_word_ids = Input(shape=(max_len,), dtype=tf.int32, name=\"input_word_ids\")\n seq_out = transformer(input_word_ids)[0]\n cls_out = seq_out[:,0,:]\n out=Dense(1,activation='sigmoid')(cls_out)\n \n model = Model(inputs=input_word_ids, outputs=out)\n optimizer=tfa.optimizers.RectifiedAdam(learning_rate=2e-5,min_lr=1e-6,total_steps=6000)\n model.compile(optimizer, loss=focal_loss(), metrics=[tf.keras.metrics.AUC()])\n \n return model\n \n \n ","metadata":{"execution":{"iopub.status.busy":"2021-06-27T02:47:07.205364Z","iopub.execute_input":"2021-06-27T02:47:07.205714Z","iopub.status.idle":"2021-06-27T02:47:07.219258Z","shell.execute_reply.started":"2021-06-27T02:47:07.205685Z","shell.execute_reply":"2021-06-27T02:47:07.21793Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## TPU Settings","metadata":{}},{"cell_type":"code","source":"# Detect hardware, return appropriate distribution strategy\ntry:\n # TPU detection. No parameters necessary if TPU_NAME environment variable is\n # set: this is always the case on Kaggle.\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver()\n print('Running on TPU ', tpu.master())\nexcept ValueError:\n tpu = None\n\nif tpu:\n tf.config.experimental_connect_to_cluster(tpu)\n tf.tpu.experimental.initialize_tpu_system(tpu)\n strategy = tf.distribute.experimental.TPUStrategy(tpu)\nelse:\n # Default distribution strategy in Tensorflow. Works on CPU and single GPU.\n strategy = tf.distribute.get_strategy()\n\nprint(\"REPLICAS: \", strategy.num_replicas_in_sync)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-06-27T02:47:07.222615Z","iopub.execute_input":"2021-06-27T02:47:07.223004Z","iopub.status.idle":"2021-06-27T02:47:12.969501Z","shell.execute_reply.started":"2021-06-27T02:47:07.222965Z","shell.execute_reply":"2021-06-27T02:47:12.968283Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"AUTO = tf.data.experimental.AUTOTUNE\n\nGCS_DS_PATH = KaggleDatasets().get_gcs_path(\"jigsaw-multilingual-toxic-comment-classification\")\nMY_GCS_DS_PATH = KaggleDatasets().get_gcs_path(\"jigsaw-train-multilingual-coments-google-api\")\n\n# Configuration\nEPOCHS = 3\nBATCH_SIZE = 16 * strategy.num_replicas_in_sync\nMAX_LEN = 192\nMODEL = '../input/jplu-tf-xlm-roberta-large'\n","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-06-27T02:47:12.971926Z","iopub.execute_input":"2021-06-27T02:47:12.972367Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# First load the real tokenizer\ntokenizer = AutoTokenizer.from_pretrained(MODEL)\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Load Train,Validation and Test data","metadata":{}},{"cell_type":"code","source":"train1 = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/jigsaw-toxic-comment-train.csv\")\ntrain2 = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/jigsaw-unintended-bias-train.csv\")\ntrain2.toxic = train2.toxic.round().astype(int)\n\n# Combine train1 with a subset of train2\ntrain = pd.concat([\n train1[['comment_text', 'toxic']],\n train2[['comment_text', 'toxic']].query('toxic==1'),\n train2[['comment_text', 'toxic']].query('toxic==0').sample(n=90000, random_state=0)\n])\n\n\nvalid = pd.read_csv('/kaggle/input/jigsaw-multilingual-toxic-comment-classification/validation.csv')\ntest = pd.read_csv('/kaggle/input/jigsaw-multilingual-toxic-comment-classification/test.csv')\nsub = pd.read_csv('/kaggle/input/jigsaw-multilingual-toxic-comment-classification/sample_submission.csv')\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"- Prepare `train` data","metadata":{}},{"cell_type":"code","source":"labels = valid.toxic.unique()\nvalues = valid.toxic.value_counts()\n\n# Use `hole` to create a donut-like pie chart\nfig = go.Figure(data=[go.Pie(labels=labels, values=values, hole=.3)])\nfig.update_layout(title=\"Target Class distribution\")\nfig.show()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"The dataset clearly has a class imbalance problem.","metadata":{}},{"cell_type":"markdown","source":"- Prepare `validation` data by adding some translated examples.","metadata":{}},{"cell_type":"code","source":"\ntoxic=train1[train1.toxic==1].id.unique()\nnon_toxic=train1[train1.toxic==0].id.unique()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def get_valid(valid):\n \n cols=['comment_text','lang','toxic','id']\n i=0\n trans=pd.DataFrame()\n path=\"../input/jigsaw-train-multilingual-coments-google-api/\"\n for file in os.listdir(path):\n if file.endswith(\"cleaned.csv\"):\n\n df=pd.read_csv(path+file,usecols=['comment_text','toxic','id'])\n df['lang']=file.split(\"-\")[-2]\n\n trans=trans.append([df[df.id.isin(toxic[i*(len(toxic)//6):(i+1)*(len(toxic)//6)])][cols],\n df[df.id.isin(non_toxic[i*len(non_toxic)//6:(i+1)*len(non_toxic)//6])][cols]])\n i+=1\n\n valid= pd.concat([valid[['comment_text','lang','toxic']],trans])\n valid = shuffle(valid).reset_index(drop=True)\n \n \nvalid = get_valid()\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Let's check the language distribution in validation set","metadata":{}},{"cell_type":"code","source":"\nlabels = valid.lang.unique()\nvalues = valid.lang.value_counts()\n# Use `hole` to create a donut-like pie chart\nfig = go.Figure(data=[go.Pie(labels=labels, values=values, hole=.3)])\nfig.update_layout(title=\"Updated validation set language distribution\")\nfig.show()","metadata":{"_kg_hide-input":true,"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import gc\ndel trans,df,train1,train2\ngc.collect()","metadata":{"_kg_hide-input":true,"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Data preparation","metadata":{}},{"cell_type":"code","source":"%%time \n\n#x_train = regular_encode(train.comment_text.values, tokenizer, maxlen=MAX_LEN)\nx_valid = regular_encode(valid.comment_text.values, tokenizer, maxlen=MAX_LEN)\nx_test = regular_encode(test.content.values, tokenizer, maxlen=MAX_LEN)\n\n#y_train = train.toxic.values\ny_valid=valid.toxic.values\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"- Prepare the `test_dataset` as usual.","metadata":{}},{"cell_type":"code","source":"\n\ntest_dataset = (\n tf.data.Dataset\n .from_tensor_slices(x_test)\n .batch(BATCH_SIZE)\n)","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"- Below function prepare and return the `tf.data.Dataset` object during each fold of cross validation.","metadata":{}},{"cell_type":"code","source":"def get_fold_data(train_ind,valid_ind):\n \n print(\"Getting fold data...\")\n \n train_x=np.vstack([x_train,x_valid[train_ind]])\n train_y=np.hstack([y_train,y_valid[train_ind]])\n \n valid_x= x_valid[valid_ind]\n valid_y =y_valid[valid_ind]\n \n \n \n train_data = (\n tf.data.Dataset\n .from_tensor_slices((train_x, train_y))\n .repeat()\n .shuffle(2048)\n .batch(BATCH_SIZE)\n .prefetch(AUTO))\n \n valid_data= (\n tf.data.Dataset\n .from_tensor_slices((valid_x, valid_y))\n .shuffle(2048)\n .batch(BATCH_SIZE)\n .cache()\n .prefetch(AUTO)\n)\n return train_data,valid_data","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Focal loss","metadata":{}},{"cell_type":"markdown","source":"- We have a very unbalanced dataset,so I decided to use focal loss.\n","metadata":{}},{"cell_type":"code","source":"from tensorflow.keras import backend as K\n\ndef focal_loss(gamma=1.5, alpha=.25):\n def focal_loss_fixed(y_true, y_pred):\n pt_1 = tf.where(tf.equal(y_true, 1), y_pred, tf.ones_like(y_pred))\n pt_0 = tf.where(tf.equal(y_true, 0), y_pred, tf.zeros_like(y_pred))\n return -K.mean(alpha * K.pow(1. - pt_1, gamma) * K.log(pt_1)) - K.mean((1 - alpha) * K.pow(pt_0, gamma) * K.log(1. - pt_0))\n return focal_loss_fixed\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## K-fold training and cross validation\n\n- Now we do 3 fold cross validation.\n- We train on full english train set + 2/3 folds of of validation set.\n- We then evaluate model performace on the 1/3 fold of validation set.\n\nRecently I found out that you can clear the TPU memory while doing the cross-validation to prevent `OOM Resource exhausted error`.","metadata":{}},{"cell_type":"code","source":"\n\npred_test=np.zeros((test.shape[0],1))\nskf = StratifiedKFold(n_splits=5,shuffle=True,random_state=777)\nval_score=[]\n\n\nfor fold,(train_ind,valid_ind) in enumerate(skf.split(x_valid,valid.lang.values)):\n \n if fold < 0:\n \n print(\"fold\",fold+1)\n \n K.clear_session()\n tf.tpu.experimental.initialize_tpu_system(tpu)\n \n train_data,valid_data=get_fold_data(train_ind,valid_ind)\n \n Checkpoint=tf.keras.callbacks.ModelCheckpoint(f\"roberta_base_{fold+1}.h5\", monitor='val_loss', verbose=1, save_best_only=True,\n save_weights_only=True, mode='min')\n \n with strategy.scope():\n transformer_layer = TFAutoModel.from_pretrained(MODEL)\n model = build_model(transformer_layer, max_len=MAX_LEN)\n \n \n \n\n\n n_steps=(x_train.shape[0]+len(train_ind))//BATCH_SIZE\n print(n_steps)\n\n print(\"training model {} \".format(fold+1))\n\n train_history = model.fit(\n train_data,\n steps_per_epoch=n_steps,\n validation_data=valid_data,\n epochs=EPOCHS,callbacks=[Checkpoint],verbose=1)\n \n print(\"Loading model...\")\n model.load_weights(f\"roberta_base_{fold+1}.h5\")\n \n \n\n print(\"fold {} validation auc {}\".format(fold+1,np.mean(train_history.history['val_auc'])))\n print(\"fold {} validation auc {}\".format(fold+1,np.mean(train_history.history['val_loss'])))\n\n val_score.append(np.mean(train_history.history['val_auc']))\n \n print('predict on test....')\n preds=model.predict(test_dataset,verbose=1)\n\n pred_test+=preds/3\n \n#print(\"Mean cross-validation AUC\",np.mean(val_score))\n\n","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Making our Submission","metadata":{}},{"cell_type":"code","source":"sub['toxic'] = pred_test\nsub.to_csv('submission.csv', index=False)\nsub.head()","metadata":{"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### If you like this work,Please leave an upvote ⬆️\n## Work in progress...\n- Improve CV vs LB Correlation\n","metadata":{}},{"cell_type":"code","source":"","metadata":{"trusted":true},"execution_count":null,"outputs":[]}]}