{"cells":[{"metadata":{},"cell_type":"markdown","source":"## About this notebook\nWe have seen much implementation of BERT and its varients (XLM RoBERTa , RoBERTa).So this leads me to try and experiment with other Language models .In this notebook i will try to provide a very concise use of GPT-2 model. You can change the model type from **Large , Xtralarge , Medium , DistilGPT-2**.\nSo lets move.Also this note book is blatant copy of **xhlulu**'s kernel. so if you want to ***UPVOTE*** this kernel than be sure to ***UPVOTE*** his notebook too.\n\n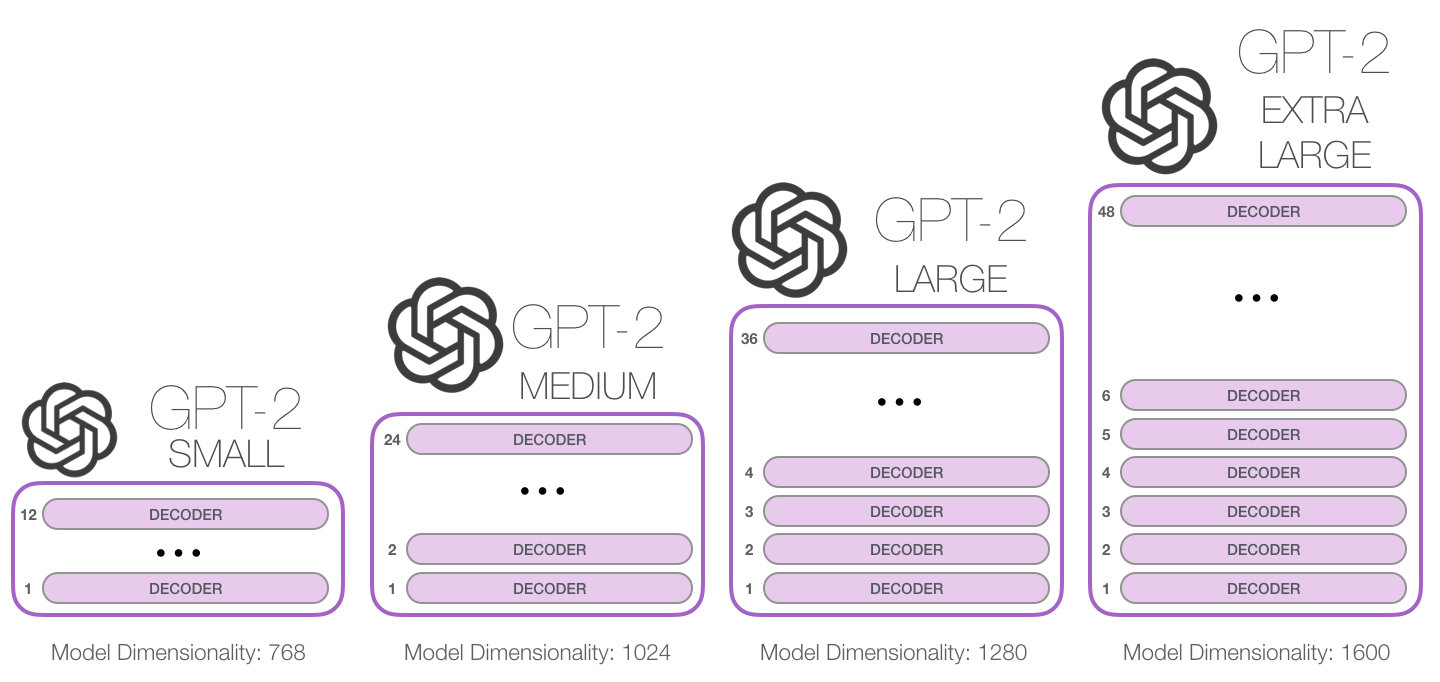\n\n**THIS USE TRANSLATED DATA, AND IS TRAIN ON THE VALIDATION SET.**\n\n\n### References\n* Original Author: [@xhlulu](https://www.kaggle.com/xhlulu/)\n* Original notebook: [Link](https://www.kaggle.com/xhlulu/jigsaw-tpu-distilbert-with-huggingface-and-keras)\n\nPlease UPVOTE this kernel if you like it. It motivates me to produce more quality content :)
\n Please do comment what your views are and what you understand from this.\n
Dont't forget to UPVOTE xhlulu's notebook ","execution_count":null},{"metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","trusted":true},"cell_type":"code","source":"import os\n\nimport numpy as np\nimport pandas as pd\nimport tensorflow as tf\nfrom tensorflow.keras.layers import Dense, Input\nfrom tensorflow.keras.optimizers import Adam\nfrom tensorflow.keras.models import Model\nfrom tensorflow.keras.callbacks import ModelCheckpoint\nfrom kaggle_datasets import KaggleDatasets\nimport transformers\nfrom transformers import TFAutoModel, AutoTokenizer\nfrom tqdm.notebook import tqdm\nfrom keras.preprocessing import sequence\nfrom tokenizers import Tokenizer, models, pre_tokenizers, decoders, processors","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Helper Functions","execution_count":null},{"metadata":{"_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","trusted":true},"cell_type":"code","source":"def fast_encode(texts, tokenizer, chunk_size=256, maxlen=192):\n \"\"\"\n https://www.kaggle.com/xhlulu/jigsaw-tpu-distilbert-with-huggingface-and-keras\n \"\"\"\n tokenizer.enable_truncation(max_length=maxlen)\n tokenizer.enable_padding(max_length=maxlen)\n all_ids = []\n \n for i in tqdm(range(0, len(texts), chunk_size)):\n text_chunk = texts[i:i+chunk_size].tolist()\n encs = tokenizer.encode_batch(text_chunk)\n all_ids.extend([enc.ids for enc in encs])\n \n return np.array(all_ids)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def gpt2_encode(texts, tokenizer, maxlen=192):\n enc_di = tokenizer.batch_encode_plus(\n texts, \n return_attention_masks=False, \n return_token_type_ids=False,\n max_length=maxlen,\n )\n pad_idx = tokenizer.convert_tokens_to_ids([''])[0]\n enc_di['input_ids'] = sequence.pad_sequences(enc_di['input_ids'], maxlen=MAX_LEN, padding='post',value = pad_idx)\n return np.array(enc_di['input_ids'])","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## TPU Configs","execution_count":null},{"metadata":{"trusted":true},"cell_type":"code","source":"# Detect hardware, return appropriate distribution strategy\ntry:\n # TPU detection. No parameters necessary if TPU_NAME environment variable is\n # set: this is always the case on Kaggle.\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver()\n print('Running on TPU ', tpu.master())\nexcept ValueError:\n tpu = None\n\nif tpu:\n tf.config.experimental_connect_to_cluster(tpu)\n tf.tpu.experimental.initialize_tpu_system(tpu)\n strategy = tf.distribute.experimental.TPUStrategy(tpu)\nelse:\n # Default distribution strategy in Tensorflow. Works on CPU and single GPU.\n strategy = tf.distribute.get_strategy()\n\nprint(\"REPLICAS: \", strategy.num_replicas_in_sync)","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Create fast tokenizer","execution_count":null},{"metadata":{},"cell_type":"markdown","source":"## Load text data into memory","execution_count":null},{"metadata":{"trusted":true},"cell_type":"code","source":"os.listdir('/kaggle/input')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"AUTO = tf.data.experimental.AUTOTUNE\n\n# Data access\nGCS_DS_PATH = KaggleDatasets().get_gcs_path('jigsaw-multilingual-toxic-comment-classification')\nMY_GCS_DS_PATH = KaggleDatasets().get_gcs_path('jigsaw-new-balanced-dataset')\nNEW_GCS_DS_PATH = KaggleDatasets().get_gcs_path('jigsaw-multilingual-toxic-test-translated')\n# Configuration\nEPOCHS = 5\nBATCH_SIZE = 16 * strategy.num_replicas_in_sync\nMAX_LEN = 192","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"from nltk import sent_tokenize\nimport re\nLANGS = {\n 'en': 'english',\n 'it': 'italian', \n 'fr': 'french', \n 'es': 'spanish',\n 'tr': 'turkish', \n 'ru': 'russian',\n 'pt': 'portuguese'\n}\n\ndef get_sentences(text, lang='en'):\n return sent_tokenize(text, LANGS.get(lang, 'english'))\n\ndef exclude_duplicate_sentences(text, lang='en'):\n sentences = []\n for sentence in get_sentences(text, lang):\n sentence = sentence.strip()\n if sentence not in sentences:\n sentences.append(sentence)\n return ' '.join(sentences)\n\ndef clean_text(text, lang='en'):\n text = str(text)\n text = re.sub(r'[0-9\"]', '', text)\n text = re.sub(r'#[\\S]+\\b', '', text)\n text = re.sub(r'@[\\S]+\\b', '', text)\n text = re.sub(r'https?\\S+', '', text)\n text = re.sub(r'\\s+', ' ', text)\n return text.strip()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"MODEL = 'gpt2-medium'\ntokenizer = AutoTokenizer.from_pretrained(MODEL)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"train1 = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/jigsaw-toxic-comment-train.csv\")\ntrain2 = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/jigsaw-unintended-bias-train.csv\")\ntrain2.toxic = train2.toxic.round().astype(int)\ntrain3 = pd.read_csv(\"/kaggle/input/jigsaw-new-balanced-dataset/new_toxic_comments.csv\")\ntrain3['toxic'] = 1\na=set(train1.columns)\n\nb = a.intersection(train2.columns)\n\n# Combine train1 with a subset of train2\ntrain = pd.concat([\n train1[b],\n train2[b].query('toxic==1'),\n train2[b].query('toxic==0').sample(n=100000, random_state=42)\n])\ndel train1\ndel train2\n\ntrain = train.drop(columns=['id'])\ntrain = train[['comment_text','toxic']]\ntrain3.columns = train.columns\ntrain = pd.concat([train,train3],axis=0)\ntrain['comment_text'] = train.comment_text.apply(lambda x : clean_text(x))\nfrom sklearn.utils import shuffle\ntrain = shuffle(train).reset_index(drop=True)\nX_test = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/test.csv\")\nsub = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/test.csv\")\nX_test = gpt2_encode(X_test.content.values, tokenizer, maxlen=MAX_LEN)\n\nX_valid = pd.read_csv(\"/kaggle/input/jigsaw-multilingual-toxic-comment-classification/validation.csv\")\nY_valid = X_valid.toxic.values\nX_valid = gpt2_encode(X_valid.comment_text.values, tokenizer, maxlen=MAX_LEN)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"X = gpt2_encode(train.comment_text.values, tokenizer, maxlen=MAX_LEN)\ny = train.toxic.values\ndel train\nimport gc\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"from tensorflow.keras import backend as K\n\ndef focal_loss(gamma=2., alpha=.2):\n def focal_loss_fixed(y_true, y_pred):\n pt_1 = tf.where(tf.equal(y_true, 1), y_pred, tf.ones_like(y_pred))\n pt_0 = tf.where(tf.equal(y_true, 0), y_pred, tf.zeros_like(y_pred))\n return -K.mean(alpha * K.pow(1. - pt_1, gamma) * K.log(pt_1)) - K.mean((1 - alpha) * K.pow(pt_0, gamma) * K.log(1. - pt_0))\n return focal_loss_fixed","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def build_lrfn(lr_start=0.000004, lr_max=0.000007, \n lr_min=0.0000002, lr_rampup_epochs=7, \n lr_sustain_epochs=0, lr_exp_decay=.87):\n lr_max = lr_max * strategy.num_replicas_in_sync\n\n def lrfn(epoch):\n if epoch < lr_rampup_epochs:\n lr = (lr_max - lr_start) / lr_rampup_epochs * epoch + lr_start\n elif epoch < lr_rampup_epochs + lr_sustain_epochs:\n lr = lr_max\n else:\n lr = (lr_max - lr_min) * lr_exp_decay**(epoch - lr_rampup_epochs - lr_sustain_epochs) + lr_min\n return lr\n \n return lrfn\n\nfrom tensorflow.keras.callbacks import Callback ","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"import matplotlib.pyplot as plt\n\nplt.figure(figsize=(10, 7))\n\n_lrfn = build_lrfn()\nplt.plot([i for i in range(35)], [_lrfn(i) for i in range(35)]);","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def build_model(transformer, loss , max_len=192):\n \n input_word_ids = Input(shape=(max_len,), dtype=tf.int32, name=\"input_word_ids\")\n sequence_output = transformer(input_word_ids)[0]\n cls_token = sequence_output[:, 0, :]\n out = Dense(1, activation='sigmoid')(cls_token)\n \n model = Model(inputs=input_word_ids, outputs=out)\n model.compile(Adam(lr=1e-6), loss=loss, metrics=[tf.keras.metrics.AUC()])\n \n return model","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"with strategy.scope():\n transformer_layer = TFAutoModel.from_pretrained(MODEL)\n model = build_model(transformer_layer, loss='binary_crossentropy', max_len=MAX_LEN)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"%%time\nimport warnings \nwarnings.filterwarnings('ignore')\npred = []\nfrom sklearn.model_selection import StratifiedKFold\nskf = StratifiedKFold(n_splits=3,shuffle = True,random_state = 42)\nfold = 1\nfor train_index, test_index in skf.split(X, y):\n X_train,a = X[train_index] , X[test_index]\n Y_train,v = y[train_index] , y[test_index]\n \n train_dataset = (\n tf.data.Dataset\n .from_tensor_slices((X_train, Y_train))\n .repeat()\n .shuffle(2048)\n .batch(BATCH_SIZE)\n .prefetch(AUTO)\n )\n\n valid_dataset = (\n tf.data.Dataset\n .from_tensor_slices((X_valid, Y_valid))\n .batch(BATCH_SIZE)\n .prefetch(AUTO)\n )\n \n test_dataset = (\n tf.data.Dataset\n .from_tensor_slices(X_test)\n .batch(BATCH_SIZE)\n .prefetch(AUTO)\n )\n \n lrfn = build_lrfn()\n lr_schedule = tf.keras.callbacks.LearningRateScheduler(lrfn, verbose=1)\n n_steps = X_train.shape[0] // BATCH_SIZE\n \n train_history = model.fit(\n train_dataset,\n steps_per_epoch=n_steps,\n validation_data=valid_dataset,\n callbacks=[lr_schedule],\n epochs=EPOCHS\n )\n sub['toxic'] = model.predict(test_dataset, verbose=1)\n sub.to_csv(str(fold) + 'gpt2m_submission.csv', index=False)\n fold = fold +1 \n print(fold)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"pygments_lexer":"ipython3","nbconvert_exporter":"python","version":"3.6.4","file_extension":".py","codemirror_mode":{"name":"ipython","version":3},"name":"python","mimetype":"text/x-python"}},"nbformat":4,"nbformat_minor":4}