
Hi Kagglers,
\n\nMy solution is based on the COCO challenge 2018 winners article: https://arxiv.org/abs/1901.07518.
\n\nhttps://github.com/amirassov/kaggle-imaterialist
\n\nHybrid Task Cascade with ResNeXt-101-64x4d-FPN backbone. This model has a metric Mask mAP = 43.9 on COCO dataset. This is SOTA for instance segmentation.
\n\nFor validation, I used 450 training samples splitted using https://github.com/trent-b/iterative-stratification.
\n\nI applied light augmentatios from the albumentations library to the original image. Then I use multi-scale training: in each iteration, the scale of short edge is randomly sampled\nfrom [600, 1200], and the scale of long edge is fixed as 1900.\n
SGD(lr=0.03, momentum=0.9, weight_decay=0.0001)if iterations < 500:\nlr = warmup(warmup_ratio=1 / 3)\nif epochs == 10:\nlr = lr ∗ 0.1\nif epochs == 18:\nlr = lr ∗ 0.1\nif epochs > 20:\nstopAfter the 12th epoch with the default parameters, the metric on LB was 0.21913. Next, I tuned postprocessing thresholds using validation data:\n* score_thr=0.5\n* nms={type: 'nms', iou_thr: 0.3}\n* max_per_img=100\n* mask_thr_binary=0.45
This improved the metric on LB: 0.21913 -> 0.30011.
\n\nI use 3 scales as well as horizontal flip at test time and ensemble the results. Testing scales are (1000, 1600), (1200, 1900), (1400, 2200).
\n\nI drew a TTA scheme for Mask R-CNN, which is implemented in mmdetection library. For Hybrid Task Cascade R-CNN, I rewrote this code.
\n\nThis improved the metric on LB: 0.30011 -> 0.31074.\n
I ensemble the 3 best checkpoints of my model. The ensemble scheme is similar to TTA.
\n\nThis improved the metric on LB: 0.31074 -> 0.31626.\n
I didn't use attributes at all: they were difficult to predict and the removal of classes with attributes greatly improved the metric.
\n\nDuring the whole competition, I deleted classes with attributes: {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} U {27, 28, 33}. But two days before the end I read [the discussion] (https://www.kaggle.com/c/imaterialist-fashion-2019-FGVC6/discussion/94811#latest548137) and added back classes {27, 28, 33 }.
This improved the metric on LB: 0.31626 -> 0.33511.
\n\nMy post-processing algorithm for avoid intersections of masks of the same class:\ndef hard_overlaps_suppression(binary_mask, scores):\n not_overlap_mask = []\n for i in np.argsort(scores)[::-1]:\n current_mask = binary_mask[..., i].copy()\n for mask in not_overlap_mask:\n current_mask = np.bitwise_and(current_mask, np.invert(mask))\n not_overlap_mask.append(current_mask)\n return np.stack(not_overlap_mask, -1)
I deleted objects with an area of less than 20 pixels.
\n\nThis improved the metric on LB: 0.33511 -> 0.33621.
", "messages": [ { "id": "549786", "postDate": "06/11/2019 03:13:40", "content": "Hi Kagglers,
\n\nMy solution is based on the COCO challenge 2018 winners article: https://arxiv.org/abs/1901.07518.
\n\nhttps://github.com/amirassov/kaggle-imaterialist
\n\nHybrid Task Cascade with ResNeXt-101-64x4d-FPN backbone. This model has a metric Mask mAP = 43.9 on COCO dataset. This is SOTA for instance segmentation.
\n\nFor validation, I used 450 training samples splitted using https://github.com/trent-b/iterative-stratification.
\n\nI applied light augmentatios from the albumentations library to the original image. Then I use multi-scale training: in each iteration, the scale of short edge is randomly sampled\nfrom [600, 1200], and the scale of long edge is fixed as 1900.\n
SGD(lr=0.03, momentum=0.9, weight_decay=0.0001)if iterations < 500:\nlr = warmup(warmup_ratio=1 / 3)\nif epochs == 10:\nlr = lr ∗ 0.1\nif epochs == 18:\nlr = lr ∗ 0.1\nif epochs > 20:\nstopAfter the 12th epoch with the default parameters, the metric on LB was 0.21913. Next, I tuned postprocessing thresholds using validation data:\n* score_thr=0.5\n* nms={type: 'nms', iou_thr: 0.3}\n* max_per_img=100\n* mask_thr_binary=0.45
This improved the metric on LB: 0.21913 -> 0.30011.
\n\nI use 3 scales as well as horizontal flip at test time and ensemble the results. Testing scales are (1000, 1600), (1200, 1900), (1400, 2200).
\n\nI drew a TTA scheme for Mask R-CNN, which is implemented in mmdetection library. For Hybrid Task Cascade R-CNN, I rewrote this code.
\n\nThis improved the metric on LB: 0.30011 -> 0.31074.\n
I ensemble the 3 best checkpoints of my model. The ensemble scheme is similar to TTA.
\n\nThis improved the metric on LB: 0.31074 -> 0.31626.\n
I didn't use attributes at all: they were difficult to predict and the removal of classes with attributes greatly improved the metric.
\n\nDuring the whole competition, I deleted classes with attributes: {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} U {27, 28, 33}. But two days before the end I read [the discussion] (https://www.kaggle.com/c/imaterialist-fashion-2019-FGVC6/discussion/94811#latest548137) and added back classes {27, 28, 33 }.
This improved the metric on LB: 0.31626 -> 0.33511.
\n\nMy post-processing algorithm for avoid intersections of masks of the same class:\ndef hard_overlaps_suppression(binary_mask, scores):\n not_overlap_mask = []\n for i in np.argsort(scores)[::-1]:\n current_mask = binary_mask[..., i].copy()\n for mask in not_overlap_mask:\n current_mask = np.bitwise_and(current_mask, np.invert(mask))\n not_overlap_mask.append(current_mask)\n return np.stack(not_overlap_mask, -1)
I deleted objects with an area of less than 20 pixels.
\n\nThis improved the metric on LB: 0.33511 -> 0.33621.
", "rawMarkdown": "Hi Kagglers,\n\nMy solution is based on the COCO challenge 2018 winners article: https://arxiv.org/abs/1901.07518. \n\n# Code: \nhttps://github.com/amirassov/kaggle-imaterialist\n\n# Model: \n[Hybrid Task Cascade with ResNeXt-101-64x4d-FPN backbone](https://github.com/open-mmlab/mmdetection/blob/master/configs/htc/htc_dconv_c3-c5_mstrain_400_1400_x101_64x4d_fpn_20e.py). This model has a metric Mask mAP = 43.9 on COCO dataset. This is SOTA for instance segmentation.\n\n# Validation:\nFor validation, I used 450 training samples splitted using https://github.com/trent-b/iterative-stratification.\n\n# Preprocessing:\nI applied light augmentatios from the [albumentations](https://github.com/albu/albumentations) library to the original image. Then I use multi-scale training: in each iteration, the scale of short edge is randomly sampled\nfrom [600, 1200], and the scale of long edge is fixed as 1900.\n\n\n# Training details:\n* pre-train from COCO\n* optimizer: `SGD(lr=0.03, momentum=0.9, weight_decay=0.0001)`\n* batch_size: 16 = 2 images per gpu x 8 gpus Tesla V100\n* learning rate scheduler:\n```if iterations < 500:\n lr = warmup(warmup_ratio=1 / 3)\nif epochs == 10:\n lr = lr ∗ 0.1\nif epochs == 18:\n lr = lr ∗ 0.1\nif epochs > 20:\n stop```\n* training time: ~3 days.\n\n# Parameter tuning:\nAfter the 12th epoch with the default parameters, the metric on LB was **0.21913**. Next, I tuned postprocessing thresholds using validation data:\n* `score_thr=0.5`\n* `nms={type: 'nms', iou_thr: 0.3}`\n* `max_per_img=100`\n* `mask_thr_binary=0.45`\n\nThis improved the metric on LB: **0.21913 -> 0.30011.**\n\n# Test time augmentation:\nI use 3 scales as well as horizontal flip at test time and ensemble the results. Testing scales are (1000, 1600), (1200, 1900), (1400, 2200). \n\nI drew a TTA scheme for Mask R-CNN, which is implemented in mmdetection library. For Hybrid Task Cascade R-CNN, I rewrote this code. \n\nThis improved the metric on LB: **0.30011 -> 0.31074.**\n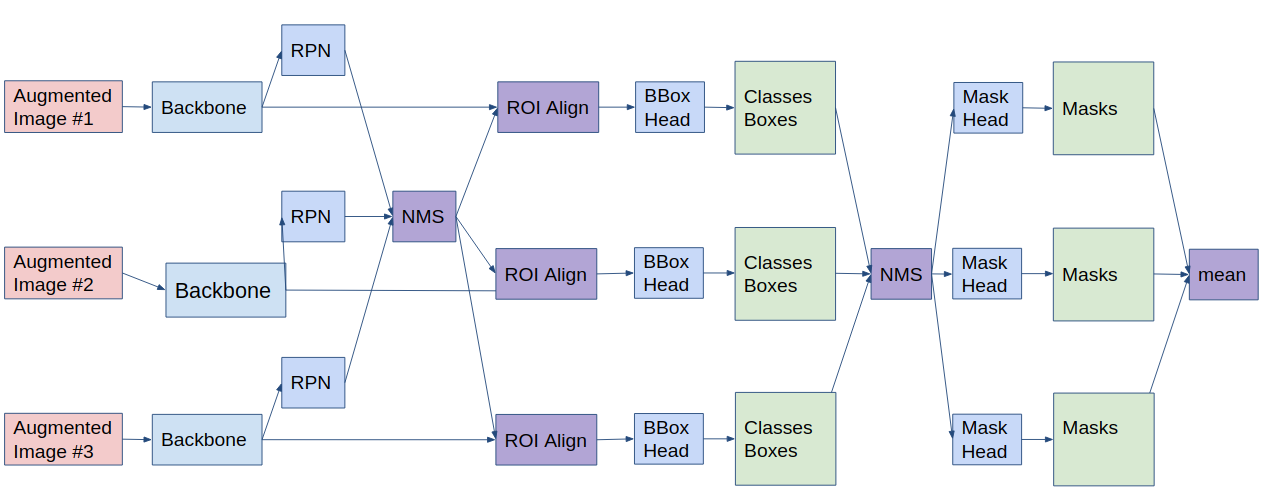\n\n# Ensemble:\nI ensemble the 3 best checkpoints of my model. The ensemble scheme is similar to TTA. \n\nThis improved the metric on LB: **0.31074 -> 0.31626.**\n\n\n# Attributes:\nI didn't use attributes at all: they were difficult to predict and the removal of classes with attributes greatly improved the metric. \n\nDuring the whole competition, I deleted classes with attributes: `{0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}` U `{27, 28, 33}`. But two days before the end I read [the discussion] (https://www.kaggle.com/c/imaterialist-fashion-2019-FGVC6/discussion/94811#latest548137) and added back classes `{27, 28, 33 }`. \n\nThis improved the metric on LB: **0.31626 -> 0.33511.**\n\n# Postprocessing for masks\nMy post-processing algorithm for avoid intersections of masks of the same class:\n```def hard_overlaps_suppression(binary_mask, scores):\n not_overlap_mask = []\n for i in np.argsort(scores)[::-1]:\n current_mask = binary_mask[..., i].copy()\n for mask in not_overlap_mask:\n current_mask = np.bitwise_and(current_mask, np.invert(mask))\n not_overlap_mask.append(current_mask)\n return np.stack(not_overlap_mask, -1)```\n\n# Small postprocessing:\nI deleted objects with an area of less than 20 pixels. \n\nThis improved the metric on LB: **0.33511 -> 0.33621.**", "votes": null }, { "id": "549788", "postDate": "06/11/2019 03:16:54", "content": "Wow, I was so close..... I had exactly the same pipeline as yours, except the part of nms threshold....
", "rawMarkdown": "Wow, I was so close..... I had exactly the same pipeline as yours, except the part of nms threshold....", "votes": null }, { "id": "549798", "postDate": "06/11/2019 03:48:14", "content": "Setting: \n* score_thr=0.5\n* nms={type: 'nms', iou_thr: 0.3}\n* max_per_img=100\n* mask_thr_binary=0.45
Seriously improves from 0.21913 to 0.30011? That was ... incredible.\nI only tried tuning the score_thr, and the improvement is only around 0.02
\n\nHave you tried Soft-NMS? lowering the nms threshold seems to have a similar goal on preserving more proposals.
\n\nThanks for the sharing, and big congrats !
", "rawMarkdown": "Setting: \n* `score_thr=0.5`\n* `nms={type: 'nms', iou_thr: 0.3}`\n* `max_per_img=100`\n* `mask_thr_binary=0.45`\n\nSeriously improves from 0.21913 to 0.30011? That was ... incredible.\nI only tried tuning the score_thr, and the improvement is only around 0.02\n\nHave you tried Soft-NMS? lowering the nms threshold seems to have a similar goal on preserving more proposals.\n\nThanks for the sharing, and big congrats !", "votes": null }, { "id": "549799", "postDate": "06/11/2019 03:49:19", "content": "Many thanks for sharing your solutions. Looking forward to your source code! Congratulations! :-)
", "rawMarkdown": "Many thanks for sharing your solutions. Looking forward to your source code! Congratulations! :-)", "votes": null }, { "id": "549808", "postDate": "06/11/2019 03:54:43", "content": "This setting also adds little to my score.
", "rawMarkdown": "This setting also adds little to my score.", "votes": null }, { "id": "549823", "postDate": "06/11/2019 04:07:31", "content": "Soft-nms increased my score by like 0.0001....
", "rawMarkdown": "Soft-nms increased my score by like 0.0001....", "votes": null }, { "id": "549824", "postDate": "06/11/2019 04:09:23", "content": "Thank you for your sharing!
", "rawMarkdown": "Thank you for your sharing!", "votes": null }, { "id": "549827", "postDate": "06/11/2019 04:20:05", "content": "I think it depends on the post-processing algorithm to avoid intersections of masks of the same class.
\n\nBy default, score_threshold = 0.001. My post-processing algorithm for masks did not delete the masks. The result was a lot of masks with small scores. This greatly degraded the metric.\nI added this algorithm to the solution description.
Soft-nms didn't increase my score.
", "rawMarkdown": "I think it depends on the post-processing algorithm to avoid intersections of masks of the same class.\n\nBy default, `score_threshold = 0.001.` My post-processing algorithm for masks did not delete the masks. The result was a lot of masks with small scores. This greatly degraded the metric.\nI added this algorithm to the solution description.\n\n\nSoft-nms didn't increase my score.", "votes": null }, { "id": "549844", "postDate": "06/11/2019 04:47:37", "content": "Looking forward to seeing your code!
", "rawMarkdown": "Looking forward to seeing your code!", "votes": null }, { "id": "549873", "postDate": "06/11/2019 05:26:02", "content": "Congratulations :) Looking forward to your code. Thank you very much.
", "rawMarkdown": "Congratulations :) Looking forward to your code. Thank you very much.", "votes": null }, { "id": "549882", "postDate": "06/11/2019 05:36:35", "content": "Thanks!
", "rawMarkdown": "Thanks!", "votes": null }, { "id": "549923", "postDate": "06/11/2019 06:31:35", "content": "Congratulations with 1st and Competitions Master!\nLooking forward to your code!\nThank you very much!
", "rawMarkdown": "Congratulations with 1st and Competitions Master!\nLooking forward to your code!\nThank you very much!", "votes": null }, { "id": "549936", "postDate": "06/11/2019 06:40:07", "content": "TOP!
", "rawMarkdown": "TOP!", "votes": null }, { "id": "549975", "postDate": "06/11/2019 07:28:20", "content": "Congratulations and thank you for your sharings!
", "rawMarkdown": "Congratulations and thank you for your sharings!", "votes": null }, { "id": "549986", "postDate": "06/11/2019 07:40:07", "content": "Pretty good! Waiting for the code!
", "rawMarkdown": "Pretty good! Waiting for the code!", "votes": null }, { "id": "550002", "postDate": "06/11/2019 07:59:30", "content": "Good job)
", "rawMarkdown": "Good job)", "votes": null }, { "id": "550102", "postDate": "06/11/2019 09:54:39", "content": "Thank you!
", "rawMarkdown": "Thank you!", "votes": null }, { "id": "550116", "postDate": "06/11/2019 10:07:42", "content": "Thanks
", "rawMarkdown": "Thanks", "votes": null }, { "id": "550160", "postDate": "06/11/2019 11:15:07", "content": "Congratulations.
\n\nIt seems that discarding classes with attributes is the key to win a gold.\nBy simply removing ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}, we could get 0.31662/0.30403 .
\n\nAccording to https://github.com/visipedia/imat_comp, there are 10K images with both segmentation and fine-grained attributes. We have 6696 in train, so probably all of the test data are with fine-grained attributes.
\n\nIt was close...
", "rawMarkdown": "Congratulations.\n\nIt seems that discarding classes with attributes is the key to win a gold.\nBy simply removing ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}, we could get 0.31662/0.30403 .\n\nAccording to https://github.com/visipedia/imat_comp, there are 10K images with both segmentation and fine-grained attributes. We have 6696 in train, so probably all of the test data are with fine-grained attributes.\n\nIt was close...", "votes": null }, { "id": "550168", "postDate": "06/11/2019 11:27:24", "content": "Congratulations and thanks for sharing!
", "rawMarkdown": "Congratulations and thanks for sharing!", "votes": null }, { "id": "550495", "postDate": "06/11/2019 17:09:02", "content": "Thank you for sharing the details
", "rawMarkdown": "Thank you for sharing the details", "votes": null }, { "id": "550552", "postDate": "06/11/2019 18:33:16", "content": "Awesome!
", "rawMarkdown": "Awesome!", "votes": null }, { "id": "550755", "postDate": "06/12/2019 02:18:41", "content": "Hi @amiras Thank you for sharing your solution! Will you attend CVPR2019 this year? Schedule of our upcoming FGVC workshop can be found here.
\n\nAs one of top 3 teams, you are invited to present your solution in our upcoming FGVC workshop at CVPR.
\n\nThank you!
", "rawMarkdown": "Hi @amiras Thank you for sharing your solution! Will you attend CVPR2019 this year? [Schedule of our upcoming FGVC workshop can be found here](https://sites.google.com/view/fgvc6/program?authuser=0).\n\nAs one of top 3 teams, you are invited to present your solution in our upcoming FGVC workshop at CVPR.\n\n1. Could you be able to send me 1-2 pages of google slides (or pdf) describing your method? So I can include it in my presentation of this challenge.\n2. You will also have access to a 4 foot x 4 foot poster board in our FGVC workshop if you want to present your method at the workshop. (If you couldn't make it to the workshop, another option is that you can send your poster to me before June 14. I can help you print it and hang in the board that day)\n\nThank you!", "votes": null }, { "id": "550887", "postDate": "06/12/2019 05:53:18", "content": "Congrats!Thank you for sharing the details.
", "rawMarkdown": "Congrats!Thank you for sharing the details.", "votes": null }, { "id": "551038", "postDate": "06/12/2019 09:21:16", "content": "Congratulations :) Looking forward to seeing your code!
", "rawMarkdown": "Congratulations :) Looking forward to seeing your code!", "votes": null }, { "id": "551098", "postDate": "06/12/2019 10:38:40", "content": "Thank you for sharing!
", "rawMarkdown": "Thank you for sharing!", "votes": null }, { "id": "551973", "postDate": "06/13/2019 11:04:37", "content": "If a line's classid is 3 4 7 8 10 11 45, you means to delete this line or just remove the attribute?
", "rawMarkdown": "If a line's classid is 3 4 7 8 10 11 45, you means to delete this line or just remove the attribute?", "votes": null }, { "id": "552021", "postDate": "06/13/2019 12:23:46", "content": "I just deleted the lines.
\n\nActually, I think the instruction of LB evaluation metric might be incorrect.\n> The score returned by the competition metric is the mean taken over the individual average precisions of each image and each ClassId in the test dataset.
\n\nHow many ClassIds do we have? It's 46 * (2^92). In train, it is 6371. Taking an average over ClassIds would be...
\n\nHere is my guess. The metric used might be a mean taken over the average precision of each image. And for each image, an overall AP is calculated. There is no ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} in the test set, so all those predictions would be FP.
", "rawMarkdown": "I just deleted the lines.\n\nActually, I think the instruction of LB evaluation metric might be incorrect.\n> The score returned by the competition metric is the mean taken over the individual average precisions of each image and each ClassId in the test dataset.\n\nHow many ClassIds do we have? It's 46 * (2^92). In train, it is 6371. Taking an average over ClassIds would be...\n\nHere is my guess. The metric used might be a mean taken over the average precision of each image. And for each image, an overall AP is calculated. There is no ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} in the test set, so all those predictions would be FP.", "votes": null }, { "id": "552092", "postDate": "06/13/2019 13:55:31", "content": "Thank you for sharing,when I remvoe it, I get 0.31802 / 0.33214 , I am a loser of this game.
", "rawMarkdown": "Thank you for sharing,when I remvoe it, I get 0.31802 / 0.33214 , I am a loser of this game.", "votes": null }, { "id": "552482", "postDate": "06/14/2019 03:24:26", "content": "thanks for sharing
", "rawMarkdown": "thanks for sharing", "votes": null }, { "id": "552612", "postDate": "06/14/2019 07:47:34", "content": "Thanks for sharing!
", "rawMarkdown": "Thanks for sharing!", "votes": null }, { "id": "552767", "postDate": "06/14/2019 13:58:55", "content": "Awesome codes!! Thank you :)
", "rawMarkdown": "Awesome codes!! Thank you :)", "votes": null }, { "id": "552829", "postDate": "06/14/2019 15:58:53", "content": "Thanks! Keep it up.
", "rawMarkdown": "Thanks! Keep it up.", "votes": null }, { "id": "553688", "postDate": "06/16/2019 06:28:01", "content": "Congrats! and also thanks a lot for sharing this
", "rawMarkdown": "Congrats! and also thanks a lot for sharing this", "votes": null }, { "id": "553775", "postDate": "06/16/2019 09:53:02", "content": "Congrats! Thank you for sharing your detailed descriptions and awesome codes !
", "rawMarkdown": "Congrats! Thank you for sharing your detailed descriptions and awesome codes !", "votes": null }, { "id": "556784", "postDate": "06/20/2019 16:38:30", "content": "Thanks for the heads up.
", "rawMarkdown": "Thanks for the heads up.", "votes": null }, { "id": "567841", "postDate": "07/04/2019 04:36:52", "content": "Thank you for sharing
", "rawMarkdown": "Thank you for sharing", "votes": null }, { "id": "614614", "postDate": "08/31/2019 19:04:12", "content": "Congratulations for the 1st place!\nThank you for sharing.
", "rawMarkdown": "Congratulations for the 1st place!\nThank you for sharing.", "votes": null }, { "id": "623510", "postDate": "09/11/2019 03:26:40", "content": "AMAZING WORK. thanks for sharing
", "rawMarkdown": "AMAZING WORK. thanks for sharing", "votes": null }, { "id": "626271", "postDate": "09/14/2019 05:27:00", "content": "@amiras How do you do ensembling? For example what if one model predict an object but another model don't?
\n\nThanks.
", "rawMarkdown": "amiras How do you do ensembling? For example what if one model predict an object but another model don't?\n\nThanks.", "votes": null }, { "id": "626701", "postDate": "09/14/2019 17:40:53", "content": "The ensemble is made using the nms algorithm. In the simple case, let one algorithm predict bboxes1, the second algorithm predict bboxes2. Next, we concatenate these answers and get bboxes = bboxes1 + bboxes2. Next we apply the nms algorithm. As a result, we get the ensemble_bboxes = nms(bboxes). For a more detailed information, see the scheme and the code.
Great job! Thanks for sharing.
", "rawMarkdown": "Great job! Thanks for sharing.", "votes": null }, { "id": "815119", "postDate": "04/21/2020 09:06:16", "content": "Hi so how do you predict ClassIds {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} if you delete all lines with this class and thus dont train on it? Those are the very basic classes that are the biggest part of the dataset.
", "rawMarkdown": "Hi so how do you predict ClassIds {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} if you delete all lines with this class and thus dont train on it? Those are the very basic classes that are the biggest part of the dataset.", "votes": null }, { "id": "2454079", "postDate": "09/24/2023 15:06:31", "content": "What a great work!
", "rawMarkdown": "What a great work!", "votes": null } ], "comments": [ { "id": 2454079, "author_name": "peterthegenius", "author_url": "", "post_date": "09/24/2023 15:06:31", "content": "What a great work!
", "votes": null, "replies": [] }, { "id": 549788, "author_name": "alexanderliao", "author_url": "", "post_date": "06/11/2019 03:16:54", "content": "Wow, I was so close..... I had exactly the same pipeline as yours, except the part of nms threshold....
", "votes": null, "replies": [] }, { "id": 549798, "author_name": "lzhbrian", "author_url": "", "post_date": "06/11/2019 03:48:14", "content": "Setting: \n* score_thr=0.5\n* nms={type: 'nms', iou_thr: 0.3}\n* max_per_img=100\n* mask_thr_binary=0.45
Seriously improves from 0.21913 to 0.30011? That was ... incredible.\nI only tried tuning the score_thr, and the improvement is only around 0.02
\n\nHave you tried Soft-NMS? lowering the nms threshold seems to have a similar goal on preserving more proposals.
\n\nThanks for the sharing, and big congrats !
", "votes": null, "replies": [ { "id": 549808, "author_name": "hesene", "author_url": "", "post_date": "06/11/2019 03:54:43", "content": "This setting also adds little to my score.
", "votes": null, "replies": [] }, { "id": 549823, "author_name": "alexanderliao", "author_url": "", "post_date": "06/11/2019 04:07:31", "content": "Soft-nms increased my score by like 0.0001....
", "votes": null, "replies": [] }, { "id": 549827, "author_name": "amiras", "author_url": "", "post_date": "06/11/2019 04:20:05", "content": "I think it depends on the post-processing algorithm to avoid intersections of masks of the same class.
\n\nBy default, score_threshold = 0.001. My post-processing algorithm for masks did not delete the masks. The result was a lot of masks with small scores. This greatly degraded the metric.\nI added this algorithm to the solution description.
Soft-nms didn't increase my score.
", "votes": null, "replies": [] } ] }, { "id": 549799, "author_name": "projdev", "author_url": "", "post_date": "06/11/2019 03:49:19", "content": "Many thanks for sharing your solutions. Looking forward to your source code! Congratulations! :-)
", "votes": null, "replies": [] }, { "id": 549824, "author_name": "hesene", "author_url": "", "post_date": "06/11/2019 04:09:23", "content": "Thank you for your sharing!
", "votes": null, "replies": [] }, { "id": 549844, "author_name": "manyfoldcv", "author_url": "", "post_date": "06/11/2019 04:47:37", "content": "Looking forward to seeing your code!
", "votes": null, "replies": [] }, { "id": 549873, "author_name": "nasimkh", "author_url": "", "post_date": "06/11/2019 05:26:02", "content": "Congratulations :) Looking forward to your code. Thank you very much.
", "votes": null, "replies": [] }, { "id": 549882, "author_name": "timmmmmms", "author_url": "", "post_date": "06/11/2019 05:36:35", "content": "Thanks!
", "votes": null, "replies": [] }, { "id": 549923, "author_name": "golubev", "author_url": "", "post_date": "06/11/2019 06:31:35", "content": "Congratulations with 1st and Competitions Master!\nLooking forward to your code!\nThank you very much!
", "votes": null, "replies": [] }, { "id": 549936, "author_name": "nuller", "author_url": "", "post_date": "06/11/2019 06:40:07", "content": "TOP!
", "votes": null, "replies": [] }, { "id": 549975, "author_name": "mathurinache", "author_url": "", "post_date": "06/11/2019 07:28:20", "content": "Congratulations and thank you for your sharings!
", "votes": null, "replies": [] }, { "id": 549986, "author_name": "brunhs", "author_url": "", "post_date": "06/11/2019 07:40:07", "content": "Pretty good! Waiting for the code!
", "votes": null, "replies": [] }, { "id": 550002, "author_name": "almakhann", "author_url": "", "post_date": "06/11/2019 07:59:30", "content": "Good job)
", "votes": null, "replies": [] }, { "id": 550102, "author_name": "azimovsh", "author_url": "", "post_date": "06/11/2019 09:54:39", "content": "Thank you!
", "votes": null, "replies": [] }, { "id": 550116, "author_name": "veegalinova", "author_url": "", "post_date": "06/11/2019 10:07:42", "content": "Thanks
", "votes": null, "replies": [] }, { "id": 550160, "author_name": "tascj0", "author_url": "", "post_date": "06/11/2019 11:15:07", "content": "Congratulations.
\n\nIt seems that discarding classes with attributes is the key to win a gold.\nBy simply removing ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}, we could get 0.31662/0.30403 .
\n\nAccording to https://github.com/visipedia/imat_comp, there are 10K images with both segmentation and fine-grained attributes. We have 6696 in train, so probably all of the test data are with fine-grained attributes.
\n\nIt was close...
", "votes": null, "replies": [ { "id": 551973, "author_name": "hesene", "author_url": "", "post_date": "06/13/2019 11:04:37", "content": "If a line's classid is 3 4 7 8 10 11 45, you means to delete this line or just remove the attribute?
", "votes": null, "replies": [] }, { "id": 552021, "author_name": "tascj0", "author_url": "", "post_date": "06/13/2019 12:23:46", "content": "I just deleted the lines.
\n\nActually, I think the instruction of LB evaluation metric might be incorrect.\n> The score returned by the competition metric is the mean taken over the individual average precisions of each image and each ClassId in the test dataset.
\n\nHow many ClassIds do we have? It's 46 * (2^92). In train, it is 6371. Taking an average over ClassIds would be...
\n\nHere is my guess. The metric used might be a mean taken over the average precision of each image. And for each image, an overall AP is calculated. There is no ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} in the test set, so all those predictions would be FP.
", "votes": null, "replies": [] }, { "id": 552092, "author_name": "hesene", "author_url": "", "post_date": "06/13/2019 13:55:31", "content": "Thank you for sharing,when I remvoe it, I get 0.31802 / 0.33214 , I am a loser of this game.
", "votes": null, "replies": [] }, { "id": 815119, "author_name": "kka217", "author_url": "", "post_date": "04/21/2020 09:06:16", "content": "Hi so how do you predict ClassIds {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} if you delete all lines with this class and thus dont train on it? Those are the very basic classes that are the biggest part of the dataset.
", "votes": null, "replies": [] } ] }, { "id": 550168, "author_name": "anushkasharma", "author_url": "", "post_date": "06/11/2019 11:27:24", "content": "Congratulations and thanks for sharing!
", "votes": null, "replies": [] }, { "id": 550495, "author_name": "mrudul", "author_url": "", "post_date": "06/11/2019 17:09:02", "content": "Thank you for sharing the details
", "votes": null, "replies": [] }, { "id": 550552, "author_name": "kevinrosalesdev", "author_url": "", "post_date": "06/11/2019 18:33:16", "content": "Awesome!
", "votes": null, "replies": [] }, { "id": 550755, "author_name": "makeitworkjml", "author_url": "", "post_date": "06/12/2019 02:18:41", "content": "Hi @amiras Thank you for sharing your solution! Will you attend CVPR2019 this year? Schedule of our upcoming FGVC workshop can be found here.
\n\nAs one of top 3 teams, you are invited to present your solution in our upcoming FGVC workshop at CVPR.
\n\nThank you!
", "votes": null, "replies": [] }, { "id": 550887, "author_name": "chrisluu", "author_url": "", "post_date": "06/12/2019 05:53:18", "content": "Congrats!Thank you for sharing the details.
", "votes": null, "replies": [] }, { "id": 551038, "author_name": "kongcraft", "author_url": "", "post_date": "06/12/2019 09:21:16", "content": "Congratulations :) Looking forward to seeing your code!
", "votes": null, "replies": [] }, { "id": 551098, "author_name": "koyyy0", "author_url": "", "post_date": "06/12/2019 10:38:40", "content": "Thank you for sharing!
", "votes": null, "replies": [] }, { "id": 552482, "author_name": "mauroban", "author_url": "", "post_date": "06/14/2019 03:24:26", "content": "thanks for sharing
", "votes": null, "replies": [] }, { "id": 552612, "author_name": "rrishabhporwal", "author_url": "", "post_date": "06/14/2019 07:47:34", "content": "Thanks for sharing!
", "votes": null, "replies": [] }, { "id": 552767, "author_name": "junhoning", "author_url": "", "post_date": "06/14/2019 13:58:55", "content": "Awesome codes!! Thank you :)
", "votes": null, "replies": [] }, { "id": 552829, "author_name": "rhhridoy", "author_url": "", "post_date": "06/14/2019 15:58:53", "content": "Thanks! Keep it up.
", "votes": null, "replies": [] }, { "id": 553688, "author_name": "arjun21", "author_url": "", "post_date": "06/16/2019 06:28:01", "content": "Congrats! and also thanks a lot for sharing this
", "votes": null, "replies": [] }, { "id": 553775, "author_name": "haradataman", "author_url": "", "post_date": "06/16/2019 09:53:02", "content": "Congrats! Thank you for sharing your detailed descriptions and awesome codes !
", "votes": null, "replies": [] }, { "id": 556784, "author_name": "ksajan12", "author_url": "", "post_date": "06/20/2019 16:38:30", "content": "Thanks for the heads up.
", "votes": null, "replies": [] }, { "id": 567841, "author_name": "wordbe", "author_url": "", "post_date": "07/04/2019 04:36:52", "content": "Thank you for sharing
", "votes": null, "replies": [] }, { "id": 614614, "author_name": "zecach", "author_url": "", "post_date": "08/31/2019 19:04:12", "content": "Congratulations for the 1st place!\nThank you for sharing.
", "votes": null, "replies": [] }, { "id": 623510, "author_name": "marcovasquez", "author_url": "", "post_date": "09/11/2019 03:26:40", "content": "AMAZING WORK. thanks for sharing
", "votes": null, "replies": [] }, { "id": 626271, "author_name": "bopengiowa", "author_url": "", "post_date": "09/14/2019 05:27:00", "content": "@amiras How do you do ensembling? For example what if one model predict an object but another model don't?
\n\nThanks.
", "votes": null, "replies": [ { "id": 626701, "author_name": "amiras", "author_url": "", "post_date": "09/14/2019 17:40:53", "content": "The ensemble is made using the nms algorithm. In the simple case, let one algorithm predict bboxes1, the second algorithm predict bboxes2. Next, we concatenate these answers and get bboxes = bboxes1 + bboxes2. Next we apply the nms algorithm. As a result, we get the ensemble_bboxes = nms(bboxes). For a more detailed information, see the scheme and the code.
Great job! Thanks for sharing.
", "votes": null, "replies": [] } ], "raw_markdown_by_id": { "549786": "Hi Kagglers,\n\nMy solution is based on the COCO challenge 2018 winners article: https://arxiv.org/abs/1901.07518. \n\n# Code: \nhttps://github.com/amirassov/kaggle-imaterialist\n\n# Model: \n[Hybrid Task Cascade with ResNeXt-101-64x4d-FPN backbone](https://github.com/open-mmlab/mmdetection/blob/master/configs/htc/htc_dconv_c3-c5_mstrain_400_1400_x101_64x4d_fpn_20e.py). This model has a metric Mask mAP = 43.9 on COCO dataset. This is SOTA for instance segmentation.\n\n# Validation:\nFor validation, I used 450 training samples splitted using https://github.com/trent-b/iterative-stratification.\n\n# Preprocessing:\nI applied light augmentatios from the [albumentations](https://github.com/albu/albumentations) library to the original image. Then I use multi-scale training: in each iteration, the scale of short edge is randomly sampled\nfrom [600, 1200], and the scale of long edge is fixed as 1900.\n\n\n# Training details:\n* pre-train from COCO\n* optimizer: `SGD(lr=0.03, momentum=0.9, weight_decay=0.0001)`\n* batch_size: 16 = 2 images per gpu x 8 gpus Tesla V100\n* learning rate scheduler:\n```if iterations < 500:\n lr = warmup(warmup_ratio=1 / 3)\nif epochs == 10:\n lr = lr ∗ 0.1\nif epochs == 18:\n lr = lr ∗ 0.1\nif epochs > 20:\n stop```\n* training time: ~3 days.\n\n# Parameter tuning:\nAfter the 12th epoch with the default parameters, the metric on LB was **0.21913**. Next, I tuned postprocessing thresholds using validation data:\n* `score_thr=0.5`\n* `nms={type: 'nms', iou_thr: 0.3}`\n* `max_per_img=100`\n* `mask_thr_binary=0.45`\n\nThis improved the metric on LB: **0.21913 -> 0.30011.**\n\n# Test time augmentation:\nI use 3 scales as well as horizontal flip at test time and ensemble the results. Testing scales are (1000, 1600), (1200, 1900), (1400, 2200). \n\nI drew a TTA scheme for Mask R-CNN, which is implemented in mmdetection library. For Hybrid Task Cascade R-CNN, I rewrote this code. \n\nThis improved the metric on LB: **0.30011 -> 0.31074.**\n\n\n# Ensemble:\nI ensemble the 3 best checkpoints of my model. The ensemble scheme is similar to TTA. \n\nThis improved the metric on LB: **0.31074 -> 0.31626.**\n\n\n# Attributes:\nI didn't use attributes at all: they were difficult to predict and the removal of classes with attributes greatly improved the metric. \n\nDuring the whole competition, I deleted classes with attributes: `{0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}` U `{27, 28, 33}`. But two days before the end I read [the discussion] (https://www.kaggle.com/c/imaterialist-fashion-2019-FGVC6/discussion/94811#latest548137) and added back classes `{27, 28, 33 }`. \n\nThis improved the metric on LB: **0.31626 -> 0.33511.**\n\n# Postprocessing for masks\nMy post-processing algorithm for avoid intersections of masks of the same class:\n```def hard_overlaps_suppression(binary_mask, scores):\n not_overlap_mask = []\n for i in np.argsort(scores)[::-1]:\n current_mask = binary_mask[..., i].copy()\n for mask in not_overlap_mask:\n current_mask = np.bitwise_and(current_mask, np.invert(mask))\n not_overlap_mask.append(current_mask)\n return np.stack(not_overlap_mask, -1)```\n\n# Small postprocessing:\nI deleted objects with an area of less than 20 pixels. \n\nThis improved the metric on LB: **0.33511 -> 0.33621.**", "549788": "Wow, I was so close..... I had exactly the same pipeline as yours, except the part of nms threshold....", "549798": "Setting: \n* `score_thr=0.5`\n* `nms={type: 'nms', iou_thr: 0.3}`\n* `max_per_img=100`\n* `mask_thr_binary=0.45`\n\nSeriously improves from 0.21913 to 0.30011? That was ... incredible.\nI only tried tuning the score_thr, and the improvement is only around 0.02\n\nHave you tried Soft-NMS? lowering the nms threshold seems to have a similar goal on preserving more proposals.\n\nThanks for the sharing, and big congrats !", "549799": "Many thanks for sharing your solutions. Looking forward to your source code! Congratulations! :-)", "549808": "This setting also adds little to my score.", "549823": "Soft-nms increased my score by like 0.0001....", "549824": "Thank you for your sharing!", "549827": "I think it depends on the post-processing algorithm to avoid intersections of masks of the same class.\n\nBy default, `score_threshold = 0.001.` My post-processing algorithm for masks did not delete the masks. The result was a lot of masks with small scores. This greatly degraded the metric.\nI added this algorithm to the solution description.\n\n\nSoft-nms didn't increase my score.", "549844": "Looking forward to seeing your code!", "549873": "Congratulations :) Looking forward to your code. Thank you very much.", "549882": "Thanks!", "549923": "Congratulations with 1st and Competitions Master!\nLooking forward to your code!\nThank you very much!", "549936": "TOP!", "549975": "Congratulations and thank you for your sharings!", "549986": "Pretty good! Waiting for the code!", "550002": "Good job)", "550102": "Thank you!", "550116": "Thanks", "550160": "Congratulations.\n\nIt seems that discarding classes with attributes is the key to win a gold.\nBy simply removing ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12}, we could get 0.31662/0.30403 .\n\nAccording to https://github.com/visipedia/imat_comp, there are 10K images with both segmentation and fine-grained attributes. We have 6696 in train, so probably all of the test data are with fine-grained attributes.\n\nIt was close...", "550168": "Congratulations and thanks for sharing!", "550495": "Thank you for sharing the details", "550552": "Awesome!", "550755": "Hi @amiras Thank you for sharing your solution! Will you attend CVPR2019 this year? [Schedule of our upcoming FGVC workshop can be found here](https://sites.google.com/view/fgvc6/program?authuser=0).\n\nAs one of top 3 teams, you are invited to present your solution in our upcoming FGVC workshop at CVPR.\n\n1. Could you be able to send me 1-2 pages of google slides (or pdf) describing your method? So I can include it in my presentation of this challenge.\n2. You will also have access to a 4 foot x 4 foot poster board in our FGVC workshop if you want to present your method at the workshop. (If you couldn't make it to the workshop, another option is that you can send your poster to me before June 14. I can help you print it and hang in the board that day)\n\nThank you!", "550887": "Congrats!Thank you for sharing the details.", "551038": "Congratulations :) Looking forward to seeing your code!", "551098": "Thank you for sharing!", "551973": "If a line's classid is 3 4 7 8 10 11 45, you means to delete this line or just remove the attribute?", "552021": "I just deleted the lines.\n\nActually, I think the instruction of LB evaluation metric might be incorrect.\n> The score returned by the competition metric is the mean taken over the individual average precisions of each image and each ClassId in the test dataset.\n\nHow many ClassIds do we have? It's 46 * (2^92). In train, it is 6371. Taking an average over ClassIds would be...\n\nHere is my guess. The metric used might be a mean taken over the average precision of each image. And for each image, an overall AP is calculated. There is no ClassId in {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} in the test set, so all those predictions would be FP.", "552092": "Thank you for sharing,when I remvoe it, I get 0.31802 / 0.33214 , I am a loser of this game.", "552482": "thanks for sharing", "552612": "Thanks for sharing!", "552767": "Awesome codes!! Thank you :)", "552829": "Thanks! Keep it up.", "553688": "Congrats! and also thanks a lot for sharing this", "553775": "Congrats! Thank you for sharing your detailed descriptions and awesome codes !", "556784": "Thanks for the heads up.", "567841": "Thank you for sharing", "614614": "Congratulations for the 1st place!\nThank you for sharing.", "623510": "AMAZING WORK. thanks for sharing", "626271": "amiras How do you do ensembling? For example what if one model predict an object but another model don't?\n\nThanks.", "626701": "The ensemble is made using the nms algorithm. In the simple case, let one algorithm predict bboxes1, the second algorithm predict bboxes2. Next, we concatenate these answers and get bboxes = bboxes1 + bboxes2. Next we apply the nms algorithm. As a result, we get the ensemble_bboxes = nms(bboxes). For a more detailed information, see the scheme  and the code.", "786868": "Great job! Thanks for sharing.", "815119": "Hi so how do you predict ClassIds {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12} if you delete all lines with this class and thus dont train on it? Those are the very basic classes that are the biggest part of the dataset.", "2454079": "What a great work!" }, "source": "meta" }