\n

A thank you to the host, and well done to all the participants. I'm frustrated that I couldn't stay in the gold tier, but I gained valuable learning experiences. I'd like to take this opportunity to express my gratitude. Although it's late, I will share my solution. My English isn't so good so feel free to ask me if there is anything unclear.
\nMy solution is:
\nI tried training LSTM and Transformers, but it didn't go well, so I abandoned them early, which led to my failure.
\nI used an ensemble of eight GraphNet-based models on final submit. A single graph model get Public 0.982 and Private 0.984 scores. Therefore, there may not have been much of an ensemble effect.
\n
Noise reduction from training data
\nI consider when the data had few observed signals within an event, it couldn't fit well and led to overfitting. So, I implemented the following cycle:
\n1) Infer to training data and exclude training data that do not predict well. Specifically, exclude data with MAE > 1.
\n2) Train on the dataset, and if the validation score improves, use that model to infer the training data again.
\n3) Construct the data set in the same manner as step 1, exclude the training data that cannot be fitted, and train again.
The above process was repeated two or three times.
\nThis idea is based on my past experience with overfitting with noisy labels, as in the PANDA competition. I think this competition deals with physical phenomena, prediction is relatively easy given ideal observational data. Therefore, I considered a model trained include data like noise would not correctly predict difficult events on test data, too. In fact, the model trained with the noisy data was able to improve the CV. Public LB also improved as did CV, so I trusts this method.
\nCustomized GraphNet-based models
\nI created models based on provided by the host, I also created models that include time variables in the information added to the KNN. And, changed the number of KNN neighborhoods (8 to 32) and pooling layers(replacing pooling to attention). I also tried other things such as changing the activation function, but the zero gradient function in the negative region does not seem to be a good. PReLU was the best, in my case.
My Failure Points
\nOthers
\nA thank you to the host, and well done to all the participants. I'm frustrated that I couldn't stay in the gold tier, but I gained valuable learning experiences. I'd like to take this opportunity to express my gratitude. Although it's late, I will share my solution. My English isn't so good so feel free to ask me if there is anything unclear.
\nMy solution is:
\nI tried training LSTM and Transformers, but it didn't go well, so I abandoned them early, which led to my failure.
\nI used an ensemble of eight GraphNet-based models on final submit. A single graph model get Public 0.982 and Private 0.984 scores. Therefore, there may not have been much of an ensemble effect.
\n
Noise reduction from training data
\nI consider when the data had few observed signals within an event, it couldn't fit well and led to overfitting. So, I implemented the following cycle:
\n1) Infer to training data and exclude training data that do not predict well. Specifically, exclude data with MAE > 1.
\n2) Train on the dataset, and if the validation score improves, use that model to infer the training data again.
\n3) Construct the data set in the same manner as step 1, exclude the training data that cannot be fitted, and train again.
The above process was repeated two or three times.
\nThis idea is based on my past experience with overfitting with noisy labels, as in the PANDA competition. I think this competition deals with physical phenomena, prediction is relatively easy given ideal observational data. Therefore, I considered a model trained include data like noise would not correctly predict difficult events on test data, too. In fact, the model trained with the noisy data was able to improve the CV. Public LB also improved as did CV, so I trusts this method.
\nCustomized GraphNet-based models
\nI created models based on provided by the host, I also created models that include time variables in the information added to the KNN. And, changed the number of KNN neighborhoods (8 to 32) and pooling layers(replacing pooling to attention). I also tried other things such as changing the activation function, but the zero gradient function in the negative region does not seem to be a good. PReLU was the best, in my case.
My Failure Points
\nOthers
\n@sinpcw thank you for the topic. Very interesting reading. And very good that you write about failure points. It is good information for beginners.
", "rawMarkdown": "sinpcw thank you for the topic. Very interesting reading. And very good that you write about failure points. It is good information for beginners.", "votes": null }, { "id": "2239181", "postDate": "04/29/2023 08:30:49", "content": "Thanks for sharing this topic. This will be helpful for beginners who are just starting out.
", "rawMarkdown": "Thanks for sharing this topic. This will be helpful for beginners who are just starting out.", "votes": null } ], "comments": [ { "id": 2238320, "author_name": "serangu", "author_url": "", "post_date": "04/28/2023 12:16:17", "content": "@sinpcw thank you for the topic. Very interesting reading. And very good that you write about failure points. It is good information for beginners.
", "votes": null, "replies": [] }, { "id": 2239181, "author_name": "ericka42", "author_url": "", "post_date": "04/29/2023 08:30:49", "content": "Thanks for sharing this topic. This will be helpful for beginners who are just starting out.
", "votes": null, "replies": [] } ], "raw_markdown_by_id": { "2238236": "A thank you to the host, and well done to all the participants. I'm frustrated that I couldn't stay in the gold tier, but I gained valuable learning experiences. I'd like to take this opportunity to express my gratitude. Although it's late, I will share my solution. My English isn't so good so feel free to ask me if there is anything unclear.\n\nMy solution is:\n- Noise reduction from training data\n- Customized GraphNet-based models\n\nI tried training LSTM and Transformers, but it didn't go well, so I abandoned them early, which led to my failure.\n\nI used an ensemble of eight GraphNet-based models on final submit. A single graph model get Public 0.982 and Private 0.984 scores. Therefore, there may not have been much of an ensemble effect.\n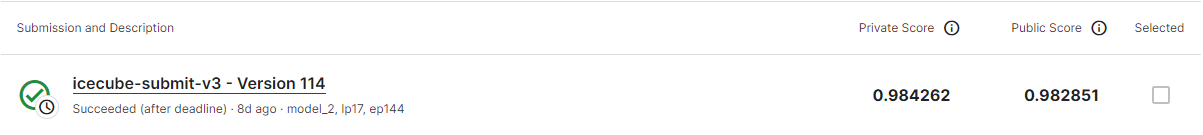\n\n\n**Noise reduction from training data**\nI consider when the data had few observed signals within an event, it couldn't fit well and led to overfitting. So, I implemented the following cycle:\n1) Infer to training data and exclude training data that do not predict well. Specifically, exclude data with MAE > 1.\n2) Train on the dataset, and if the validation score improves, use that model to infer the training data again.\n3) Construct the data set in the same manner as step 1, exclude the training data that cannot be fitted, and train again.\n\nThe above process was repeated two or three times.\n\nThis idea is based on my past experience with overfitting with noisy labels, as in the PANDA competition. I think this competition deals with physical phenomena, prediction is relatively easy given ideal observational data. Therefore, I considered a model trained include data like noise would not correctly predict difficult events on test data, too. In fact, the model trained with the noisy data was able to improve the CV. Public LB also improved as did CV, so I trusts this method.\n\n**Customized GraphNet-based models**\nI created models based on provided by the host, I also created models that include time variables in the information added to the KNN. And, changed the number of KNN neighborhoods (8 to 32) and pooling layers(replacing pooling to attention). I also tried other things such as changing the activation function, but the zero gradient function in the negative region does not seem to be a good. PReLU was the best, in my case.\n\n**My Failure Points**\n- Other information\nTried to include information on QE, etc., but could not pursue it very deeply, especially since GNN did not seem to improve.\n- Other approach\nI could not train LSTM and Transformer well. It is possible that the inputs and settings were incorrect, but the biggest failure was to terminate this approach prematurely.\n- post-process\nAttempted post-processing in the classification task to deal with cases where the exact opposite direction was obtained, but it did not work. \n- Interpolation\nSince the accuracy was poor for events with few observed signals, I looked for ways to improve the accuracy by interpolating signals at intermediate times and intermediate locations, but this did not work.\n- Imaging Idea\nTried to create an ensemble factor by predicting the position and orientation of the sensor as a video/imaging task, but it did not work because the number of events was too large (storage was disk full). I should have focused on something else.\n\n**Others**\n- [inference notebook](https://www.kaggle.com/code/sinpcw/icecube-submit) (version 111 is best LB.)", "2238320": "sinpcw thank you for the topic. Very interesting reading. And very good that you write about failure points. It is good information for beginners.", "2239181": "Thanks for sharing this topic. This will be helpful for beginners who are just starting out." }, "source": "meta" }