{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"name":"python","version":"3.10.13","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"},"kaggle":{"accelerator":"none","dataSources":[{"sourceId":59093,"databundleVersionId":7469972,"sourceType":"competition"},{"sourceId":7655089,"sourceType":"datasetVersion","datasetId":4463022},{"sourceId":7824772,"sourceType":"datasetVersion","datasetId":4585029}],"dockerImageVersionId":30648,"isInternetEnabled":false,"language":"python","sourceType":"notebook","isGpuEnabled":false}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# [CV 0.68 | LB 0.46] DilatedInception WaveNet in PyTorch - Inference\n\n## Introduction\nAfter joining this competition, I focus on validating how far raw EEG signals can go through many experiments. Finally, I find an simple architecture mixing the concept of **dilation** and **inception**, which can be seen as an extension of [Chris' version](https://www.kaggle.com/code/cdeotte/wavenet-starter-lb-0-52). And, I'm happy to announce that we can achieve CV 0.68 (below 0.7) and LB 0.46 with this architecture. Don't forget to upvote Chris' notebook!\n\n## About this Notebook\nIn this kernel, I run the inference process with 5-fold models (equally-weighted blending) and obtain LB 0.46. If you're also interested in training part, pleasse see [[LB 0.46] DilatedInception WaveNet - Training](https://www.kaggle.com/code/abaojiang/lb-0-46-dilatedinception-wavenet-training).\n\n## Acknowledgements\nSpecial thanks to [@cdeotte](https://www.kaggle.com/cdeotte)'s sharing, [WaveNet Starter - [LB 0.52]](https://www.kaggle.com/code/cdeotte/wavenet-starter-lb-0-52).\n\n\n## Table of Contents\n* [1. Load Data](#load_data)\n* [2. Define Dataset](#dataset)\n* [3. Create Test Loader](#test_loader)\n* [4. Define Model Architecture](#model)\n* [5. Load Models](#load_models)\n* [6. Run Inference](#infer)\n* [7. Submission](#sub)\n\n## Import Packages","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19"}},{"cell_type":"code","source":"import gc\nimport os\nfrom typing import Any, Dict, List, Optional, Tuple, Type, Union\nimport pickle\nimport warnings\nfrom pathlib import Path\nfrom tqdm.notebook import tqdm\nwarnings.simplefilter(\"ignore\")\n\nimport numpy as np\nimport pandas as pd\nimport yaml\nfrom scipy.signal import butter, lfilter\n\nimport torch\nimport torch.nn as nn\nimport torch.nn.functional as F\nfrom torch import Tensor\nfrom torch.utils.data import Dataset, DataLoader","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:51.641350Z","iopub.execute_input":"2024-03-13T23:42:51.641792Z","iopub.status.idle":"2024-03-13T23:42:56.671846Z","shell.execute_reply.started":"2024-03-13T23:42:51.641760Z","shell.execute_reply":"2024-03-13T23:42:56.670847Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Define Data Paths and Configuration and Metadata","metadata":{}},{"cell_type":"code","source":"DATA_PATH = Path(\"/kaggle/input/hms-harmful-brain-activity-classification\")\n\nclass CFG:\n exp_id = \"0311-17-20-55\"\n model_path = Path(\"/kaggle/input/dilated-wavenet/0311-17-20-55\")\n device = torch.device(\"cuda:0\" if torch.cuda.is_available() else \"cpu\")\n \n # == Data ==\n # Chris' 8 channels\n feats = [\n \"Fp1\", \"T3\", \"C3\", \"O1\",\n \"Fp2\", \"C4\", \"T4\", \"O2\"\n ]\n cast_eegs = True\n dataset = {\n \"eeg\": {\n \"n_feats\": 8,\n \"apply_chris_magic_ch8\": True,\n \"normalize\": True,\n \"apply_butter_lowpass_filter\": True,\n \"apply_mu_law_encoding\": False,\n \"downsample\": 5\n }\n }\n \n # == Data Loader ==\n batch_size = 32\n \n \nN_CLASSES = 6\nTGT_VOTE_COLS = [\n \"seizure_vote\", \"lpd_vote\", \"gpd_vote\", \"lrda_vote\",\n \"grda_vote\", \"other_vote\"\n]\nEEG_FREQ = 200 # Hz\nEEG_WLEN = 50 # sec\nEEG_PTS = int(EEG_FREQ * EEG_WLEN)","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:56.673661Z","iopub.execute_input":"2024-03-13T23:42:56.674081Z","iopub.status.idle":"2024-03-13T23:42:56.681908Z","shell.execute_reply.started":"2024-03-13T23:42:56.674055Z","shell.execute_reply":"2024-03-13T23:42:56.680154Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 1. Load Data\n[**Go to Table of Content**](#toc)\n\nNote test data will be replaced with **hidden test set** during rerun.","metadata":{}},{"cell_type":"code","source":"def _get_eeg_window(file: Path) -> np.ndarray:\n \"\"\"Return cropped EEG window.\n\n Default setting is to return the middle 50-sec window.\n\n Args:\n file: EEG file path\n test: if True, there's no need to truncate EEGs\n\n Returns:\n eeg_win: cropped EEG window \n \"\"\"\n eeg = pd.read_parquet(file, columns=CFG.feats)\n n_pts = len(eeg)\n offset = (n_pts - EEG_PTS) // 2\n eeg = eeg.iloc[offset:offset + EEG_PTS]\n \n eeg_win = np.zeros((EEG_PTS, len(CFG.feats)))\n for j, col in enumerate(CFG.feats):\n if CFG.cast_eegs:\n eeg_raw = eeg[col].values.astype(\"float32\")\n else:\n eeg_raw = eeg[col].values \n\n # Fill missing values\n mean = np.nanmean(eeg_raw)\n if np.isnan(eeg_raw).mean() < 1:\n eeg_raw = np.nan_to_num(eeg_raw, nan=mean)\n else: \n # All missing\n eeg_raw[:] = 0\n eeg_win[:, j] = eeg_raw \n \n return eeg_win ","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-03-13T23:42:56.683699Z","iopub.execute_input":"2024-03-13T23:42:56.684623Z","iopub.status.idle":"2024-03-13T23:42:56.714742Z","shell.execute_reply.started":"2024-03-13T23:42:56.684591Z","shell.execute_reply":"2024-03-13T23:42:56.713753Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test = pd.read_csv(DATA_PATH / \"test.csv\")\nprint(f\"Test data shape | {test.shape}\")","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:56.717353Z","iopub.execute_input":"2024-03-13T23:42:56.717758Z","iopub.status.idle":"2024-03-13T23:42:56.746798Z","shell.execute_reply.started":"2024-03-13T23:42:56.717735Z","shell.execute_reply":"2024-03-13T23:42:56.745801Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"uniq_eeg_ids = test[\"eeg_id\"].unique()\nn_uniq_eeg_ids = len(uniq_eeg_ids)\n\nall_eegs = {}\nfor i, eeg_id in tqdm(enumerate(uniq_eeg_ids), total=n_uniq_eeg_ids):\n eeg_win = _get_eeg_window(DATA_PATH / \"test_eegs\" / f\"{eeg_id}.parquet\")\n all_eegs[eeg_id] = eeg_win\n\nprint(f\"Demo EEG shape | {list(all_eegs.values())[0].shape}\")","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:56.748199Z","iopub.execute_input":"2024-03-13T23:42:56.748860Z","iopub.status.idle":"2024-03-13T23:42:56.918825Z","shell.execute_reply.started":"2024-03-13T23:42:56.748825Z","shell.execute_reply":"2024-03-13T23:42:56.918150Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 2. Define Dataset\n[**Go to Table of Content**](#toc)","metadata":{}},{"cell_type":"code","source":"class _EEGTransformer(object):\n \"\"\"Data transformer for raw EEG signals.\"\"\"\n\n FEAT2CODE = {f: i for i, f in enumerate(CFG.feats)}\n\n def __init__(\n self,\n n_feats: int,\n apply_chris_magic_ch8: bool = True,\n normalize: bool = True,\n apply_butter_lowpass_filter: bool = True,\n apply_mu_law_encoding: bool = False,\n downsample: Optional[int] = None,\n ) -> None:\n self.n_feats = n_feats\n self.apply_chris_magic_ch8 = apply_chris_magic_ch8\n self.normalize = normalize\n self.apply_butter_lowpass_filter = apply_butter_lowpass_filter\n self.apply_mu_law_encoding = apply_mu_law_encoding\n self.downsample = downsample\n\n def transform(self, x: np.ndarray) -> np.ndarray:\n \"\"\"Apply transformation on raw EEG signals.\n \n Args:\n x: raw EEG signals, with shape (L, C)\n\n Return:\n x_: transformed EEG signals\n \"\"\"\n x_ = x.copy()\n if self.apply_chris_magic_ch8:\n x_ = self._apply_chris_magic_ch8(x_)\n\n if self.normalize:\n x_ = np.clip(x_, -1024, 1024)\n x_ = np.nan_to_num(x_, nan=0) / 32.0\n\n if self.apply_butter_lowpass_filter:\n x_ = self._butter_lowpass_filter(x_) \n\n if self.apply_mu_law_encoding:\n x_ = self._quantize_data(x_, 1)\n\n if self.downsample is not None:\n x_ = x_[::self.downsample, :]\n\n return x_\n\n def _apply_chris_magic_ch8(self, x: np.ndarray) -> np.ndarray:\n \"\"\"Generate features based on Chris' magic formula.\"\"\" \n x_tmp = np.zeros((EEG_PTS, self.n_feats), dtype=\"float32\")\n\n # Generate features\n x_tmp[:, 0] = x[:, self.FEAT2CODE[\"Fp1\"]] - x[:, self.FEAT2CODE[\"T3\"]]\n x_tmp[:, 1] = x[:, self.FEAT2CODE[\"T3\"]] - x[:, self.FEAT2CODE[\"O1\"]]\n \n x_tmp[:, 2] = x[:, self.FEAT2CODE[\"Fp1\"]] - x[:, self.FEAT2CODE[\"C3\"]]\n x_tmp[:, 3] = x[:, self.FEAT2CODE[\"C3\"]] - x[:, self.FEAT2CODE[\"O1\"]]\n \n x_tmp[:, 4] = x[:, self.FEAT2CODE[\"Fp2\"]] - x[:, self.FEAT2CODE[\"C4\"]]\n x_tmp[:, 5] = x[:, self.FEAT2CODE[\"C4\"]] - x[:, self.FEAT2CODE[\"O2\"]]\n \n x_tmp[:, 6] = x[:, self.FEAT2CODE[\"Fp2\"]] - x[:, self.FEAT2CODE[\"T4\"]]\n x_tmp[:, 7] = x[:, self.FEAT2CODE[\"T4\"]] - x[:, self.FEAT2CODE[\"O2\"]]\n\n return x_tmp\n\n def _butter_lowpass_filter(self, data, cutoff_freq=20, sampling_rate=200, order=4):\n nyquist = 0.5 * sampling_rate\n normal_cutoff = cutoff_freq / nyquist\n b, a = butter(order, normal_cutoff, btype=\"low\", analog=False)\n filtered_data = lfilter(b, a, data, axis=0)\n\n return filtered_data\n \n def _quantize_data(self, data, classes):\n mu_x = self._mu_law_encoding(data, classes)\n \n return mu_x\n\n def _mu_law_encoding(self, data, mu):\n mu_x = np.sign(data) * np.log(1 + mu * np.abs(data)) / np.log(mu + 1)\n\n return mu_x","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-03-13T23:42:56.919816Z","iopub.execute_input":"2024-03-13T23:42:56.920390Z","iopub.status.idle":"2024-03-13T23:42:56.933168Z","shell.execute_reply.started":"2024-03-13T23:42:56.920368Z","shell.execute_reply":"2024-03-13T23:42:56.932534Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"class EEGDataset(Dataset):\n \"\"\"Dataset for pure raw EEG signals.\n\n Args:\n data: processed data\n split: data split\n\n Attributes:\n _n_samples: number of samples\n _infer: if True, the dataset is constructed for inference\n *Note: Ground truth is not provided.\n \"\"\"\n\n def __init__(\n self,\n data: Dict[str, Any],\n split: str,\n **dataset_cfg: Any,\n ) -> None:\n self.metadata = data[\"meta\"]\n self.all_eegs = data[\"eeg\"]\n self.dataset_cfg = dataset_cfg\n\n # Raw EEG data transformer\n self.eeg_params = dataset_cfg[\"eeg\"]\n self.eeg_trafo = _EEGTransformer(**self.eeg_params)\n\n self._set_n_samples()\n self._infer = True if split == \"test\" else False\n\n self._stream_X = True if self.all_eegs is None else False\n self._X, self._y = self._transform()\n\n def _set_n_samples(self) -> None:\n assert len(self.metadata) == self.metadata[\"eeg_id\"].nunique()\n self._n_samples = len(self.metadata)\n\n def _transform(self) -> Tuple[Optional[np.ndarray], np.ndarray]:\n \"\"\"Transform feature and target matrices.\"\"\"\n if self.eeg_params[\"downsample\"] is not None:\n eeg_len = int(EEG_PTS / self.eeg_params[\"downsample\"])\n else:\n eeg_len = int(EEG_PTS)\n if not self._stream_X:\n X = np.zeros((self._n_samples, eeg_len, self.eeg_params[\"n_feats\"]), dtype=\"float32\")\n else:\n X = None\n y = np.zeros((self._n_samples, N_CLASSES), dtype=\"float32\") if not self._infer else None\n\n for i, row in tqdm(self.metadata.iterrows(), total=len(self.metadata)):\n # Process raw EEG signals\n if not self._stream_X:\n # Retrieve raw EEG signals\n eeg = self.all_eegs[row[\"eeg_id\"]]\n\n # Apply EEG transformer\n x = self.eeg_trafo.transform(eeg)\n\n X[i] = x\n\n if not self._infer:\n y[i] = row[TGT_VOTE_COLS] \n\n return X, y\n\n def __len__(self) -> int:\n return self._n_samples\n\n def __getitem__(self, idx: int) -> Dict[str, Tensor]:\n if self._X is None:\n # Load data here...\n# x = np.load(...)\n# x = self.eeg_trafo.transform(x)\n pass\n else:\n x = self._X[idx, ...]\n data_sample = {\"x\": torch.tensor(x, dtype=torch.float32)}\n if not self._infer:\n data_sample[\"y\"] = torch.tensor(self._y[idx, :], dtype=torch.float32)\n\n return data_sample","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:56.934212Z","iopub.execute_input":"2024-03-13T23:42:56.934440Z","iopub.status.idle":"2024-03-13T23:42:56.949767Z","shell.execute_reply.started":"2024-03-13T23:42:56.934420Z","shell.execute_reply":"2024-03-13T23:42:56.948662Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 3. Create Test Loader\n[**Go to Table of Content**](#toc)","metadata":{"execution":{"iopub.status.busy":"2024-02-19T09:45:33.011157Z","iopub.execute_input":"2024-02-19T09:45:33.011657Z","iopub.status.idle":"2024-02-19T09:45:33.017641Z","shell.execute_reply.started":"2024-02-19T09:45:33.011622Z","shell.execute_reply":"2024-02-19T09:45:33.016379Z"}}},{"cell_type":"code","source":"test_data = {\"meta\": test, \"eeg\": all_eegs}\ntest_loader = DataLoader(\n EEGDataset(test_data, \"test\", **CFG.dataset),\n batch_size=CFG.batch_size,\n shuffle=False,\n num_workers=0\n)\nprint(f\"There are {len(test_loader.dataset)} test samples to infer.\")","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:56.951261Z","iopub.execute_input":"2024-03-13T23:42:56.951763Z","iopub.status.idle":"2024-03-13T23:42:56.991634Z","shell.execute_reply.started":"2024-03-13T23:42:56.951738Z","shell.execute_reply":"2024-03-13T23:42:56.990749Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 4. Define Model Architecture\n[**Go to Table of Content**](#toc)\n\n[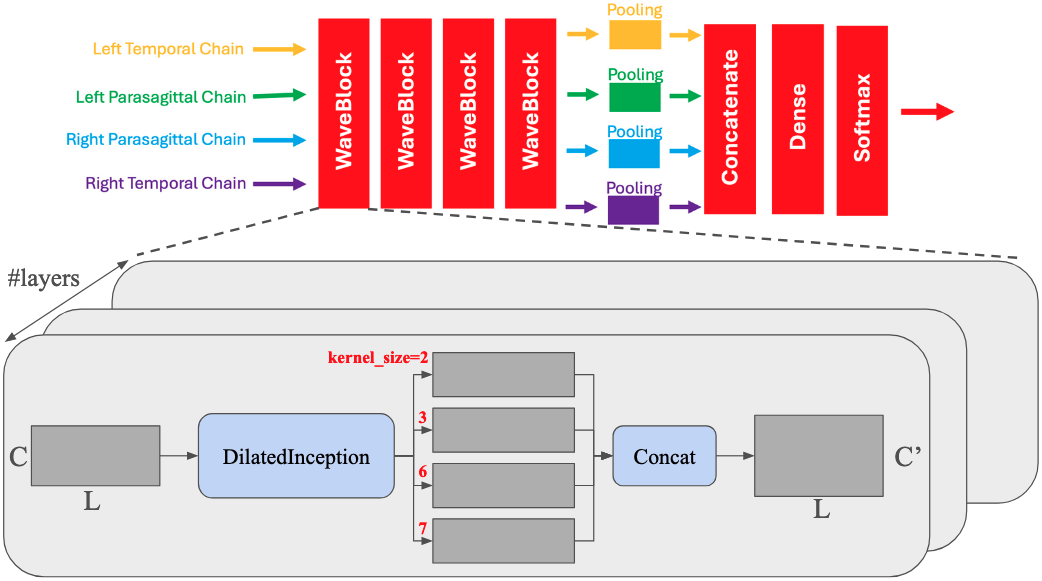](https://postimg.cc/7bdRnCBZ)","metadata":{}},{"cell_type":"code","source":"class _WaveBlock(nn.Module):\n \"\"\"WaveNet block.\n\n Args:\n kernel_size: kernel size, pass a list of kernel sizes for\n inception\n \"\"\"\n\n def __init__(\n self,\n n_layers: int, \n in_dim: int,\n h_dim: int,\n kernel_size: Union[int, List[int]],\n conv_module: Optional[Type[nn.Module]] = None,\n ) -> None:\n super().__init__()\n\n self.n_layers = n_layers\n self.dilation_rates = [2**l for l in range(n_layers)]\n\n self.in_conv = nn.Conv2d(in_dim, h_dim, kernel_size=(1, 1)) \n self.gated_tcns = nn.ModuleList()\n self.skip_convs = nn.ModuleList()\n for layer in range(n_layers):\n c_in, c_out = h_dim, h_dim\n self.gated_tcns.append(\n _GatedTCN(\n in_dim=c_in,\n h_dim=c_out,\n kernel_size=kernel_size,\n dilation_factor=self.dilation_rates[layer],\n conv_module=conv_module,\n )\n )\n self.skip_convs.append(nn.Conv2d(h_dim, h_dim, kernel_size=(1, 1)))\n\n # Initialize parameters\n nn.init.xavier_uniform_(self.in_conv.weight, gain=nn.init.calculate_gain(\"relu\"))\n nn.init.zeros_(self.in_conv.bias)\n for i in range(len(self.skip_convs)):\n nn.init.xavier_uniform_(self.skip_convs[i].weight, gain=nn.init.calculate_gain(\"relu\"))\n nn.init.zeros_(self.skip_convs[i].bias)\n\n def forward(self, x: Tensor) -> Tensor:\n \"\"\"Forward pass.\n \n Shape:\n x: (B, C, N, L), where C denotes in_dim\n x_skip: (B, C', N, L), where C' denotes h_dim\n \"\"\"\n # Input convolution\n x = self.in_conv(x)\n\n x_skip = x\n for layer in range(self.n_layers):\n x = self.gated_tcns[layer](x)\n x = self.skip_convs[layer](x)\n\n # Skip-connection\n x_skip = x_skip + x \n\n return x_skip\n\n\nclass _GatedTCN(nn.Module):\n \"\"\"Gated temporal convolution layer.\n\n Parameters:\n conv_module: customized convolution module\n \"\"\"\n\n def __init__(\n self,\n in_dim: int,\n h_dim: int,\n kernel_size: Union[int, List[int]],\n dilation_factor: int,\n dropout: Optional[float] = None,\n conv_module: Optional[Type[nn.Module]] = None,\n ) -> None:\n super().__init__()\n\n # Model blocks\n if conv_module is None:\n self.filt = nn.Conv2d(\n in_channels=in_dim, out_channels=h_dim, kernel_size=(1, kernel_size), dilation=dilation_factor\n )\n self.gate = nn.Conv2d(\n in_channels=in_dim, out_channels=h_dim, kernel_size=(1, kernel_size), dilation=dilation_factor\n )\n else:\n self.filt = conv_module(\n in_channels=in_dim, out_channels=h_dim, kernel_size=kernel_size, dilation=dilation_factor\n )\n self.gate = conv_module(\n in_channels=in_dim, out_channels=h_dim, kernel_size=kernel_size, dilation=dilation_factor\n )\n\n if dropout is not None:\n self.dropout = nn.Dropout(dropout)\n else:\n self.dropout = None\n\n def forward(self, x: Tensor) -> Tensor:\n \"\"\"Forward pass.\n\n Parameters:\n x: input sequence\n\n Return:\n h: output sequence\n\n Shape:\n x: (B, C, N, L), where L denotes the input sequence length\n h: (B, h_dim, N, L')\n \"\"\"\n x_filt = F.tanh(self.filt(x))\n x_gate = F.sigmoid(self.gate(x))\n h = x_filt * x_gate\n if self.dropout is not None:\n h = self.dropout(h)\n\n return h\n\n\nclass _DilatedInception(nn.Module):\n \"\"\"Dilated inception layer.\n\n Note that `out_channels` will be split across #kernels.\n \"\"\"\n\n def __init__(\n self, \n in_channels: int, \n out_channels: int, \n kernel_size: List[int], \n dilation: int\n ) -> None:\n super().__init__()\n\n # Network parameters\n n_kernels = len(kernel_size)\n assert out_channels % n_kernels == 0, \"`out_channels` must be divisible by #kernels.\"\n h_dim = out_channels // n_kernels\n\n # Model blocks\n self.convs = nn.ModuleList()\n for k in kernel_size:\n self.convs.append(\n nn.Conv2d(\n in_channels=in_channels, \n out_channels=h_dim, \n kernel_size=(1, k),\n padding=\"same\",\n dilation=dilation),\n )\n\n def forward(self, x: Tensor) -> Tensor:\n \"\"\"Forward pass.\n\n Parameters:\n x: input sequence\n\n Return:\n h: output sequence\n\n Shape:\n x: (B, C, N, L), where C = in_channels\n h: (B, C', N, L'), where C' = out_channels\n \"\"\"\n x_convs = []\n for conv in self.convs:\n x_conv = conv(x)\n x_convs.append(x_conv)\n h = torch.cat(x_convs, dim=1)\n\n return h","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-03-13T23:42:56.992760Z","iopub.execute_input":"2024-03-13T23:42:56.993649Z","iopub.status.idle":"2024-03-13T23:42:57.016840Z","shell.execute_reply.started":"2024-03-13T23:42:56.993617Z","shell.execute_reply":"2024-03-13T23:42:57.015770Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"class DilatedInceptionWaveNet(nn.Module):\n \"\"\"WaveNet architecture with dilated inception conv.\"\"\"\n\n def __init__(self,) -> None:\n super().__init__()\n\n kernel_size = [2, 3, 6, 7]\n\n # Model blocks \n self.wave_module = nn.Sequential(\n _WaveBlock(12, 1, 16, kernel_size, _DilatedInception),\n _WaveBlock(8, 16, 32, kernel_size, _DilatedInception),\n _WaveBlock(4, 32, 64, kernel_size, _DilatedInception),\n _WaveBlock(1, 64, 64, kernel_size, _DilatedInception),\n )\n self.output = nn.Sequential(\n nn.Linear(64 * 4, 64),\n nn.ReLU(),\n nn.Linear(64, N_CLASSES)\n ) \n\n def forward(self, inputs: Dict[str, Tensor]) -> Tensor:\n \"\"\"Forward pass.\n\n Shape:\n x: (B, L, C)\n \"\"\"\n x = inputs[\"x\"]\n bs, length, in_dim = x.shape\n x = x.transpose(1, 2).unsqueeze(dim=2) # (B, C, N, L), N is redundant\n\n x_ll_1 = self.wave_module(x[:, 0:1, :])\n x_ll_2 = self.wave_module(x[:, 1:2, :])\n x_ll = (F.adaptive_avg_pool2d(x_ll_1, (1, 1)) + F.adaptive_avg_pool2d(x_ll_2, (1, 1))) / 2\n\n x_rl_1 = self.wave_module(x[:, 2:3, :])\n x_rl_2 = self.wave_module(x[:, 3:4, :])\n x_rl = (F.adaptive_avg_pool2d(x_rl_1, (1, 1)) + F.adaptive_avg_pool2d(x_rl_2, (1, 1))) / 2\n\n x_lp_1 = self.wave_module(x[:, 4:5, :])\n x_lp_2 = self.wave_module(x[:, 5:6, :])\n x_lp = (F.adaptive_avg_pool2d(x_lp_1, (1, 1)) + F.adaptive_avg_pool2d(x_lp_2, (1, 1))) / 2\n\n x_rp_1 = self.wave_module(x[:, 6:7, :])\n x_rp_2 = self.wave_module(x[:, 7:8, :])\n x_rp = (F.adaptive_avg_pool2d(x_rp_1, (1, 1)) + F.adaptive_avg_pool2d(x_rp_2, (1, 1))) / 2\n\n x = torch.cat([x_ll, x_rl, x_lp, x_rp], axis=1).reshape(bs, -1)\n output = self.output(x)\n\n return output","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:57.019449Z","iopub.execute_input":"2024-03-13T23:42:57.019736Z","iopub.status.idle":"2024-03-13T23:42:57.033781Z","shell.execute_reply.started":"2024-03-13T23:42:57.019714Z","shell.execute_reply":"2024-03-13T23:42:57.033061Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 5. Load Models\n[**Go to Table of Content**](#toc)","metadata":{}},{"cell_type":"code","source":"models = []\nfor fold, file in enumerate(sorted(CFG.model_path.glob(\"./*.pth\"))):\n print(f\"Load model from {file}...\")\n fold_model = DilatedInceptionWaveNet()\n fold_model.load_state_dict(torch.load(file, map_location=CFG.device))\n fold_model = fold_model.to(CFG.device)\n models.append(fold_model)","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:57.034698Z","iopub.execute_input":"2024-03-13T23:42:57.034946Z","iopub.status.idle":"2024-03-13T23:42:58.200541Z","shell.execute_reply.started":"2024-03-13T23:42:57.034926Z","shell.execute_reply":"2024-03-13T23:42:58.199889Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 6. Run Inference\n[**Go to Table of Content**](#toc)","metadata":{}},{"cell_type":"code","source":"@torch.no_grad()\ndef _infer(inputs: Dict[str, Tensor], models: List[nn.Module]) -> Tensor:\n n_models = len(models)\n\n for i, model in enumerate(models):\n model.eval()\n y_pred_fold = F.softmax(model(inputs)) / n_models # (B, N_CLASSES)\n \n if i == 0:\n y_pred = y_pred_fold\n else:\n y_pred += y_pred_fold\n \n return y_pred","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-03-13T23:42:58.201413Z","iopub.execute_input":"2024-03-13T23:42:58.202190Z","iopub.status.idle":"2024-03-13T23:42:58.207689Z","shell.execute_reply.started":"2024-03-13T23:42:58.202166Z","shell.execute_reply":"2024-03-13T23:42:58.206721Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"y_preds = []\nfor i, batch_data in enumerate(test_loader):\n batch_data[\"x\"] = batch_data[\"x\"].to(CFG.device)\n y_pred = _infer(batch_data, models)\n y_preds.append(y_pred.detach().cpu().numpy())\ny_preds = np.vstack(y_preds)\nprint(f\"Sum of row 0 in y_preds {np.sum(y_preds[0, :])}.\")","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:42:58.208815Z","iopub.execute_input":"2024-03-13T23:42:58.209034Z","iopub.status.idle":"2024-03-13T23:43:02.143214Z","shell.execute_reply.started":"2024-03-13T23:42:58.209016Z","shell.execute_reply":"2024-03-13T23:43:02.142114Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"\n## 7. Submission\n[**Go to Table of Content**](#toc)","metadata":{}},{"cell_type":"code","source":"sub = pd.DataFrame({\"eeg_id\": test.eeg_id.values})\nsub[TGT_VOTE_COLS] = y_preds\nsub.to_csv(\"submission.csv\", index=False)\n\nprint(\"===== Submission Demo =====\")\nsub.head()","metadata":{"execution":{"iopub.status.busy":"2024-03-13T23:43:02.144323Z","iopub.execute_input":"2024-03-13T23:43:02.144582Z","iopub.status.idle":"2024-03-13T23:43:02.168818Z","shell.execute_reply.started":"2024-03-13T23:43:02.144546Z","shell.execute_reply":"2024-03-13T23:43:02.167510Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"","metadata":{},"execution_count":null,"outputs":[]}]}