{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"name":"python","version":"3.10.12","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"},"kaggle":{"accelerator":"gpu","dataSources":[{"sourceId":59093,"databundleVersionId":7469972,"sourceType":"competition"},{"sourceId":7392733,"sourceType":"datasetVersion","datasetId":4297749},{"sourceId":7465251,"sourceType":"datasetVersion","datasetId":4317718}],"dockerImageVersionId":30636,"isInternetEnabled":false,"language":"python","sourceType":"notebook","isGpuEnabled":true}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# | HMS: WaveNet [Train] \n\n***\n\nThis is the **PyTorch 🔥 version** of [Chris Deotte WaveNet Starter](https://www.kaggle.com/code/cdeotte/wavenet-starter-lb-0-52) give him an upvote too! ⬆️\n\nYour goal in this competition is to detect and classify seizures and other types of harmful brain activity. You will develop a model trained on electroencephalography (EEG) signals recorded from critically ill hospital patients.\n\nIn this notebook you will learn how to train a `WaveNet` model for seizures classification using PyTorch. Hope you enjoy it and find it useful.\n\nI also made a **PyTorch 🔥 version** of Chris' EfficientNetB0 notebook here:\n- [HMS | EfficientNetB0 PyTorch [Train]](https://www.kaggle.com/code/alejopaullier/hms-efficientnetb0-pytorch-train)\n- [HMS | EfficientNetB0 PyTorch [Inference]](https://www.kaggle.com/code/alejopaullier/hms-efficientnetb0-pytorch-inference)\n\n### Table of Contents \n\n\n\n# | Introduction [↑](#top) \n\n***\n\nThis model only uses two features. We can engineer more features and/or modify the model architecture to improve CV score and LB score. Furthermore we can build 1 model which inputs both spectrogram images and eeg waveforms. The two EEG features in this notebook are:\n- feature 1 : `Fp1 minus O1`\n- feature 2 : `Fp2 minus O2`\n\nFeature 1 is the beginning of the montage chains `LL` and `LP` minus the ending of montage `LL` and `LP`. And feature 2 is the beginning of the montage chains `RL` and `RP` minus the ending of montage `RL` and `RP`.\n\n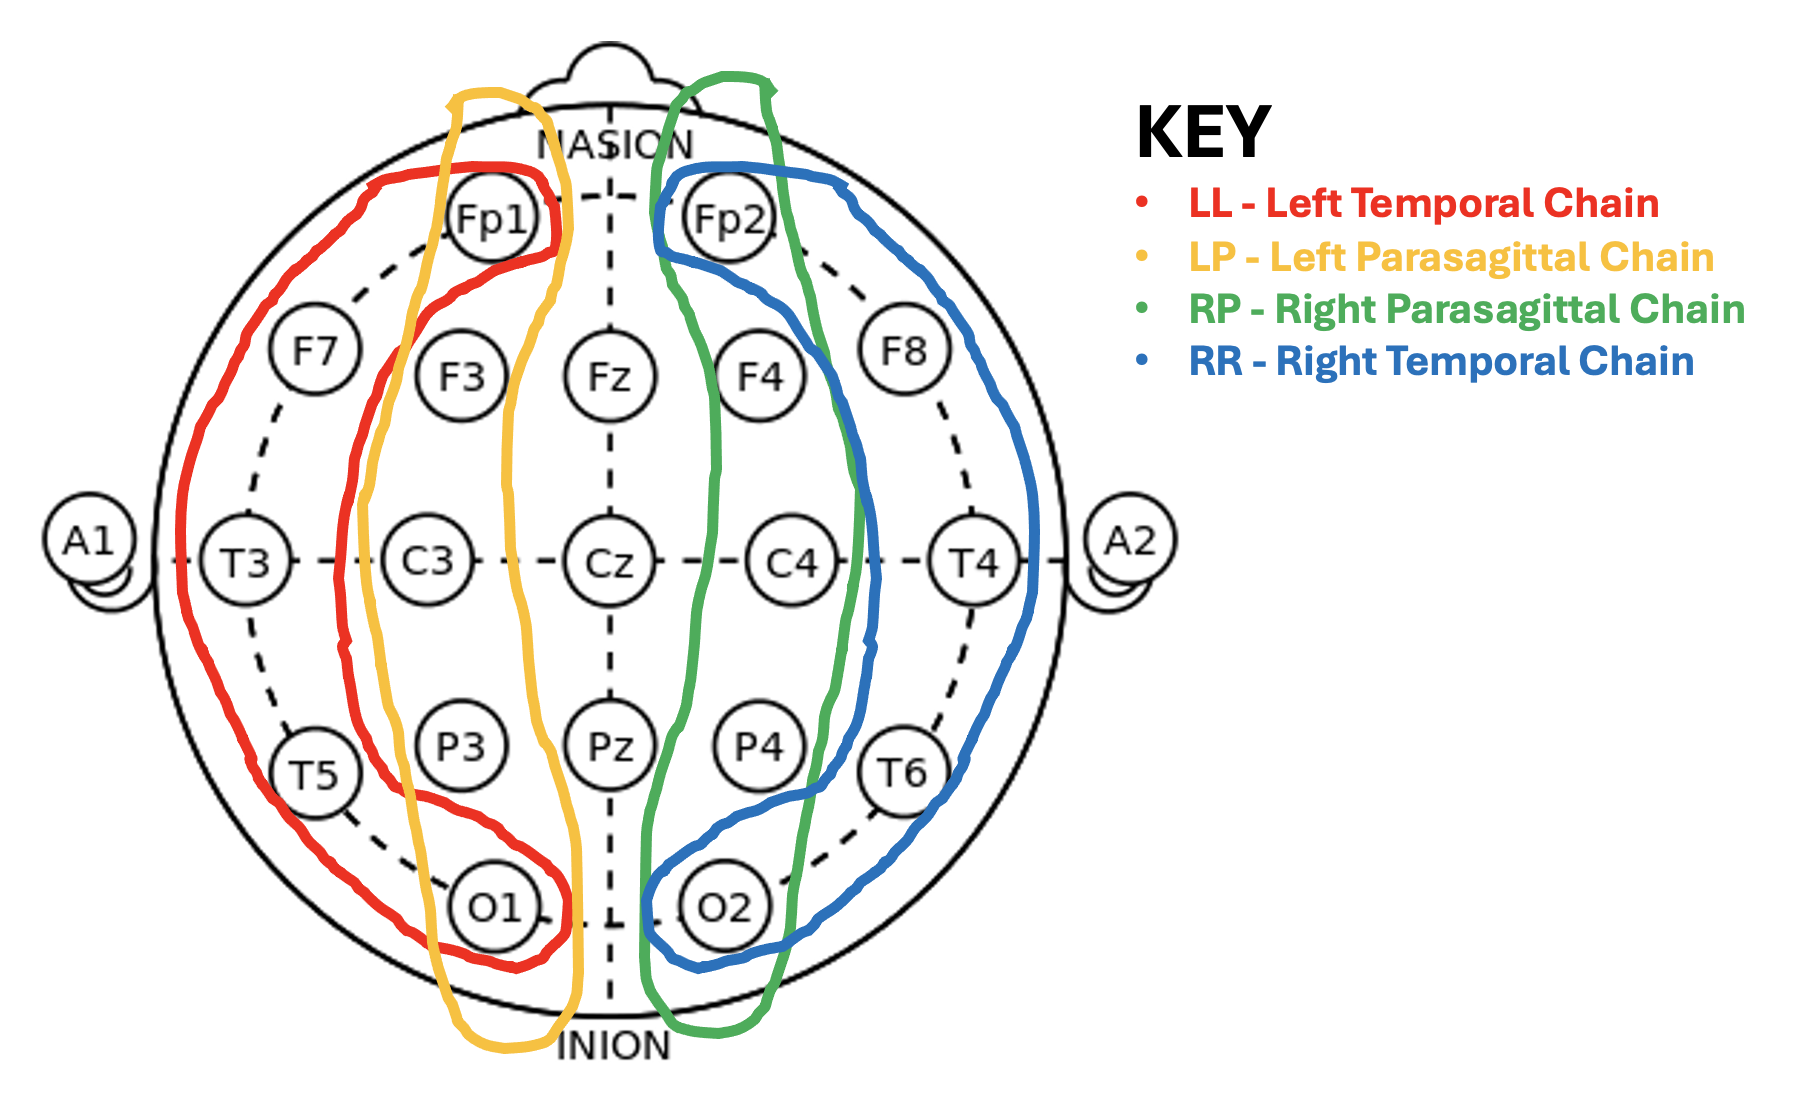 \n\nWe add more features and update the model architecture to evaluate each montage chain separately and then concatenate the features. This new architecture is motivated by the discovery of a better formula to utilize EEG explained in discussion [here][2]\n\n* Version 5,6: Use 2 features - CV 0.91 LB 0.66\n* Version 7,8: Use 8 features grouped as 4 chains. Downsample time 5x - **CV 0.81 LB 0.53**, wow!\n\nWe train our new model in version 7, then save model weights. Then load model into version 8 to submit to LB.\n\n
 \n\n[1]: https://www.kaggle.com/code/seshurajup/eda-train-csv\n[2]: https://www.kaggle.com/competitions/hms-harmful-brain-activity-classification/discussion/469760\n\n### Useful References\n\n- [Understand this competition's data](https://www.kaggle.com/competitions/hms-harmful-brain-activity-classification/discussion/468010)\n","metadata":{}},{"cell_type":"markdown","source":"# | Import Libraries [↑](#top) \n\n***\n\nImport all the required libraries for this notebook.","metadata":{}},{"cell_type":"code","source":"import gc\nimport math\nimport matplotlib.pyplot as plt\nimport multiprocessing\nimport numpy as np\nimport os\nimport pandas as pd\nimport random\nimport time\nimport torch\nimport torch.nn as nn\n\n\nfrom glob import glob\nfrom torch.utils.data import DataLoader, Dataset\nfrom tqdm import tqdm\nfrom typing import Dict, List\n\nos.environ[\"CUDA_VISIBLE_DEVICES\"] = \"0,1\"\ndevice = torch.device(\"cuda:0\" if torch.cuda.is_available() else \"cpu\")\nprint('Using', torch.cuda.device_count(), 'GPU(s)')\n!mkdir models","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:42:11.312402Z","iopub.execute_input":"2024-02-16T15:42:11.313010Z","iopub.status.idle":"2024-02-16T15:42:15.388253Z","shell.execute_reply.started":"2024-02-16T15:42:11.312966Z","shell.execute_reply":"2024-02-16T15:42:15.387232Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Configuration [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"class config:\n AMP = True\n BATCH_SIZE_TRAIN = 32\n BATCH_SIZE_VALID = 32\n EPOCHS = 5\n FOLDS = 5\n GRADIENT_ACCUMULATION_STEPS = 1\n MAX_GRAD_NORM = 1e7\n NUM_WORKERS = 0 # multiprocessing.cpu_count()\n PRINT_FREQ = 20\n SEED = 20\n TRAIN_FULL_DATA = False\n VISUALIZE = True\n WEIGHT_DECAY = 0.01\n \n \nclass paths:\n OUTPUT_DIR = \"/kaggle/working/\"\n TRAIN_CSV = \"/kaggle/input/hms-harmful-brain-activity-classification/train.csv\"\n TRAIN_EEGS = \"/kaggle/input/hms-harmful-brain-activity-classification/train_eegs/\"","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:42:15.390400Z","iopub.execute_input":"2024-02-16T15:42:15.391067Z","iopub.status.idle":"2024-02-16T15:42:15.397326Z","shell.execute_reply.started":"2024-02-16T15:42:15.391039Z","shell.execute_reply":"2024-02-16T15:42:15.396433Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Utils [↑](#top) \n\n***\n\nUtility functions.","metadata":{}},{"cell_type":"code","source":"class AverageMeter(object):\n \"\"\"Computes and stores the average and current value\"\"\"\n def __init__(self):\n self.reset()\n\n def reset(self):\n self.val = 0\n self.avg = 0\n self.sum = 0\n self.count = 0\n\n def update(self, val, n=1):\n self.val = val\n self.sum += val * n\n self.count += n\n self.avg = self.sum / self.count\n\n\ndef asMinutes(s: float):\n \"Convert to minutes.\"\n m = math.floor(s / 60)\n s -= m * 60\n return '%dm %ds' % (m, s)\n\n\ndef timeSince(since: float, percent: float):\n now = time.time()\n s = now - since\n es = s / (percent)\n rs = es - s\n return '%s (remain %s)' % (asMinutes(s), asMinutes(rs))\n\n\ndef get_logger(filename=paths.OUTPUT_DIR):\n from logging import getLogger, INFO, StreamHandler, FileHandler, Formatter\n logger = getLogger(__name__)\n logger.setLevel(INFO)\n handler1 = StreamHandler()\n handler1.setFormatter(Formatter(\"%(message)s\"))\n handler2 = FileHandler(filename=f\"{filename}.log\")\n handler2.setFormatter(Formatter(\"%(message)s\"))\n logger.addHandler(handler1)\n logger.addHandler(handler2)\n return logger\n\ndef eeg_from_parquet(parquet_path: str, display: bool = False) -> np.ndarray:\n \"\"\"\n This function reads a parquet file and extracts the middle 50 seconds of readings. Then it fills NaN values\n with the mean value (ignoring NaNs).\n :param parquet_path: path to parquet file.\n :param display: whether to display EEG plots or not.\n :return data: np.array of shape (time_steps, eeg_features) -> (10_000, 8)\n \"\"\"\n # === Extract middle 50 seconds ===\n eeg = pd.read_parquet(parquet_path, columns=eeg_features)\n rows = len(eeg)\n offset = (rows - 10_000) // 2 # 50 * 200 = 10_000\n eeg = eeg.iloc[offset:offset+10_000] # middle 50 seconds, has the same amount of readings to left and right\n if display: \n plt.figure(figsize=(10,5))\n offset = 0\n # === Convert to numpy ===\n data = np.zeros((10_000, len(eeg_features))) # create placeholder of same shape with zeros\n for index, feature in enumerate(eeg_features):\n x = eeg[feature].values.astype('float32') # convert to float32\n mean = np.nanmean(x) # arithmetic mean along the specified axis, ignoring NaNs\n nan_percentage = np.isnan(x).mean() # percentage of NaN values in feature\n # === Fill nan values ===\n if nan_percentage < 1: # if some values are nan, but not all\n x = np.nan_to_num(x, nan=mean)\n else: # if all values are nan\n x[:] = 0\n data[:, index] = x\n if display: \n if index != 0:\n offset += x.max()\n plt.plot(range(10_000), x-offset, label=feature)\n offset -= x.min()\n if display:\n plt.legend()\n name = parquet_path.split('/')[-1].split('.')[0]\n plt.yticks([])\n plt.title(f'EEG {name}',size=16)\n plt.show() \n return data\n\n\ndef seed_everything(seed: int):\n random.seed(seed)\n np.random.seed(seed)\n torch.manual_seed(seed)\n os.environ['PYTHONHASHSEED'] = str(seed) \n \n \ndef sep():\n print(\"-\"*100)\n\n \ntarget_preds = [x + \"_pred\" for x in ['seizure_vote', 'lpd_vote', 'gpd_vote', 'lrda_vote', 'grda_vote', 'other_vote']]\nlabel_to_num = {'Seizure': 0, 'LPD': 1, 'GPD': 2, 'LRDA': 3, 'GRDA': 4, 'Other':5}\nnum_to_label = {v: k for k, v in label_to_num.items()}\nLOGGER = get_logger()\nseed_everything(config.SEED)","metadata":{"_kg_hide-input":true,"execution":{"iopub.status.busy":"2024-02-16T15:42:15.398692Z","iopub.execute_input":"2024-02-16T15:42:15.398946Z","iopub.status.idle":"2024-02-16T15:42:15.424097Z","shell.execute_reply.started":"2024-02-16T15:42:15.398924Z","shell.execute_reply":"2024-02-16T15:42:15.423159Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Load Data [↑](#top) \n\n***\n\nLoad the competition's data.","metadata":{}},{"cell_type":"code","source":"train_df = pd.read_csv(paths.TRAIN_CSV)\nlabel_cols = train_df.columns[-6:]\nprint(f\"Train cataframe shape is: {train_df.shape}\")\nprint(f\"Labels: {list(label_cols)}\")\ntrain_df.head()","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:42:15.425317Z","iopub.execute_input":"2024-02-16T15:42:15.425621Z","iopub.status.idle":"2024-02-16T15:42:15.747673Z","shell.execute_reply.started":"2024-02-16T15:42:15.425597Z","shell.execute_reply":"2024-02-16T15:42:15.746747Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Read one EEG parquet\n\nAll of the EEG data (for both train and test) was collected at a frequency of 200 samples per second,\n\nEach EEG parquet results in a dataframe with `seconds` rows and 20 columns.\n\n- EEG features are: `['Fp1', 'F3', 'C3', 'P3', 'F7', 'T3', 'T5', 'O1', 'Fz', 'Cz', 'Pz', 'Fp2', 'F4', 'C4', 'P4', 'F8', 'T4', 'T6', 'O2', 'EKG']`\n- We will use these features: `['Fp1','T3','C3','O1','Fp2','C4','T4','O2']`\n\n","metadata":{}},{"cell_type":"code","source":"eeg_df = pd.read_parquet(paths.TRAIN_EEGS + \"100261680.parquet\")\neeg_features = eeg_df.columns\nprint(f'There are {len(eeg_features)} raw eeg features')\nprint(list(eeg_features))\neeg_features = ['Fp1','T3','C3','O1','Fp2','C4','T4','O2']\nfeature_to_index = {x:y for x,y in zip(eeg_features, range(len(eeg_features)))}","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:42:15.749927Z","iopub.execute_input":"2024-02-16T15:42:15.750208Z","iopub.status.idle":"2024-02-16T15:42:16.055926Z","shell.execute_reply.started":"2024-02-16T15:42:15.750184Z","shell.execute_reply":"2024-02-16T15:42:16.054936Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Read all EEG parquets","metadata":{}},{"cell_type":"code","source":"%%time\n\nCREATE_EEGS = False\nall_eegs = {}\nvisualize = 1\neeg_paths = glob(paths.TRAIN_EEGS + \"*.parquet\")\neeg_ids = train_df.eeg_id.unique()\n\nfor i, eeg_id in tqdm(enumerate(eeg_ids)): \n # Save EEG to Python dictionary of numpy arrays\n eeg_path = paths.TRAIN_EEGS + str(eeg_id) + \".parquet\"\n data = eeg_from_parquet(eeg_path, display=i| Data pre-processing [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"df = pd.read_csv(paths.TRAIN_CSV)\nlabel_cols = df.columns[-6:]\n\ntrain_df = df.groupby('eeg_id')[['patient_id']].agg('first')\naux = df.groupby('eeg_id')[label_cols].agg('sum') \n\nfor label in label_cols:\n train_df[label] = aux[label].values\n \ny_data = train_df[label_cols].values\ny_data = y_data / y_data.sum(axis=1,keepdims=True)\ntrain_df[label_cols] = y_data\n\naux = df.groupby('eeg_id')[['expert_consensus']].agg('first')\ntrain_df['target'] = aux\n\ntrain_df = train_df.reset_index()\ntrain_df = train_df.loc[train_df.eeg_id.isin(eeg_ids)]\nprint(f\"Train dataframe with unique eeg_id has shape: {train_df.shape}\")\ntrain_df.head()","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:34.661825Z","iopub.execute_input":"2024-02-16T15:44:34.662437Z","iopub.status.idle":"2024-02-16T15:44:34.911990Z","shell.execute_reply.started":"2024-02-16T15:44:34.662399Z","shell.execute_reply":"2024-02-16T15:44:34.911086Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Validation [↑](#top) \n\n***\n\nWe train using `GroupKFold` on `patient_id`.","metadata":{}},{"cell_type":"code","source":"from sklearn.model_selection import KFold, GroupKFold\n\n\ngkf = GroupKFold(n_splits=config.FOLDS)\nfor fold, (train_index, valid_index) in enumerate(gkf.split(train_df, train_df.target, train_df.patient_id)):\n train_df.loc[valid_index, \"fold\"] = int(fold)\n \ndisplay(train_df.groupby('fold').size()), sep()\ndisplay(train_df.head())","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:34.913365Z","iopub.execute_input":"2024-02-16T15:44:34.913763Z","iopub.status.idle":"2024-02-16T15:44:35.424038Z","shell.execute_reply.started":"2024-02-16T15:44:34.913727Z","shell.execute_reply":"2024-02-16T15:44:35.423132Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Butter Low-Pass Filter [↑](#top) \n\n***\n\n- [scipy.signal.butter()][1]\n- [scipy.signal.lfilter()][2]\n\n[1]: https://docs.scipy.org/doc/scipy/reference/generated/scipy.signal.butter.html#scipy.signal.butter\n[2]: https://docs.scipy.org/doc/scipy/reference/generated/scipy.signal.lfilter.html#scipy.signal.lfilter","metadata":{}},{"cell_type":"code","source":"from scipy.signal import butter, lfilter\n\ndef butter_lowpass_filter(data, cutoff_freq: int = 20, sampling_rate: int = 200, order: int = 4):\n nyquist = 0.5 * sampling_rate\n normal_cutoff = cutoff_freq / nyquist\n b, a = butter(order, normal_cutoff, btype='low', analog=False)\n filtered_data = lfilter(b, a, data, axis=0)\n return filtered_data","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:35.425620Z","iopub.execute_input":"2024-02-16T15:44:35.425965Z","iopub.status.idle":"2024-02-16T15:44:35.487730Z","shell.execute_reply.started":"2024-02-16T15:44:35.425932Z","shell.execute_reply":"2024-02-16T15:44:35.487001Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"## Visualize\n","metadata":{}},{"cell_type":"code","source":"frequencies = [1,2,4,8,16][::-1] # frequencies in Hz\nx = [all_eegs[eeg_ids[0]][:,0]] # select one EEG feature\n\nfor frequency in frequencies:\n x.append(butter_lowpass_filter(x[0], cutoff_freq=frequency))\n\nplt.figure(figsize=(12,8))\nplt.plot(range(10_000), x[0], label='without filter')\nfor k in range(1,len(x)):\n plt.plot(range(10_000),x[k]-k*(x[0].max()-x[0].min()), label=f'with filter {frequencies[k-1]}Hz')\n\nplt.legend()\nplt.yticks([])\nplt.title('Butter Low-Pass Filter Examples',size=18)\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:35.488800Z","iopub.execute_input":"2024-02-16T15:44:35.489059Z","iopub.status.idle":"2024-02-16T15:44:36.048322Z","shell.execute_reply.started":"2024-02-16T15:44:35.489036Z","shell.execute_reply":"2024-02-16T15:44:36.047381Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Dataset [↑](#top) \n\n***\n\nCreate a custom `Dataset` to load data.\n\n- [How to Convert EEG to Spectrograms][1]: to understand the feature engineering performed in the generation method.\n- [How To Create Spectrogram From Eeg?][2]: original post on how to create Spectrograms from EEGs.\n- [Introduction to EEG][3]: short video to better understand EEGs.\n\n[1]: https://www.kaggle.com/competitions/hms-harmful-brain-activity-classification/discussion/469760\n[2]: https://www.kaggle.com/competitions/hms-harmful-brain-activity-classification/discussion/467877\n[3]: https://www.youtube.com/watch?v=XMizSSOejg0","metadata":{}},{"cell_type":"code","source":"class CustomDataset(Dataset):\n def __init__(\n self, df: pd.DataFrame, config, mode: str = 'train',\n eegs: Dict[int, np.ndarray] = all_eegs, downsample: int = 5\n ): \n self.df = df\n self.config = config\n self.batch_size = self.config.BATCH_SIZE_TRAIN\n self.mode = mode\n self.eegs = eegs\n self.downsample = downsample\n \n def __len__(self):\n \"\"\"\n Length of dataset.\n \"\"\"\n return len(self.df)\n \n def __getitem__(self, index):\n \"\"\"\n Get one item.\n \"\"\"\n X, y = self.__data_generation(index)\n X = X[::self.downsample,:]\n output = {\n \"X\": torch.tensor(X, dtype=torch.float32),\n \"y\": torch.tensor(y, dtype=torch.float32)\n }\n return output\n \n def __data_generation(self, index):\n row = self.df.iloc[index]\n X = np.zeros((10_000, 8), dtype='float32')\n y = np.zeros(6, dtype='float32')\n data = self.eegs[row.eeg_id]\n\n # === Feature engineering ===\n X[:,0] = data[:,feature_to_index['Fp1']] - data[:,feature_to_index['T3']]\n X[:,1] = data[:,feature_to_index['T3']] - data[:,feature_to_index['O1']]\n\n X[:,2] = data[:,feature_to_index['Fp1']] - data[:,feature_to_index['C3']]\n X[:,3] = data[:,feature_to_index['C3']] - data[:,feature_to_index['O1']]\n\n X[:,4] = data[:,feature_to_index['Fp2']] - data[:,feature_to_index['C4']]\n X[:,5] = data[:,feature_to_index['C4']] - data[:,feature_to_index['O2']]\n\n X[:,6] = data[:,feature_to_index['Fp2']] - data[:,feature_to_index['T4']]\n X[:,7] = data[:,feature_to_index['T4']] - data[:,feature_to_index['O2']]\n\n # === Standarize ===\n X = np.clip(X,-1024, 1024)\n X = np.nan_to_num(X, nan=0) / 32.0\n\n # === Butter Low-pass Filter ===\n X = butter_lowpass_filter(X)\n \n if self.mode != 'test':\n y = row[label_cols].values.astype(np.float32)\n \n return X, y","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:36.049584Z","iopub.execute_input":"2024-02-16T15:44:36.049879Z","iopub.status.idle":"2024-02-16T15:44:36.064241Z","shell.execute_reply.started":"2024-02-16T15:44:36.049853Z","shell.execute_reply":"2024-02-16T15:44:36.063356Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | DataLoader [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"train_dataset = CustomDataset(train_df, config, mode=\"train\")\ntrain_loader = DataLoader(\n train_dataset,\n batch_size=config.BATCH_SIZE_TRAIN,\n shuffle=False,\n num_workers=config.NUM_WORKERS, pin_memory=True, drop_last=True\n)\noutput = train_dataset[0]\nX, y = output[\"X\"], output[\"y\"]\nprint(f\"X shape: {X.shape}\")\nprint(f\"y shape: {y.shape}\")","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:36.065545Z","iopub.execute_input":"2024-02-16T15:44:36.065857Z","iopub.status.idle":"2024-02-16T15:44:36.108674Z","shell.execute_reply.started":"2024-02-16T15:44:36.065827Z","shell.execute_reply":"2024-02-16T15:44:36.107742Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"### Visualize DataLoader\n","metadata":{}},{"cell_type":"code","source":"if config.VISUALIZE:\n for batch in train_loader:\n X = batch.pop(\"X\")\n y = batch.pop(\"y\")\n for item in range(4):\n plt.figure(figsize=(20,4))\n offset = 0\n for col in range(X.shape[-1]):\n if col != 0:\n offset -= X[item,:,col].min()\n plt.plot(range(2_000), X[item,:,col]+offset,label=f'feature {col+1}')\n offset += X[item,:,col].max()\n tt = f'{y[col][0]:0.1f}'\n for t in y[col][1:]:\n tt += f', {t:0.1f}'\n plt.title(f'EEG_Id = {eeg_ids[item]}\\nTarget = {tt}',size=14)\n plt.legend()\n plt.show()\n break","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:36.109854Z","iopub.execute_input":"2024-02-16T15:44:36.110190Z","iopub.status.idle":"2024-02-16T15:44:39.055302Z","shell.execute_reply.started":"2024-02-16T15:44:36.110157Z","shell.execute_reply":"2024-02-16T15:44:39.054422Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Model [↑](#top) \n\n***\n\n
 ","metadata":{}},{"cell_type":"code","source":"class Wave_Block(nn.Module):\n def __init__(self, in_channels: int, out_channels: int, dilation_rates: int, kernel_size: int = 3):\n \"\"\"\n WaveNet building block.\n :param in_channels: number of input channels.\n :param out_channels: number of output channels.\n :param dilation_rates: how many levels of dilations are used.\n :param kernel_size: size of the convolving kernel.\n \"\"\"\n super(Wave_Block, self).__init__()\n self.num_rates = dilation_rates\n self.convs = nn.ModuleList()\n self.filter_convs = nn.ModuleList()\n self.gate_convs = nn.ModuleList()\n self.convs.append(nn.Conv1d(in_channels, out_channels, kernel_size=1, bias=True))\n \n dilation_rates = [2 ** i for i in range(dilation_rates)]\n for dilation_rate in dilation_rates:\n self.filter_convs.append(\n nn.Conv1d(out_channels, out_channels, kernel_size=kernel_size,\n padding=int((dilation_rate*(kernel_size-1))/2), dilation=dilation_rate))\n self.gate_convs.append(\n nn.Conv1d(out_channels, out_channels, kernel_size=kernel_size,\n padding=int((dilation_rate*(kernel_size-1))/2), dilation=dilation_rate))\n self.convs.append(nn.Conv1d(out_channels, out_channels, kernel_size=1, bias=True))\n \n for i in range(len(self.convs)):\n nn.init.xavier_uniform_(self.convs[i].weight, gain=nn.init.calculate_gain('relu'))\n nn.init.zeros_(self.convs[i].bias)\n\n for i in range(len(self.filter_convs)):\n nn.init.xavier_uniform_(self.filter_convs[i].weight, gain=nn.init.calculate_gain('relu'))\n nn.init.zeros_(self.filter_convs[i].bias)\n\n for i in range(len(self.gate_convs)):\n nn.init.xavier_uniform_(self.gate_convs[i].weight, gain=nn.init.calculate_gain('relu'))\n nn.init.zeros_(self.gate_convs[i].bias)\n\n def forward(self, x):\n x = self.convs[0](x)\n res = x\n for i in range(self.num_rates):\n tanh_out = torch.tanh(self.filter_convs[i](x))\n sigmoid_out = torch.sigmoid(self.gate_convs[i](x))\n x = tanh_out * sigmoid_out\n x = self.convs[i + 1](x) \n res = res + x\n return res\n \nclass WaveNet(nn.Module):\n def __init__(self, input_channels: int = 1, kernel_size: int = 3):\n super(WaveNet, self).__init__()\n self.model = nn.Sequential(\n Wave_Block(input_channels, 8, 12, kernel_size),\n Wave_Block(8, 16, 8, kernel_size),\n Wave_Block(16, 32, 4, kernel_size),\n Wave_Block(32, 64, 1, kernel_size) \n )\n def forward(self, x: torch.Tensor) -> torch.Tensor:\n x = x.permute(0, 2, 1) \n output = self.model(x)\n return output\n\n\nclass CustomModel(nn.Module):\n def __init__(self):\n super(CustomModel, self).__init__()\n self.model = WaveNet()\n self.global_avg_pooling = nn.AdaptiveAvgPool1d(1)\n self.dropout = 0.0\n self.head = nn.Sequential(\n nn.Linear(256, 64),\n nn.BatchNorm1d(64),\n nn.ReLU(),\n nn.Dropout(self.dropout),\n nn.Linear(64, 6)\n )\n \n def forward(self, x: torch.Tensor):\n \"\"\"\n Forwward pass.\n \"\"\"\n x1 = self.model(x[:, :, 0:1])\n x1 = self.global_avg_pooling(x1)\n x1 = x1.squeeze()\n x2 = self.model(x[:, :, 1:2])\n x2 = self.global_avg_pooling(x2)\n x2 = x2.squeeze()\n z1 = torch.mean(torch.stack([x1, x2]), dim=0)\n\n x1 = self.model(x[:, :, 2:3])\n x1 = self.global_avg_pooling(x1)\n x1 = x1.squeeze()\n x2 = self.model(x[:, :, 3:4])\n x2 = self.global_avg_pooling(x2)\n x2 = x2.squeeze()\n z2 = torch.mean(torch.stack([x1, x2]), dim=0)\n \n x1 = self.model(x[:, :, 4:5])\n x1 = self.global_avg_pooling(x1)\n x1 = x1.squeeze()\n x2 = self.model(x[:, :, 5:6])\n x2 = self.global_avg_pooling(x2)\n x2 = x2.squeeze()\n z3 = torch.mean(torch.stack([x1, x2]), dim=0)\n \n x1 = self.model(x[:, :, 6:7])\n x1 = self.global_avg_pooling(x1)\n x1 = x1.squeeze()\n x2 = self.model(x[:, :, 7:8])\n x2 = self.global_avg_pooling(x2)\n x2 = x2.squeeze()\n z4 = torch.mean(torch.stack([x1, x2]), dim=0)\n \n y = torch.cat([z1, z2, z3, z4], dim=1)\n y = self.head(y)\n \n return y\n\nmodel = CustomModel()\ntotal_params = sum(p.numel() for p in model.parameters())\nprint(f\"Total number of parameters: {total_params}\")","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:39.059992Z","iopub.execute_input":"2024-02-16T15:44:39.060368Z","iopub.status.idle":"2024-02-16T15:44:39.112072Z","shell.execute_reply.started":"2024-02-16T15:44:39.060321Z","shell.execute_reply":"2024-02-16T15:44:39.111256Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Scheduler [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"from torch.optim.lr_scheduler import OneCycleLR\n\nEPOCHS = config.EPOCHS\nBATCHES = len(train_loader)\nsteps = []\nlrs = []\noptim_lrs = []\nmodel = CustomModel()\noptimizer = torch.optim.AdamW(model.parameters(), lr=1e-4)\nscheduler = OneCycleLR(\n optimizer,\n max_lr=1e-3,\n epochs=config.EPOCHS,\n steps_per_epoch=len(train_loader),\n pct_start=0.1,\n anneal_strategy=\"cos\",\n final_div_factor=100,\n)\nfor epoch in range(EPOCHS):\n for batch in range(BATCHES):\n scheduler.step()\n lrs.append(scheduler.get_last_lr()[0])\n steps.append(epoch * BATCHES + batch)\n\nmax_lr = max(lrs)\nmin_lr = min(lrs)\nprint(f\"Maximum LR: {max_lr} | Minimum LR: {min_lr}\")\nplt.figure()\nplt.plot(steps, lrs, label='OneCycle')\nplt.ticklabel_format(axis='y', style='sci', scilimits=(0,0))\nplt.xlabel(\"Step\")\nplt.ylabel(\"Learning Rate\")\nplt.show()","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:39.113080Z","iopub.execute_input":"2024-02-16T15:44:39.113343Z","iopub.status.idle":"2024-02-16T15:44:39.319587Z","shell.execute_reply.started":"2024-02-16T15:44:39.113320Z","shell.execute_reply":"2024-02-16T15:44:39.318548Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Loss Function [↑](#top) \n\n***\n\nIn PyTorch's [KLDivLoss][1], the reduction parameter determines how the loss is aggregated across different dimensions. Two common options are `mean` and `batchmean`.\n\n- `reduction`='mean': When reduction is set to \"mean\", the Kullback-Leibler Divergence loss is computed and then averaged over all the elements in the input tensor. The result is a scalar value representing the mean loss.\n- `reduction`='batchmean': When reduction is set to \"batchmean\", the Kullback-Leibler Divergence loss is computed independently for each item in the batch, and then the mean is taken over the batch dimension. This is useful when you have a batch of samples, and you want the average loss per sample.\n\n[1]: https://pytorch.org/docs/stable/generated/torch.nn.KLDivLoss.html\n","metadata":{}},{"cell_type":"code","source":"import torch.nn.functional as F\n\n# === Reduction = \"mean\" ===\ncriterion = nn.KLDivLoss(reduction=\"mean\")\ny_pred = F.log_softmax(torch.randn(6, 2, requires_grad=True), dim=1)\ny_true = F.softmax(torch.rand(6, 2), dim=1)\nprint(f\"Predictions: {y_pred}\")\nprint(f\"Targets: {y_true}\")\noutput = criterion(y_pred, y_true)\nprint(f\"Output: {output}\")\n\nprint(\"\\n\", \"=\"*100, \"\\n\")\n\n# === Reduction = \"batchmean\" ===\ncriterion = nn.KLDivLoss(reduction=\"batchmean\")\ny_pred = F.log_softmax(torch.randn(2, 6, requires_grad=True), dim=1)\ny_true = F.softmax(torch.rand(2, 6), dim=1)\nprint(f\"Predictions: {y_pred}\")\nprint(f\"Targets: {y_true}\")\noutput = criterion(y_pred, y_true)\nprint(f\"Output: {output}\")","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:39.320860Z","iopub.execute_input":"2024-02-16T15:44:39.321822Z","iopub.status.idle":"2024-02-16T15:44:39.361865Z","shell.execute_reply.started":"2024-02-16T15:44:39.321783Z","shell.execute_reply":"2024-02-16T15:44:39.361034Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Train and Validation Functions [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"def train_epoch(train_loader, model, optimizer, epoch, scheduler, device):\n \"\"\"One epoch training pass.\"\"\"\n model.train()\n criterion = nn.KLDivLoss(reduction=\"batchmean\")\n scaler = torch.cuda.amp.GradScaler(enabled=config.AMP)\n losses = AverageMeter()\n start = end = time.time()\n global_step = 0\n \n # ========== ITERATE OVER TRAIN BATCHES ============\n with tqdm(train_loader, unit=\"train_batch\", desc='Train') as tqdm_train_loader:\n for step, batch in enumerate(tqdm_train_loader):\n X = batch.pop(\"X\").to(device) # send inputs to `device`\n y = batch.pop(\"y\").to(device) # send labels to `device`\n batch_size = y.size(0)\n with torch.cuda.amp.autocast(enabled=config.AMP):\n y_preds = model(X)\n loss = criterion(F.log_softmax(y_preds, dim=1), y)\n if config.GRADIENT_ACCUMULATION_STEPS > 1:\n loss = loss / config.GRADIENT_ACCUMULATION_STEPS\n losses.update(loss.item(), batch_size)\n scaler.scale(loss).backward()\n grad_norm = torch.nn.utils.clip_grad_norm_(model.parameters(), config.MAX_GRAD_NORM)\n \n if (step + 1) % config.GRADIENT_ACCUMULATION_STEPS == 0:\n scaler.step(optimizer)\n scaler.update()\n optimizer.zero_grad()\n global_step += 1\n scheduler.step()\n end = time.time()\n\n # ========== LOG INFO ==========\n if step % config.PRINT_FREQ == 0 or step == (len(train_loader)-1):\n print('Epoch: [{0}][{1}/{2}] '\n 'Elapsed {remain:s} '\n 'Loss: {loss.avg:.4f} '\n 'Grad: {grad_norm:.4f} '\n 'LR: {lr:.8f} '\n .format(epoch+1, step, len(train_loader), \n remain=timeSince(start, float(step+1)/len(train_loader)),\n loss=losses,\n grad_norm=grad_norm,\n lr=scheduler.get_last_lr()[0]))\n\n return losses.avg\n\n\ndef valid_epoch(valid_loader, model, device):\n model.eval() \n softmax = nn.Softmax(dim=1)\n losses = AverageMeter()\n prediction_dict = {}\n preds = []\n start = end = time.time()\n with tqdm(valid_loader, unit=\"valid_batch\", desc='Validation') as tqdm_valid_loader:\n for step, batch in enumerate(tqdm_valid_loader):\n X = batch.pop(\"X\").to(device) \n y = batch.pop(\"y\").to(device)\n batch_size = y.size(0)\n with torch.no_grad():\n y_preds = model(X)\n loss = criterion(F.log_softmax(y_preds, dim=1), y)\n if config.GRADIENT_ACCUMULATION_STEPS > 1:\n loss = loss / config.GRADIENT_ACCUMULATION_STEPS\n losses.update(loss.item(), batch_size)\n y_preds = softmax(y_preds)\n preds.append(y_preds.to('cpu').numpy()) \n end = time.time()\n\n # ========== LOG INFO ==========\n if step % config.PRINT_FREQ == 0 or step == (len(valid_loader)-1):\n print('EVAL: [{0}/{1}] '\n 'Elapsed {remain:s} '\n 'Loss: {loss.avg:.4f} '\n .format(step, len(valid_loader),\n remain=timeSince(start, float(step+1)/len(valid_loader)),\n loss=losses))\n \n prediction_dict[\"predictions\"] = np.concatenate(preds)\n return losses.avg, prediction_dict","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:39.363128Z","iopub.execute_input":"2024-02-16T15:44:39.363400Z","iopub.status.idle":"2024-02-16T15:44:39.381083Z","shell.execute_reply.started":"2024-02-16T15:44:39.363377Z","shell.execute_reply":"2024-02-16T15:44:39.380272Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Train Loop [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"def train_loop(df, fold):\n \n LOGGER.info(f\"========== Fold: {fold} training ==========\")\n\n # ======== SPLIT ==========\n train_folds = df[df['fold'] != fold].reset_index(drop=True)\n valid_folds = df[df['fold'] == fold].reset_index(drop=True)\n \n # ======== DATASETS ==========\n train_dataset = CustomDataset(train_folds, config, mode=\"train\")\n valid_dataset = CustomDataset(valid_folds, config, mode=\"train\")\n \n # ======== DATALOADERS ==========\n train_loader = DataLoader(train_dataset,\n batch_size=config.BATCH_SIZE_TRAIN,\n shuffle=True,\n num_workers=config.NUM_WORKERS, pin_memory=True, drop_last=True)\n valid_loader = DataLoader(valid_dataset,\n batch_size=config.BATCH_SIZE_VALID,\n shuffle=False,\n num_workers=config.NUM_WORKERS, pin_memory=True, drop_last=False)\n \n # ======== MODEL ==========\n model = CustomModel()\n model.to(device)\n\n optimizer = torch.optim.AdamW(model.parameters(), lr=0.1, weight_decay=config.WEIGHT_DECAY)\n scheduler = OneCycleLR(\n optimizer,\n max_lr=1e-3,\n epochs=config.EPOCHS,\n steps_per_epoch=len(train_loader),\n pct_start=0.1,\n anneal_strategy=\"cos\",\n final_div_factor=100,\n )\n\n # ======= LOSS ==========\n criterion = nn.KLDivLoss(reduction=\"batchmean\")\n \n best_loss = np.inf\n # ====== ITERATE EPOCHS ========\n for epoch in range(config.EPOCHS):\n start_time = time.time()\n\n # ======= TRAIN ==========\n avg_train_loss = train_epoch(train_loader, model, optimizer, epoch, scheduler, device)\n\n # ======= EVALUATION ==========\n avg_val_loss, prediction_dict = valid_epoch(valid_loader, model, device)\n predictions = prediction_dict[\"predictions\"]\n \n # ======= SCORING ==========\n elapsed = time.time() - start_time\n\n LOGGER.info(f'Epoch {epoch+1} - avg_train_loss: {avg_train_loss:.4f} avg_val_loss: {avg_val_loss:.4f} time: {elapsed:.0f}s')\n \n if avg_val_loss < best_loss:\n best_loss = avg_val_loss\n LOGGER.info(f'Epoch {epoch+1} - Save Best Loss: {best_loss:.4f} Model')\n torch.save({'model': model.state_dict(),\n 'predictions': predictions},\n f\"/kaggle/working/models/wavenet_fold_{fold}_best.pth\")\n\n predictions = torch.load(f\"/kaggle/working/models/wavenet_fold_{fold}_best.pth\", \n map_location=torch.device('cpu'))['predictions']\n valid_folds[target_preds] = predictions\n\n torch.cuda.empty_cache()\n gc.collect()\n \n return valid_folds","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:44:39.382388Z","iopub.execute_input":"2024-02-16T15:44:39.382840Z","iopub.status.idle":"2024-02-16T15:44:39.395966Z","shell.execute_reply.started":"2024-02-16T15:44:39.382815Z","shell.execute_reply":"2024-02-16T15:44:39.395198Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Train [↑](#top) \n\n***","metadata":{}},{"cell_type":"code","source":"def get_result(oof_df):\n kl_loss = nn.KLDivLoss(reduction=\"batchmean\")\n labels = torch.tensor(oof_df[label_cols].values)\n preds = torch.tensor(oof_df[target_preds].values)\n preds = F.log_softmax(preds, dim=1)\n result = kl_loss(preds, labels)\n return result\n\nif not config.TRAIN_FULL_DATA:\n oof_df = pd.DataFrame()\n for fold in range(config.FOLDS):\n if fold in [0, 1, 2, 3, 4]:\n _oof_df = train_loop(train_df, fold)\n oof_df = pd.concat([oof_df, _oof_df])\n LOGGER.info(f\"========== Fold {fold} finished ==========\")\n oof_df = oof_df.reset_index(drop=True)\n oof_df.to_csv('/kaggle/working/models/oof_df.csv', index=False)\nelse:\n train_loop_full_data(train_df)","metadata":{"scrolled":true,"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"! zip -r models.zip /kaggle/working/models","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:45:16.622974Z","iopub.status.idle":"2024-02-16T15:45:16.623296Z","shell.execute_reply.started":"2024-02-16T15:45:16.623132Z","shell.execute_reply":"2024-02-16T15:45:16.623146Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# | Score [↑](#top) \n\n***","metadata":{"execution":{"iopub.status.busy":"2024-02-15T22:27:03.071166Z","iopub.execute_input":"2024-02-15T22:27:03.071564Z","iopub.status.idle":"2024-02-15T22:27:03.084649Z","shell.execute_reply.started":"2024-02-15T22:27:03.071534Z","shell.execute_reply":"2024-02-15T22:27:03.083623Z"}}},{"cell_type":"code","source":"import sys\nsys.path.append('/kaggle/input/kaggle-kl-div')\nfrom kaggle_kl_div import score\n\n# === Pre-process OOF ===\nlabel_cols = label_cols.tolist()\ngt = train_df[[\"eeg_id\"] + label_cols]\ngt.sort_values(by=\"eeg_id\", inplace=True)\ngt.reset_index(inplace=True, drop=True)\n\npreds = oof_df[[\"eeg_id\"] + target_preds]\npreds.columns = [\"eeg_id\"] + label_cols\npreds.sort_values(by=\"eeg_id\", inplace=True)\npreds.reset_index(inplace=True, drop=True)\n\ny_trues = gt[label_cols]\ny_preds = preds[label_cols]\n\noof = pd.DataFrame(y_preds.copy())\noof['id'] = np.arange(len(oof))\n\ntrue = pd.DataFrame(y_trues.copy())\ntrue['id'] = np.arange(len(true))\n\ncv = score(solution=true, submission=oof, row_id_column_name='id')\nprint('CV Score with WaveNet Raw EEG =',cv)","metadata":{"execution":{"iopub.status.busy":"2024-02-16T15:45:16.624627Z","iopub.status.idle":"2024-02-16T15:45:16.624947Z","shell.execute_reply.started":"2024-02-16T15:45:16.624788Z","shell.execute_reply":"2024-02-16T15:45:16.624803Z"},"trusted":true},"execution_count":null,"outputs":[]}]}