
G2Net Gravitational Waves
\n\n\n","metadata":{}},{"cell_type":"markdown","source":"What are we discussing today?
\n Constant Q Transform
\n GPU Efficient Network
\n FastAI
\n Test Time Augmentation
\n Weights and Biases for Experiment Tracking","metadata":{}},{"cell_type":"markdown","source":"
Upvote the kernel if you find it insightful!
","metadata":{}},{"cell_type":"markdown","source":"Wandb is a developer tool for companies turn deep learning research projects into deployed software by helping teams track their models, visualize model performance and easily automate training and improving models.\nWe will use their tools to log hyperparameters and output metrics from your runs, then visualize and compare results and quickly share findings with your colleagues.
We'll be using this to train our K Fold Cross Validation and gain better insights about our training.
Import GPU Efficient Network from Github
","metadata":{}},{"cell_type":"code","source":"!git clone https://github.com/idstcv/GPU-Efficient-Networks.git","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-30T14:07:19.812001Z","iopub.execute_input":"2021-07-30T14:07:19.812336Z","iopub.status.idle":"2021-07-30T14:07:21.284269Z","shell.execute_reply.started":"2021-07-30T14:07:19.812302Z","shell.execute_reply":"2021-07-30T14:07:21.283228Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"cd ./GPU-Efficient-Networks","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-30T14:07:21.285976Z","iopub.execute_input":"2021-07-30T14:07:21.286330Z","iopub.status.idle":"2021-07-30T14:07:21.294763Z","shell.execute_reply.started":"2021-07-30T14:07:21.286288Z","shell.execute_reply":"2021-07-30T14:07:21.293604Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"import GENet","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:21.297015Z","iopub.execute_input":"2021-07-30T14:07:21.297643Z","iopub.status.idle":"2021-07-30T14:07:22.965841Z","shell.execute_reply.started":"2021-07-30T14:07:21.297602Z","shell.execute_reply":"2021-07-30T14:07:22.964848Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"cd ../","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"execution":{"iopub.status.busy":"2021-07-30T14:07:22.969281Z","iopub.execute_input":"2021-07-30T14:07:22.969584Z","iopub.status.idle":"2021-07-30T14:07:22.978228Z","shell.execute_reply.started":"2021-07-30T14:07:22.969544Z","shell.execute_reply":"2021-07-30T14:07:22.977244Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Import Libraries
","metadata":{}},{"cell_type":"code","source":"# Python library to interact with the file system.\nimport os\n\n#Visualization\nimport plotly.express as px\n\n\n# Software library written for data manipulation and analysis.\nimport pandas as pd\n\n# fastai library for computer vision tasks\nfrom fastai.vision.all import *\nfrom fastai.callback.wandb import *\n\n# Developing and training neural network based deep learning models.\nimport torch\nfrom torch import nn\n\n# Python library for image augmentation\nimport albumentations as A\n\n\nimport wandb\nwandb.login()","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-07-30T14:07:22.981420Z","iopub.execute_input":"2021-07-30T14:07:22.981925Z","iopub.status.idle":"2021-07-30T14:07:36.824620Z","shell.execute_reply.started":"2021-07-30T14:07:22.981896Z","shell.execute_reply":"2021-07-30T14:07:36.823739Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Define Seed for Reproducibility
","metadata":{}},{"cell_type":"code","source":"def set_seed(dls, x=42): \n random.seed(x)\n dls.rng.seed(x) \n np.random.seed(x)\n torch.manual_seed(x)\n torch.backends.cudnn.deterministic = True\n torch.backends.cudnn.benchmark = False\n if torch.cuda.is_available(): \n torch.cuda.manual_seed_all(x)\n ","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:36.826018Z","iopub.execute_input":"2021-07-30T14:07:36.826494Z","iopub.status.idle":"2021-07-30T14:07:36.832974Z","shell.execute_reply.started":"2021-07-30T14:07:36.826449Z","shell.execute_reply":"2021-07-30T14:07:36.831805Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Load Train and Test
","metadata":{}},{"cell_type":"code","source":"path = Path('../input/g2net-constant-q-transformed')","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:36.834459Z","iopub.execute_input":"2021-07-30T14:07:36.834853Z","iopub.status.idle":"2021-07-30T14:07:36.843190Z","shell.execute_reply.started":"2021-07-30T14:07:36.834817Z","shell.execute_reply":"2021-07-30T14:07:36.842291Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_df = pd.read_csv(path/'training_labels.csv')\ntrain_df","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:36.846275Z","iopub.execute_input":"2021-07-30T14:07:36.846825Z","iopub.status.idle":"2021-07-30T14:07:37.327210Z","shell.execute_reply.started":"2021-07-30T14:07:36.846786Z","shell.execute_reply":"2021-07-30T14:07:37.326392Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"train_df['id'] = train_df['id'].map(lambda x : f'{path}/train_cqt/train_cqt/{x}.png' )\ntrain_df.head()","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:37.329208Z","iopub.execute_input":"2021-07-30T14:07:37.329574Z","iopub.status.idle":"2021-07-30T14:07:37.727213Z","shell.execute_reply.started":"2021-07-30T14:07:37.329535Z","shell.execute_reply":"2021-07-30T14:07:37.726213Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"\ntrain_df = train_df.sample(frac=0.1, random_state=42)\ntrain_df = train_df.reset_index(drop=True)\nlen(train_df)","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:37.728694Z","iopub.execute_input":"2021-07-30T14:07:37.729062Z","iopub.status.idle":"2021-07-30T14:07:37.763804Z","shell.execute_reply.started":"2021-07-30T14:07:37.729026Z","shell.execute_reply":"2021-07-30T14:07:37.762832Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Minimal EDA
","metadata":{}},{"cell_type":"code","source":"dist = train_df.target.map({0:'Target 0', 1:'Target 1'})\ndist = dist.value_counts()\nfig = px.pie(dist,\n values='target',\n names=dist.index,\n hole=.4,title=\"Target Distribution\")\nfig.update_traces(textinfo='percent+label', pull=0.05)\nfig.show()","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:37.765156Z","iopub.execute_input":"2021-07-30T14:07:37.765508Z","iopub.status.idle":"2021-07-30T14:07:38.833478Z","shell.execute_reply.started":"2021-07-30T14:07:37.765470Z","shell.execute_reply":"2021-07-30T14:07:38.831742Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Create Dataloaders
","metadata":{}},{"cell_type":"code","source":"# obtain the input images.\ndef get_x(r):\n return r['id']\n\n# obtain the targets.\ndef get_y(r):\n return r['target']","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:38.835052Z","iopub.execute_input":"2021-07-30T14:07:38.835422Z","iopub.status.idle":"2021-07-30T14:07:38.840309Z","shell.execute_reply.started":"2021-07-30T14:07:38.835385Z","shell.execute_reply":"2021-07-30T14:07:38.839264Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Albumentations with FastAI
\n\n The Albumentation code has been borrowed from Fastai docs. It's very common to use different transforms on the training dataset versus the validation dataset. Lets see how!
\nAlbumentations is a Python library for image augmentation. Image augmentation is used in deep learning and computer vision tasks to increase the quality of trained models. The purpose of image augmentation is to create new training samples from the existing data.
\n📍 Albumentations supports all common computer vision tasks such as classification, semantic segmentation, instance segmentation, object detection, and pose estimation.
\n📍 The library provides a simple unified API to work with all data types: images (RBG-images, grayscale images, multispectral images), segmentation masks, bounding boxes, and keypoints.
\n📍 The library contains more than 70 different augmentations to generate new training samples from the existing data.
\n📍 Albumentations is fast.
\n","metadata":{}},{"cell_type":"code","source":"'''AlbumentationsTransform will perform different transforms over both\n the training and validation datasets ''' \nclass AlbumentationsTransform(RandTransform):\n \n '''split_idx is None, which allows for us to say when we're setting our split_idx.\n We set an order to 2 which means any resize operations are done first before our new transform. '''\n split_idx, order = None, 2\n \n def __init__(self, train_aug, valid_aug): store_attr()\n \n # Inherit from RandTransform, allows for us to set that split_idx in our before_call.\n def before_call(self, b, split_idx):\n self.idx = split_idx\n \n # If split_idx is 0, run the trainining augmentation, otherwise run the validation augmentation. \n def encodes(self, img: PILImage):\n if self.idx == 0:\n aug_img = self.train_aug(image=np.array(img))['image']\n else:\n aug_img = self.valid_aug(image=np.array(img))['image']\n return PILImage.create(aug_img)","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:38.841718Z","iopub.execute_input":"2021-07-30T14:07:38.842128Z","iopub.status.idle":"2021-07-30T14:07:38.851587Z","shell.execute_reply.started":"2021-07-30T14:07:38.842079Z","shell.execute_reply":"2021-07-30T14:07:38.850351Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"def get_train_aug(size): \n \n return A.Compose([\n # allows to combine RandomCrop and RandomScale\n A.RandomResizedCrop(size,size),\n \n # Randomly apply affine transforms: translate, scale and rotate the input.\n A.ShiftScaleRotate(p=0.5),\n \n # Randomly change hue, saturation and value of the input image.\n A.HueSaturationValue(hue_shift_limit=0.2, sat_shift_limit=0.2, val_shift_limit=0.2, p=0.5),\n \n # Randomly change brightness and contrast of the input image.\n A.RandomBrightnessContrast(brightness_limit=(-0.1,0.1), contrast_limit=(-0.1, 0.1), p=0.5),\n \n # CoarseDropout of the rectangular regions in the image.\n A.CoarseDropout(p=0.5),\n \n # Cutout of the square regions in the image.\n A.Cutout(p=0.5) ])\n\ndef get_valid_aug(size): \n \n return A.Compose([\n # Crop the central part of the input. \n A.CenterCrop(size, size, p=1.),\n \n # Resize the input to the given height and width. \n A.Resize(size,size)], p=1.)","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:38.853105Z","iopub.execute_input":"2021-07-30T14:07:38.853726Z","iopub.status.idle":"2021-07-30T14:07:38.862517Z","shell.execute_reply.started":"2021-07-30T14:07:38.853679Z","shell.execute_reply":"2021-07-30T14:07:38.861557Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"'''The first step item_tfms resizes all the images to the same size (this happens on the CPU) \n and then batch_tfms happens on the GPU for the entire batch of images. '''\n# Transforms we need to do for each image in the dataset\nitem_tfms = [Resize(224), AlbumentationsTransform(get_train_aug(224), get_valid_aug(224))]\n\n# Transforms that can take place on a batch of images\nbatch_tfms = [Normalize.from_stats(*imagenet_stats)]","metadata":{"_kg_hide-output":true,"execution":{"iopub.status.busy":"2021-07-30T14:07:38.863759Z","iopub.execute_input":"2021-07-30T14:07:38.864326Z","iopub.status.idle":"2021-07-30T14:07:44.612020Z","shell.execute_reply.started":"2021-07-30T14:07:38.864285Z","shell.execute_reply":"2021-07-30T14:07:44.611002Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"
Preprocess and Prepare Dataloader
","metadata":{}},{"cell_type":"code","source":"def get_data(bs=32, data_df=train_df):\n dblock = DataBlock(blocks=(ImageBlock, CategoryBlock),\n splitter=RandomSplitter(seed=42), # split data into training and validation subsets.\n get_x=get_x, # obtain the input images.\n get_y=get_y, # obtain the targets.\n item_tfms = item_tfms,\n batch_tfms = batch_tfms)\n return dblock.dataloaders(data_df,bs=bs)\n\ndls = get_data()\nset_seed(dls, 42)","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:44.613523Z","iopub.execute_input":"2021-07-30T14:07:44.613930Z","iopub.status.idle":"2021-07-30T14:07:55.533227Z","shell.execute_reply.started":"2021-07-30T14:07:44.613890Z","shell.execute_reply":"2021-07-30T14:07:55.532179Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Visualize Stacked CQT Images
","metadata":{}},{"cell_type":"code","source":"# We can call show_batch() to see what a sample of a batch looks like.\ndls.show_batch()","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:55.534735Z","iopub.execute_input":"2021-07-30T14:07:55.535125Z","iopub.status.idle":"2021-07-30T14:07:57.104433Z","shell.execute_reply.started":"2021-07-30T14:07:55.535087Z","shell.execute_reply":"2021-07-30T14:07:57.102531Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"GPU Efficient Networks
\n\n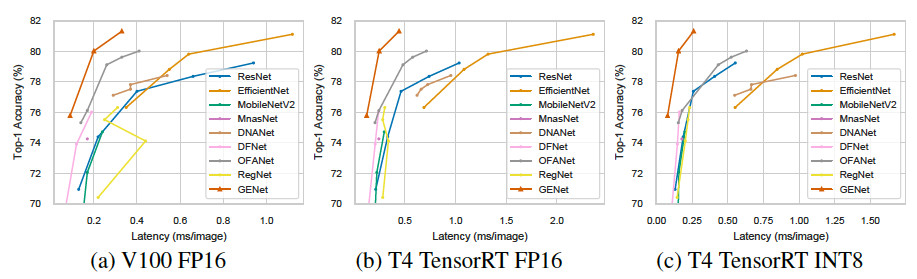\n\n The proposed design space is optimized for fast GPU inference. In this space, it uses a semi-automatic NAS to help us design GPU-Efficient Networks. GENets use full convolutions in low-level stages and depth-wise\nconvolution and/or bottleneck structure in high-level stages.
This design is inspired by the observation that convolutional kernels in the high-level stages are more likely to have low intrinsic rank and different types of convolutions have different kinds of efficiency on GPU.
","metadata":{}},{"cell_type":"code","source":"model = GENet.genet_large(pretrained=True, root='../input/genetparam/')","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:07:57.106131Z","iopub.execute_input":"2021-07-30T14:07:57.107068Z","iopub.status.idle":"2021-07-30T14:08:00.145973Z","shell.execute_reply.started":"2021-07-30T14:07:57.106998Z","shell.execute_reply":"2021-07-30T14:08:00.144915Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"wandb.init(project='G2Net-Fastai', job_type='train', name = 'GPU Efficient Network Large', config = {'competetion': 'G2Net','_wandb_kernel':'tang'})","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:08:00.147583Z","iopub.execute_input":"2021-07-30T14:08:00.147973Z","iopub.status.idle":"2021-07-30T14:08:06.921152Z","shell.execute_reply.started":"2021-07-30T14:08:00.147916Z","shell.execute_reply":"2021-07-30T14:08:06.920184Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Group together some dls, a model, and metrics to handle training\nlearn = Learner(dls, model, metrics = RocAucBinary(), cbs=[WandbCallback(log='all'), SaveModelCallback()]) ","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:08:06.924842Z","iopub.execute_input":"2021-07-30T14:08:06.926609Z","iopub.status.idle":"2021-07-30T14:08:06.936749Z","shell.execute_reply.started":"2021-07-30T14:08:06.925304Z","shell.execute_reply":"2021-07-30T14:08:06.935737Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# Choosing a good learning rate\nlearn.lr_find()","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:08:06.939289Z","iopub.execute_input":"2021-07-30T14:08:06.940352Z","iopub.status.idle":"2021-07-30T14:08:58.948756Z","shell.execute_reply.started":"2021-07-30T14:08:06.940311Z","shell.execute_reply":"2021-07-30T14:08:58.947957Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"# We can use the fine_tune function to train a model with this given learning rate\nlearn.fine_tune(4, base_lr=0.0010000000474974513)","metadata":{"execution":{"iopub.status.busy":"2021-07-30T14:09:07.942087Z","iopub.execute_input":"2021-07-30T14:09:07.942426Z","iopub.status.idle":"2021-07-30T15:06:41.386135Z","shell.execute_reply.started":"2021-07-30T14:09:07.942393Z","shell.execute_reply":"2021-07-30T15:06:41.385212Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"
Check out the Weights and Biases Dashboard here $\\rightarrow$
","metadata":{}},{"cell_type":"markdown","source":"Final Metrics

Prediction Samples

Evaluation Metrics

Submission
Test Time Augmentation (TTA)
\n\n Similar to what Data Augmentation is doing to the training set, the purpose of Test Time Augmentation is to perform random modifications to the test images. Thus, instead of showing the regular, “clean” images, only once to the trained model, we will show it the augmented images several times. We will then average the predictions of each corresponding image and take that as our final guess.
\nThe reason why it works is that, by averaging our predictions, on randomly modified images, we are also averaging the errors. The error can be big in a single vector, leading to a wrong answer, but when averaged, only the correct answer stand out.