{"cells":[{"metadata":{"_uuid":"876f0b63cba53419fbf7527034bf2c5f93885309","_cell_guid":"f5be4ac1-d0a2-442b-ac57-f7b0c764dae9"},"cell_type":"markdown","source":"# Freesound General-Purpose Audio Tagging Challenge\n\n\n\nFreesound is a collaborative database of Creative Commons Licensed sounds. The aim of this competition is to classify audio files that cover real-world sounds from musical instruments, humans, animals, machines, etc. Few of the labels are: `Trumpet`, `Squeak`, `Meow`, `Applause` and `Finger_sapping`. One of the challenges is that not all labels are manually verified. A creative solution should be able to partially rely on these *weak* annotations.\n\nLet's take a tour of the data visualization and model building through this kernel. If you like this work, please show your support by upvotes. Happy Kaggling!\n\n### Contents\n1. [Exploratory Data Analysis](#eda)\n * [Loading data](#loading_data)\n * [Distribution of Categories](#distribution)\n * [Reading Audio Files](#audio_files)\n * [Audio Length](#audio_length)\n2. [Building a Model using Raw Wave](#1d_model_building)\n * [Model Discription](#1d_discription)\n * [Configuration](#configuration)\n * [DataGenerator class](#data_generator)\n * [Normalization](#1d_normalization)\n * [Training 1D Conv](#1d_training)\n * [Ensembling 1D Conv Predictions](#1d_ensembling)\n3. [Introduction to MFCC](#intro_mfcc)\n * [Generating MFCC using Librosa](#librosa_mfcc)\n4. [Building a Model using MFCC](#2d_model_building)\n * [Preparing Data](#2d_data)\n * [Normalization](#2d_normalization)\n * [Training 2D Conv on MFCC](#2d_training)\n * [Ensembling 2D Conv Predictions](#2d_ensembling)\n5. [Ensembling 1D Conv and 2D Conv Predictions](#1d_2d_ensembling)\n6. [Results and Conclusion](#conclusion)\n\n\n\n## 1. Exploratory Data Analysis"},{"metadata":{"_cell_guid":"39ab28e6-67b2-4129-9dbb-846c81ba85f2","_uuid":"d00095bca1801c4058b75e706058a0651808596f","collapsed":true,"trusted":true},"cell_type":"code","source":"# Change this to True to replicate the result\nCOMPLETE_RUN = False","execution_count":43,"outputs":[]},{"metadata":{"_uuid":"4c065a37dd33e869d93ccd8d78daed628e58112b","_cell_guid":"d4905db9-005f-42f0-aa6b-1408acef7371"},"cell_type":"markdown","source":"\n### Loading data"},{"metadata":{"_cell_guid":"5abea3ac-4fa5-4c4f-893f-7f2afa49e523","_kg_hide-output":true,"_uuid":"337e0950ca948be32d5d881c1a3c675ccf7ac523","trusted":true,"collapsed":true},"cell_type":"code","source":"import numpy as np\nnp.random.seed(1001)\n\nimport os\nimport shutil\n\nimport IPython\nimport matplotlib\nimport matplotlib.pyplot as plt\nimport pandas as pd\nimport seaborn as sns\nfrom tqdm import tqdm_notebook\nfrom sklearn.model_selection import StratifiedKFold\n\n%matplotlib inline\nmatplotlib.style.use('ggplot')","execution_count":1,"outputs":[]},{"metadata":{"collapsed":true,"_cell_guid":"97700e3e-82e1-4ce2-9da4-3f8f264e7558","_kg_hide-output":true,"_uuid":"2ca1929548de57afb1c4fde19c10f7b18c64264e","trusted":true},"cell_type":"code","source":"train = pd.read_csv(\"../input/freesound-audio-tagging/train.csv\")\ntest = pd.read_csv(\"../input/freesound-audio-tagging/sample_submission.csv\")","execution_count":3,"outputs":[]},{"metadata":{"_cell_guid":"a418ce4d-b104-4710-b50d-e9ab1e7e420f","_kg_hide-output":true,"_uuid":"1acc16aa65e8f39a5abd8b60906740a671659f1b","trusted":true},"cell_type":"code","source":"train.head(10)","execution_count":7,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"37095374c676d40e81d2327bdddecd004fdcf675"},"cell_type":"code","source":"test.head()","execution_count":5,"outputs":[]},{"metadata":{"_cell_guid":"afceb447-9a8f-4cc4-a7b2-eabc75c3f0aa","_kg_hide-output":true,"_uuid":"dad27c6a5ef1fdad658ce710fe16fca58c75a05c","scrolled":true,"trusted":true},"cell_type":"code","source":"print(\"Number of training examples=\", train.shape[0], \" Number of classes=\", len(train.label.unique()))","execution_count":6,"outputs":[]},{"metadata":{"_cell_guid":"99b8ebbd-aa18-427a-ab33-e88553a564f6","_kg_hide-output":true,"_uuid":"0c3e7629b5e60cfad2a7e1681dcf6e7c55c92e43","trusted":true},"cell_type":"code","source":"print(train.label.unique())","execution_count":8,"outputs":[]},{"metadata":{"_uuid":"2edb326e66f4c699bd3cc5ec43279d40e7777180","_cell_guid":"008c5a97-9c50-4a52-9b65-568986f9bbd6"},"cell_type":"markdown","source":"\n### Distribution of Categories"},{"metadata":{"trusted":true,"scrolled":true,"_uuid":"f44d3c7ddd0ada659b6f4742c910a280bad8c25a"},"cell_type":"code","source":"category_group.unstack()","execution_count":14,"outputs":[]},{"metadata":{"_cell_guid":"67e5b2e9-cee7-4bf0-84d4-b79bfa6928fd","_uuid":"fef9ca7602b65d3637884eddd38fa5f01a530e81","scrolled":false,"trusted":true},"cell_type":"code","source":"category_group = train.groupby(['label', 'manually_verified']).count()\nplot = category_group.unstack().reindex(category_group.unstack().sum(axis=1).sort_values().index)\\\n .plot(kind='bar', stacked=True, title=\"Number of Audio Samples per Category\", figsize=(16,10))\nplot.set_xlabel(\"Category\")\nplot.set_ylabel(\"Number of Samples\");","execution_count":25,"outputs":[]},{"metadata":{"_cell_guid":"29538dc2-387a-4910-a203-f105c97ce0e6","_kg_hide-output":true,"_uuid":"c2ca61efa1696baa87f831f7df927fd1cba7abbf","trusted":true},"cell_type":"code","source":"print('Minimum samples per category = ', min(train.label.value_counts()))\nprint('Maximum samples per category = ', max(train.label.value_counts()))","execution_count":26,"outputs":[]},{"metadata":{"_uuid":"d0ed18e06d39f962d1a2a58f4743171c9c4970e9","_cell_guid":"a715d812-98fc-459a-8695-13940b2ca1de"},"cell_type":"markdown","source":"We observe that:\n1. The number of audio samples per category is **non-nform**. The minimum number of audio samples in a category is `94` while the maximum is `300`\n2. Also, the proportion of `maually_verified` labels per category is non-uniform.\n\n### Reading Audio Files\n\nThe audios are [Pulse-code modulated](https://en.wikipedia.org/wiki/Audio_bit_depth) with a [bit depth](https://en.wikipedia.org/wiki/Audio_bit_depth) of 16 and a [sampling rate](https://en.wikipedia.org/wiki/Sampling_%28signal_processing%29) of 44.1 kHz\n\n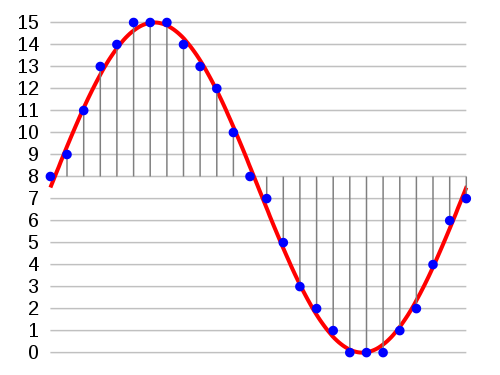\n\n* **Bit-depth = 16**: The amplitude of each sample in the audio is one of 2^16 (=65536) possible values. \n* **Samplig rate = 44.1 kHz**: Each second in the audio consists of 44100 samples. So, if the duration of the audio file is 3.2 seconds, the audio will consist of 44100\\*3.2 = 141120 values.\n\nLet's listen to an audio file in our dataset and load it to a numpy array"},{"metadata":{"_cell_guid":"20d2c517-01f9-46a9-b339-6ce415bc59d2","_uuid":"e15d81dcb2a4433b94182eb588ccb183e27fa700","trusted":true},"cell_type":"code","source":"import IPython.display as ipd # To play sound in the notebook\nfname = '../input/freesound-audio-tagging/audio_train/' + '00044347.wav' # Hi-hat\nipd.Audio(fname)","execution_count":29,"outputs":[]},{"metadata":{"_cell_guid":"efe10cb8-13f1-405e-8b71-ca5758ee18d4","_uuid":"101f9997c5c8cd0392c1f367684331d3f6e80422","trusted":true},"cell_type":"code","source":"# Using wave library\nimport wave\nwav = wave.open(fname)\nprint(\"Sampling (frame) rate = \", wav.getframerate())\nprint(\"Total samples (frames) = \", wav.getnframes())\nprint(\"Duration = \", wav.getnframes()/wav.getframerate())","execution_count":30,"outputs":[]},{"metadata":{"_cell_guid":"3c9f1564-fa50-4f4b-87d9-2070fc44770d","_uuid":"e4ea69354f032c0b511b50693c750e19fb4f6cb3","trusted":true},"cell_type":"code","source":"# Using scipy\nfrom scipy.io import wavfile\nrate, data = wavfile.read(fname)\nprint(\"Sampling (frame) rate = \", rate)\nprint(\"Total samples (frames) = \", data.shape)\nprint(data)","execution_count":31,"outputs":[]},{"metadata":{"_uuid":"bacb576c223074c03d0cb5c55b917df2e1261498","_cell_guid":"3c6c2a6f-4914-4e13-84be-6b8492487c7b"},"cell_type":"markdown","source":"Let's plot the audio frames"},{"metadata":{"_cell_guid":"eeb3e8ab-106f-4e67-84fd-7bf8c9847c8e","_uuid":"a1e25d48f74b38784d7588e5c33af9b03248e7d3","scrolled":false,"trusted":true},"cell_type":"code","source":"plt.plot(data, '-', );","execution_count":32,"outputs":[]},{"metadata":{"_uuid":"762301b9c5d7653d761205e172ff3da88745400f","_cell_guid":"79293dfd-e254-47f3-8909-ff32f08f87aa"},"cell_type":"markdown","source":"Let's zoom in on first 1000 frames"},{"metadata":{"_cell_guid":"bfb06a3e-b501-4570-89ea-008781414144","_uuid":"7c1b21e52e83d0bc723a48a32ced87445a540fa9","trusted":true},"cell_type":"code","source":"plt.figure(figsize=(16, 4))\nplt.plot(data[:500], '.'); plt.plot(data[:500], '-');","execution_count":33,"outputs":[]},{"metadata":{"_uuid":"b3a730fc5ee4a9ab5904cddda84a05ac118c749d","_cell_guid":"42761f3d-0d20-4a97-843a-02186299f76b"},"cell_type":"markdown","source":"\n### Audio Length\n\nWe shall now analyze the lengths of the audio files in our dataset"},{"metadata":{"_cell_guid":"40b7ba05-45df-4779-be29-b177b9b9b8e1","_uuid":"867f0074922314b78de6bd9d14b308b634d1fbbe","scrolled":false,"trusted":true},"cell_type":"code","source":"train['nframes'] = train['fname'].apply(lambda f: wave.open('../input/freesound-audio-tagging/audio_train/' + f).getnframes())\ntest['nframes'] = test['fname'].apply(lambda f: wave.open('../input/freesound-audio-tagging/audio_test/' + f).getnframes())\n\n_, ax = plt.subplots(figsize=(16, 4))\nsns.violinplot(ax=ax, x=\"label\", y=\"nframes\", data=train)\nplt.xticks(rotation=90)\nplt.title('Distribution of audio frames, per label', fontsize=16)\nplt.show()","execution_count":36,"outputs":[]},{"metadata":{"trusted":true,"_uuid":"2c7baf8a829b1954bfb12fdaf52534fdc4fb4814"},"cell_type":"code","source":"train.head(10)","execution_count":38,"outputs":[]},{"metadata":{"_uuid":"92ea60bb1827c9ec4dd261d015739dde762f9b18","_cell_guid":"fa8fa2bd-359c-4f53-b94b-67a6c1acde64"},"cell_type":"markdown","source":"We observe:\n1. The distribution of audio length across labels is non-uniform and has high variance.\n\nLet's now analyze the frame length distribution in Train and Test."},{"metadata":{"_cell_guid":"e49045f1-7c44-4f1a-b740-d45ec3b6b321","_uuid":"0ec5676601b04e3fdbae4052122c9db1a68251a9","trusted":true},"cell_type":"code","source":"fig, axes = plt.subplots(nrows=1, ncols=2, figsize=(16,5))\ntrain.nframes.hist(bins=100, ax=axes[0])\ntest.nframes.hist(bins=100, ax=axes[1])\nplt.suptitle('Frame Length Distribution in Train and Test', ha='center', fontsize='large');","execution_count":39,"outputs":[]},{"metadata":{"_uuid":"3e517330a7209f25fa69056db1214f27fb585824","_cell_guid":"72c8dc2d-8385-4f74-8820-8d805fee8dc0"},"cell_type":"markdown","source":"We observe:\n1. Majority of the audio files are short.\n1. There are four `abnormal` length in the test histogram. Let's analyze them."},{"metadata":{"_cell_guid":"f36e006f-fb47-4134-94a8-aede32f770ad","_uuid":"8495f1f7fdaffa09623458aa66803c6a2e156537","scrolled":true,"trusted":true},"cell_type":"code","source":"abnormal_length = [707364, 353682, 138474, 184338]\n\nfor length in abnormal_length:\n abnormal_fnames = test.loc[test.nframes == length, 'fname'].values\n print(\"Frame length = \", length, \" Number of files = \", abnormal_fnames.shape[0], end=\" \")\n fname = np.random.choice(abnormal_fnames)\n print(\"Playing \", fname)\n IPython.display.display(ipd.Audio( '../input/freesound-audio-tagging/audio_test/' + fname))","execution_count":41,"outputs":[]},{"metadata":{"_uuid":"64462b38a986a2f40deeb6a053b9d99d8f6993b5","_cell_guid":"146baca0-66cc-4ce1-8d16-16ae5764a354"},"cell_type":"markdown","source":"\n## 2. Building a Model using Raw Wave\nWe will build two models:\n1. The first model will take the raw audio (1D array) as input and the primary operation will be Conv1D\n2. The second model will take the MFCCs as input. (We will explain MFCC later)\n\n\n### Keras Model using raw wave\n\nOur model has the architecture as follows:\n\n\n**Important:**\nDue to the time limit on Kaggle Kernels, it is not possible to perform 10-fold training of a large model. I have trained the model locally and uploaded its output files as a dataset. If you wish to train the bigger model, change `COMPLETE_RUN = True` at the beginning of the kernel."},{"metadata":{"_cell_guid":"0ef1062c-be8a-4021-a50a-3df9bacd30fc","_uuid":"2df0e6e509896eaefd30f6b4c15b55736760aafa","collapsed":true},"cell_type":"markdown","source":"#### Some sssential imports"},{"metadata":{"_cell_guid":"58fbb75c-1ef8-478f-a5fd-3fe6cfda32af","_kg_hide-output":true,"_uuid":"36454f818dcbe02852e7a639d428a004a387ce9f","trusted":true},"cell_type":"code","source":"import librosa\nimport numpy as np\nimport scipy\nfrom keras import losses, models, optimizers\nfrom keras.activations import relu, softmax\nfrom keras.callbacks import (EarlyStopping, LearningRateScheduler,\n ModelCheckpoint, TensorBoard, ReduceLROnPlateau)\nfrom keras.layers import (Convolution1D, Dense, Dropout, GlobalAveragePooling1D, \n GlobalMaxPool1D, Input, MaxPool1D, concatenate)\nfrom keras.utils import Sequence, to_categorical","execution_count":42,"outputs":[]},{"metadata":{"_uuid":"927b4d615e24291f3c9510b653e723dc031fd042","_cell_guid":"64df4fea-4917-4762-b9be-68163f590c13"},"cell_type":"markdown","source":"\n#### Configuration"},{"metadata":{"_uuid":"a9dc3968c8915e1d96f0bc011e67db26932ab0a3","_cell_guid":"1dda9e10-5b51-430a-b20d-a319695df25d"},"cell_type":"markdown","source":"The Configuration object stores those learning parameters that are shared between data generators, models, and training functions. Anything that is `global` as far as the training is concerned can become the part of Configuration object."},{"metadata":{"_cell_guid":"e0836104-1a4d-485d-9cc1-3e5b82f449de","_uuid":"66640745984135b853d36eac127fb2da302319ad","collapsed":true,"trusted":true},"cell_type":"code","source":"class Config(object):\n def __init__(self,\n sampling_rate=16000, audio_duration=2, n_classes=41,\n use_mfcc=False, n_folds=10, learning_rate=0.0001, \n max_epochs=50, n_mfcc=20):\n self.sampling_rate = sampling_rate\n self.audio_duration = audio_duration\n self.n_classes = n_classes\n self.use_mfcc = use_mfcc\n self.n_mfcc = n_mfcc\n self.n_folds = n_folds\n self.learning_rate = learning_rate\n self.max_epochs = max_epochs\n\n self.audio_length = self.sampling_rate * self.audio_duration\n if self.use_mfcc:\n self.dim = (self.n_mfcc, 1 + int(np.floor(self.audio_length/512)), 1)\n else:\n self.dim = (self.audio_length, 1)","execution_count":44,"outputs":[]},{"metadata":{"_cell_guid":"dbdcf3fb-f915-482c-ad8f-d8578de8f080","_uuid":"b1a794352ac7505abcf212d1b1c6deef32178ab3","collapsed":true},"cell_type":"markdown","source":"\n#### DataGenerator Class"},{"metadata":{"_uuid":"f1a0716a545ade83970005951719e71cebe35ab2","_cell_guid":"059d4658-f1a4-4d6a-ae67-05140fc9bac6"},"cell_type":"markdown","source":"The DataGenerator class inherits from **`keras.utils.Sequence`** . It is useful for preprocessing and feeding the data to a Keras model. \n* Once initialized with a batch_size, it computes the number of batches in an epoch. The **`__len__`** method tells Keras how many batches to draw in each epoch. \n* The **`__getitem__`** method takes an index (which is the batch number) and returns a batch of the data (both X and y) after calculating the offset. During test time, only `X` is returned.\n* If we want to perform some action after each epoch (like shuffle the data, or increase the proportion of augmented data), we can use the **`on_epoch_end`** method.\n\nNote:\n**`Sequence`** are a safer way to do multiprocessing. This structure guarantees that the network will only train once on each sample per epoch which is not the case with generators."},{"metadata":{"_cell_guid":"f9d14e7d-89d8-42f0-9eb3-f895645b2de2","_uuid":"aca30bc0f6fccf71e4b9a68e5c04c1aaf950b169","collapsed":true,"trusted":true},"cell_type":"code","source":"class DataGenerator(Sequence):\n def __init__(self, config, data_dir, list_IDs, labels=None, \n batch_size=64, preprocessing_fn=lambda x: x):\n self.config = config\n self.data_dir = data_dir\n self.list_IDs = list_IDs\n self.labels = labels\n self.batch_size = batch_size\n self.preprocessing_fn = preprocessing_fn\n self.on_epoch_end()\n self.dim = self.config.dim\n\n def __len__(self):\n return int(np.ceil(len(self.list_IDs) / self.batch_size))\n\n def __getitem__(self, index):\n indexes = self.indexes[index*self.batch_size:(index+1)*self.batch_size]\n list_IDs_temp = [self.list_IDs[k] for k in indexes]\n return self.__data_generation(list_IDs_temp)\n\n def on_epoch_end(self):\n self.indexes = np.arange(len(self.list_IDs))\n\n def __data_generation(self, list_IDs_temp):\n cur_batch_size = len(list_IDs_temp)\n X = np.empty((cur_batch_size, *self.dim))\n\n input_length = self.config.audio_length\n for i, ID in enumerate(list_IDs_temp):\n file_path = self.data_dir + ID\n \n # Read and Resample the audio\n data, _ = librosa.core.load(file_path, sr=self.config.sampling_rate,\n res_type='kaiser_fast')\n\n # Random offset / Padding\n if len(data) > input_length:\n max_offset = len(data) - input_length\n offset = np.random.randint(max_offset)\n data = data[offset:(input_length+offset)]\n else:\n if input_length > len(data):\n max_offset = input_length - len(data)\n offset = np.random.randint(max_offset)\n else:\n offset = 0\n data = np.pad(data, (offset, input_length - len(data) - offset), \"constant\")\n \n # Normalization + Other Preprocessing\n if self.config.use_mfcc:\n data = librosa.feature.mfcc(data, sr=self.config.sampling_rate,\n n_mfcc=self.config.n_mfcc)\n data = np.expand_dims(data, axis=-1)\n else:\n data = self.preprocessing_fn(data)[:, np.newaxis]\n X[i,] = data\n\n if self.labels is not None:\n y = np.empty(cur_batch_size, dtype=int)\n for i, ID in enumerate(list_IDs_temp):\n y[i] = self.labels[ID]\n return X, to_categorical(y, num_classes=self.config.n_classes)\n else:\n return X","execution_count":45,"outputs":[]},{"metadata":{"_uuid":"6b69d10980c7aad004c6a7fa860c649d0b875a0f","_cell_guid":"49a23330-291d-4eb7-aeb9-4abcfd648277"},"cell_type":"markdown","source":"\n#### Normalization\n\nNormalization is a crucial preprocessing step. The simplest method is rescaling the range of features to scale the range in [0, 1]. "},{"metadata":{"_cell_guid":"bb5936dd-5fb1-4894-8165-6daf372a6832","_uuid":"c9db10ad526815730a6e5a1f057de8c9bff12615","collapsed":true,"trusted":true},"cell_type":"code","source":"def audio_norm(data):\n max_data = np.max(data)\n min_data = np.min(data)\n data = (data-min_data)/(max_data-min_data+1e-6)\n return data-0.5","execution_count":46,"outputs":[]},{"metadata":{"_uuid":"c2f0bbd810926b309d3b02473e937a2a86bc9005","_cell_guid":"3b9656b0-31d3-47ea-9bb3-789a40026793"},"cell_type":"markdown","source":"* The dummy model is just for debugging purpose.\n* Our 1D Conv model is fairly deep and is trained using Adam Optimizer with a learning rate of 0.0001"},{"metadata":{"_cell_guid":"245887b3-a0dc-498d-900c-dd1c2898d955","_uuid":"40771630994b93eee040c239f1c0e3bf88f13ced","collapsed":true,"trusted":true},"cell_type":"code","source":"def get_1d_dummy_model(config):\n \n nclass = config.n_classes\n input_length = config.audio_length\n \n inp = Input(shape=(input_length,1))\n x = GlobalMaxPool1D()(inp)\n out = Dense(nclass, activation=softmax)(x)\n\n model = models.Model(inputs=inp, outputs=out)\n opt = optimizers.Adam(config.learning_rate)\n\n model.compile(optimizer=opt, loss=losses.categorical_crossentropy, metrics=['acc'])\n return model\n\ndef get_1d_conv_model(config):\n \n nclass = config.n_classes\n input_length = config.audio_length\n \n inp = Input(shape=(input_length,1))\n x = Convolution1D(16, 9, activation=relu, padding=\"valid\")(inp)\n x = Convolution1D(16, 9, activation=relu, padding=\"valid\")(x)\n x = MaxPool1D(16)(x)\n x = Dropout(rate=0.1)(x)\n \n x = Convolution1D(32, 3, activation=relu, padding=\"valid\")(x)\n x = Convolution1D(32, 3, activation=relu, padding=\"valid\")(x)\n x = MaxPool1D(4)(x)\n x = Dropout(rate=0.1)(x)\n \n x = Convolution1D(32, 3, activation=relu, padding=\"valid\")(x)\n x = Convolution1D(32, 3, activation=relu, padding=\"valid\")(x)\n x = MaxPool1D(4)(x)\n x = Dropout(rate=0.1)(x)\n \n x = Convolution1D(256, 3, activation=relu, padding=\"valid\")(x)\n x = Convolution1D(256, 3, activation=relu, padding=\"valid\")(x)\n x = GlobalMaxPool1D()(x)\n x = Dropout(rate=0.2)(x)\n\n x = Dense(64, activation=relu)(x)\n x = Dense(1028, activation=relu)(x)\n out = Dense(nclass, activation=softmax)(x)\n\n model = models.Model(inputs=inp, outputs=out)\n opt = optimizers.Adam(config.learning_rate)\n\n model.compile(optimizer=opt, loss=losses.categorical_crossentropy, metrics=['acc'])\n return model","execution_count":47,"outputs":[]},{"metadata":{"_uuid":"32afe89ebdee366de311a6fffb5c49a0e568aaa8","_cell_guid":"2e67aa4a-f2d0-4889-a1da-b6d3217edb5e"},"cell_type":"markdown","source":"\n#### Training 1D Conv"},{"metadata":{"_uuid":"ddbcf58975c5cd7436314a77e5b8f938640bcf34","_cell_guid":"a93de421-33be-4104-bcfa-b581cbde3d75"},"cell_type":"markdown","source":"It is important to convert raw labels to integer indices"},{"metadata":{"_cell_guid":"e9027035-0e77-47dd-8616-113c1cfb37e0","_uuid":"53aca10261dea0b8357e39adb513c7689b7c07ff","collapsed":true,"trusted":true},"cell_type":"code","source":"LABELS = list(train.label.unique())\nlabel_idx = {label: i for i, label in enumerate(LABELS)}\ntrain.set_index(\"fname\", inplace=True)\ntest.set_index(\"fname\", inplace=True)\ntrain[\"label_idx\"] = train.label.apply(lambda x: label_idx[x])\nif not COMPLETE_RUN:\n train = train[:2000]\n test = test[:2000]","execution_count":48,"outputs":[]},{"metadata":{"_cell_guid":"f2f2dc50-77d3-43ba-bf7f-3c6b39beb67b","_uuid":"604a3c7971599898b5614a67da12da84ab651a55","collapsed":true,"trusted":true},"cell_type":"code","source":"config = Config(sampling_rate=16000, audio_duration=2, n_folds=10, learning_rate=0.001)\nif not COMPLETE_RUN:\n config = Config(sampling_rate=100, audio_duration=1, n_folds=2, max_epochs=1)","execution_count":49,"outputs":[]},{"metadata":{"_uuid":"7a2a5e44d82a2b9e04117b76464225278ec4a1d8","_cell_guid":"e31b98ec-cecb-4584-9bbc-bc2748476b49"},"cell_type":"markdown","source":"Here is the code for 10-fold training:\n* We use **`from sklearn.cross_validation.StratifiedKFold`** for splitting the trainig data into 10 folds.\n* We use some Keras callbacks to monitor the training.\n * **`ModelCheckpoint`** saves the best weight of our model (using validation data). We use this weight to make test predictions.\n * **`EarlyStopping`** stops the training once validation loss ceases to decrease\n * **`TensorBoard`** helps us visualize training and validation loss and accuracy.\n* We fit the model using **`DataGenerator`** for training and validation splits. \n* We get both training and test predictions and save them as .npy format. We also generate a submission file. For 10-fold CV, the number of prediction files should be 10. We will ensemble these predictions later."},{"metadata":{"collapsed":true,"_cell_guid":"e81537d9-d886-4bd5-a923-7efe1aa1812d","_kg_hide-output":true,"_uuid":"1e68d5ae8e431445151c8c7744fadb65fbf692c8"},"cell_type":"markdown","source":"```python\nPREDICTION_FOLDER = \"predictions_1d_conv\"\nif not os.path.exists(PREDICTION_FOLDER):\n os.mkdir(PREDICTION_FOLDER)\nif os.path.exists('logs/' + PREDICTION_FOLDER):\n shutil.rmtree('logs/' + PREDICTION_FOLDER)\n\nskf = StratifiedKFold(train.label_idx, n_folds=config.n_folds)\n\nfor i, (train_split, val_split) in enumerate(skf):\n train_set = train.iloc[train_split]\n val_set = train.iloc[val_split]\n checkpoint = ModelCheckpoint('best_%d.h5'%i, monitor='val_loss', verbose=1, save_best_only=True)\n early = EarlyStopping(monitor=\"val_loss\", mode=\"min\", patience=5)\n tb = TensorBoard(log_dir='./logs/' + PREDICTION_FOLDER + '/fold_%d'%i, write_graph=True)\n\n callbacks_list = [checkpoint, early, tb]\n print(\"Fold: \", i)\n print(\"#\"*50)\n if COMPLETE_RUN:\n model = get_1d_conv_model(config)\n else:\n model = get_1d_dummy_model(config)\n\n train_generator = DataGenerator(config, '../input/freesound-audio-tagging/audio_train/', train_set.index, \n train_set.label_idx, batch_size=64,\n preprocessing_fn=audio_norm)\n val_generator = DataGenerator(config, '../input/freesound-audio-tagging/audio_train/', val_set.index, \n val_set.label_idx, batch_size=64,\n preprocessing_fn=audio_norm)\n \n history = model.fit_generator(train_generator, callbacks=callbacks_list, validation_data=val_generator,\n epochs=config.max_epochs, use_multiprocessing=True, workers=6, max_queue_size=20)\n \n model.load_weights('best_%d.h5'%i)\n \n # Save train predictions\n train_generator = DataGenerator(config, '../input/freesound-audio-tagging/audio_train/', train.index, batch_size=128,\n preprocessing_fn=audio_norm)\n predictions = model.predict_generator(train_generator, use_multiprocessing=True, \n workers=6, max_queue_size=20, verbose=1)\n np.save(PREDICTION_FOLDER + \"/train_predictions_%d.npy\"%i, predictions)\n \n # Save test predictions\n test_generator = DataGenerator(config, '../input/freesound-audio-tagging/audio_test/', test.index, batch_size=128,\n preprocessing_fn=audio_norm)\n predictions = model.predict_generator(test_generator, use_multiprocessing=True, \n workers=6, max_queue_size=20, verbose=1)\n np.save(PREDICTION_FOLDER + \"/test_predictions_%d.npy\"%i, predictions)\n \n # Make a submission file\n top_3 = np.array(LABELS)[np.argsort(-predictions, axis=1)[:, :3]]\n predicted_labels = [' '.join(list(x)) for x in top_3]\n test['label'] = predicted_labels\n test[['label']].to_csv(PREDICTION_FOLDER + \"/predictions_%d.csv\"%i)\n ```"},{"metadata":{"_uuid":"2afcdcf0f77f8685f57e2d119ec0cc650b7255d7","_cell_guid":"488df4a9-b090-4397-a649-2e94f9ee82ad"},"cell_type":"markdown","source":"\n#### Ensembling 1D Conv Predictions\nNow that we have trained our model, it is time average the predictions of 10-folds. We will try Geometric Mean averaging and see what will be our Public LB score."},{"metadata":{"collapsed":true,"_cell_guid":"4050aede-678b-4f9e-bb95-e70f79e4f6bd","_kg_hide-output":true,"_uuid":"bfdddecb92be07d06e71d25b1812d064a0cee66d","trusted":true},"cell_type":"code","source":"pred_list = []\nfor i in range(10):\n pred_list.append(np.load(\"../input/freesound-prediction-file/test_predictions_%d.npy\"%i))\nprediction = np.ones_like(pred_list[0])\nfor pred in pred_list:\n prediction = prediction*pred\nprediction = prediction**(1./len(pred_list))\n# Make a submission file\ntop_3 = np.array(LABELS)[np.argsort(-prediction, axis=1)[:, :3]]\npredicted_labels = [' '.join(list(x)) for x in top_3]\ntest = pd.read_csv('../input/freesound-audio-tagging/sample_submission.csv')\ntest['label'] = predicted_labels\ntest[['fname', 'label']].to_csv(\"1d_conv_ensembled_submission.csv\", index=False)","execution_count":50,"outputs":[]},{"metadata":{"_uuid":"40ef0374888d1453eed07c8daa18f231c12ef36d","_cell_guid":"8c437de1-ecc0-4c72-9595-c689c101a72c"},"cell_type":"markdown","source":"\n## 3. Introuction to MFCC\n\nAs we have seen in the previous section, our Deep Learning models are powerful enough to classify sounds from the raw audio. We do not require any complex feature engineering. But before the Deep Learning era, people developed techniques to extract features from audio signals. It turns out that these techniques are still useful. One such technique is computing the MFCC (Mel Frquency Cepstral Coefficients) from the raw audio. Before we jump to MFCC, let's talk about extracting features from the sound.\n\nIf we just want to classify some sound, we should build features that are **speaker independent**. Any feature that only gives information about the speaker (like the pitch of their voice) will not be helpful for classification. In other words, we should extract features that depend on the \"content\" of the audio rather than the nature of the speaker. Also, a good feature extraction technique should mimic the human speech perception. We don't hear loudness on a linear scale. If we want to double the perceived loudness of a sound, we have to put 8 times as much energy into it. Instead of a linear scale, our perception system uses a log scale. \n\nTaking these things into account, Davis and Mermelstein came up with MFCC in the 1980's. MFCC mimics the logarithmic perception of loudness and pitch of human auditory system and tries to eliminate speaker dependent characteristics by excluding the fundamental frequency and their harmonics. The underlying mathematics is quite complicated and we will skip that. For those interested, here is the [detailed explanation](http://practicalcryptography.com/miscellaneous/machine-learning/guide-mel-frequency-cepstral-coefficients-mfccs/).\n\n\n\n\n#### Generating MFCC using Librosa\nThe library librosa has a function to calculate MFCC. Let's compute the MFCC of an audio file and visualize it."},{"metadata":{"_cell_guid":"dcb2a6e7-b086-4d1a-94a4-215f2cb101d0","_uuid":"2f8dfd08f109ababeaca9ce900b68b8a716d28b7","collapsed":true,"trusted":true},"cell_type":"code","source":"import librosa\nSAMPLE_RATE = 44100\nfname = '../input/freesound-audio-tagging/audio_train/' + '00044347.wav' # Hi-hat\nwav, _ = librosa.core.load(fname, sr=SAMPLE_RATE)\nwav = wav[:2*44100]","execution_count":51,"outputs":[]},{"metadata":{"_cell_guid":"6250242e-e3c5-4cb9-8405-43d3279dada1","_kg_hide-output":true,"_uuid":"7498089442d866816aabc85234a8a5546c5e58da","trusted":true},"cell_type":"code","source":"mfcc = librosa.feature.mfcc(wav, sr = SAMPLE_RATE, n_mfcc=40)\nmfcc.shape","execution_count":52,"outputs":[]},{"metadata":{"_cell_guid":"d02be92a-f208-42c2-ac4a-e0b2b22ba195","_uuid":"f4054a6856eaa16cf82cacb5bd08ea53cdab386b","trusted":true},"cell_type":"code","source":"plt.imshow(mfcc, cmap='hot', interpolation='nearest');","execution_count":53,"outputs":[]},{"metadata":{"_uuid":"59502f44b22674250a047e89b610867d6c6306c3","_cell_guid":"5015b22f-5de8-4a86-aef4-074bf90023aa"},"cell_type":"markdown","source":"\n## 4. Building a Model using MFCC\n\nWe will build now build a 2D Convolutional model using MFCC. "},{"metadata":{"collapsed":true,"_cell_guid":"384fe65d-fe10-4eee-826c-75c4dffcfa2d","_kg_hide-output":true,"_uuid":"ed54039a4e0b91d10f603799feb8166404bbceec","trusted":false},"cell_type":"code","source":"from keras.layers import (Convolution2D, GlobalAveragePooling2D, BatchNormalization, Flatten,\n GlobalMaxPool2D, MaxPool2D, concatenate, Activation)\nfrom keras.utils import Sequence, to_categorical\nfrom keras import backend as K","execution_count":null,"outputs":[]},{"metadata":{"_cell_guid":"97d07753-d78d-465d-936d-7f03eaf1def1","_uuid":"0b2ac601f52ae4ed9dc849fcd095ab94cfe878fe","collapsed":true,"trusted":false},"cell_type":"code","source":"def get_2d_dummy_model(config):\n \n nclass = config.n_classes\n \n inp = Input(shape=(config.dim[0],config.dim[1],1))\n x = GlobalMaxPool2D()(inp)\n out = Dense(nclass, activation=softmax)(x)\n\n model = models.Model(inputs=inp, outputs=out)\n opt = optimizers.Adam(config.learning_rate)\n\n model.compile(optimizer=opt, loss=losses.categorical_crossentropy, metrics=['acc'])\n return model\n\n\ndef get_2d_conv_model(config):\n \n nclass = config.n_classes\n \n inp = Input(shape=(config.dim[0],config.dim[1],1))\n x = Convolution2D(32, (4,10), padding=\"same\")(inp)\n x = BatchNormalization()(x)\n x = Activation(\"relu\")(x)\n x = MaxPool2D()(x)\n \n x = Convolution2D(32, (4,10), padding=\"same\")(x)\n x = BatchNormalization()(x)\n x = Activation(\"relu\")(x)\n x = MaxPool2D()(x)\n \n x = Convolution2D(32, (4,10), padding=\"same\")(x)\n x = BatchNormalization()(x)\n x = Activation(\"relu\")(x)\n x = MaxPool2D()(x)\n \n x = Convolution2D(32, (4,10), padding=\"same\")(x)\n x = BatchNormalization()(x)\n x = Activation(\"relu\")(x)\n x = MaxPool2D()(x)\n\n x = Flatten()(x)\n x = Dense(64)(x)\n x = BatchNormalization()(x)\n x = Activation(\"relu\")(x)\n out = Dense(nclass, activation=softmax)(x)\n\n model = models.Model(inputs=inp, outputs=out)\n opt = optimizers.Adam(config.learning_rate)\n\n model.compile(optimizer=opt, loss=losses.categorical_crossentropy, metrics=['acc'])\n return model","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"d88e90fdc36c77c10ecc8f674d6fd39c8e4d78fb","_cell_guid":"c0c823de-9971-4247-9501-dc74d2f95d8e"},"cell_type":"markdown","source":"\n### Preparing data"},{"metadata":{"_cell_guid":"eb5aef7d-669b-4cde-9e09-a2bfaa379cc9","_uuid":"70b8cd145ae3838c7974fe257403c8c7fbc8552a","collapsed":true,"trusted":false},"cell_type":"code","source":"config = Config(sampling_rate=44100, audio_duration=2, n_folds=10, \n learning_rate=0.001, use_mfcc=True, n_mfcc=40)\nif not COMPLETE_RUN:\n config = Config(sampling_rate=44100, audio_duration=2, n_folds=2, \n max_epochs=1, use_mfcc=True, n_mfcc=40)","execution_count":null,"outputs":[]},{"metadata":{"_cell_guid":"5b9b1c9b-7e02-46f3-96f6-67ebc9bf9132","_uuid":"5242e943f1bc1154d19c03c361a826553c811cfe","collapsed":true,"trusted":false},"cell_type":"code","source":"def prepare_data(df, config, data_dir):\n X = np.empty(shape=(df.shape[0], config.dim[0], config.dim[1], 1))\n input_length = config.audio_length\n for i, fname in enumerate(df.index):\n print(fname)\n file_path = data_dir + fname\n data, _ = librosa.core.load(file_path, sr=config.sampling_rate, res_type=\"kaiser_fast\")\n\n # Random offset / Padding\n if len(data) > input_length:\n max_offset = len(data) - input_length\n offset = np.random.randint(max_offset)\n data = data[offset:(input_length+offset)]\n else:\n if input_length > len(data):\n max_offset = input_length - len(data)\n offset = np.random.randint(max_offset)\n else:\n offset = 0\n data = np.pad(data, (offset, input_length - len(data) - offset), \"constant\")\n\n data = librosa.feature.mfcc(data, sr=config.sampling_rate, n_mfcc=config.n_mfcc)\n data = np.expand_dims(data, axis=-1)\n X[i,] = data\n return X","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"bb3bc487b52a549a856807dd838a4f6cd209917d","_cell_guid":"c9910de1-388b-470e-8908-6df548f1b866"},"cell_type":"markdown","source":"```python\nX_train = prepare_data(train, config, '../input/freesound-audio-tagging/audio_train/')\nX_test = prepare_data(test, config, '../input/freesound-audio-tagging/audio_test/')\ny_train = to_categorical(train.label_idx, num_classes=config.n_classes)\n```"},{"metadata":{"_uuid":"89e8bd3dc6d1f432309e668685fb98d1ce866e95","_cell_guid":"a0e0b17b-d2f8-47f8-9b4d-fff3b2761dde"},"cell_type":"markdown","source":"\n#### Normalization\n"},{"metadata":{"_uuid":"60b6d9dfcb25eb9b3cef7e05675d67b104e24b31","_cell_guid":"928b0993-7799-4b75-bef8-c1df3755632e"},"cell_type":"markdown","source":"```python\nmean = np.mean(X_train, axis=0)\nstd = np.std(X_train, axis=0)\n\nX_train = (X_train - mean)/std\nX_test = (X_test - mean)/std\n```"},{"metadata":{"_uuid":"b70fea949114595111c39f9f64fb1752603e3fdf","_cell_guid":"af8afd09-66bf-4618-ad95-d70db35b90ec"},"cell_type":"markdown","source":"\n#### Training 2D Conv on MFCC"},{"metadata":{"_uuid":"ab0f2bc7e7bbaced3eb2e4c3acb7c7c63aa73681","_cell_guid":"10fb7477-8122-49fb-be81-1adb7aa45c7f"},"cell_type":"markdown","source":"```python\nPREDICTION_FOLDER = \"predictions_2d_conv\"\nif not os.path.exists(PREDICTION_FOLDER):\n os.mkdir(PREDICTION_FOLDER)\nif os.path.exists('logs/' + PREDICTION_FOLDER):\n shutil.rmtree('logs/' + PREDICTION_FOLDER)\n\nskf = StratifiedKFold(train.label_idx, n_folds=config.n_folds)\nfor i, (train_split, val_split) in enumerate(skf):\n K.clear_session()\n X, y, X_val, y_val = X_train[train_split], y_train[train_split], X_train[val_split], y_train[val_split]\n checkpoint = ModelCheckpoint('best_%d.h5'%i, monitor='val_loss', verbose=1, save_best_only=True)\n reduce_lr = ReduceLROnPlateau(monitor='val_loss', factor=0.1, patience=5, verbose=1)\n tb = TensorBoard(log_dir='./logs/' + PREDICTION_FOLDER + '/fold_%i'%i, write_graph=True)\n callbacks_list = [checkpoint, tb, reduce_lr]\n print(\"#\"*50)\n print(\"Fold: \", i)\n model = get_2d_conv_model(config)\n history = model.fit(X, y, validation_data=(X_val, y_val), callbacks=callbacks_list, \n batch_size=64, epochs=config.max_epochs)\n model.load_weights('best_%d.h5'%i)\n\n # Save train predictions\n predictions = model.predict(X_train, batch_size=64, verbose=1)\n np.save(PREDICTION_FOLDER + \"/train_predictions_%d.npy\"%i, predictions)\n\n # Save test predictions\n predictions = model.predict(X_test, batch_size=64, verbose=1)\n np.save(PREDICTION_FOLDER + \"/test_predictions_%d.npy\"%i, predictions)\n\n # Make a submission file\n top_3 = np.array(LABELS)[np.argsort(-predictions, axis=1)[:, :3]]\n predicted_labels = [' '.join(list(x)) for x in top_3]\n test['label'] = predicted_labels\n test[['label']].to_csv(PREDICTION_FOLDER + \"/predictions_%d.csv\"%i)\n```"},{"metadata":{"_uuid":"b4421687f65fd8068c04fcdfdb419bf4f08c5f2c","_cell_guid":"4bd794b7-c09e-42d6-8f8a-158758921273"},"cell_type":"markdown","source":"\n#### Ensembling 2D Conv Predictions"},{"metadata":{"_cell_guid":"8c253178-6cde-4bad-835d-d09484f381ed","_uuid":"e6868eb538b9fed874fcb02183d2edd348d38b5f","collapsed":true,"trusted":false},"cell_type":"code","source":"pred_list = []\nfor i in range(10):\n pred_list.append(np.load(\"../input/freesound-prediction-data-2d-conv-reduced-lr/test_predictions_%d.npy\"%i))\nprediction = np.ones_like(pred_list[0])\nfor pred in pred_list:\n prediction = prediction*pred\nprediction = prediction**(1./len(pred_list))\n# Make a submission file\ntop_3 = np.array(LABELS)[np.argsort(-prediction, axis=1)[:, :3]]\npredicted_labels = [' '.join(list(x)) for x in top_3]\ntest = pd.read_csv('../input/freesound-audio-tagging/sample_submission.csv')\ntest['label'] = predicted_labels\ntest[['fname', 'label']].to_csv(\"2d_conv_ensembled_submission.csv\", index=False)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"38feef2350dfa3c099bd6fb2e1a0b921716606a8","_cell_guid":"b67760f2-f8cd-498a-b340-4910d8c443d3"},"cell_type":"markdown","source":"\n## 5. Ensembling 1D Conv and 2D Conv Predictions"},{"metadata":{"_cell_guid":"12566257-72a5-4aa3-9e11-763c98489810","_uuid":"448e8f9034d9d43a4642b1f441965b272425ba63","collapsed":true,"trusted":false},"cell_type":"code","source":"pred_list = []\nfor i in range(10):\n pred_list.append(np.load(\"../input/freesound-prediction-data-2d-conv-reduced-lr/test_predictions_%d.npy\"%i))\nfor i in range(10):\n pred_list.append(np.load(\"../input/freesound-prediction-file/test_predictions_%d.npy\"%i))\nprediction = np.ones_like(pred_list[0])\nfor pred in pred_list:\n prediction = prediction*pred\nprediction = prediction**(1./len(pred_list))\n# Make a submission file\ntop_3 = np.array(LABELS)[np.argsort(-prediction, axis=1)[:, :3]]\npredicted_labels = [' '.join(list(x)) for x in top_3]\ntest = pd.read_csv('../input/freesound-audio-tagging/sample_submission.csv')\ntest['label'] = predicted_labels\ntest[['fname', 'label']].to_csv(\"1d_2d_ensembled_submission.csv\", index=False)","execution_count":null,"outputs":[]},{"metadata":{"_uuid":"836b4a9008b4a239f3c41d8f3997bd49fa3c2280","_cell_guid":"34e4b1a5-49ac-49ff-a9cd-9b341d784e9b"},"cell_type":"markdown","source":"\n## Results and Conclusion"},{"metadata":{"_cell_guid":"1f6bb71f-f461-414c-90d1-725c03f368ff","_uuid":"01cfbfa163adb3da8b7b7da3310fb9e38ce0d478","collapsed":true},"cell_type":"markdown","source":"So far, we have trained two models. Let's analyze their relative complexity and strength.\n\n\n\n| Model | Number of Trainable parameters | Public LB score |\n| ------------- |:-------------:| -----:|\n| 1D Conv on Raw wave | 360,513 | 0.809 |\n| 2D Conv on MFCC | 168,361 | 0.844 |\n| 1D Conv + 2D Conv Ensemble | N/A | 0.895 |\n\n**As we can see, 2D Convolution on MFCC performs better than 1D Convolution on Raw waves.**"},{"metadata":{"_uuid":"b8db90dc506d23d6241c606ca03fd1762f38f36f","_cell_guid":"78397951-3d15-45c1-bc29-17c853d7adf5"},"cell_type":"markdown","source":"## Coming Soon\n\n1. Data Augmentation\n2. Training on Manually Verified Labels"}],"metadata":{"language_info":{"name":"python","version":"3.6.4","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"},"kernelspec":{"display_name":"Python 3","language":"python","name":"python3"}},"nbformat":4,"nbformat_minor":1}