{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"name":"python","version":"3.10.13","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"},"kaggle":{"accelerator":"tpu1vmV38","dataSources":[{"sourceId":18278,"databundleVersionId":968043,"sourceType":"competition"}],"dockerImageVersionId":30617,"isInternetEnabled":true,"language":"python","sourceType":"notebook","isGpuEnabled":false}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"# Classification de Fleurs sur TPU","metadata":{}},{"cell_type":"markdown","source":"La compétition Kaggle concerne la classification de 104 types de fleurs basée sur leurs images, issues de cinq ensembles de données publics différents.","metadata":{}},{"cell_type":"markdown","source":" ","metadata":{}},{"cell_type":"markdown","source":"# Unité de Traitement Tensoriel (TPU)","metadata":{}},{"cell_type":"markdown","source":"Les TPU sont des accélérateurs matériels puissants spécialisés dans les tâches d'apprentissage profond. Ils ont été développés (et utilisés pour la première fois) par Google pour traiter de grandes bases de données d'images, telles que l'extraction de tout le texte de Street View. Cette compétition est conçue pour vous permettre d'essayer les TPU.","metadata":{}},{"cell_type":"markdown","source":"
 ","metadata":{}},{"cell_type":"markdown","source":"Les GPU modernes sont organisés autour de \"cœurs\" programmables, une architecture très flexible qui leur permet de gérer une variété de tâches telles que le rendu 3D, l'apprentissage profond, les simulations physiques, etc. Les TPU, en revanche, associent un processeur vectoriel classique à une unité de multiplication matricielle dédiée et excellent dans toutes les tâches où les grandes multiplications matricielles dominent, comme les réseaux neuronaux.\n\nLorsque Google a conçu le TPU, nous avons construit une architecture spécifique au domaine. Cela signifie qu'au lieu de concevoir un processeur à usage général, ils l'ont conçu comme un processeur matriciel spécialisé pour les charges de travail des réseaux neuronaux. Les TPU ne peuvent pas exécuter de traitement de texte, contrôler des moteurs de fusée ou effectuer des transactions bancaires, mais ils peuvent gérer les multiplications et additions massives pour les réseaux neuronaux, à des vitesses extrêmement rapides tout en consommant beaucoup moins d'énergie et en occupant un espace physique plus réduit.\n\nLe TPU charge les données depuis la mémoire. À chaque multiplication exécutée, le résultat sera transmis aux multiplicateurs suivants tout en prenant en compte la sommation en même temps. Ainsi, la sortie sera la sommation de tous les résultats de multiplication entre les données et les paramètres. Pendant tout le processus de calculs massifs et de passage de données, aucun accès à la mémoire n'est nécessaire du tout.","metadata":{}},{"cell_type":"markdown","source":"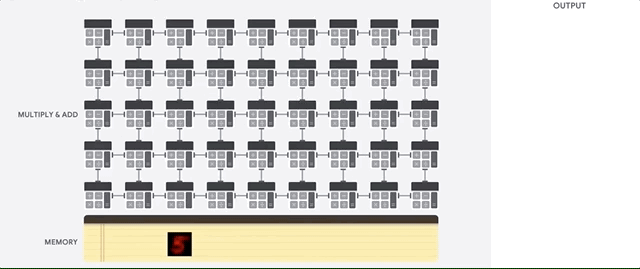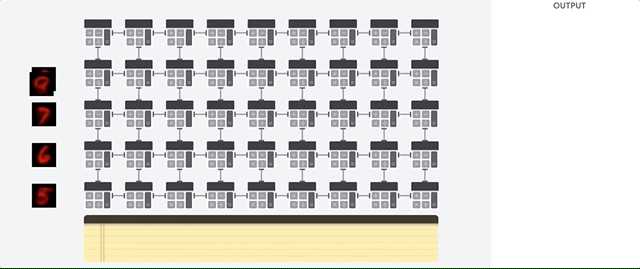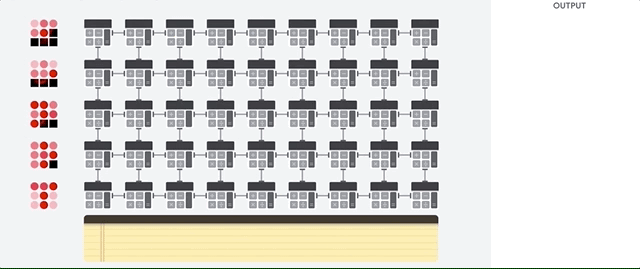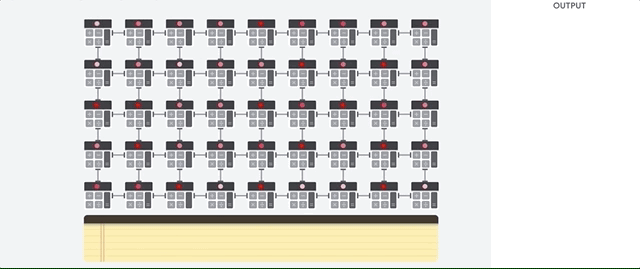","metadata":{}},{"cell_type":"markdown","source":"# Description des Données :","metadata":{}},{"cell_type":"markdown","source":"Cette compétition fournit ses fichiers au format TFRecord. Le format TFRecord est un format conteneur fréquemment utilisé dans Tensorflow pour regrouper et partager des fichiers de données afin d'optimiser la performance de l'entraînement. Chaque fichier contient l'identifiant, l'étiquette (la classe de l'échantillon, pour les données d'entraînement) et img (les pixels réels sous forme de tableau) pour de nombreuses images.\n\n* 12753 images d'entraînement\n* 3712 images de validation\n* 7382 images de test non étiquetées","metadata":{}},{"cell_type":"code","source":"# This Python 3 environment comes with many helpful analytics libraries installed\n# It is defined by the kaggle/python Docker image: https://github.com/kaggle/docker-python\n# For example, here's several helpful packages to load\n\nimport numpy as np # linear algebra\nimport pandas as pd # data processing, CSV file I/O (e.g. pd.read_csv)\n\n# Input data files are available in the read-only \"../input/\" directory\n# For example, running this (by clicking run or pressing Shift+Enter) will list all files under the input directory\n\nimport os\nfor dirname, _, filenames in os.walk('/kaggle/input'):\n for filename in filenames:\n print(os.path.join(dirname, filename))\n\n# You can write up to 20GB to the current directory (/kaggle/working/) that gets preserved as output when you create a version using \"Save & Run All\" \n# You can also write temporary files to /kaggle/temp/, but they won't be saved outside of the current session","metadata":{"_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","execution":{"iopub.status.busy":"2023-12-11T02:46:52.404926Z","iopub.execute_input":"2023-12-11T02:46:52.405271Z","iopub.status.idle":"2023-12-11T02:46:53.377997Z","shell.execute_reply.started":"2023-12-11T02:46:52.405242Z","shell.execute_reply":"2023-12-11T02:46:53.377173Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Obtention des Bibliothèques Nécessaires","metadata":{}},{"cell_type":"code","source":"import math, re, os\nimport tensorflow as tf\nfrom matplotlib import pyplot as plt\nfrom kaggle_datasets import KaggleDatasets\nfrom sklearn.metrics import f1_score, precision_score, recall_score, confusion_matrix\n\nprint(\"Tensorflow version \", tf.__version__)\nAUTO = tf.data.experimental.AUTOTUNE","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:47:00.203543Z","iopub.execute_input":"2023-12-11T02:47:00.203912Z","iopub.status.idle":"2023-12-11T02:47:15.843227Z","shell.execute_reply.started":"2023-12-11T02:47:00.203883Z","shell.execute_reply":"2023-12-11T02:47:15.842225Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"try:\n tpu = tf.distribute.cluster_resolver.TPUClusterResolver(tpu='local')\n tf.config.experimental_connect_to_cluster(tpu)\n # This is the TPU initialization code that has to be at the beginning.\n tf.tpu.experimental.initialize_tpu_system(tpu)\n print(\"All devices: \", tf.config.list_logical_devices('TPU'))\n strategy = tf.distribute.TPUStrategy(tpu)\nexcept ValueError:\n strategy = tf.distribute.get_strategy()\n \nprint(\"Number of accelerators: \", strategy.num_replicas_in_sync)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:47:19.861066Z","iopub.execute_input":"2023-12-11T02:47:19.862326Z","iopub.status.idle":"2023-12-11T02:47:28.691646Z","shell.execute_reply.started":"2023-12-11T02:47:19.862288Z","shell.execute_reply":"2023-12-11T02:47:28.690635Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"GCS_DS_PATH = KaggleDatasets().get_gcs_path()","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:48:27.025249Z","iopub.execute_input":"2023-12-11T02:48:27.025628Z","iopub.status.idle":"2023-12-11T02:48:27.031165Z","shell.execute_reply.started":"2023-12-11T02:48:27.025598Z","shell.execute_reply":"2023-12-11T02:48:27.030143Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"IMAGE_SIZE = [512, 512]\nEPOCHS = 12\nBATCH_SIZE = 16 * strategy.num_replicas_in_sync\n\nGCS_PATH_SELECT = {\n 192: GCS_DS_PATH + '/tfrecords-jpeg-192x192',\n 224: GCS_DS_PATH + '/tfrecords-jpeg-224x224',\n 331: GCS_DS_PATH + '/tfrecords-jpeg-331x331',\n 512: GCS_DS_PATH + '/tfrecords-jpeg-512x512',\n}\nGCS_PATH = GCS_PATH_SELECT[IMAGE_SIZE[0]]\n\nTRAINING_FILENAMES = tf.io.gfile.glob(GCS_PATH + '/train/*.tfrec')\nVALIDATION_FILENAMES = tf.io.gfile.glob(GCS_PATH + '/val/*.tfrec')\nTEST_FILENAMES = tf.io.gfile.glob(GCS_PATH + '/test/*.tfrec')\n\nCLASSES = ['pink primrose', 'hard-leaved pocket orchid', 'canterbury bells', 'sweet pea', 'wild geranium', 'tiger lily', 'moon orchid', 'bird of paradise', 'monkshood', 'globe thistle', # 00 - 09\n 'snapdragon', \"colt's foot\", 'king protea', 'spear thistle', 'yellow iris', 'globe-flower', 'purple coneflower', 'peruvian lily', 'balloon flower', 'giant white arum lily', # 10 - 19\n 'fire lily', 'pincushion flower', 'fritillary', 'red ginger', 'grape hyacinth', 'corn poppy', 'prince of wales feathers', 'stemless gentian', 'artichoke', 'sweet william', # 20 - 29\n 'carnation', 'garden phlox', 'love in the mist', 'cosmos', 'alpine sea holly', 'ruby-lipped cattleya', 'cape flower', 'great masterwort', 'siam tulip', 'lenten rose', # 30 - 39\n 'barberton daisy', 'daffodil', 'sword lily', 'poinsettia', 'bolero deep blue', 'wallflower', 'marigold', 'buttercup', 'daisy', 'common dandelion', # 40 - 49\n 'petunia', 'wild pansy', 'primula', 'sunflower', 'lilac hibiscus', 'bishop of llandaff', 'gaura', 'geranium', 'orange dahlia', 'pink-yellow dahlia', # 50 - 59\n 'cautleya spicata', 'japanese anemone', 'black-eyed susan', 'silverbush', 'californian poppy', 'osteospermum', 'spring crocus', 'iris', 'windflower', 'tree poppy', # 60 - 69\n 'gazania', 'azalea', 'water lily', 'rose', 'thorn apple', 'morning glory', 'passion flower', 'lotus', 'toad lily', 'anthurium', # 70 - 79\n 'frangipani', 'clematis', 'hibiscus', 'columbine', 'desert-rose', 'tree mallow', 'magnolia', 'cyclamen ', 'watercress', 'canna lily', # 80 - 89\n 'hippeastrum ', 'bee balm', 'pink quill', 'foxglove', 'bougainvillea', 'camellia', 'mallow', 'mexican petunia', 'bromelia', 'blanket flower', # 90 - 99\n 'trumpet creeper', 'blackberry lily', 'common tulip', 'wild rose'] # 100 - 102\nprint('No of Classes : ', len(CLASSES))\n","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:48:30.043684Z","iopub.execute_input":"2023-12-11T02:48:30.044074Z","iopub.status.idle":"2023-12-11T02:48:30.070987Z","shell.execute_reply.started":"2023-12-11T02:48:30.044043Z","shell.execute_reply":"2023-12-11T02:48:30.069624Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Utilitaires de visualisation","metadata":{}},{"cell_type":"code","source":"np.set_printoptions(threshold=15, linewidth=80)\n\ndef batch_to_numpy_images_and_labels(data):\n images, labels = data\n numpy_images = images.numpy()\n numpy_labels = labels.numpy()\n \n if numpy_labels.dtype == object:\n numpy_labels = [None for _ in enumerate(numpy_images)]\n return numpy_images, numpy_labels\n\ndef title_from_label_and_target(label, correct_label):\n if correct_label is None:\n return CLASSES[label], True\n correct = (label == correct_label)\n return \"{} [{}{}{}]\".format(CLASSES[label], \n 'OK' if correct else 'NO', u'\\u2192' if not correct else '',\n CLASSES[correct_label] if not correct else ''), correct\n\ndef display_one_flower(image, title, subplot, red=False, titlesize=16):\n plt.subplot(*subplot)\n plt.axis('off')\n plt.imshow(image)\n \n if len(title) > 0:\n plt.title(title, fontsize=int(titlesize) if not red else int(titlesize/1.2),\n color='red' if red else 'black',\n fontdict={'verticalalignment':'center'},\n pad=int(titlesize/1.5))\n return (subplot[0], subplot[1], subplot[2]+1)\n\ndef display_batch_of_images(databatch, predictions=None):\n images, labels = batch_to_numpy_images_and_labels(databatch)\n if labels is None:\n labels = [None for _ in enumerate(images)]\n \n rows = int(math.sqrt(len(images)))\n cols = len(images)//rows\n \n FIGSIZE = 13.0\n SPACING = 0.1\n subplot=(rows,cols,1)\n \n if rows < cols:\n plt.figure(figsize=(FIGSIZE,FIGSIZE/cols*rows))\n else:\n plt.figure(figsize=(FIGSIZE/rows*cols,FIGSIZE))\n \n for i, (image, label) in enumerate(zip(images[:rows*cols], labels[:rows*cols])):\n title = '' if label is None else CLASSES[label]\n correct = True\n if predictions is not None:\n title, correct = title_from_label_and_target(predictions[i], label)\n dynamic_titlesize = FIGSIZE*SPACING/max(rows,cols)*40+3\n subplot = display_one_flower(image, title, subplot, not correct,\n titlesize=dynamic_titlesize)\n \n plt.tight_layout()\n if label is None and predictions is None:\n plt.subplots_adjust(wspace=0, hspace=0)\n else:\n plt.subplots_adjust(wspace=SPACING, hspace=SPACING)\n plt.show()\n \ndef display_confusion_matrix(cmat, score, precision, recall):\n plt.figure(figsize=(15,15))\n ax = plt.gca()\n ax.matshow(cmat, cmap='Reds')\n ax.set_xticks(range(len(CLASSES)))\n ax.set_xticklabels(CLASSES, fontdict={'fontsize': 7})\n plt.setp(ax.get_xticklabels(), rotation=45, ha='left', rotation_mode='anchor')\n \n ax.set_yticks(range(len(CLASSES)))\n ax.set_yticklabels(CLASSES, fontdict={'fontsize': 7})\n plt.setp(ax.get_yticklabels(), rotation=45, ha='right', rotation_mode='anchor')\n \n titlestring=''\n if score is not None:\n titlestring += 'f1 = {:.3f} '.format(score)\n if precision is not None:\n titlestring += '\\nprecision = {:.3f} '.format(precision)\n if recall is not None:\n titlestring += '\\nrecall = {:.3f} '.format(recall)\n if len(titlestring) > 0:\n ax.text(101, 1, titlestring, fontdict={'fontsize': 18,\n 'horizontalalignment': 'right',\n 'verticalalignment': 'top',\n 'color': '#804040'})\n plt.show()\n \ndef display_training_curves(training, validation, title, subplot):\n if subplot%10==1:\n plt.subplots(figsize=(10,10), facecolor='#F0F0F0')\n plt.tight_layout()\n ax = plt.subplot(subplot)\n ax.set_facecolor('#F8F8F8')\n ax.plot(training)\n ax.plot(validation)\n ax.set_title('model ' + title)\n ax.set_ylabel(title)\n ax.set_xlabel('epoch')\n ax.legend(['train', 'valid.'])","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:48:34.928001Z","iopub.execute_input":"2023-12-11T02:48:34.928340Z","iopub.status.idle":"2023-12-11T02:48:34.945326Z","shell.execute_reply.started":"2023-12-11T02:48:34.928311Z","shell.execute_reply":"2023-12-11T02:48:34.944524Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Datasets","metadata":{}},{"cell_type":"markdown","source":"L'ensemble de données contient des données au format TFRecords, qui est un format binaire couramment utilisé pour stocker de grands ensembles de données dans TensorFlow.\n\nLa fonction ci-dessous prend une chaîne d'image en entrée, la décode et normalise également les valeurs des pixels dans une plage [0,1].","metadata":{}},{"cell_type":"code","source":"def decode_image(image_data):\n image = tf.image.decode_jpeg(image_data, channels=3)\n image = tf.reshape(image, [*IMAGE_SIZE, 3])\n return image","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:48:48.071545Z","iopub.execute_input":"2023-12-11T02:48:48.071901Z","iopub.status.idle":"2023-12-11T02:48:48.076446Z","shell.execute_reply.started":"2023-12-11T02:48:48.071869Z","shell.execute_reply":"2023-12-11T02:48:48.075565Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Cette fonction lit et analyse un exemple de TFRecord qui a été étiqueté. Un exemple comprend une image au format chaîne de bytes et une étiquette de classe correspondante. \nL'image est décodée en utilisant la fonction decode_image, et l'étiquette est convertie en tf.int32.","metadata":{}},{"cell_type":"code","source":"def read_labeled_tfrecord(example):\n LABELED_TFREC_FORMAT = {\n 'image': tf.io.FixedLenFeature([], tf.string),\n 'class': tf.io.FixedLenFeature([], tf.int64),\n }\n example = tf.io.parse_single_example(example, LABELED_TFREC_FORMAT)\n image = decode_image(example['image'])\n label = tf.cast(example['class'], tf.int32)\n return image, label","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:48:55.190875Z","iopub.execute_input":"2023-12-11T02:48:55.191244Z","iopub.status.idle":"2023-12-11T02:48:55.196242Z","shell.execute_reply.started":"2023-12-11T02:48:55.191212Z","shell.execute_reply":"2023-12-11T02:48:55.195405Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Cette fonction lit les TFRecords qui ne sont pas étiquetés, ce qui est conçu pour des ensembles de données où nous devons prédire les étiquettes pour l'ensemble de données de test donné.","metadata":{}},{"cell_type":"code","source":"def read_unlabeled_tfrecord(example):\n UNLABELED_TFREC_FORMAT = {\n 'image': tf.io.FixedLenFeature([], tf.string),\n 'id': tf.io.FixedLenFeature([], tf.string),\n }\n example = tf.io.parse_single_example(example, UNLABELED_TFREC_FORMAT)\n image = decode_image(example['image'])\n idnum = example['id']\n return image, idnum","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:00.556672Z","iopub.execute_input":"2023-12-11T02:49:00.557033Z","iopub.status.idle":"2023-12-11T02:49:00.562011Z","shell.execute_reply.started":"2023-12-11T02:49:00.556995Z","shell.execute_reply":"2023-12-11T02:49:00.561206Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"Cette fonction est utilisée pour charger des données et peut gérer des données étiquetées ainsi que non étiquetées, en fonction du paramètre 'labelled' (étiqueté).","metadata":{}},{"cell_type":"code","source":"def load_dataset(filenames, labeled=True, ordered=False):\n ignore_order = tf.data.Options()\n if not ordered:\n ignore_order.experimental_deterministic = False\n \n dataset = tf.data.TFRecordDataset(filenames, num_parallel_reads=AUTO)\n dataset = dataset.with_options(ignore_order)\n dataset = dataset.map(read_labeled_tfrecord if labeled else read_unlabeled_tfrecord,\n num_parallel_calls=AUTO)\n return dataset","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:03.323788Z","iopub.execute_input":"2023-12-11T02:49:03.324122Z","iopub.status.idle":"2023-12-11T02:49:03.328719Z","shell.execute_reply.started":"2023-12-11T02:49:03.324092Z","shell.execute_reply":"2023-12-11T02:49:03.327993Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"La performance des réseaux neuronaux d'apprentissage profond s'améliore souvent avec la quantité de données disponibles. L'augmentation des données d'image est une technique qui peut être utilisée pour étendre artificiellement la taille d'un ensemble de données d'entraînement en créant des versions modifiées des images de l'ensemble de données.\n\n### Augmentation des données\n\nCertaines des techniques populaires d'Augmentation d'Image incluent :\n\n* Retournement\n* Rotation\n* Mise à l'échelle\n* Recadrage\n* Translation\n* Ajout de bruit gaussien\n\nPour ce projet, nous avons utilisé le retournement ci-dessous.","metadata":{}},{"cell_type":"code","source":"def data_augment(image, label):\n image = tf.image.random_flip_left_right(image)\n return image, label","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:09.588724Z","iopub.execute_input":"2023-12-11T02:49:09.589050Z","iopub.status.idle":"2023-12-11T02:49:09.592782Z","shell.execute_reply.started":"2023-12-11T02:49:09.589021Z","shell.execute_reply":"2023-12-11T02:49:09.591992Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"En chargeant des fichiers TFRecord étiquetés, en répétant l'ensemble de données sur plusieurs époques, en réarrangeant les données et en regroupant les données, cette fonction assemble l'ensemble de données d'entraînement. Un processus similaire est suivi pour les ensembles de données de test et de validation.","metadata":{}},{"cell_type":"code","source":"def get_training_dataset():\n dataset = load_dataset(TRAINING_FILENAMES, labeled=True)\n dataset = dataset.map(data_augment, num_parallel_calls=AUTO)\n dataset = dataset.repeat()\n dataset = dataset.shuffle(2048)\n dataset = dataset.batch(BATCH_SIZE)\n dataset = dataset.prefetch(AUTO)\n return dataset\n\ndef get_validation_dataset(ordered=True):\n dataset = load_dataset(VALIDATION_FILENAMES, labeled=True, ordered=ordered)\n dataset = dataset.batch(BATCH_SIZE)\n dataset = dataset.cache()\n dataset = dataset.prefetch(AUTO)\n return dataset\n\ndef get_test_dataset(ordered=False):\n dataset = load_dataset(TEST_FILENAMES, labeled=False, ordered=ordered)\n dataset = dataset.batch(BATCH_SIZE)\n dataset = dataset.prefetch(AUTO)\n return dataset\n\ndef count_data_items(filenames):\n n = [int(re.compile(r\"-([0-9]*)\\.\").search(filename).group(1)) for filename in filenames]\n return np.sum(n)\n\nNUM_TRAINING_IMAGES = count_data_items(TRAINING_FILENAMES)\nNUM_VALIDATION_IMAGES = count_data_items(VALIDATION_FILENAMES)\nNUM_TEST_IMAGES = count_data_items(TEST_FILENAMES)\nSTEPS_PER_EPOCH = NUM_TRAINING_IMAGES // BATCH_SIZE\nVALIDATION_STEPS = -(-NUM_VALIDATION_IMAGES // BATCH_SIZE)\nTEST_STEPS = -(-NUM_TEST_IMAGES//BATCH_SIZE) \n# 19//2 = 9\n# -(-19//2) = 10\nprint(\"Dataset: {} training images, {} validation images, {} unlabeled test images\"\n .format(NUM_TRAINING_IMAGES, NUM_VALIDATION_IMAGES, NUM_TEST_IMAGES))","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:14.224829Z","iopub.execute_input":"2023-12-11T02:49:14.225159Z","iopub.status.idle":"2023-12-11T02:49:14.233832Z","shell.execute_reply.started":"2023-12-11T02:49:14.225130Z","shell.execute_reply":"2023-12-11T02:49:14.233003Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Visualisations de l'ensemble de données","metadata":{}},{"cell_type":"code","source":"print(\"Training data shapes:\")\nfor image, label in get_training_dataset().take(3):\n print(image.numpy().shape, label.numpy().shape)\nprint(\"Training data label examples:\", label.numpy())\nprint(\"=\"*30)\nprint(\"Validation data shapes:\")\nfor image, label in get_validation_dataset().take(3):\n print(image.numpy().shape, label.numpy().shape)\nprint(\"Validation data label examples:\", label.numpy())\nprint(\"=\"*30)\nprint(\"Test data shapes:\")\nfor image, idnum in get_test_dataset().take(3):\n print(image.numpy().shape, idnum.numpy().shape)\nprint(\"Test data IDs:\", idnum.numpy().astype(\"U\"))","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:28.239241Z","iopub.execute_input":"2023-12-11T02:49:28.239549Z","iopub.status.idle":"2023-12-11T02:49:30.496300Z","shell.execute_reply.started":"2023-12-11T02:49:28.239522Z","shell.execute_reply":"2023-12-11T02:49:30.495135Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"training_dataset = get_training_dataset()\ntraining_dataset = training_dataset.unbatch().batch(20)\ntrain_batch = iter(training_dataset)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:36.591146Z","iopub.execute_input":"2023-12-11T02:49:36.591532Z","iopub.status.idle":"2023-12-11T02:49:36.667281Z","shell.execute_reply.started":"2023-12-11T02:49:36.591502Z","shell.execute_reply":"2023-12-11T02:49:36.666113Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"display_batch_of_images(next(train_batch))","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:39.728457Z","iopub.execute_input":"2023-12-11T02:49:39.728857Z","iopub.status.idle":"2023-12-11T02:49:42.478698Z","shell.execute_reply.started":"2023-12-11T02:49:39.728824Z","shell.execute_reply":"2023-12-11T02:49:42.477713Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"test_dataset = get_test_dataset()\ntest_dataset = test_dataset.unbatch().batch(20)\ntest_batch = iter(test_dataset)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:48.541487Z","iopub.execute_input":"2023-12-11T02:49:48.541872Z","iopub.status.idle":"2023-12-11T02:49:48.601723Z","shell.execute_reply.started":"2023-12-11T02:49:48.541842Z","shell.execute_reply":"2023-12-11T02:49:48.600523Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"display_batch_of_images(next(test_batch))","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:49:50.714235Z","iopub.execute_input":"2023-12-11T02:49:50.714608Z","iopub.status.idle":"2023-12-11T02:49:52.944335Z","shell.execute_reply.started":"2023-12-11T02:49:50.714578Z","shell.execute_reply":"2023-12-11T02:49:52.943157Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Construction d'un modèle","metadata":{}},{"cell_type":"markdown","source":"Ici, nous utilisons le modèle pré-entraîné de réseau neuronal convolutif Xception, entraîné sur l'ensemble de données ImageNet. De plus, le modèle pré-entraîné est empilé avec des couches supplémentaires en utilisant l'API séquentielle. Ainsi que le modèle VGG16.","metadata":{}},{"cell_type":"code","source":"with strategy.scope():\n img_adjust_layer = tf.keras.layers.Lambda(\n lambda data: tf.keras.applications.xception.preprocess_input(\n tf.cast(data, tf.float32)), input_shape=[*IMAGE_SIZE, 3])\n pretrained_model = tf.keras.applications.Xception(weights='imagenet', include_top=False)\n #img_adjust_layer = tf.keras.layers.Lambda(\n # lambda data: tf.keras.applications.vgg16.preprocess_input(\n # tf.cast(data, tf.float32)), input_shape=[*IMAGE_SIZE, 3]\n #)\n \n #pretrained_model = tf.keras.applications.VGG16(weights=\"imagenet\", include_top=False)\n pretrained_model.trainable = False\n \n model = tf.keras.Sequential([\n img_adjust_layer,\n pretrained_model,\n tf.keras.layers.GlobalAveragePooling2D(),\n tf.keras.layers.Dense(len(CLASSES), activation='softmax')\n ])\n \nmodel.compile(\n optimizer='adam',\n loss='sparse_categorical_crossentropy',\n metrics=['sparse_categorical_accuracy'],\n steps_per_execution=16\n)\n\nmodel.summary()","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:54:24.372803Z","iopub.execute_input":"2023-12-11T02:54:24.373310Z","iopub.status.idle":"2023-12-11T02:54:34.159939Z","shell.execute_reply.started":"2023-12-11T02:54:24.373241Z","shell.execute_reply":"2023-12-11T02:54:34.158902Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Entraînement","metadata":{}},{"cell_type":"code","source":"history = model.fit(get_training_dataset(),\n steps_per_epoch=STEPS_PER_EPOCH,\n epochs=EPOCHS,\n validation_data=get_validation_dataset(),\n validation_steps=VALIDATION_STEPS)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:55:02.767721Z","iopub.execute_input":"2023-12-11T02:55:02.768112Z","iopub.status.idle":"2023-12-11T02:57:35.190413Z","shell.execute_reply.started":"2023-12-11T02:55:02.768080Z","shell.execute_reply":"2023-12-11T02:57:35.189137Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"display_training_curves(history.history[\"loss\"], history.history[\"val_loss\"], 'loss', 211)\ndisplay_training_curves(history.history['sparse_categorical_accuracy'],\n history.history['val_sparse_categorical_accuracy'], 'accuracy', 212)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:57:45.303084Z","iopub.execute_input":"2023-12-11T02:57:45.303421Z","iopub.status.idle":"2023-12-11T02:57:45.810532Z","shell.execute_reply.started":"2023-12-11T02:57:45.303392Z","shell.execute_reply":"2023-12-11T02:57:45.809567Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Matrice de confusion","metadata":{}},{"cell_type":"code","source":"cmdataset = get_validation_dataset(ordered=True)\nimages_ds = cmdataset.map(lambda image, label: image)\nlabels_ds = cmdataset.map(lambda image, label: label).unbatch()\n\ncm_correct_labels = next(iter(labels_ds.batch(NUM_VALIDATION_IMAGES))).numpy()\ncm_probabilities = model.predict(images_ds, steps=VALIDATION_STEPS)\ncm_predictions = np.argmax(cm_probabilities, axis=-1)\nprint(\"Correct labels: \", cm_correct_labels.shape, cm_correct_labels)\nprint(\"Predicted labels: \", cm_predictions.shape, cm_predictions)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:57:52.827565Z","iopub.execute_input":"2023-12-11T02:57:52.827932Z","iopub.status.idle":"2023-12-11T02:58:22.274135Z","shell.execute_reply.started":"2023-12-11T02:57:52.827893Z","shell.execute_reply":"2023-12-11T02:58:22.272845Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"cmat = confusion_matrix(cm_correct_labels, cm_predictions, labels=range(len(CLASSES)))\nscore = f1_score(cm_correct_labels, cm_predictions, labels=range(len(CLASSES)), average='macro')\nprecision = precision_score(cm_correct_labels, cm_predictions, labels=range(len(CLASSES)), average='macro')\nrecall = recall_score(cm_correct_labels, cm_predictions, labels=range(len(CLASSES)), average='macro')\ncmat = (cmat.T/cmat.sum(axis=1)).T\ndisplay_confusion_matrix(cmat, score, precision, recall)\nprint(\"f1 score: {:.3f}, precision: {:.3f}, recall: {:.3f}\".format(score, precision, recall))","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:59:11.169050Z","iopub.execute_input":"2023-12-11T02:59:11.169382Z","iopub.status.idle":"2023-12-11T02:59:12.756532Z","shell.execute_reply.started":"2023-12-11T02:59:11.169355Z","shell.execute_reply":"2023-12-11T02:59:12.755287Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Prédictions","metadata":{}},{"cell_type":"code","source":"test_ds = get_test_dataset(ordered=True)\n\nprint(\"Computing predictions...\")\ntest_images_ds = test_ds.map(lambda image, idnum: image)\nprobabilities = model.predict(test_images_ds, steps=TEST_STEPS)\npredictions = np.argmax(probabilities, axis=-1)\nprint(predictions)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T02:59:45.287525Z","iopub.execute_input":"2023-12-11T02:59:45.287987Z","iopub.status.idle":"2023-12-11T03:00:02.594629Z","shell.execute_reply.started":"2023-12-11T02:59:45.287875Z","shell.execute_reply":"2023-12-11T03:00:02.593376Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"markdown","source":"# Validation visuelle","metadata":{}},{"cell_type":"code","source":"dataset = get_validation_dataset()\ndataset = dataset.unbatch().batch(20)\nbatch = iter(dataset)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T03:00:17.241180Z","iopub.execute_input":"2023-12-11T03:00:17.241537Z","iopub.status.idle":"2023-12-11T03:00:17.304093Z","shell.execute_reply.started":"2023-12-11T03:00:17.241509Z","shell.execute_reply":"2023-12-11T03:00:17.302886Z"},"trusted":true},"execution_count":null,"outputs":[]},{"cell_type":"code","source":"images, labels = next(batch)\nprobabilities = model.predict(tf.cast(images, tf.float32))\npredictions = np.argmax(probabilities, axis=-1)\ndisplay_batch_of_images((images, labels), predictions)","metadata":{"execution":{"iopub.status.busy":"2023-12-11T03:00:28.955630Z","iopub.execute_input":"2023-12-11T03:00:28.955963Z","iopub.status.idle":"2023-12-11T03:00:44.327026Z","shell.execute_reply.started":"2023-12-11T03:00:28.955917Z","shell.execute_reply":"2023-12-11T03:00:44.325870Z"},"trusted":true},"execution_count":null,"outputs":[]}]}