\n

We sincerely appreciate Kaggle and the competition organizers for offering this invaluable opportunity. We also extend our gratitude to @hengck23 and @fnands for their significant contributions. fnands's notebook and hengck23's discussion provided a solid foundation for our approach. Finally, I am grateful to my teammate @luoziqian for the excellent collaboration.
\nOur approach is based on an ensemble of multiple lightweight segmentation models, with parameter sizes ranging from 873K to 14.2M. Following segmentation, we computed particle centroids using CC3D and filtered small clusters based on voxel count statistics.
\nThe overall pipeline is illustrated below:
\n
We initiated our experiments using the MONAI UNet baseline model. Throughout our trials, we observed that models with a large number of parameters were prone to overfitting and often performed worse than lighter models. Consequently, we opted for lightweight architectures such as UNet3D, VoxResNet, VoxHRNet, SegResNet, DynUNet, and DenseVNet.
\nHowever, while experimenting with VoxResNet, VoxHRNet, and DenseVNet, we encountered stability issues, including performance fluctuations and difficulties in convergence. Upon further analysis, we identified that MONAI UNet employs InstanceNorm3d and PReLU. By modifying the normalization and activation layers accordingly, we achieved more stable model performance.
The model architecture of MONAI UNet is shown below:
\n
The following figure compares the training performance of MONAI UNet with InstanceNorm3d and PReLU versus BatchNorm3d and ReLU across 5 experiments, demonstrating that the use of InstanceNorm3d and PReLU results in more stable training.
\n
For the final ensemble, we selected models based on their public leaderboard scores:
\nOur training configuration was designed to ensure stability and optimal performance. We found that the segmentation mask radius, loss function and data augmentation strategies played a crucial role in achieving reliable results.
\nWe applied ground truth masks with a customized radius for each particle.
\n| Particle Types | \nDefault Radius | \nLuoziqian's Radius | \nLion's Radius | \n
|---|---|---|---|
| apo-ferritin | \n60 | \n60 x 0.5 | \n80 x 0.4 | \n
| beta-galactosidase | \n90 | \n90 x 0.5 | \n90 x 0.4 | \n
| ribosome | \n150 | \n150 x 0.5 | \n150 x 0.4 | \n
| thyroglobulin | \n130 | \n130 x 0.5 | \n120 x 0.4 | \n
| virus-like-particle | \n135 | \n135 x 0.5 | \n150 x 0.4 | \n
Lion's models:
\n[128, 256, 256] or [128, 384, 384]200 epochs0.001 (no learning rate scheduler)2 or 40.1 or 0.3[1.0, 1.0, 0.0, 2.0, 1.0, 2.0, 1.0]Luoziqian's models
\n[128, 200, 200] or [128, 256, 256]100 or 300 epochspatience=201 or 2Lion's models:
\n[1, 1, 1, 1, 2, 1, 2] for balanced samplingLuoziqian's models
\n| No | \nModel | \nDeveloper | \nArchitecture | \nParameters | \nValid ID | \nNormalization | \nActivation | \nPublic LB | \nPrivate LB | \n
|---|---|---|---|---|---|---|---|---|---|
| 1 | \nepoch122-step2952-valid_loss0.3625-val_metric0.8367.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_86_3 | \nInstanceNorm3d | \nPReLU | \n0.77379 | \n0.76582 | \n
| 2 | \nepoch148-step3576-valid_loss1.1154-val_metric0.7722.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_6_4 | \nInstanceNorm3d | \nPReLU | \n0.77021 | \n0.76725 | \n
| 3 | \nepoch153-step3696-valid_loss0.3021-val_metric0.8900.ckpt | \nLion | \nUNet3D | \n1.6M | \nTS_69_2 | \nInstanceNorm3d | \nPReLU | \n0.77205 | \n0.76676 | \n
| 4 | \nepoch194-step4680-valid_loss1.0213-val_metric0.8788.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_69_2 | \nInstanceNorm3d | \nPReLU | \n0.77390 | \n0.76737 | \n
| 5 | \nepoch138-step3336-valid_loss0.3690-val_metric0.8476.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76543 | \n0.76025 | \n
| 6 | \nepoch152-step3672-valid_loss0.4333-val_metric0.7929.ckpt | \nLion | \nDenseVNet | \n873K | \nTS_6_6 | \nInstanceNorm3d | \nPReLU | \n0.76528 | \n0.75417 | \n
| 7 | \nepoch195-step4704-valid_loss0.4258-val_metric0.7914.ckpt | \nLion | \nVoxResNet | \n7.0M | \nTS_6_6 | \nInstanceNorm3d | \nPReLU | \n0.77457 | \n0.76593 | \n
| 8 | \nepoch188-step4536-valid_loss0.4231-val_metric0.8659.ckpt | \nLion | \nVoxHRNet | \n1.4M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76738 | \n0.75995 | \n
| 9 | \nepoch198-step4776-valid_loss0.3471-val_metric0.8730.ckpt | \nLion | \nVoxHRNet | \n1.4M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76135 | \n0.75848 | \n
| 10 | \nepoch133-val_loss0.52-val_metric0.56-step3216.ckpt | \nLuoziqian | \nUNet3D | \n1.1M | \nTS_6_4 | \nBatchNorm3d | \nPReLU | \n0.76844 | \n0.76320 | \n
| 11 | \nepoch314-val_loss0.54-val_metric0.54-step7560.ckpt | \nLuoziqian | \nSegResNet | \n1.2M | \nTS_6_4 | \nGroupNorm | \nReLU | \n0.75521 | \n0.74647 | \n
| 12 | \nepoch114-val_loss0.55-val_metric0.53-Step2760.ckpt | \nLuoziqian | \nUNet2E3D | \n14.2M | \nTS_6_4 | \nBatchNorm3d | \nReLU | \n0.73758 | \n0.72966 | \n
We select the models with the best public leaderboard scores for the final submission.
\n| Models | \nEnsemble Strategy | \nCertainty Threshold | \nPublic LB | \nPrivate LB | \nSelected | \n
|---|---|---|---|---|---|
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.23 | \n0.79094 | \n0.78641 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.18 | \n0.79213 | \n0.78630 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.15 | \n0.79307 | \n0.78457 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nweighted | \n0.15 | \n0.79247 | \n0.78417 | \n❌ | \n
| [1, 2, 3, 4, 6, 12] | \nAverage | \n0.15 | \n0.78701 | \n0.78389 | \n❌ | \n
| [1, 2, 3, 4, 5, 6, 7] | \nAverage | \n0.15 | \n0.79104 | \n0.78277 | \n❌ | \n
| [1, 2, 3, 4, 7, 9, 12] | \nAverage | \n0.15 | \n0.79391 | \n0.78283 | \n✅ | \n
| [1, 2, 3, 4, 6, 7, 9, 10, 11, 12] | \nAverage | \n0.15 | \n0.79355 | \n0.78381 | \n✅ | \n
We used CC3D to convert the segmentation results into particle clusters and applied the following strategies for cluster selection:
Inference Notebook
\nLion's Training Code
\nLuoziqian's Training Code
Gubins, Ilja, et al. \"SHREC 2020: Classification in cryo-electron tomograms.\" Computers & Graphics 91 (2020): 279-289.
", "messages": [ { "id": 3117241, "postDate": "2025-02-06T18:53:56.557Z", "content": "We sincerely appreciate Kaggle and the competition organizers for offering this invaluable opportunity. We also extend our gratitude to @hengck23 and @fnands for their significant contributions. fnands's notebook and hengck23's discussion provided a solid foundation for our approach. Finally, I am grateful to my teammate @luoziqian for the excellent collaboration.
\nOur approach is based on an ensemble of multiple lightweight segmentation models, with parameter sizes ranging from 873K to 14.2M. Following segmentation, we computed particle centroids using CC3D and filtered small clusters based on voxel count statistics.
\nThe overall pipeline is illustrated below:
\n
We initiated our experiments using the MONAI UNet baseline model. Throughout our trials, we observed that models with a large number of parameters were prone to overfitting and often performed worse than lighter models. Consequently, we opted for lightweight architectures such as UNet3D, VoxResNet, VoxHRNet, SegResNet, DynUNet, and DenseVNet.
\nHowever, while experimenting with VoxResNet, VoxHRNet, and DenseVNet, we encountered stability issues, including performance fluctuations and difficulties in convergence. Upon further analysis, we identified that MONAI UNet employs InstanceNorm3d and PReLU. By modifying the normalization and activation layers accordingly, we achieved more stable model performance.
The model architecture of MONAI UNet is shown below:
\n
The following figure compares the training performance of MONAI UNet with InstanceNorm3d and PReLU versus BatchNorm3d and ReLU across 5 experiments, demonstrating that the use of InstanceNorm3d and PReLU results in more stable training.
\n
For the final ensemble, we selected models based on their public leaderboard scores:
\nOur training configuration was designed to ensure stability and optimal performance. We found that the segmentation mask radius, loss function and data augmentation strategies played a crucial role in achieving reliable results.
\nWe applied ground truth masks with a customized radius for each particle.
\n| Particle Types | \nDefault Radius | \nLuoziqian's Radius | \nLion's Radius | \n
|---|---|---|---|
| apo-ferritin | \n60 | \n60 x 0.5 | \n80 x 0.4 | \n
| beta-galactosidase | \n90 | \n90 x 0.5 | \n90 x 0.4 | \n
| ribosome | \n150 | \n150 x 0.5 | \n150 x 0.4 | \n
| thyroglobulin | \n130 | \n130 x 0.5 | \n120 x 0.4 | \n
| virus-like-particle | \n135 | \n135 x 0.5 | \n150 x 0.4 | \n
Lion's models:
\n[128, 256, 256] or [128, 384, 384]200 epochs0.001 (no learning rate scheduler)2 or 40.1 or 0.3[1.0, 1.0, 0.0, 2.0, 1.0, 2.0, 1.0]Luoziqian's models
\n[128, 200, 200] or [128, 256, 256]100 or 300 epochspatience=201 or 2Lion's models:
\n[1, 1, 1, 1, 2, 1, 2] for balanced samplingLuoziqian's models
\n| No | \nModel | \nDeveloper | \nArchitecture | \nParameters | \nValid ID | \nNormalization | \nActivation | \nPublic LB | \nPrivate LB | \n
|---|---|---|---|---|---|---|---|---|---|
| 1 | \nepoch122-step2952-valid_loss0.3625-val_metric0.8367.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_86_3 | \nInstanceNorm3d | \nPReLU | \n0.77379 | \n0.76582 | \n
| 2 | \nepoch148-step3576-valid_loss1.1154-val_metric0.7722.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_6_4 | \nInstanceNorm3d | \nPReLU | \n0.77021 | \n0.76725 | \n
| 3 | \nepoch153-step3696-valid_loss0.3021-val_metric0.8900.ckpt | \nLion | \nUNet3D | \n1.6M | \nTS_69_2 | \nInstanceNorm3d | \nPReLU | \n0.77205 | \n0.76676 | \n
| 4 | \nepoch194-step4680-valid_loss1.0213-val_metric0.8788.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_69_2 | \nInstanceNorm3d | \nPReLU | \n0.77390 | \n0.76737 | \n
| 5 | \nepoch138-step3336-valid_loss0.3690-val_metric0.8476.ckpt | \nLion | \nUNet3D | \n1.1M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76543 | \n0.76025 | \n
| 6 | \nepoch152-step3672-valid_loss0.4333-val_metric0.7929.ckpt | \nLion | \nDenseVNet | \n873K | \nTS_6_6 | \nInstanceNorm3d | \nPReLU | \n0.76528 | \n0.75417 | \n
| 7 | \nepoch195-step4704-valid_loss0.4258-val_metric0.7914.ckpt | \nLion | \nVoxResNet | \n7.0M | \nTS_6_6 | \nInstanceNorm3d | \nPReLU | \n0.77457 | \n0.76593 | \n
| 8 | \nepoch188-step4536-valid_loss0.4231-val_metric0.8659.ckpt | \nLion | \nVoxHRNet | \n1.4M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76738 | \n0.75995 | \n
| 9 | \nepoch198-step4776-valid_loss0.3471-val_metric0.8730.ckpt | \nLion | \nVoxHRNet | \n1.4M | \nTS_73_6 | \nInstanceNorm3d | \nPReLU | \n0.76135 | \n0.75848 | \n
| 10 | \nepoch133-val_loss0.52-val_metric0.56-step3216.ckpt | \nLuoziqian | \nUNet3D | \n1.1M | \nTS_6_4 | \nBatchNorm3d | \nPReLU | \n0.76844 | \n0.76320 | \n
| 11 | \nepoch314-val_loss0.54-val_metric0.54-step7560.ckpt | \nLuoziqian | \nSegResNet | \n1.2M | \nTS_6_4 | \nGroupNorm | \nReLU | \n0.75521 | \n0.74647 | \n
| 12 | \nepoch114-val_loss0.55-val_metric0.53-Step2760.ckpt | \nLuoziqian | \nUNet2E3D | \n14.2M | \nTS_6_4 | \nBatchNorm3d | \nReLU | \n0.73758 | \n0.72966 | \n
We select the models with the best public leaderboard scores for the final submission.
\n| Models | \nEnsemble Strategy | \nCertainty Threshold | \nPublic LB | \nPrivate LB | \nSelected | \n
|---|---|---|---|---|---|
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.23 | \n0.79094 | \n0.78641 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.18 | \n0.79213 | \n0.78630 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nAverage | \n0.15 | \n0.79307 | \n0.78457 | \n❌ | \n
| [1, 2, 3, 4, 7, 8, 12] | \nweighted | \n0.15 | \n0.79247 | \n0.78417 | \n❌ | \n
| [1, 2, 3, 4, 6, 12] | \nAverage | \n0.15 | \n0.78701 | \n0.78389 | \n❌ | \n
| [1, 2, 3, 4, 5, 6, 7] | \nAverage | \n0.15 | \n0.79104 | \n0.78277 | \n❌ | \n
| [1, 2, 3, 4, 7, 9, 12] | \nAverage | \n0.15 | \n0.79391 | \n0.78283 | \n✅ | \n
| [1, 2, 3, 4, 6, 7, 9, 10, 11, 12] | \nAverage | \n0.15 | \n0.79355 | \n0.78381 | \n✅ | \n
We used CC3D to convert the segmentation results into particle clusters and applied the following strategies for cluster selection:
Inference Notebook
\nLion's Training Code
\nLuoziqian's Training Code
Gubins, Ilja, et al. \"SHREC 2020: Classification in cryo-electron tomograms.\" Computers & Graphics 91 (2020): 279-289.
", "rawMarkdown": "## Acknowledgments\n\nWe sincerely appreciate Kaggle and the competition organizers for offering this invaluable opportunity. We also extend our gratitude to @hengck23 and @fnands for their significant contributions. [**fnands's notebook**](https://www.kaggle.com/code/fnands/baseline-unet-train-submit/notebook) and [**hengck23's discussion**](https://www.kaggle.com/competitions/czii-cryo-et-object-identification/discussion/547350#3056648) provided a solid foundation for our approach. Finally, I am grateful to my teammate @luoziqian for the excellent collaboration.\n\n## Summary\n\nOur approach is based on an ensemble of multiple lightweight segmentation models, with parameter sizes ranging from 873K to 14.2M. Following segmentation, we computed particle centroids using CC3D and filtered small clusters based on voxel count statistics.\n\n## Overall Pipeline\n\nThe overall pipeline is illustrated below:\n\n\n\n## Model Architecture\n\nWe initiated our experiments using the MONAI UNet baseline model. Throughout our trials, we observed that models with a large number of parameters were prone to overfitting and often performed worse than lighter models. Consequently, we opted for lightweight architectures such as UNet3D, VoxResNet, VoxHRNet, SegResNet, DynUNet, and DenseVNet.\n\nHowever, while experimenting with VoxResNet, VoxHRNet, and DenseVNet, we encountered stability issues, including performance fluctuations and difficulties in convergence. Upon further analysis, we identified that MONAI UNet employs `InstanceNorm3d` and `PReLU`. By modifying the normalization and activation layers accordingly, we achieved more stable model performance.\n\nThe model architecture of MONAI UNet is shown below:\n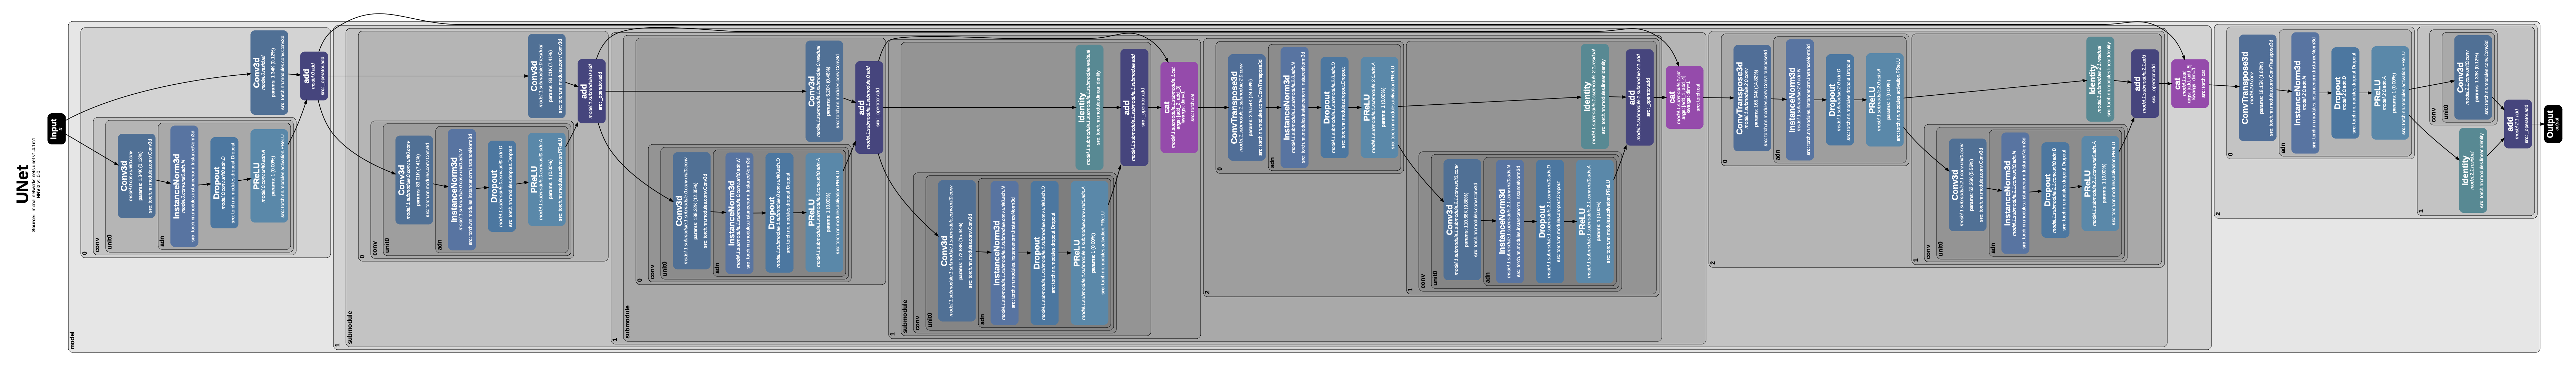\n\nThe following figure compares the training performance of MONAI UNet with InstanceNorm3d and PReLU versus BatchNorm3d and ReLU across 5 experiments, demonstrating that the use of InstanceNorm3d and PReLU results in more stable training.\n\n\n\nFor the final ensemble, we selected models based on their public leaderboard scores:\n\n- UNet3D\n- VoxResNet\n- VoxHRNet\n- SegResNet\n- DenseVNet\n- UNet2E3D\n\n## Training Strategy\n\nOur training configuration was designed to ensure stability and optimal performance. We found that the **segmentation mask radius**, **loss function** and **data augmentation strategies** played a crucial role in achieving reliable results.\n\n#### Segmentation Mask:\n\nWe applied ground truth masks with a customized radius for each particle.\n\n| **Particle Types** | **Default Radius** |**Luoziqian's Radius** | **Lion's Radius** |\n| ------------------- | ------------------ | ----------------------- | ---------------- |\n| apo-ferritin | 60 | 60 x 0.5 | 80 x 0.4 | \n| beta-galactosidase | 90 | 90 x 0.5 | 90 x 0.4 |\n| ribosome | 150 | 150 x 0.5 | 150 x 0.4 |\n| thyroglobulin | 130 | 130 x 0.5 |120 x 0.4 |\n| virus-like-particle | 135 | 135 x 0.5 | 150 x 0.4 | \n\n#### Training Settings:\n\n**Lion's** models:\n- patch size `[128, 256, 256]` or `[128, 384, 384]`\n- `200` epochs\n- 7 classes\n- Optimizer: AdamW with a learning rate of `0.001` (no learning rate scheduler)\n- Batch size: `2` or `4`\n- Drop path rate: `0.1` or `0.3`\n- Model selection based on the F-beta metric, save top-5 best model\n- Loss functions:\n - Tversky Loss\n - Cross-Entropy Loss with weights `[1.0, 1.0, 0.0, 2.0, 1.0, 2.0, 1.0]`\n\n**Luoziqian's** models\n- patch size `[128, 200, 200]` or `[128, 256, 256]`\n- `100` or `300` epochs\n- 6 classes\n- Early stopping with `patience=20`\n- Batch size: `1` or `2`\n- Model selection is based on the evaluation loss. The last 100 models are saved and their F-beta scores are verified\n- Loss functions:\n - Dice Loss\n - Tversky Loss\n - Cross-Entropy Loss, scaled to 0.05 or 0.1\n\n\n#### Augmentations:\n\n**Lion's** models:\n\n- RandCropByLabelClassesd with ratios `[1, 1, 1, 1, 2, 1, 2]` for balanced sampling\n- RandRotate90d\n- RandFlipd\n- RandAffined\n- RandGaussianNoised\n\n**Luoziqian's** models\n- RandCropByLabelClassesd\n- RandRotate90d\n- RandFlipd\n- RandShiftIntensityd\n\n\n#### Model Performance with 7 TTA Summary (Partial Selection)\n\n| **No** | **Model** | **Developer** | **Architecture** | **Parameters** | **Valid ID** | **Normalization** | **Activation** | **Public LB** | **Private LB** |\n| ------ | -------------------------------------------------------- | ----------------| ---------------- | -------------- | ----------------- | ----------------- | -------------- | ------------- | -------------- |\n| 1 | epoch122-step2952-valid_loss0.3625-val_metric0.8367.ckpt | Lion | UNet3D | 1.1M | TS_86_3 | InstanceNorm3d | PReLU | 0.77379 | 0.76582 |\n| 2 | epoch148-step3576-valid_loss1.1154-val_metric0.7722.ckpt | Lion | UNet3D | 1.1M | TS_6_4 | InstanceNorm3d | PReLU | 0.77021 | 0.76725 |\n| 3 | epoch153-step3696-valid_loss0.3021-val_metric0.8900.ckpt | Lion | UNet3D | 1.6M | TS_69_2 | InstanceNorm3d | PReLU | 0.77205 | 0.76676 |\n| 4 | epoch194-step4680-valid_loss1.0213-val_metric0.8788.ckpt | Lion | UNet3D | 1.1M | TS_69_2 | InstanceNorm3d | PReLU | 0.77390 | 0.76737 |\n| 5 | epoch138-step3336-valid_loss0.3690-val_metric0.8476.ckpt | Lion | UNet3D | 1.1M | TS_73_6 | InstanceNorm3d | PReLU | 0.76543 | 0.76025 |\n| 6 | epoch152-step3672-valid_loss0.4333-val_metric0.7929.ckpt | Lion | DenseVNet | 873K | TS_6_6 | InstanceNorm3d | PReLU | 0.76528 | 0.75417 |\n| 7 | epoch195-step4704-valid_loss0.4258-val_metric0.7914.ckpt | Lion | VoxResNet | 7.0M | TS_6_6 | InstanceNorm3d | PReLU | 0.77457 | 0.76593 |\n| 8 | epoch188-step4536-valid_loss0.4231-val_metric0.8659.ckpt | Lion | VoxHRNet | 1.4M | TS_73_6 | InstanceNorm3d | PReLU | 0.76738 | 0.75995 |\n| 9 | epoch198-step4776-valid_loss0.3471-val_metric0.8730.ckpt | Lion | VoxHRNet | 1.4M | TS_73_6 | InstanceNorm3d | PReLU | 0.76135 | 0.75848 |\n| 10 | epoch133-val_loss0.52-val_metric0.56-step3216.ckpt | Luoziqian | UNet3D | 1.1M | TS_6_4 | BatchNorm3d | PReLU | 0.76844 | 0.76320 |\n| 11 | epoch314-val_loss0.54-val_metric0.54-step7560.ckpt | Luoziqian | SegResNet | 1.2M | TS_6_4 | GroupNorm | ReLU | 0.75521 | 0.74647 |\n| 12 | epoch114-val_loss0.55-val_metric0.53-Step2760.ckpt | Luoziqian | UNet2E3D | 14.2M | TS_6_4 | BatchNorm3d | ReLU | 0.73758 | 0.72966 |\n\n\n## Ensemble Strategy (Partial Selection)\nWe select the models with the best public leaderboard scores for the final submission.\n\n| **Models** | **Ensemble Strategy** | **Certainty Threshold** | **Public LB** | **Private LB** | **Selected** |\n| --------------------------------- | --------------------- | --------------------- | ------------- | -------------- | ----------------- |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.23 | 0.79094 | 0.78641 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.18 | 0.79213 | 0.78630 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.15 | 0.79307 | 0.78457 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | weighted | 0.15 | 0.79247 | 0.78417 | ❌ |\n| [1, 2, 3, 4, 6, 12] | Average | 0.15 | 0.78701 | 0.78389 | ❌ |\n| [1, 2, 3, 4, 5, 6, 7] | Average | 0.15 | 0.79104 | 0.78277 | ❌ |\n| [1, 2, 3, 4, 7, 9, 12] | Average | 0.15 | 0.79391 | 0.78283 | ✅ |\n| [1, 2, 3, 4, 6, 7, 9, 10, 11, 12] | Average | 0.15 | 0.79355 | 0.78381 | ✅ |\n\n## Post-processing (Cluster Removal)\n\nWe used `CC3D` to convert the segmentation results into particle clusters and applied the following strategies for cluster selection:\n\n- Threshold-based clustering (the threshold is set to 0.15 for all classses to improve recall)\n- Cluster size filtering\n\n## Methods that Did Not Yield Improvements:\n\n- Synthetic data\n- Second-stage classification\n- Heavy-weight models (transformer-based models)\n\n## Code\n\n[Inference Notebook](https://www.kaggle.com/code/luoziqian/7-model-6tta-t4x2-patch-norm-v2?scriptVersionId=220452693)\n[Lion's Training Code](https://github.com/GWwangshuo/Kaggle-2024-CZII-Pub)\n[Luoziqian's Training Code](https://github.com/luoziqianX/CZII-CryoET-Object-Identification-2nd-luoziqian)\n\n## Reference\n\nGubins, Ilja, et al. \"SHREC 2020: Classification in cryo-electron tomograms.\" *Computers & Graphics* 91 (2020): 279-289.",
"votes": 44
},
{
"id": 3117309,
"postDate": "2025-02-06T20:36:24.863Z",
"content": "Wow, you have very strong single models. Focus on stabilizing the training might be the trick(s) we missed. Congratulations on the gold and the prize!
", "rawMarkdown": "Wow, you have very strong single models. Focus on stabilizing the training might be the trick(s) we missed. Congratulations on the gold and the prize!", "votes": 2 }, { "id": 3120885, "postDate": "2025-02-11T03:15:04.657Z", "content": "Congratulations !
\nI've realized that there are a lot of room for improvement even if segmentation + cc3d approach and lack of my skills to design experiments.
\nIn Luoziqian's Training Code, I cannot find output comp metrics in training code. Did you choose best model by other way ?
You can change the path_dir in compute-cv-7TTA.ipynb and run it to calculate the F-beta4 score of ckpts after training. I think the Tversky Loss for each class is enough for me to initially rule out less successful experiments. Since measuring F-beta4 during training would significantly increase the experiment time and my limited computing resources, I did not calculate it during training.
", "rawMarkdown": "You can change the path_dir in [compute-cv-7TTA.ipynb](https://github.com/luoziqianX/CZII-CryoET-Object-Identification-2nd-luoziqian/blob/main/compute-cv-7TTA.ipynb) and run it to calculate the F-beta4 score of ckpts after training. I think the Tversky Loss for each class is enough for me to initially rule out less successful experiments. Since measuring F-beta4 during training would significantly increase the experiment time and my limited computing resources, I did not calculate it during training.", "votes": 4 } ] }, { "id": 3119199, "postDate": "2025-02-09T02:21:27.833Z", "content": "Congratulations! @sjtuwangshuo .
\nWhich sample do you use to validate?
", "rawMarkdown": "Congratulations! @sjtuwangshuo .\n\nWhich sample do you use to validate? ", "replies": [ { "id": 3119239, "postDate": "2025-02-09T04:05:20.560Z", "content": "Initial Strategy:
\nRefinement:
\nSubsequently, Luoziqian observed that models validated on ['TS_5_4', 'TS_6_4', 'TS_69_2'] tend to achieve better public leaderboard performance, though not consistently. Based on this observation, I evaluate model performance using 7× TTA on these specific folds and submit the model with the highest F-beta score.
For details on the validation samples of the selected models used in the final ensemble, please refer to the \"Model Performance with 7× TTA Summary (Partial Selection)\" section of this post.
Congratulations! thank you for sharing your solution
\nI have a question :why experiment no.2 and no.10/11/12 have such a huge different valid score(0.7x vs 0.5x,but lb very close)?
", "rawMarkdown": "Congratulations! thank you for sharing your solution\n\nI have a question :why experiment no.2 and no.10/11/12 have such a huge different valid score(0.7x vs 0.5x,but lb very close)?\n\n", "replies": [ { "id": 3118546, "postDate": "2025-02-08T07:30:02.710Z", "content": "Could you please clarify what is meant by “0.7x vs. 0.5x, but lb very close”? Please note that the experiments presented thus far represent only a subset of the complete experimental results. Additionally, my colleague, Luoziqian, has developed several models based on the MONAI UNet architecture that achieve a public leaderboard score exceeding 0.760; however, these models do not exhibit improved performance when ensembled.
", "rawMarkdown": "Could you please clarify what is meant by “0.7x vs. 0.5x, but lb very close”? Please note that the experiments presented thus far represent only a subset of the complete experimental results. Additionally, my colleague, Luoziqian, has developed several models based on the MONAI UNet architecture that achieve a public leaderboard score exceeding 0.760; however, these models do not exhibit improved performance when ensembled.", "replies": [ { "id": 3118558, "postDate": "2025-02-08T07:42:32.960Z", "content": "噢是这样的,我看你实验的model列里面有val_metric这一项,no.2和no.10,no.11,no.12都是用TS_6_4作为验证集,好像这几个的验证集指标差异挺大的,想问问看是不是有什么特殊处理我错过了
", "rawMarkdown": "噢是这样的,我看你实验的model列里面有val_metric这一项,no.2和no.10,no.11,no.12都是用TS_6_4作为验证集,好像这几个的验证集指标差异挺大的,想问问看是不是有什么特殊处理我错过了" }, { "id": 3118572, "postDate": "2025-02-08T08:01:55.547Z", "content": "Our experiments indicated that several factors significantly affect performance, including spatial size, mask radius, data augmentation strategies, loss functions, normalization layers, and activation layers.
\nIn the comparison between Experiment No.2 and Experiment No.10, the following differences were observed matter:
Furthermore, when comparing Experiment No.2 with Experiments No.11 and No.12, we found that the MONAI UNet outperformed both SegResNet and UNet2E3D. This improved performance can be attributed to several architectural features of the MONAI UNet:
InstanceNorm3d in conjunction with PReLU activation.1/4 as opposed to 1/8, 1/16, or 1/32.ConvTransposed3D instead of conventional upsampling.residual blocks, which enhances parameter efficiency and reduce t the likelihood of overfitting.For both SegResNet and UNet2E3D, modifications were implemented based on our experimental investigations to facilitate training convergence. Specifically, we:
\nDespite these modifications, neither SegResNet nor UNet2E3D outperformed the MONAI UNet.
", "rawMarkdown": "Our experiments indicated that several factors significantly affect performance, including spatial size, mask radius, data augmentation strategies, loss functions, normalization layers, and activation layers.\n\nIn the comparison between Experiment `No.2` and Experiment `No.10`, the following differences were observed matter:\n- Patch spatial size\n- Mask radius\n- Data augmentation strategies\n- Loss functions\n- Number of classes\n\nFurthermore, when comparing Experiment `No.2` with Experiments `No.11` and `No.12`, we found that the MONAI UNet outperformed both SegResNet and UNet2E3D. This improved performance can be attributed to several architectural features of the MONAI UNet:\n\n- The use of `InstanceNorm3d` in conjunction with `PReLU activation`.\n- An encoder downsampling factor of `1/4` as opposed to `1/8`, `1/16`, or `1/32`.\n- The implementation of a deconvolution layer using `ConvTransposed3D` instead of conventional upsampling.\n- The incorporation of `residual blocks`, which enhances parameter efficiency and reduce t the likelihood of overfitting.\n\nFor both SegResNet and UNet2E3D, modifications were implemented based on our experimental investigations to facilitate training convergence. Specifically, we:\n- Revised the normalization and activation layers.\n- Replaced the decoder with a deconvolution layer.\n- Reduced the number of decoder channels to create a more lightweight model.\n\nDespite these modifications, neither SegResNet nor UNet2E3D outperformed the MONAI UNet.", "votes": 1 } ] } ] }, { "id": 3117336, "postDate": "2025-02-06T21:33:08.730Z", "content": "Congrats! Glad the notebook helped you get started!
", "rawMarkdown": "Congrats! Glad the notebook helped you get started!" }, { "id": 3118220, "postDate": "2025-02-07T18:57:19.297Z", "rawMarkdown": "", "isDeleted": true } ], "comments": [ { "id": 3117309, "author_name": "Sinan Calisir", "author_url": "", "post_date": "2025-02-06T20:36:24.863000", "content": "Wow, you have very strong single models. Focus on stabilizing the training might be the trick(s) we missed. Congratulations on the gold and the prize!
", "votes": 2, "replies": [] }, { "id": 3120885, "author_name": "Aurora_blue", "author_url": "", "post_date": "2025-02-11T03:15:04.657000", "content": "Congratulations !
\nI've realized that there are a lot of room for improvement even if segmentation + cc3d approach and lack of my skills to design experiments.
\nIn Luoziqian's Training Code, I cannot find output comp metrics in training code. Did you choose best model by other way ?
You can change the path_dir in compute-cv-7TTA.ipynb and run it to calculate the F-beta4 score of ckpts after training. I think the Tversky Loss for each class is enough for me to initially rule out less successful experiments. Since measuring F-beta4 during training would significantly increase the experiment time and my limited computing resources, I did not calculate it during training.
", "votes": 4, "replies": [] } ] }, { "id": 3119199, "author_name": "ForcewithMe", "author_url": "", "post_date": "2025-02-09T02:21:27.833000", "content": "Congratulations! @sjtuwangshuo .
\nWhich sample do you use to validate?
", "votes": 0, "replies": [ { "id": 3119239, "author_name": "AnnieGo", "author_url": "", "post_date": "2025-02-09T04:05:20.560000", "content": "Initial Strategy:
\nRefinement:
\nSubsequently, Luoziqian observed that models validated on ['TS_5_4', 'TS_6_4', 'TS_69_2'] tend to achieve better public leaderboard performance, though not consistently. Based on this observation, I evaluate model performance using 7× TTA on these specific folds and submit the model with the highest F-beta score.
For details on the validation samples of the selected models used in the final ensemble, please refer to the \"Model Performance with 7× TTA Summary (Partial Selection)\" section of this post.
Congratulations! thank you for sharing your solution
\nI have a question :why experiment no.2 and no.10/11/12 have such a huge different valid score(0.7x vs 0.5x,but lb very close)?
", "votes": 0, "replies": [ { "id": 3118546, "author_name": "AnnieGo", "author_url": "", "post_date": "2025-02-08T07:30:02.710000", "content": "Could you please clarify what is meant by “0.7x vs. 0.5x, but lb very close”? Please note that the experiments presented thus far represent only a subset of the complete experimental results. Additionally, my colleague, Luoziqian, has developed several models based on the MONAI UNet architecture that achieve a public leaderboard score exceeding 0.760; however, these models do not exhibit improved performance when ensembled.
", "votes": 0, "replies": [ { "id": 3118558, "author_name": "FatLiuyun", "author_url": "", "post_date": "2025-02-08T07:42:32.960000", "content": "噢是这样的,我看你实验的model列里面有val_metric这一项,no.2和no.10,no.11,no.12都是用TS_6_4作为验证集,好像这几个的验证集指标差异挺大的,想问问看是不是有什么特殊处理我错过了
", "votes": 0, "replies": [] }, { "id": 3118572, "author_name": "AnnieGo", "author_url": "", "post_date": "2025-02-08T08:01:55.547000", "content": "Our experiments indicated that several factors significantly affect performance, including spatial size, mask radius, data augmentation strategies, loss functions, normalization layers, and activation layers.
\nIn the comparison between Experiment No.2 and Experiment No.10, the following differences were observed matter:
Furthermore, when comparing Experiment No.2 with Experiments No.11 and No.12, we found that the MONAI UNet outperformed both SegResNet and UNet2E3D. This improved performance can be attributed to several architectural features of the MONAI UNet:
InstanceNorm3d in conjunction with PReLU activation.1/4 as opposed to 1/8, 1/16, or 1/32.ConvTransposed3D instead of conventional upsampling.residual blocks, which enhances parameter efficiency and reduce t the likelihood of overfitting.For both SegResNet and UNet2E3D, modifications were implemented based on our experimental investigations to facilitate training convergence. Specifically, we:
\nDespite these modifications, neither SegResNet nor UNet2E3D outperformed the MONAI UNet.
", "votes": 1, "replies": [] } ] } ] }, { "id": 3117336, "author_name": "fnands", "author_url": "", "post_date": "2025-02-06T21:33:08.730000", "content": "Congrats! Glad the notebook helped you get started!
", "votes": 0, "replies": [] }, { "id": 3118220, "author_name": "", "author_url": "", "post_date": "2025-02-07T18:57:19.297000", "content": "", "votes": 0, "replies": [] } ], "raw_markdown_by_id": { "3117241": "## Acknowledgments\n\nWe sincerely appreciate Kaggle and the competition organizers for offering this invaluable opportunity. We also extend our gratitude to @hengck23 and @fnands for their significant contributions. [**fnands's notebook**](https://www.kaggle.com/code/fnands/baseline-unet-train-submit/notebook) and [**hengck23's discussion**](https://www.kaggle.com/competitions/czii-cryo-et-object-identification/discussion/547350#3056648) provided a solid foundation for our approach. Finally, I am grateful to my teammate @luoziqian for the excellent collaboration.\n\n## Summary\n\nOur approach is based on an ensemble of multiple lightweight segmentation models, with parameter sizes ranging from 873K to 14.2M. Following segmentation, we computed particle centroids using CC3D and filtered small clusters based on voxel count statistics.\n\n## Overall Pipeline\n\nThe overall pipeline is illustrated below:\n\n\n\n## Model Architecture\n\nWe initiated our experiments using the MONAI UNet baseline model. Throughout our trials, we observed that models with a large number of parameters were prone to overfitting and often performed worse than lighter models. Consequently, we opted for lightweight architectures such as UNet3D, VoxResNet, VoxHRNet, SegResNet, DynUNet, and DenseVNet.\n\nHowever, while experimenting with VoxResNet, VoxHRNet, and DenseVNet, we encountered stability issues, including performance fluctuations and difficulties in convergence. Upon further analysis, we identified that MONAI UNet employs `InstanceNorm3d` and `PReLU`. By modifying the normalization and activation layers accordingly, we achieved more stable model performance.\n\nThe model architecture of MONAI UNet is shown below:\n\n\nThe following figure compares the training performance of MONAI UNet with InstanceNorm3d and PReLU versus BatchNorm3d and ReLU across 5 experiments, demonstrating that the use of InstanceNorm3d and PReLU results in more stable training.\n\n\n\nFor the final ensemble, we selected models based on their public leaderboard scores:\n\n- UNet3D\n- VoxResNet\n- VoxHRNet\n- SegResNet\n- DenseVNet\n- UNet2E3D\n\n## Training Strategy\n\nOur training configuration was designed to ensure stability and optimal performance. We found that the **segmentation mask radius**, **loss function** and **data augmentation strategies** played a crucial role in achieving reliable results.\n\n#### Segmentation Mask:\n\nWe applied ground truth masks with a customized radius for each particle.\n\n| **Particle Types** | **Default Radius** |**Luoziqian's Radius** | **Lion's Radius** |\n| ------------------- | ------------------ | ----------------------- | ---------------- |\n| apo-ferritin | 60 | 60 x 0.5 | 80 x 0.4 | \n| beta-galactosidase | 90 | 90 x 0.5 | 90 x 0.4 |\n| ribosome | 150 | 150 x 0.5 | 150 x 0.4 |\n| thyroglobulin | 130 | 130 x 0.5 |120 x 0.4 |\n| virus-like-particle | 135 | 135 x 0.5 | 150 x 0.4 | \n\n#### Training Settings:\n\n**Lion's** models:\n- patch size `[128, 256, 256]` or `[128, 384, 384]`\n- `200` epochs\n- 7 classes\n- Optimizer: AdamW with a learning rate of `0.001` (no learning rate scheduler)\n- Batch size: `2` or `4`\n- Drop path rate: `0.1` or `0.3`\n- Model selection based on the F-beta metric, save top-5 best model\n- Loss functions:\n - Tversky Loss\n - Cross-Entropy Loss with weights `[1.0, 1.0, 0.0, 2.0, 1.0, 2.0, 1.0]`\n\n**Luoziqian's** models\n- patch size `[128, 200, 200]` or `[128, 256, 256]`\n- `100` or `300` epochs\n- 6 classes\n- Early stopping with `patience=20`\n- Batch size: `1` or `2`\n- Model selection is based on the evaluation loss. The last 100 models are saved and their F-beta scores are verified\n- Loss functions:\n - Dice Loss\n - Tversky Loss\n - Cross-Entropy Loss, scaled to 0.05 or 0.1\n\n\n#### Augmentations:\n\n**Lion's** models:\n\n- RandCropByLabelClassesd with ratios `[1, 1, 1, 1, 2, 1, 2]` for balanced sampling\n- RandRotate90d\n- RandFlipd\n- RandAffined\n- RandGaussianNoised\n\n**Luoziqian's** models\n- RandCropByLabelClassesd\n- RandRotate90d\n- RandFlipd\n- RandShiftIntensityd\n\n\n#### Model Performance with 7 TTA Summary (Partial Selection)\n\n| **No** | **Model** | **Developer** | **Architecture** | **Parameters** | **Valid ID** | **Normalization** | **Activation** | **Public LB** | **Private LB** |\n| ------ | -------------------------------------------------------- | ----------------| ---------------- | -------------- | ----------------- | ----------------- | -------------- | ------------- | -------------- |\n| 1 | epoch122-step2952-valid_loss0.3625-val_metric0.8367.ckpt | Lion | UNet3D | 1.1M | TS_86_3 | InstanceNorm3d | PReLU | 0.77379 | 0.76582 |\n| 2 | epoch148-step3576-valid_loss1.1154-val_metric0.7722.ckpt | Lion | UNet3D | 1.1M | TS_6_4 | InstanceNorm3d | PReLU | 0.77021 | 0.76725 |\n| 3 | epoch153-step3696-valid_loss0.3021-val_metric0.8900.ckpt | Lion | UNet3D | 1.6M | TS_69_2 | InstanceNorm3d | PReLU | 0.77205 | 0.76676 |\n| 4 | epoch194-step4680-valid_loss1.0213-val_metric0.8788.ckpt | Lion | UNet3D | 1.1M | TS_69_2 | InstanceNorm3d | PReLU | 0.77390 | 0.76737 |\n| 5 | epoch138-step3336-valid_loss0.3690-val_metric0.8476.ckpt | Lion | UNet3D | 1.1M | TS_73_6 | InstanceNorm3d | PReLU | 0.76543 | 0.76025 |\n| 6 | epoch152-step3672-valid_loss0.4333-val_metric0.7929.ckpt | Lion | DenseVNet | 873K | TS_6_6 | InstanceNorm3d | PReLU | 0.76528 | 0.75417 |\n| 7 | epoch195-step4704-valid_loss0.4258-val_metric0.7914.ckpt | Lion | VoxResNet | 7.0M | TS_6_6 | InstanceNorm3d | PReLU | 0.77457 | 0.76593 |\n| 8 | epoch188-step4536-valid_loss0.4231-val_metric0.8659.ckpt | Lion | VoxHRNet | 1.4M | TS_73_6 | InstanceNorm3d | PReLU | 0.76738 | 0.75995 |\n| 9 | epoch198-step4776-valid_loss0.3471-val_metric0.8730.ckpt | Lion | VoxHRNet | 1.4M | TS_73_6 | InstanceNorm3d | PReLU | 0.76135 | 0.75848 |\n| 10 | epoch133-val_loss0.52-val_metric0.56-step3216.ckpt | Luoziqian | UNet3D | 1.1M | TS_6_4 | BatchNorm3d | PReLU | 0.76844 | 0.76320 |\n| 11 | epoch314-val_loss0.54-val_metric0.54-step7560.ckpt | Luoziqian | SegResNet | 1.2M | TS_6_4 | GroupNorm | ReLU | 0.75521 | 0.74647 |\n| 12 | epoch114-val_loss0.55-val_metric0.53-Step2760.ckpt | Luoziqian | UNet2E3D | 14.2M | TS_6_4 | BatchNorm3d | ReLU | 0.73758 | 0.72966 |\n\n\n## Ensemble Strategy (Partial Selection)\nWe select the models with the best public leaderboard scores for the final submission.\n\n| **Models** | **Ensemble Strategy** | **Certainty Threshold** | **Public LB** | **Private LB** | **Selected** |\n| --------------------------------- | --------------------- | --------------------- | ------------- | -------------- | ----------------- |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.23 | 0.79094 | 0.78641 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.18 | 0.79213 | 0.78630 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | Average | 0.15 | 0.79307 | 0.78457 | ❌ |\n| [1, 2, 3, 4, 7, 8, 12] | weighted | 0.15 | 0.79247 | 0.78417 | ❌ |\n| [1, 2, 3, 4, 6, 12] | Average | 0.15 | 0.78701 | 0.78389 | ❌ |\n| [1, 2, 3, 4, 5, 6, 7] | Average | 0.15 | 0.79104 | 0.78277 | ❌ |\n| [1, 2, 3, 4, 7, 9, 12] | Average | 0.15 | 0.79391 | 0.78283 | ✅ |\n| [1, 2, 3, 4, 6, 7, 9, 10, 11, 12] | Average | 0.15 | 0.79355 | 0.78381 | ✅ |\n\n## Post-processing (Cluster Removal)\n\nWe used `CC3D` to convert the segmentation results into particle clusters and applied the following strategies for cluster selection:\n\n- Threshold-based clustering (the threshold is set to 0.15 for all classses to improve recall)\n- Cluster size filtering\n\n## Methods that Did Not Yield Improvements:\n\n- Synthetic data\n- Second-stage classification\n- Heavy-weight models (transformer-based models)\n\n## Code\n\n[Inference Notebook](https://www.kaggle.com/code/luoziqian/7-model-6tta-t4x2-patch-norm-v2?scriptVersionId=220452693)\n[Lion's Training Code](https://github.com/GWwangshuo/Kaggle-2024-CZII-Pub)\n[Luoziqian's Training Code](https://github.com/luoziqianX/CZII-CryoET-Object-Identification-2nd-luoziqian)\n\n## Reference\n\nGubins, Ilja, et al. \"SHREC 2020: Classification in cryo-electron tomograms.\" *Computers & Graphics* 91 (2020): 279-289.",
"3117309": "Wow, you have very strong single models. Focus on stabilizing the training might be the trick(s) we missed. Congratulations on the gold and the prize!",
"3120885": "Congratulations !\nI've realized that there are a lot of room for improvement even if segmentation + cc3d approach and lack of my skills to design experiments.\nIn Luoziqian's Training Code, I cannot find output comp metrics in training code. Did you choose best model by other way ?",
"3119199": "Congratulations! @sjtuwangshuo .\n\nWhich sample do you use to validate? ",
"3118525": "Congratulations! thank you for sharing your solution\n\nI have a question :why experiment no.2 and no.10/11/12 have such a huge different valid score(0.7x vs 0.5x,but lb very close)?\n\n",
"3117336": "Congrats! Glad the notebook helped you get started!",
"3118220": ""
}
}