
\n\nTransformers, which are popular for language modeling, have been explored for solving vision tasks recently, e.g., the Vision Transformers (ViT) for image classification. The ViT model splits each image into a sequence of tokens with fixed length and then applies multiple Transformer layers to model their global relation for classification. However, ViT achieves inferior performance compared with CNNs when trained from scratch on a midsize dataset (e.g., ImageNet). We find it is because: 1) the simple tokenization of input images fails to model the important local structure (e.g., edges, lines) among neighboring pixels, leading to its low training sample efficiency; 2) the redundant attention backbone design of ViT leads to limited feature richness in fixed computation budgets and limited training samples.
\n
\n To overcome such limitations, we propose a new Tokens-To-Token Vision Transformers (T2T-ViT), which introduces 1) a layer-wise Tokens-to-Token (T2T) transformation to progressively structurize the image to tokens by recursively aggregating neighboring Tokens into one Token (Tokens-to-Token), such that local structure presented by surrounding tokens can be modeled and tokens length can be reduced; 2) an efficient backbone with a deep-narrow structure for vision transformers motivated by CNN architecture design after extensive study. Notably, T2T-ViT reduces the parameter counts and MACs of vanilla ViT by 200\\%, while achieving more than 2.5\\% improvement when trained from scratch on ImageNet. It also outperforms ResNets and achieves comparable performance with MobileNets when directly training on ImageNet. For example, T2T-ViT with ResNet50 comparable size can achieve 80.7\\% top-1 accuracy on ImageNet.
paper: https://arxiv.org/abs/2101.11986v1
\ncode: https://github.com/yitu-opensource/T2T-ViT
Wasn't the thing about ViT being that is it pretrained on massive amounts of data, it can perform just like cnns or even better?
\nAlso, even I think that the hype is mostly about ViT crossing a line from nlp to computer vision.
", "rawMarkdown": "Wasn't the thing about ViT being that is it pretrained on massive amounts of data, it can perform just like cnns or even better?\n\nAlso, even I think that the hype is mostly about ViT crossing a line from nlp to computer vision.", "votes": null } ], "comments": [ { "id": 1179416, "author_name": "vyombhatia", "author_url": "", "post_date": "01/31/2021 14:48:06", "content": "Wasn't the thing about ViT being that is it pretrained on massive amounts of data, it can perform just like cnns or even better?
\nAlso, even I think that the hype is mostly about ViT crossing a line from nlp to computer vision.
", "votes": null, "replies": [] } ], "raw_markdown_by_id": { "1177781": "> Transformers, which are popular for language modeling, have been explored for solving vision tasks recently, e.g., the Vision Transformers (ViT) for image classification. The ViT model splits each image into a sequence of tokens with fixed length and then applies multiple Transformer layers to model their global relation for classification. However, ViT achieves inferior performance compared with CNNs when trained from scratch on a midsize dataset (e.g., ImageNet). We find it is because: 1) the simple tokenization of input images fails to model the important local structure (e.g., edges, lines) among neighboring pixels, leading to its low training sample efficiency; 2) the redundant attention backbone design of ViT leads to limited feature richness in fixed computation budgets and limited training samples.\nTo overcome such limitations, we propose a new Tokens-To-Token Vision Transformers (T2T-ViT), which introduces 1) a layer-wise Tokens-to-Token (T2T) transformation to progressively structurize the image to tokens by recursively aggregating neighboring Tokens into one Token (Tokens-to-Token), such that local structure presented by surrounding tokens can be modeled and tokens length can be reduced; 2) an efficient backbone with a deep-narrow structure for vision transformers motivated by CNN architecture design after extensive study. Notably, T2T-ViT reduces the parameter counts and MACs of vanilla ViT by 200\\%, while achieving more than 2.5\\% improvement when trained from scratch on ImageNet. It also outperforms ResNets and achieves comparable performance with MobileNets when directly training on ImageNet. For example, T2T-ViT with ResNet50 comparable size can achieve 80.7\\% top-1 accuracy on ImageNet.\n\npaper: https://arxiv.org/abs/2101.11986v1\ncode: https://github.com/yitu-opensource/T2T-ViT\n\n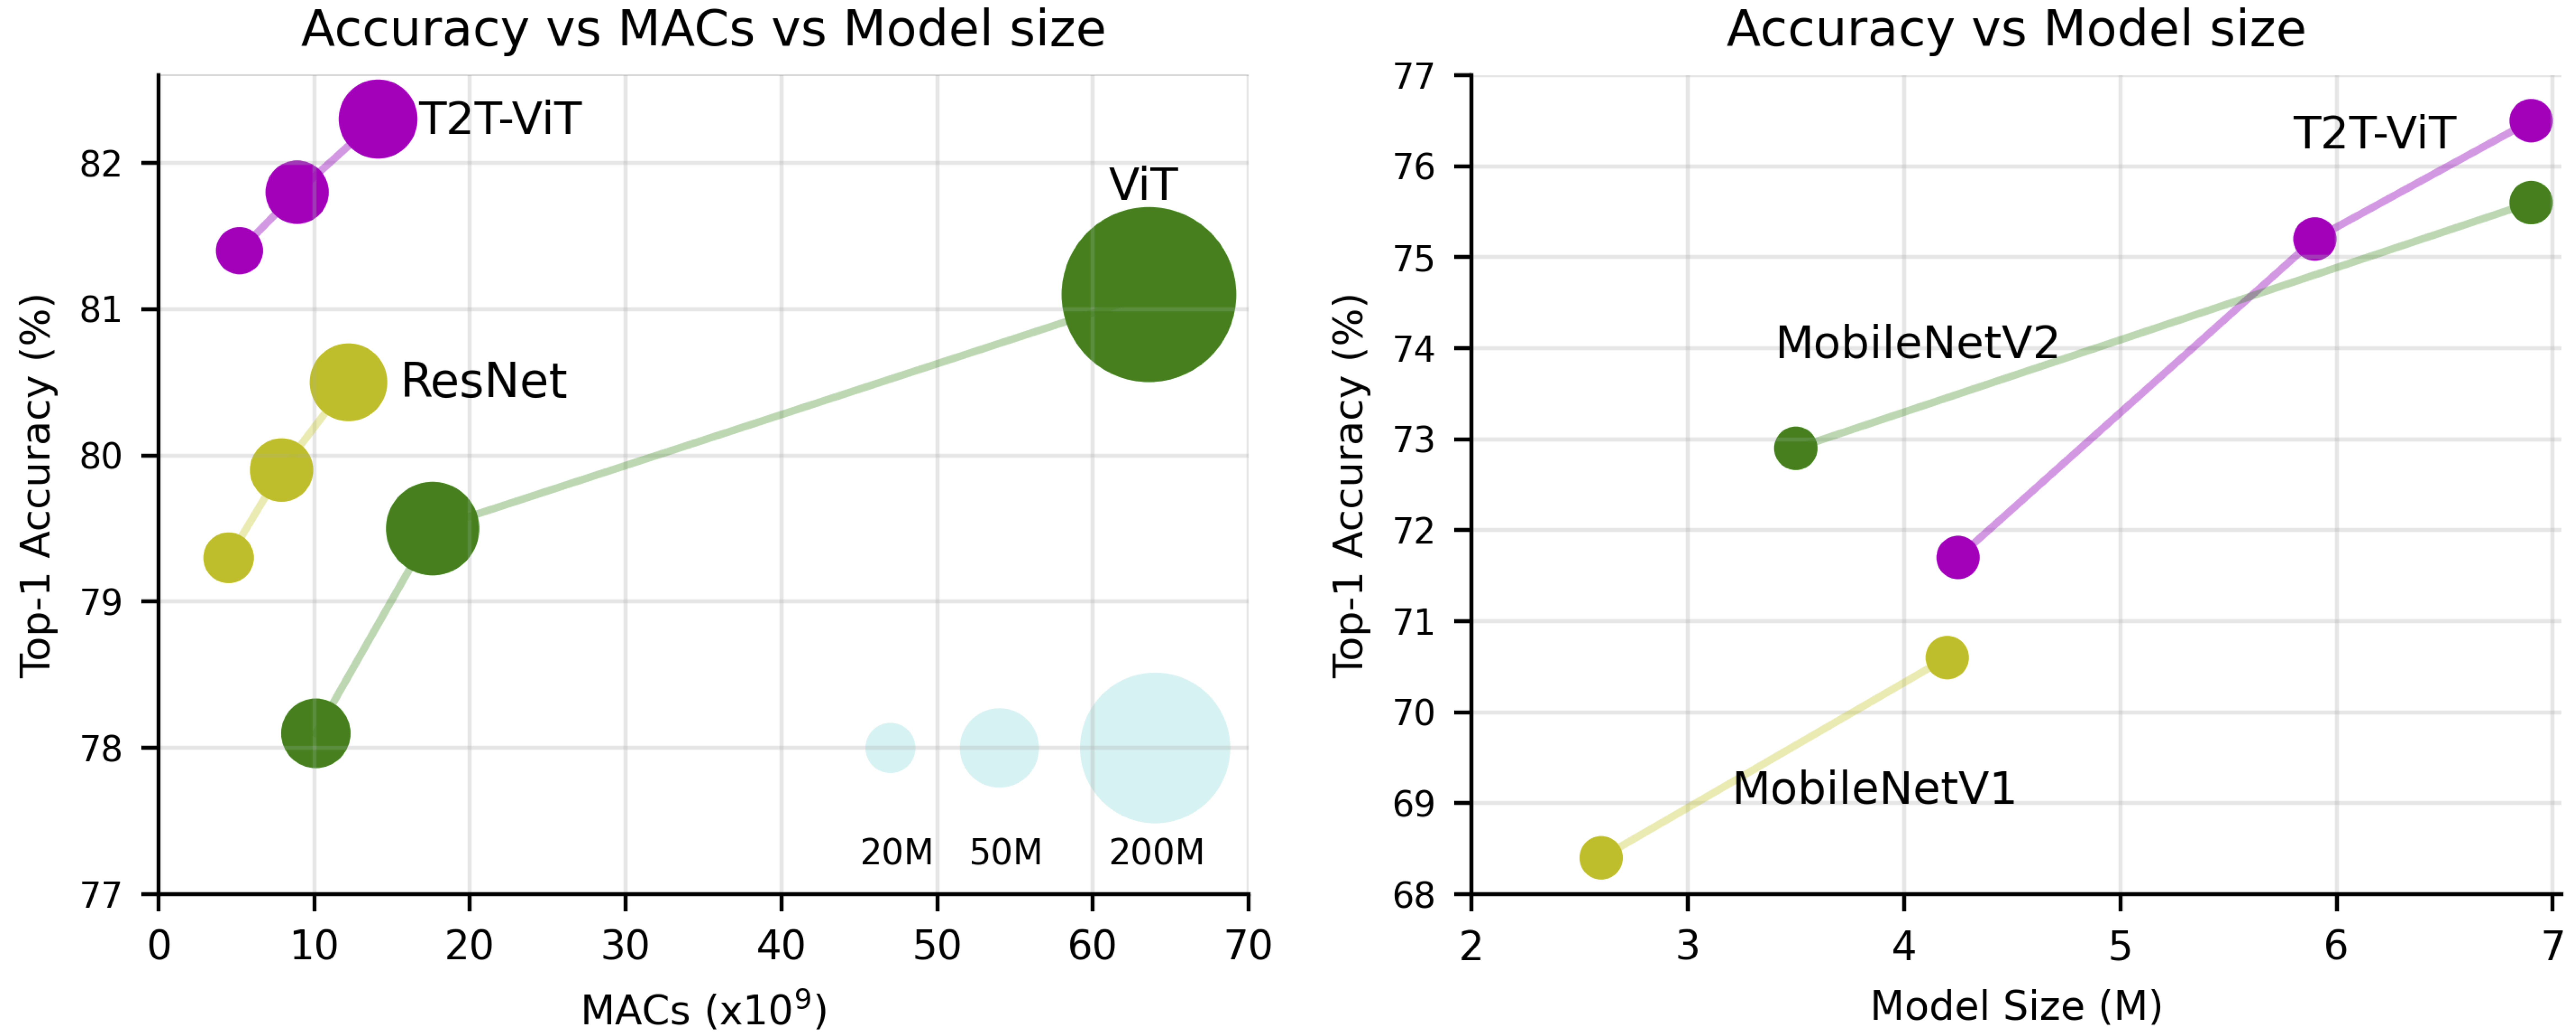", "1179416": "Wasn't the thing about ViT being that is it pretrained on massive amounts of data, it can perform just like cnns or even better?\n\nAlso, even I think that the hype is mostly about ViT crossing a line from nlp to computer vision." }, "source": "meta" }