\n

Dear all,
\nI have created 2500 additional images with CrossFade augmentation. The file has been extended with the names of the new images and their labels. (trainA.csv)
\n2500 CrossFade Augmented Images
", "messages": [ { "id": "1113915", "postDate": "12/15/2020 19:53:34", "content": "Dear all,
\nI have created 2500 additional images with CrossFade augmentation. The file has been extended with the names of the new images and their labels. (trainA.csv)
\n2500 CrossFade Augmented Images
", "rawMarkdown": "Dear all,\n\nI have created 2500 additional images with CrossFade augmentation. The file has been extended with the names of the new images and their labels. (trainA.csv)\n\n[2500 CrossFade Augmented Images](https://www.kaggle.com/frankmollard/2500-mixup-augmented-images)", "votes": null }, { "id": "1116806", "postDate": "12/17/2020 13:35:56", "content": "I have never used CrossFade…. does it help? because from the images i dont think it can help
", "rawMarkdown": "I have never used CrossFade.... does it help? because from the images i dont think it can help", "votes": null }, { "id": "1116910", "postDate": "12/17/2020 14:58:49", "content": "It is also called MixUp Augmentation.
\n
Very Interesting!!! I didn't even know something like this existed. Thanks for sharing!
", "rawMarkdown": "Very Interesting!!! I didn't even know something like this existed. Thanks for sharing!", "votes": null }, { "id": "1116980", "postDate": "12/17/2020 16:02:01", "content": "Usually you would do this in the training loop, here are the mixup functions used:
\ndef mixup(data,targets,alpha):\n\n indices = torch.randperm(data.size(0))\n shuffled_data = data[indices]\n shuffled_targets = targets[indices]\n\n lam = np.random.beta(alpha, alpha)\n data = data * lam + shuffled_data * (1 - lam)\n targets = [targets, shuffled_targets, lam]\n\n return data, targets\n\ndef mixup_criterion(preds, targets):\n targets1, targets2, lam = targets\n criterion = nn.CrossEntropyLoss()\n return lam * criterion(preds, targets1) + (1 - lam) * criterion(\n preds, targets2)\nthen in the training loop:
\nfor batch_idx, (images, target) in enumerate(trainloader):\n image, target=mixup(image, target, 0.4)\n output = model(image)\n loss=mixup_criterion(output,target)\n ...\nVery nice solution. However, you have a run time advantage due to the preprocessing.
", "rawMarkdown": "Very nice solution. However, you have a run time advantage due to the preprocessing.", "votes": null }, { "id": "1117129", "postDate": "12/17/2020 18:38:31", "content": "Honestly it is negliable computation, for me it adds 15-30 sec per epoch and with this way you technically never have the same examples per epoch. You can do the same with cutmix
", "rawMarkdown": "Honestly it is negliable computation, for me it adds 15-30 sec per epoch and with this way you technically never have the same examples per epoch. You can do the same with cutmix", "votes": null }, { "id": "1117143", "postDate": "12/17/2020 18:59:11", "content": "I recommend to use a simple generator for the preprocessed images as well. I have created them to add them to the existing images. Therefore, the targetA.csv i added with the corresponding lable. This is just an additional option.
", "rawMarkdown": "I recommend to use a simple generator for the preprocessed images as well. I have created them to add them to the existing images. Therefore, the targetA.csv i added with the corresponding lable. This is just an additional option.", "votes": null }, { "id": "1118976", "postDate": "12/19/2020 15:41:58", "content": "really great to know. Thanks !
", "rawMarkdown": "really great to know. Thanks !", "votes": null } ], "comments": [ { "id": 1116806, "author_name": "harshsdw", "author_url": "", "post_date": "12/17/2020 13:35:56", "content": "I have never used CrossFade…. does it help? because from the images i dont think it can help
", "votes": null, "replies": [ { "id": 1116910, "author_name": "frankmollard", "author_url": "", "post_date": "12/17/2020 14:58:49", "content": "It is also called MixUp Augmentation.
\n
Very Interesting!!! I didn't even know something like this existed. Thanks for sharing!
", "votes": null, "replies": [] }, { "id": 1118976, "author_name": "", "author_url": "", "post_date": "12/19/2020 15:41:58", "content": "really great to know. Thanks !
", "votes": null, "replies": [] } ] }, { "id": 1116980, "author_name": "yannmajewski", "author_url": "", "post_date": "12/17/2020 16:02:01", "content": "Usually you would do this in the training loop, here are the mixup functions used:
\ndef mixup(data,targets,alpha):\n\n indices = torch.randperm(data.size(0))\n shuffled_data = data[indices]\n shuffled_targets = targets[indices]\n\n lam = np.random.beta(alpha, alpha)\n data = data * lam + shuffled_data * (1 - lam)\n targets = [targets, shuffled_targets, lam]\n\n return data, targets\n\ndef mixup_criterion(preds, targets):\n targets1, targets2, lam = targets\n criterion = nn.CrossEntropyLoss()\n return lam * criterion(preds, targets1) + (1 - lam) * criterion(\n preds, targets2)\nthen in the training loop:
\nfor batch_idx, (images, target) in enumerate(trainloader):\n image, target=mixup(image, target, 0.4)\n output = model(image)\n loss=mixup_criterion(output,target)\n ...\nVery nice solution. However, you have a run time advantage due to the preprocessing.
", "votes": null, "replies": [] }, { "id": 1117129, "author_name": "yannmajewski", "author_url": "", "post_date": "12/17/2020 18:38:31", "content": "Honestly it is negliable computation, for me it adds 15-30 sec per epoch and with this way you technically never have the same examples per epoch. You can do the same with cutmix
", "votes": null, "replies": [] }, { "id": 1117143, "author_name": "frankmollard", "author_url": "", "post_date": "12/17/2020 18:59:11", "content": "I recommend to use a simple generator for the preprocessed images as well. I have created them to add them to the existing images. Therefore, the targetA.csv i added with the corresponding lable. This is just an additional option.
", "votes": null, "replies": [] } ] } ], "raw_markdown_by_id": { "1113915": "Dear all,\n\nI have created 2500 additional images with CrossFade augmentation. The file has been extended with the names of the new images and their labels. (trainA.csv)\n\n[2500 CrossFade Augmented Images](https://www.kaggle.com/frankmollard/2500-mixup-augmented-images)", "1116806": "I have never used CrossFade.... does it help? because from the images i dont think it can help", "1116910": "It is also called MixUp Augmentation.\n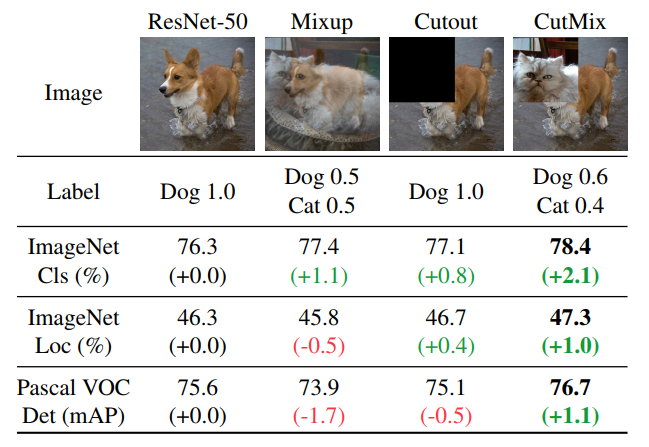", "1116941": "Very Interesting!!! I didn't even know something like this existed. Thanks for sharing!", "1116980": "Usually you would do this in the training loop, here are the mixup functions used:\n```\ndef mixup(data,targets,alpha):\n \n indices = torch.randperm(data.size(0))\n shuffled_data = data[indices]\n shuffled_targets = targets[indices]\n \n lam = np.random.beta(alpha, alpha)\n data = data * lam + shuffled_data * (1 - lam)\n targets = [targets, shuffled_targets, lam]\n\n return data, targets\n\ndef mixup_criterion(preds, targets):\n targets1, targets2, lam = targets\n criterion = nn.CrossEntropyLoss()\n return lam * criterion(preds, targets1) + (1 - lam) * criterion(\n preds, targets2)\n```\n\n\nthen in the training loop:\n```\nfor batch_idx, (images, target) in enumerate(trainloader):\n image, target=mixup(image, target, 0.4)\n output = model(image)\n loss=mixup_criterion(output,target)\n ...\n```", "1117058": "Very nice solution. However, you have a run time advantage due to the preprocessing.", "1117129": "Honestly it is negliable computation, for me it adds 15-30 sec per epoch and with this way you technically never have the same examples per epoch. You can do the same with cutmix", "1117143": "I recommend to use a simple generator for the preprocessed images as well. I have created them to add them to the existing images. Therefore, the targetA.csv i added with the corresponding lable. This is just an additional option.", "1118976": "really great to know. Thanks !" }, "source": "meta" }