
Thanks to kaggle and everyone involved for hosting this exciting competition. It was a great learning experience and it was very interesting to see how much of our 1st place cryo ET methodology could be applied here. Thanks to @bloodaxe for this great team experience. I would also like to thank the Armed Forces of Ukraine for providing safety and security for my team mate to participate in this competition.
\nThe solution is an ensemble of a simple 3D-ResNet18 Classifier and object detection models from MONAI. We also used MONAI for augmentations, and exported models via jit or TensorRT, which gave significant speedup and enabled us to have a slightly larger ensemble. We use the additional data shared by @brendanartley
\nThis post covers the ResNet18 classification based approach. For object detection part see @bloodaxe writeup: 4th place solution [Object Detection Part]
\nI split the original training data by Voxel Size and the external data by dataset id, to somewhat mimic train/ test difference. 4 Folds were used. Correlation with LB was not very good, so I mainly relied on LB score for feedback.
\n3D images were scaled to a fixed voxel size of 15.6 and saved to disk using int8.
\nSince models are trained from scratch, augmentations were essential to prevent overfitting.
\nI used RandomCrop (size 96x160x160), Flip on each axis within the torch dataloader, and additionally scale + rotation on GPU (all from MONAI). Additionally, I used a customized implementation of MixUp which was highly effective to train longer and prevent overfitting. I implemented a version which makes sure to not have more than 1 motor in a mixed patch. Additionally, positive samples, i.e. crops with motor in it, were oversampled by having a total fraction of 12.5%
Modelling was quite interesting in this competition. I started with the 3D UNET from our 1st place solution of CryoET competition, which worked already quite well. After learning about the forgiveness of the competition metric with respect to localization, I tried to simplify the model further and get rid of any decoder altogether, since the 32x downscaled model output should already be enough. Surprisingly, a simple ResNet3D encoder worked. My approach works the following:
\nInput for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 3x5x5 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss.
\nFor inference I used a sliding window aproach with an overlap of 0.5. For motor localisation, simplytake the patch with max prediction value of the 75 classes. Then use the patch location + and offset coming from the 3x5x5 grid to determine the final localisation. This very simple and fast model scores 0.875 on public LB (5th place) individually!
The architecture might be easier to understand via code:
\n monai.networks.nets mnn\n\n ():\n bs, c, d, h, w = y.shape\n idxs = torch.where(y>)\n item idxs[:]:\n item //= scale\n y2 = torch.zeros((bs,c,d//scale,h//scale,w//scale), dtype=y.dtype, layout=y.layout, device=y.device)\n y2[idxs] += \n y2\n\ncfg.backbone_args = (model_name=,\n spatial_dims=, \n pretrained=, \nin_channels=)\n\n (nn.Module):\n\n ():\n (Net, ).__init__()\n\n .backbone = mnn.ResNetFeatures(**cfg.backbone_args)\n .global_pool = nn.AdaptiveAvgPool3d()\n .reg_head = nn.Conv3d(,,kernel_size=,stride=)\n .cls_head = torch.nn.Linear(,) \n\n ():\n\n x = batch[]\n\n out = .backbone(x)[-]\n loc_logits = .reg_head(out)\n cls_logits = .cls_head(.global_pool(out).flatten())\n\n loss = .custom_loss(y,loc_logits,cls_logits)\n outputs = {:loss,:loc_logits}\n outputs\n\n ():\n\n y2 = downscale(target,scale=)\n l = logits.flatten()\n y3 = y2.flatten()\n y3 = torch.cat([y3,-y3.()[][:,]],dim=-)\n l2 = torch.cat([l,cls_logits],dim=-)\n l_cls = DenseCrossEntropy1D()(l2,y3)\n l_cls\nFor threshoolding I used a quantile based a aproach as this was much more stable when comparing different models.
\nThe model was trained with bf16, and each fold needs about 17h on a single A100 for training. Although the model is small and simple, I tried a lot of other architectures, and alternatives performed much worse. So I sticked with this one.
\nCode base is very close to 1st place solution of cryo et , so I will save me the trouble to publish this one.
\nCheers. Questions welcome.
Thanks for the write up. So it seems that for 3d medical image, 3d net often works better than 2d net, even when there is domain shift or the 3d net is simple.
\nThe softmax localisation directly solved the the problem and replace the post processing
", "rawMarkdown": "Thanks for the write up. So it seems that for 3d medical image, 3d net often works better than 2d net, even when there is domain shift or the 3d net is simple.\n\nThe softmax localisation directly solved the the problem and replace the post processing", "votes": null }, { "id": "3218805", "postDate": "06/06/2025 18:12:08", "content": "\n\nInput for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 355 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss.
\n
Giving a class for each pixel in the grid. Localization by classification, that blow up mind. Very nice one!
", "rawMarkdown": ">Input for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 355 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss.\n\nGiving a class for each pixel in the grid. Localization by classification, that blow up mind. Very nice one!", "votes": null }, { "id": "3218852", "postDate": "06/06/2025 19:49:05", "content": "This approach shares the same idea with SimCC, which is a little bit generalized version even for finegrained localization. Also remind me of DSNT with spatial softmax+no post processing as well
", "rawMarkdown": "This approach shares the same idea with [SimCC](https://arxiv.org/pdf/2107.03332), which is a little bit generalized version even for finegrained localization. Also remind me of [DSNT](https://arxiv.org/pdf/1801.07372) with spatial softmax+no post processing as well", "votes": null }, { "id": "3218858", "postDate": "06/06/2025 20:09:42", "content": "@christofhenkel amazing idea, the approach is simple but also hard to discover. When did you find this?
", "rawMarkdown": "christofhenkel amazing idea, the approach is simple but also hard to discover. When did you find this?", "votes": null }, { "id": "3218860", "postDate": "06/06/2025 20:13:15", "content": "Thanks, very unique and elegant solution.
\nI’m suprised that you successed with small XY patch size of (160, 160). Now I know that one can make it works.
\nOne more question, have you tried direct regression approach, so we need to predict 4 logits only?
Yes, I tried direct regression. It was the 2nd best approach for me
", "rawMarkdown": "Yes, I tried direct regression. It was the 2nd best approach for me", "votes": null }, { "id": "3219087", "postDate": "06/07/2025 06:38:04", "content": "I found it 3 weeks before end. I started with Segmentation using Unet, like 1st place. Then using a lot of experiments arrived at a regression based solution, i.e. using 4 logits output. 1 Logit for motor/ no motor classification and 3 logits for xyz offset. Then simplified to using the feature map directly with a BCE loss, and finally changed to CE Loss as only one output pixel can be correct at max.
", "rawMarkdown": "I found it 3 weeks before end. I started with Segmentation using Unet, like 1st place. Then using a lot of experiments arrived at a regression based solution, i.e. using 4 logits output. 1 Logit for motor/ no motor classification and 3 logits for xyz offset. Then simplified to using the feature map directly with a BCE loss, and finally changed to CE Loss as only one output pixel can be correct at max.", "votes": null }, { "id": "3219183", "postDate": "06/07/2025 08:57:29", "content": "@christofhenkel that's clutch. Look forward to explore deeper about your method. Seems it can have further innovative designs.
", "rawMarkdown": "christofhenkel that's clutch. Look forward to explore deeper about your method. Seems it can have further innovative designs.", "votes": null }, { "id": "3219221", "postDate": "06/07/2025 10:24:25", "content": "i think accuracy of the coord is not issue here becuase the radius threshold in metric computation is large.
\ni think there are several motor like structure in one tomograph and the key to winning could be choosing the correct one.
\nso \"sofmax-based loss\" is a good choice. (this is the same reason why 2d approach get slightly lower score ?)
the issue is how to avoid overfitting when training with \"sofmax-based loss\" as this converge \"much more easily\".
", "rawMarkdown": "i think accuracy of the coord is not issue here becuase the radius threshold in metric computation is large.\ni think there are several motor like structure in one tomograph and the key to winning could be choosing the correct one.\nso \"sofmax-based loss\" is a good choice. (this is the same reason why 2d approach get slightly lower score ?)\n\nthe issue is how to avoid overfitting when training with \"sofmax-based loss\" as this converge \"much more easily\".", "votes": null }, { "id": "3219222", "postDate": "06/07/2025 10:26:00", "content": "i am curious if \"3 logits for xyz offset\" is better than \"1 logits for xyz offset\". do you experiment results for it? decoupling seems to be a possible regularisation and maybe reduce overfitting?
", "rawMarkdown": "i am curious if \"3 logits for xyz offset\" is better than \"1 logits for xyz offset\". do you experiment results for it? decoupling seems to be a possible regularisation and maybe reduce overfitting?", "votes": null }, { "id": "3219239", "postDate": "06/07/2025 11:04:09", "content": "@hengck23 I think later one is better, handling everything all at once seems have advantages. I've tried his strategy in my dual-GNN approach, the pb score instantly reach 0.876-0.885
", "rawMarkdown": "hengck23 I think later one is better, handling everything all at once seems have advantages. I've tried his strategy in my dual-GNN approach, the pb score instantly reach 0.876-0.885", "votes": null }, { "id": "3221741", "postDate": "06/11/2025 11:55:28", "content": "\n\nI flatten the 355 output \"pixels\"
\n
Can you explain where the \"355\" comes from here please?
", "rawMarkdown": "> I flatten the 355 output \"pixels\"\n\nCan you explain where the \"355\" comes from here please?", "votes": null }, { "id": "3222112", "postDate": "06/11/2025 20:26:58", "content": "its a typo. I meant \"flatten the 3x5x5 output pixels\"
", "rawMarkdown": "its a typo. I meant \"flatten the 3x5x5 output pixels\"", "votes": null }, { "id": "3235523", "postDate": "06/29/2025 10:49:25", "content": "\n\nI implemented a version which makes sure to not have more than 1 motor in a mixed patch
\n
Hi @christofhenkel, could you please clarify what exactly this means? Does this imply
\nOR
\nThanks
", "rawMarkdown": "> I implemented a version which makes sure to not have more than 1 motor in a mixed patch\n\nHi @christofhenkel, could you please clarify what exactly this means? Does this imply\n\n1. You only use original data samples that contain a single motor, and your MixUp implementation just ensures that you don’t accidentally introduce a second motor by mixing patches with motors at different locations?\n\nOR\n\n2. Your MixUp implementation handles cases where input patches itself may contain more than one motor, but the logic ensures that only one motor remains in the mixed patch (possibly by masking, cropping, or other logic)?\n\n\nThanks", "votes": null } ], "comments": [ { "id": 3218799, "author_name": "hengck23", "author_url": "", "post_date": "06/06/2025 17:56:12", "content": "Thanks for the write up. So it seems that for 3d medical image, 3d net often works better than 2d net, even when there is domain shift or the 3d net is simple.
\nThe softmax localisation directly solved the the problem and replace the post processing
", "votes": null, "replies": [ { "id": 3218852, "author_name": "dangnh0611", "author_url": "", "post_date": "06/06/2025 19:49:05", "content": "This approach shares the same idea with SimCC, which is a little bit generalized version even for finegrained localization. Also remind me of DSNT with spatial softmax+no post processing as well
", "votes": null, "replies": [ { "id": 3219221, "author_name": "hengck23", "author_url": "", "post_date": "06/07/2025 10:24:25", "content": "i think accuracy of the coord is not issue here becuase the radius threshold in metric computation is large.
\ni think there are several motor like structure in one tomograph and the key to winning could be choosing the correct one.
\nso \"sofmax-based loss\" is a good choice. (this is the same reason why 2d approach get slightly lower score ?)
the issue is how to avoid overfitting when training with \"sofmax-based loss\" as this converge \"much more easily\".
", "votes": null, "replies": [] } ] } ] }, { "id": 3218805, "author_name": "sacuscreed", "author_url": "", "post_date": "06/06/2025 18:12:08", "content": "\n\nInput for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 355 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss.
\n
Giving a class for each pixel in the grid. Localization by classification, that blow up mind. Very nice one!
", "votes": null, "replies": [] }, { "id": 3218858, "author_name": "tom99763", "author_url": "", "post_date": "06/06/2025 20:09:42", "content": "@christofhenkel amazing idea, the approach is simple but also hard to discover. When did you find this?
", "votes": null, "replies": [ { "id": 3219087, "author_name": "christofhenkel", "author_url": "", "post_date": "06/07/2025 06:38:04", "content": "I found it 3 weeks before end. I started with Segmentation using Unet, like 1st place. Then using a lot of experiments arrived at a regression based solution, i.e. using 4 logits output. 1 Logit for motor/ no motor classification and 3 logits for xyz offset. Then simplified to using the feature map directly with a BCE loss, and finally changed to CE Loss as only one output pixel can be correct at max.
", "votes": null, "replies": [ { "id": 3219183, "author_name": "tom99763", "author_url": "", "post_date": "06/07/2025 08:57:29", "content": "@christofhenkel that's clutch. Look forward to explore deeper about your method. Seems it can have further innovative designs.
", "votes": null, "replies": [] }, { "id": 3219222, "author_name": "hengck23", "author_url": "", "post_date": "06/07/2025 10:26:00", "content": "i am curious if \"3 logits for xyz offset\" is better than \"1 logits for xyz offset\". do you experiment results for it? decoupling seems to be a possible regularisation and maybe reduce overfitting?
", "votes": null, "replies": [ { "id": 3219239, "author_name": "tom99763", "author_url": "", "post_date": "06/07/2025 11:04:09", "content": "@hengck23 I think later one is better, handling everything all at once seems have advantages. I've tried his strategy in my dual-GNN approach, the pb score instantly reach 0.876-0.885
", "votes": null, "replies": [] } ] } ] } ] }, { "id": 3218860, "author_name": "dangnh0611", "author_url": "", "post_date": "06/06/2025 20:13:15", "content": "Thanks, very unique and elegant solution.
\nI’m suprised that you successed with small XY patch size of (160, 160). Now I know that one can make it works.
\nOne more question, have you tried direct regression approach, so we need to predict 4 logits only?
Yes, I tried direct regression. It was the 2nd best approach for me
", "votes": null, "replies": [] } ] }, { "id": 3221741, "author_name": "optimo", "author_url": "", "post_date": "06/11/2025 11:55:28", "content": "\n\nI flatten the 355 output \"pixels\"
\n
Can you explain where the \"355\" comes from here please?
", "votes": null, "replies": [ { "id": 3222112, "author_name": "christofhenkel", "author_url": "", "post_date": "06/11/2025 20:26:58", "content": "its a typo. I meant \"flatten the 3x5x5 output pixels\"
", "votes": null, "replies": [] } ] }, { "id": 3235523, "author_name": "uryednap", "author_url": "", "post_date": "06/29/2025 10:49:25", "content": "\n\nI implemented a version which makes sure to not have more than 1 motor in a mixed patch
\n
Hi @christofhenkel, could you please clarify what exactly this means? Does this imply
\nOR
\nThanks
", "votes": null, "replies": [] } ], "raw_markdown_by_id": { "3218735": "Thanks to kaggle and everyone involved for hosting this exciting competition. It was a great learning experience and it was very interesting to see how much of our 1st place cryo ET methodology could be applied here. Thanks to @bloodaxe for this great team experience. I would also like to thank the Armed Forces of Ukraine for providing safety and security for my team mate to participate in this competition. \n\n## TLDR\nThe solution is an ensemble of a simple 3D-ResNet18 Classifier and object detection models from MONAI. We also used MONAI for augmentations, and exported models via jit or TensorRT, which gave significant speedup and enabled us to have a slightly larger ensemble. We use the additional data shared by @brendanartley \n\nThis post covers the ResNet18 classification based approach. For object detection part see @bloodaxe writeup: 4th place solution [[Object Detection Part]](https://www.kaggle.com/competitions/byu-locating-bacterial-flagellar-motors-2025/discussion/583228)\n\n## Cross validation\nI split the original training data by Voxel Size and the external data by dataset id, to somewhat mimic train/ test difference. 4 Folds were used. Correlation with LB was not very good, so I mainly relied on LB score for feedback.\n\n## Data preprocessing/ augmentations\n3D images were scaled to a fixed voxel size of 15.6 and saved to disk using int8.\nSince models are trained from scratch, augmentations were essential to prevent overfitting.\nI used RandomCrop (size 96x160x160), Flip on each axis within the torch dataloader, and additionally scale + rotation on GPU (all from MONAI). Additionally, I used a customized implementation of MixUp which was highly effective to train longer and prevent overfitting. I implemented a version which makes sure to not have more than 1 motor in a mixed patch. Additionally, positive samples, i.e. crops with motor in it, were oversampled by having a total fraction of 12.5%\n\n## Model\nModelling was quite interesting in this competition. I started with the 3D UNET from our 1st place solution of CryoET competition, which worked already quite well. After learning about the forgiveness of the competition metric with respect to localization, I tried to simplify the model further and get rid of any decoder altogether, since the 32x downscaled model output should already be enough. Surprisingly, a simple ResNet3D encoder worked. My approach works the following:\n\nInput for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 3x5x5 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss. \nFor inference I used a sliding window aproach with an overlap of 0.5. For motor localisation, simplytake the patch with max prediction value of the 75 classes. Then use the patch location + and offset coming from the 3x5x5 grid to determine the final localisation. This very simple and fast model scores 0.875 on public LB (5th place) individually! \n\n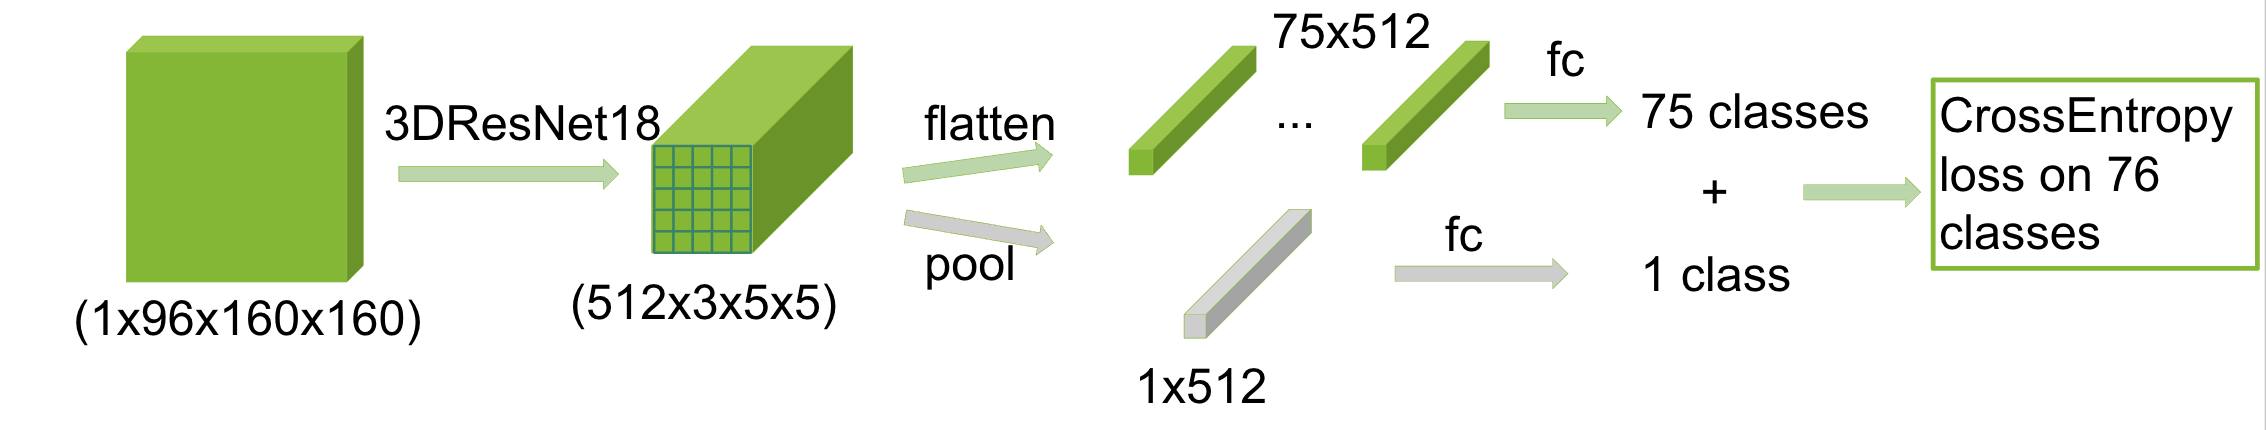\n\nThe architecture might be easier to understand via code:\n\n\n```python\nimport monai.networks.nets as mnn\n\ndef downscale(y, scale=32):\n bs, c, d, h, w = y.shape\n idxs = torch.where(y>0)\n for item in idxs[2:]:\n item //= scale\n y2 = torch.zeros((bs,c,d//scale,h//scale,w//scale), dtype=y.dtype, layout=y.layout, device=y.device)\n y2[idxs] += 1\n return y2\n\ncfg.backbone_args = dict(model_name='resnet18',\n spatial_dims=3, \n pretrained=False, \nin_channels=1)\n\nclass Net(nn.Module):\n\n def __init__(self, cfg):\n super(Net, self).__init__()\n \n self.backbone = mnn.ResNetFeatures(**cfg.backbone_args)\n self.global_pool = nn.AdaptiveAvgPool3d(1)\n self.reg_head = nn.Conv3d(512,1,kernel_size=1,stride=1)\n self.cls_head = torch.nn.Linear(512,1) \n \n def forward(self, batch):\n\n x = batch['input']\n \n out = self.backbone(x)[-1]\n loc_logits = self.reg_head(out)\n cls_logits = self.cls_head(self.global_pool(out).flatten(1))\n\n loss = self.custom_loss(y,loc_logits,cls_logits)\n outputs = {'loss':loss,'logits':loc_logits}\n return outputs\n\n def custom_loss(self, target, logits, cls_logits):\n\n y2 = downscale(target,scale=32)\n l = logits.flatten(1)\n y3 = y2.flatten(1)\n y3 = torch.cat([y3,1-y3.max(1)[0][:,None]],dim=-1)\n l2 = torch.cat([l,cls_logits],dim=-1)\n l_cls = DenseCrossEntropy1D()(l2,y3)\n return l_cls\n\n```\n\nFor threshoolding I used a quantile based a aproach as this was much more stable when comparing different models. \n\nThe model was trained with bf16, and each fold needs about 17h on a single A100 for training. Although the model is small and simple, I tried a lot of other architectures, and alternatives performed much worse. So I sticked with this one. \n\nCode base is very close to[ 1st place solution of cryo et ](https://github.com/ChristofHenkel/kaggle-cryoet-1st-place-segmentation), so I will save me the trouble to publish this one. \nCheers. Questions welcome.", "3218799": "Thanks for the write up. So it seems that for 3d medical image, 3d net often works better than 2d net, even when there is domain shift or the 3d net is simple.\n\nThe softmax localisation directly solved the the problem and replace the post processing", "3218805": ">Input for the classification model are 96x160x160 image patches, which resulted in a feature map of 512x3x5x5 leaving the resnet backbone. I flatten the 355 output \"pixels\" and use a simple fully conected 512->1 layer to have a binary prediction for each pixel, which are basically 75 classes, determin the motor location. I also add an additional class to reflect having no-motor in the crop. So in total its a simple 3D-ResNet18 classifier with 76 classes, which is trained with CrossEntropy Loss.\n\nGiving a class for each pixel in the grid. Localization by classification, that blow up mind. Very nice one!", "3218852": "This approach shares the same idea with [SimCC](https://arxiv.org/pdf/2107.03332), which is a little bit generalized version even for finegrained localization. Also remind me of [DSNT](https://arxiv.org/pdf/1801.07372) with spatial softmax+no post processing as well", "3218858": "christofhenkel amazing idea, the approach is simple but also hard to discover. When did you find this?", "3218860": "Thanks, very unique and elegant solution.\nI’m suprised that you successed with small XY patch size of (160, 160). Now I know that one can make it works.\nOne more question, have you tried direct regression approach, so we need to predict 4 logits only?", "3219084": "Yes, I tried direct regression. It was the 2nd best approach for me", "3219087": "I found it 3 weeks before end. I started with Segmentation using Unet, like 1st place. Then using a lot of experiments arrived at a regression based solution, i.e. using 4 logits output. 1 Logit for motor/ no motor classification and 3 logits for xyz offset. Then simplified to using the feature map directly with a BCE loss, and finally changed to CE Loss as only one output pixel can be correct at max.", "3219183": "christofhenkel that's clutch. Look forward to explore deeper about your method. Seems it can have further innovative designs.", "3219221": "i think accuracy of the coord is not issue here becuase the radius threshold in metric computation is large.\ni think there are several motor like structure in one tomograph and the key to winning could be choosing the correct one.\nso \"sofmax-based loss\" is a good choice. (this is the same reason why 2d approach get slightly lower score ?)\n\nthe issue is how to avoid overfitting when training with \"sofmax-based loss\" as this converge \"much more easily\".", "3219222": "i am curious if \"3 logits for xyz offset\" is better than \"1 logits for xyz offset\". do you experiment results for it? decoupling seems to be a possible regularisation and maybe reduce overfitting?", "3219239": "hengck23 I think later one is better, handling everything all at once seems have advantages. I've tried his strategy in my dual-GNN approach, the pb score instantly reach 0.876-0.885", "3221741": "> I flatten the 355 output \"pixels\"\n\nCan you explain where the \"355\" comes from here please?", "3222112": "its a typo. I meant \"flatten the 3x5x5 output pixels\"", "3235523": "> I implemented a version which makes sure to not have more than 1 motor in a mixed patch\n\nHi @christofhenkel, could you please clarify what exactly this means? Does this imply\n\n1. You only use original data samples that contain a single motor, and your MixUp implementation just ensures that you don’t accidentally introduce a second motor by mixing patches with motors at different locations?\n\nOR\n\n2. Your MixUp implementation handles cases where input patches itself may contain more than one motor, but the logic ensures that only one motor remains in the mixed patch (possibly by masking, cropping, or other logic)?\n\n\nThanks" }, "source": "meta" }