{"metadata":{"kernelspec":{"language":"python","display_name":"Python 3","name":"python3"},"language_info":{"name":"python","version":"3.10.12","mimetype":"text/x-python","codemirror_mode":{"name":"ipython","version":3},"pygments_lexer":"ipython3","nbconvert_exporter":"python","file_extension":".py"},"kaggle":{"accelerator":"none","dataSources":[{"sourceId":19596,"databundleVersionId":1292430,"sourceType":"competition"},{"sourceId":3172,"sourceType":"datasetVersion","datasetId":1833},{"sourceId":1158683,"sourceType":"datasetVersion","datasetId":655608},{"sourceId":1184794,"sourceType":"datasetVersion","datasetId":673455}],"isInternetEnabled":true,"language":"python","sourceType":"notebook","isGpuEnabled":false}},"nbformat_minor":4,"nbformat":4,"cells":[{"cell_type":"markdown","source":"\nTable of Contents \n\n1. [Introduction](#1) \n2. [Exploratory Data Analysis](#2) \n * [Importing Libraries](#21)\n * [Load Bird Species Dataset](#22)\n * [Bird Species Analysis](#23)\n * [Recordings by geographical location](#231)\n * [Samples by Country](#24)\n * [Samples by Date](#25)\n * [Birds Seen](#26)\n * [Pitch](#27)\n * [Sampling Rate](#28)\n * [Volume](#29)\n * [Channels](#210)\n * [Recordists](#211)\n * [Ratings](#212)\n * [Bird seen by Country](#213)\n3. [Audio Data analysis](#3) \n * [Playing audio](#31)\n * [Visualizing audio in 2D](#32)\n * [Spectrogram analysis](#33)\n4. [Feature Extraction](#4) \n * [Spectral Centroid](#41)\n * [Spectral Bandwidth](#42)\n * [Spectral Rolloff](#43)\n * [Zero-Crossing Rate](#44)\n * [Mel-Frequency Cepstral Coefficients(MFCCs)](#45)\n * [Chroma feature](#46)\n5. [Compare sound features](#5)","metadata":{}},{"cell_type":"markdown","source":"\n# 1. Introduction
\n\nDo you hear the birds chirping outside your window? Over 10,000 bird species occur in the world, and they can be found in nearly every environment, from untouched rainforests to suburbs and even cities. Birds play an essential role in nature. They are high up in the food chain and integrate changes occurring at lower levels. As such, birds are excellent indicators of deteriorating habitat quality and environmental pollution. However, it is often easier to hear birds than see them. \n\nWith proper sound detection and classification, researchers could automatically intuit factors about an area’s quality of life based on a changing bird population.\n\nThere are already many projects underway to extensively monitor birds by continuously recording natural soundscapes over long periods. However, as many living and nonliving things make noise, the analysis of these datasets is often done manually by domain experts. These analyses are painstakingly slow, and results are often incomplete. Data science may be able to assist, so researchers have turned to large crowdsourced databases of focal recordings of birds to train AI models. Unfortunately, there is a domain mismatch between the training data (short recording of individual birds) and the soundscape recordings (long recordings with often multiple species calling at the same time) used in monitoring applications. This is one of the reasons why the performance of the currently used AI models has been subpar.\n\n## Objective \nTo identify a wide variety of bird vocalizations in soundscape recordings. Due to the complexity of the recordings, they contain weak labels. There might be anthropogenic sounds (e.g., airplane overflights) or other bird and non-bird (e.g., chipmunk) calls in the background, with a particular labeled bird species in the foreground. Bring new ideas to build effective detectors and classifiers for analyzing complex soundscape recordings.\n\nSo let us use the dataset of Cornell Lab of Ornithology’s Center for Conservation Bioacoustics (CCB) to do a complete exploratory data analysis and finding the insights about data and based on the findings come up with AI model that can achieve the above objective.\n\n\n# Exploratory Data Analysis\n## Importing Libraries","metadata":{}},{"cell_type":"code","source":"!pip install librosa\n!pip install pandas-bokeh\n!pip install chart_studio\n!pip install pydub","metadata":{"trusted":true,"_kg_hide-output":false,"execution":{"iopub.status.busy":"2025-01-26T20:02:27.955281Z","iopub.execute_input":"2025-01-26T20:02:27.955721Z"}},"outputs":[],"execution_count":null},{"cell_type":"code","source":"from plotly.subplots import make_subplots\nimport plotly.graph_objects as go\nimport matplotlib.pyplot as plt\nimport matplotlib.pyplot as plt\nimport IPython.display as ipd\nimport plotly.express as px\nimport librosa.display\nimport pandas as pd\nimport numpy as np\nimport librosa\nimport warnings\nimport IPython\nimport os\nimport wave\nimport pandas_profiling \nimport pandas_bokeh\nfrom bokeh.models.widgets import DataTable, TableColumn\nfrom bokeh.models import ColumnDataSource\nimport matplotlib.pyplot as plt\nimport plotly.graph_objs as go\nimport chart_studio.plotly as py\nimport plotly.figure_factory as ff\nfrom plotly.offline import iplot\nimport cufflinks\nfrom IPython.display import IFrame\nfrom tqdm import tqdm_notebook\nimport IPython as ipy\nimport IPython.display as ipyd\nimport folium\nfrom folium.plugins import HeatMap, HeatMapWithTime\nimport plotly.express as px\nimport re\nfrom pydub import AudioSegment\nfrom scipy.io import wavfile as wav\nimport struct\nfrom scipy.io import wavfile as wav\nfrom colorama import Fore, Back, Style\nimport sklearn\nfrom sklearn.model_selection import train_test_split\nfrom sklearn.preprocessing import LabelEncoder, StandardScaler\nimport datetime as dt\nfrom datetime import datetime \nimport os\nfor dirname, _, filenames in os.walk('/kaggle/input'):\n for filename in filenames:\n print(os.path.join(dirname, filename))\n\nimport warnings\nwarnings.filterwarnings('ignore')\ncufflinks.go_offline()\ncufflinks.set_config_file(world_readable=True, theme='pearl')\nplt.style.use('fivethirtyeight')\nplt.show()\npandas_bokeh.output_notebook()\npd.set_option('plotting.backend', 'pandas_bokeh')\nwarnings.filterwarnings(action='ignore')","metadata":{"trusted":true,"_kg_hide-input":false,"_kg_hide-output":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Load Bird songs Dataset","metadata":{}},{"cell_type":"code","source":"train = pd.read_csv(\"../input/birdsong-recognition/train.csv\")\nmedia_path = '/kaggle/input/birdsong-recognition/train_audio/'","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"train.info()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"def bird_sound_plotter(full_path,data): \n rate, wave_sample = wav.read(full_path)\n wave_file = open(full_path,\"rb\")\n riff_fmt = wave_file.read(36)\n bit_depth_string = riff_fmt[-2:]\n bit_depth = struct.unpack(\"H\",bit_depth_string)[0]\n print(Fore.CYAN+data['title'].upper())\n print('_'*len(data['title']))\n print('')\n print('Scientific Name:',data['sci_name'])\n print(\"Recorded in {} country \".format(data['country']))\n print('Recordist: ',data['author'])\n print('Number of Channels: ',wave_sample.shape[1] if len(wave_sample.shape)>1 else 1)\n print('Number of Samples: ',len(wave_sample))\n print('Rating: ',data['rating'])\n print('Sampling rate: ',rate,'Hz')\n print('Bit depth: ',bit_depth)\n print('Duration: ',wave_sample.shape[0]/rate,' second')\n plt.figure(figsize=(12, 4))\n plt.plot(wave_sample)\n return ipd.Audio(full_path)\n\ndef plot_bird_sound_wave(sp):\n train_sound_data = train[train['species']==sp]\n idx = np.random.choice(train_sound_data.index,1)[0]\n bird_sound_data = train_sound_data.loc[idx,:]\n src = os.path.join('/kaggle/input/birdsong-recognition/train_audio/',bird_sound_data['ebird_code'],bird_sound_data['filename'])\n bird_sound_mp3 = AudioSegment.from_mp3(src)\n filename=bird_sound_data['filename'].split('.')[0]+'.wav'\n bird_sound_mp3.export(filename,format='wav')\n return bird_sound_plotter(filename,bird_sound_data)","metadata":{"_kg_hide-output":true,"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Bird Species Analysis\n\nLet us find out from the dataset how many bird species exist and what are they","metadata":{}},{"cell_type":"code","source":"ebird = train['ebird_code'].value_counts().index.to_list()\nebird_code_path = 'https://ebird.org/species/'\nspecies = [ebird_code_path+i for i in ebird]","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"IFrame(species[16], width=1200, height=600)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"IFrame(species[100], width=1200, height=600)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"print(\"There are {} unique species of birds in train dataset\".format(train.species.nunique()))","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"train['species'].value_counts().sort_values(ascending = False).iplot(kind='bar',color='#85500BF')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Recordings by Geographical Location","metadata":{}},{"cell_type":"code","source":"from kaggle_secrets import UserSecretsClient\nuser_secrets = UserSecretsClient()\nbird_song_geographical_location = user_secrets.get_secret(\"bird_song\")\nbird_song_map = user_secrets.get_secret(\"location\")\ntrain.latitude = train.latitude.str.replace('Not specified','nan').astype(np.float16)\ntrain.longitude = train.longitude.str.replace('Not specified','nan').astype(np.float16)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"px.set_mapbox_access_token(bird_song_map)\nfig = px.scatter_mapbox(train,\n lat='latitude',\n lon='longitude',\n size='duration',\n color='rating',\n hover_name='species',\n hover_data=['country','elevation','duration'],\n color_continuous_scale=px.colors.sequential.Rainbow,\n mapbox_style='stamen-terrain',\n zoom=0.5)\nfig.update_geos(fitbounds=\"locations\", visible=True)\nfig.update_geos(projection_type=\"mercator\")\nfig.update_layout(height=1000,width=1200,margin={\"r\":100,\"t\":200,\"l\":0,\"b\":0})\nfig.update_layout(title='Recording Locations',template='seaborn',\n hoverlabel=dict(bgcolor=\"white\", font_size=16, font_family=\"Rockwell\"))\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Samples by Country","metadata":{}},{"cell_type":"code","source":"country_counts = train.country.value_counts().sort_index(ascending=False) \ndf1 = pd.DataFrame({\"Count\": country_counts},index=train.country)","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"p_hbar = df1.plot_bokeh(\n kind=\"barh\",\n x=country_counts.index,\n xlabel=\"Count\",\n ylabel=\"Country\",\n title=\"Distribution of Bird Species Across Country\", \n alpha=0.4,\n figsize=(800,300),\n legend = \"top_right\",\n show_figure=False)\npandas_bokeh.plot_grid([[p_hbar]],plot_width=1100,plot_height=1000)","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Date of Recordings","metadata":{}},{"cell_type":"code","source":"plt.figure(figsize=(100, 120))\ntrain['date'].value_counts().sort_index().plot(color='blue',alpha=.8)","metadata":{"_kg_hide-input":true,"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Birds Seen","metadata":{}},{"cell_type":"code","source":"train['bird_seen'].value_counts()\n\nlabels = train['bird_seen'].value_counts().index\nvalues = train['bird_seen'].value_counts().values\ncolors=['#9793bf','#bf3fbf']\n\nfig = go.Figure(data=[go.Pie(labels=labels, values=values, textinfo='label+percent',\n insidetextorientation='radial',marker=dict(colors=colors))])\nfig.update_layout(title='Bird Seen')\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Pitch","metadata":{}},{"cell_type":"code","source":"train['pitch'].value_counts()\nlabels = train['pitch'].value_counts().index\nvalues = train['pitch'].value_counts().values\ncolors=['#0093bf','#af3fbf']\n\nfig = go.Figure(data=[go.Pie(labels=labels, values=values, textinfo='label+percent',\n insidetextorientation='radial',marker=dict(colors=colors))])\nfig.update_layout(title='Pitch',annotations=[dict(text='Pitch', x=0.51, y=0.5, font_size=20, showarrow=False)])\nfig.update_traces(hole=.4, hoverinfo=\"label+percent+name\")\nfig.update_traces(hoverinfo='label+percent', textinfo='value', textfont_size=20,\n marker=dict(colors=colors, line=dict(color='#000000', width=2)))\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Sampling Rate\n\nSampling rate (audio) or sampling frequency defines the number of samples per second.","metadata":{}},{"cell_type":"code","source":"train['sampling_rate'].value_counts().sort_values(ascending = False).iplot(kind='bar',color='#09055BF')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Volume","metadata":{}},{"cell_type":"code","source":"train['volume'].value_counts()\nlabels = train['volume'].value_counts().index\nvalues = train['volume'].value_counts().values\ncolors=['#9993bf','#df3abf']\n\nfig = go.Figure(data=[go.Pie(labels=labels, values=values, textinfo='label+percent',\n insidetextorientation='radial',marker=dict(colors=colors))])\nfig.update_layout(title='Pitch',annotations=[dict(text='Volume', x=0.51, y=0.5, font_size=18, showarrow=False)])\nfig.update_traces(hole=.4, hoverinfo=\"label+percent+name\")\nfig.update_traces(hoverinfo='label+percent', textinfo='value', textfont_size=20,\n marker=dict(colors=colors, line=dict(color='#000000', width=2)))\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Channels\nChannel is the passage way a signal or data is transported.One Channel is usually referred to as mono, while more Channels could either indicate stereo, surround sound and the like.","metadata":{}},{"cell_type":"code","source":"channels = train.groupby('channels',as_index=False)['title'].count().sort_values('channels')\nfig = go.Figure()\nfig.add_trace(go.Bar(x=channels['channels'],y=channels['title'],marker_line_color='red',marker_line_width=2.5,text=channels['title'],textposition='auto'))\nfig.update_layout(template='seaborn',height=600,title='Channels',paper_bgcolor='rgb(255,255,255)',plot_bgcolor='rgb(255,255,255)',\n xaxis=dict(title='Channels',nticks=20,mirror=True,linewidth=1,linecolor='green'),\n yaxis=dict(title='Counts',mirror=False,linewidth=1,linecolor='black',gridcolor='darkgrey'))\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Recordist\nLet us find out the number of people who provided the recordings","metadata":{}},{"cell_type":"code","source":"train['recordist'].nunique()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### Now lets say view top 25 recordists and their contributions","metadata":{}},{"cell_type":"code","source":"train['recordist'].value_counts()[:25].sort_values().iplot(kind='barh',color='#89000BF')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Ratings\nLet us find out the ratings","metadata":{}},{"cell_type":"code","source":"ratings = train.groupby('rating',as_index=False)['title'].count().sort_values('rating')\nfig = go.Figure()\nfig.add_trace(go.Bar(x=ratings['rating'],y=ratings['title'],marker_line_color='red',marker_line_width=2.5,text=ratings['title'],textposition='auto'))\nfig.update_layout(template='seaborn',height=600,title='Ratings',paper_bgcolor='rgb(255,255,255)',plot_bgcolor='rgb(255,255,255)',\n xaxis=dict(title='Ratings',nticks=20,mirror=True,linewidth=1,linecolor='green'),\n yaxis=dict(title='Counts',mirror=False,linewidth=1,linecolor='black',gridcolor='darkgrey'))\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Bird Seen by Country","metadata":{}},{"cell_type":"code","source":"bird_seen_countries = train.groupby(['country','bird_seen'],as_index=False).agg({'title':'count','rating':'mean'})\\\n .sort_values('title',ascending=False).reset_index()\nbird_seen_countries = bird_seen_countries.loc[:50,:]\nseen_color = {'yes':'rgb(130, 17, 193)','no':'rgb(229, 58, 156)'}\nfig = go.Figure()\nfor seen in ['yes','no']:\n fig.add_trace(go.Bar(name=seen,y=bird_seen_countries[bird_seen_countries['bird_seen']==seen]['country'],\n x=bird_seen_countries[bird_seen_countries['bird_seen']==seen]['title'],orientation='h',\n marker_line_color='black',marker_line_width=1.5,\n text=np.round(bird_seen_countries[bird_seen_countries['bird_seen']==seen]['rating'],2),textposition='inside',\n marker_color=seen_color[seen]))\nfig.update_layout(height=1500,template='seaborn',paper_bgcolor='rgb(255,255,255)',plot_bgcolor='rgb(255,255,255)',barmode='stack',\n hovermode='y unified',width=1200,\n xaxis=dict(title='No of Recordings',type='log',mirror='allticks',linewidth=2,linecolor='black',\n showgrid=True,gridcolor='darkgray'),\n yaxis=dict(title='Country',mirror=True,linewidth=2,linecolor='black',tickfont=dict(size=12)),\n legend=dict(title='Bird seen in Country',x=0.71,y=0.95,bgcolor='rgba(255, 255, 255, 0)',\n bordercolor='rgba(255, 255, 255, 0)'),\n title='Number of Recordings & Average Ratings per Country [Top 50]')\nfig.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# Audio Data Analysis","metadata":{}},{"cell_type":"markdown","source":"## Playing Audio\n\nThere are about 264 bird species in the dataset and for each species multiple recordings are present.\nWe will be demonstrating the randomly bird chirps recording from the dataset and its sound plot.\n\n### Snow Bunting\n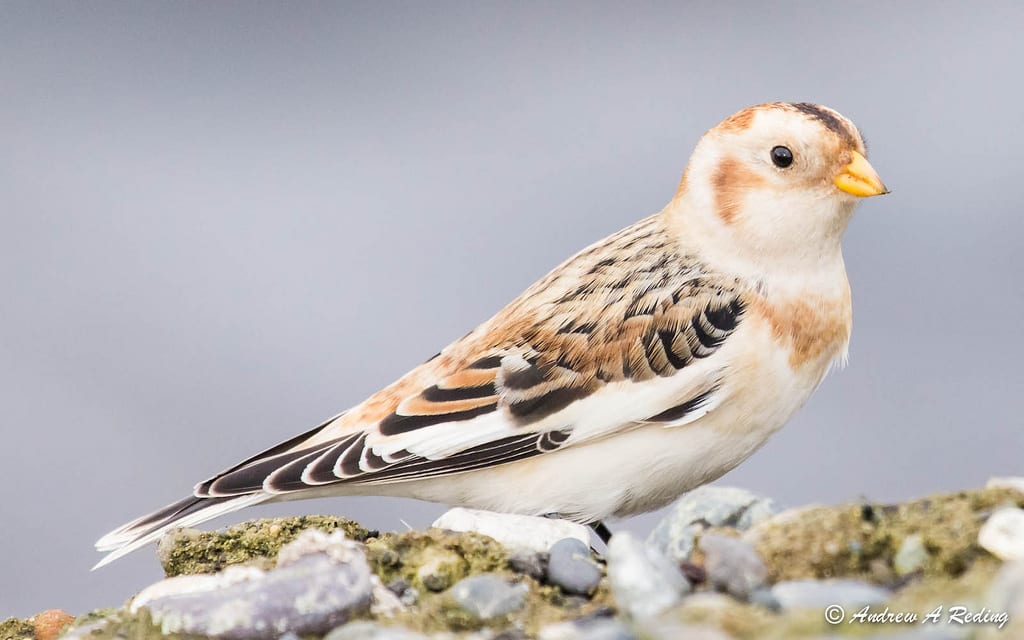\n","metadata":{}},{"cell_type":"code","source":"plot_bird_sound_wave('Snow Bunting')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"### Caspian Tern\n\n","metadata":{}},{"cell_type":"code","source":"plot_bird_sound_wave('Caspian Tern')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"### Barn Swallow\n","metadata":{}},{"cell_type":"code","source":"plot_bird_sound_wave('Barn Swallow')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Visualizing Audio in 2D","metadata":{}},{"cell_type":"code","source":"train = pd.read_csv(\"../input/birdsong-recognition/train.csv\")","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"path=\"../input/birdsong-recognition/train_audio/\"\nbirds=train.ebird_code.unique()[:20]\nfile=train[train.ebird_code==birds[0]]['filename'][0]","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"plt.figure(figsize=(10,20 ))\nfor i in range(0,20):\n file=train[train.ebird_code==birds[i]]['filename'].values[0]\n audio_path=os.path.join(path,birds[i],file)\n plt.subplot(20,1,i+1)\n x , sr = librosa.load(audio_path)\n librosa.display.waveplot(x, sr=sr)\n plt.gca().set_title(birds[i])\n plt.gca().get_xaxis().set_visible(False)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## Spectrogram Analysis\n\n\n\n**What is a spectrogram?**\nA spectrogram is a visual way of representing the signal strength, or “loudness”, of a signal over time at various frequencies present in a particular waveform. Not only can one see whether there is more or less energy at, for example, 2 Hz vs 10 Hz, but one can also see how energy levels vary over time. In other sciences spectrograms are commonly used to display frequencies of sound waves produced by humans, machinery, animals, whales, jets, etc., as recorded by microphones. In the seismic world, spectrograms are increasingly being used to look at frequency content of continuous signals recorded by individual or groups of seismometers to help distinguish and characterize different types of earthquakes or other vibrations in the earth. \n\n**How do you read a spectrogram?**\n\nSpectrograms are basically two-dimensional graphs, with a third dimension represented by colors. Time runs from left (oldest) to right (youngest) along the horizontal axis. Each of our volcano and earthquake sub-groups of spectrograms shows 10 minutes of data with the tic marks along the horizontal axis corresponding to 1-minute intervals. The vertical axis represents frequency, which can also be thought of as pitch or tone, with the lowest frequencies at the bottom and the highest frequencies at the top. The amplitude (or energy or “loudness”) of a particular frequency at a particular time is represented by the third dimension, color, with dark blues corresponding to low amplitudes and brighter colors up through red corresponding to progressively stronger (or louder) amplitudes.\n\nAbove the spectrogram is the raw seismogram, drawn using the same horizontal time axis as the spectrogram (including the same tick marks), with the vertical axis representing wave amplitude. This plot is analogous to webicorder-style plots (or seismograms) that can be accessed via other parts of our website. Collectively, the spectrogram-seismogram combination is a very powerful visualization tool, as it allows you to see raw waveforms for individual events and also the strength or “loudness” at various frequencies. The frequency content of an event can be very important in determining what produced the signal.","metadata":{}},{"cell_type":"code","source":"plt.figure(figsize=(30,20))\nfor i in range(0,5):\n file=train[train.ebird_code==birds[i]]['filename'].values[0]\n audio_path=os.path.join(path,birds[i],file)\n plt.subplot(5,1,i+1)\n x , sr = librosa.load(audio_path)\n x = librosa.stft(x)\n Xdb = librosa.amplitude_to_db(abs(x))\n librosa.display.specshow(Xdb, sr=sr, x_axis='time', y_axis='hz')\n plt.gca().set_title(birds[i])\n plt.gca().get_xaxis().set_visible(False)\n plt.colorbar()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# 4. Audio Features\n## Spectral Centroid\nThe spectral centroid is a measure used in digital signal processing to characterise a spectrum. It indicates where the center of mass of the spectrum is located. Perceptually, it has a robust connection with the impression of brightness of a sound.","metadata":{}},{"cell_type":"markdown","source":"## Spectral Bandwidth\nThe spectral bandwidth is defined as the width of the band of light at one-half the peak maximum (or full width at half maximum [FWHM]) and is represented by the two vertical red lines and λSB on the wavelength axis.","metadata":{}},{"cell_type":"markdown","source":"## Spectral Rolloff\nA feature extractor that extracts the Spectral Rolloff Point. This is a measure measure of the amount of the right-skewedness of the power spectrum.\nThe spectral rolloff point is the fraction of bins in the power spectrum at which 85% of the power is at lower frequencies.","metadata":{}},{"cell_type":"markdown","source":"## Zero-Crossing Rate\nBy looking at different speech and audio waveforms, we can see that depending on the content, they vary a lot in their smoothness. For example, voiced speech sounds are more smooth than unvoiced ones. Smoothness is thus a informative characteristic of the signal.\n\nA very simple way for measuring smoothness of a signal is to calculate the number of zero-crossing within a segment of that signal. A voice signal oscillates slowly - for example, a 100 Hz signal will cross zero 100 per second - whereas an unvoiced fricative can have 3000 zero crossing per second.\n\nTo calculate of the zero-crossing rate of a signal you need to compare the sign of each pair of consecutive samples. In other words, for a length N signal you need O(N) operations. Such calculations are also extremely simple to implement, which makes the zero-crossing rate an attractive measure for low-complexity applications. However, there are also many drawbacks with the zero-crossing rate:\n\nThe number of zero-crossings in a segment is an integer number. A continuous-valued measure would allow more detailed analysis.\nMeasure is applicable only on longer segments of the signal, since short segments might not have any or just a few zero crossings.\nTo make the measure consistent, we must assume that the signal is zero-mean. You should therefore subtract the mean of each segment before calculating the zero-crossings rate.\nAn alternative to the zero-crossing rate is to calculate the autocorrelation at lag-1. It can be estimated also from short segments, it is continuous-valued and arithmetic complexity is also O(N).\n\n","metadata":{}},{"cell_type":"markdown","source":"## Mel-Frequency Cepstral Coefficients(MFCCs)\n\n**Mel Frequency Cepstral Coefficient (MFCC) tutorial**\nThe first step in any automatic speech recognition system is to extract features i.e. identify the components of the audio signal that are good for identifying the linguistic content and discarding all the other stuff which carries information like background noise, emotion etc.\n\nThe main point to understand about speech is that the sounds generated by a human are filtered by the shape of the vocal tract including tongue, teeth etc. This shape determines what sound comes out. If we can determine the shape accurately, this should give us an accurate representation of the phoneme being produced. The shape of the vocal tract manifests itself in the envelope of the short time power spectrum, and the job of MFCCs is to accurately represent this envelope. This page will provide a short tutorial on MFCCs.\n\nMel Frequency Cepstral Coefficents (MFCCs) are a feature widely used in automatic speech and speaker recognition. They were introduced by Davis and Mermelstein in the 1980's, and have been state-of-the-art ever since. Prior to the introduction of MFCCs, Linear Prediction Coefficients (LPCs) and Linear Prediction Cepstral Coefficients (LPCCs) (click here for a tutorial on cepstrum and LPCCs) and were the main feature type for automatic speech recognition (ASR), especially with HMM classifiers. This page will go over the main aspects of MFCCs, why they make a good feature for ASR, and how to implement them.\n\nSteps at a Glance \nWe will give a high level intro to the implementation steps, then go in depth why we do the things we do. Towards the end we will go into a more detailed description of how to calculate MFCCs.\n\n* Frame the signal into short frames.\n* For each frame calculate the periodogram estimate of the power spectrum.\n* Apply the mel filterbank to the power spectra, sum the energy in each filter.\n* Take the logarithm of all filterbank energies.\n* Take the DCT of the log filterbank energies.\n* Keep DCT coefficients 2-13, discard the rest.\n* There are a few more things commonly done, sometimes the frame energy is appended to each feature vector. Delta and Delta-Delta features are usually also appended. Liftering is also commonly applied to the final features.","metadata":{}},{"cell_type":"markdown","source":"## Chroma feature","metadata":{}},{"cell_type":"markdown","source":"# 5. Compare Sound Features","metadata":{}},{"cell_type":"markdown","source":"# Spotify Music - EDA \n\nIn continuation of previous kernel about spotify music data extraction -Part 1 \nhttps://www.kaggle.com/pavansanagapati/spotify-music-api-data-extraction-part1\n\nWe now will use the data extracted from Spotify to perform two steps as follows\n\n#### 1. Explore the Audio Features and analyze\n#### 2. Build a Machine Learning Model \n\n## 1. Explore the Audio Features and analyze","metadata":{}},{"cell_type":"code","source":"#Import Libraries\nimport pandas as pd\nimport seaborn as sns\nimport numpy as np\nimport matplotlib.pyplot as plt\nfrom matplotlib import style\nfrom sklearn.model_selection import cross_val_predict\nfrom sklearn import metrics\nfrom sklearn import svm\n%matplotlib inline\nimport pandas_profiling ","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### Let us first analyse at high level the data in the spotify music dataframe that we build by accessing the spotify data as shown in part 1 of this kernel https://www.kaggle.com/pavansanagapati/spotify-music-api-data-extraction-part1.","metadata":{}},{"cell_type":"code","source":"spotify_music_df = pd.read_csv('../input/spotify-music-data/spotify_music.csv')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_df.shape","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_df.columns","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"Let us now add few more dataframes available datasets in kaggle for our deeper analysis","metadata":{}},{"cell_type":"code","source":"spotify_music_other_df = pd.read_csv('../input/spotifyclassification/data.csv')\nspotify_music_other_df.shape","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_df.columns","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### **Important Note**: Considered only those columns which are related to audio features as follows :\n\n**Acousticness :** A confidence measure from 0.0 to 1.0 of whether the track is acoustic. 1.0 represents high confidence the track is acoustic.\n\n**Danceability** : Danceability describes how suitable a track is for dancing based on a combination of musical elements including tempo, rhythm stability, beat strength, and overall regularity. A value of 0.0 is least danceable and 1.0 is most danceable.\n\n**Energy** : Energy is a measure from 0.0 to 1.0 and represents a perceptual measure of intensity and activity. Typically, energetic tracks feel fast, loud, and noisy. For example, death metal has high energy, while a Bach prelude scores low on the scale. Perceptual features contributing to this attribute include dynamic range, perceived loudness, timbre, onset rate, and general entropy.\n\n**Instrumentalness**: Predicts whether a track contains no vocals. “Ooh” and “aah” sounds are treated as instrumental in this context. Rap or spoken word tracks are clearly “vocal”. The closer the instrumentalness value is to 1.0, the greater likelihood the track contains no vocal content. Values above 0.5 are intended to represent instrumental tracks, but confidence is higher as the value approaches 1.0.\n\n**Liveness**: Detects the presence of an audience in the recording. Higher liveness values represent an increased probability that the track was performed live. A value above 0.8 provides strong likelihood that the track is live.\n\n**Loudness**: he overall loudness of a track in decibels (dB). Loudness values are averaged across the entire track and are useful for comparing relative loudness of tracks. Loudness is the quality of a sound that is the primary psychological correlate of physical strength (amplitude). Values typical range between -60 and 0 db.\n\n**Speechiness**: Speechiness detects the presence of spoken words in a track. The more exclusively speech-like the recording (e.g. talk show, audio book, poetry), the closer to 1.0 the attribute value. Values above 0.66 describe tracks that are probably made entirely of spoken words. Values between 0.33 and 0.66 describe tracks that may contain both music and speech, either in sections or layered, including such cases as rap music. Values below 0.33 most likely represent music and other non-speech-like tracks.\n\n**Valence**: A measure from 0.0 to 1.0 describing the musical positiveness conveyed by a track. Tracks with high valence sound more positive (e.g. happy, cheerful, euphoric), while tracks with low valence sound more negative (e.g. sad, depressed, angry).\n\n**Tempo**: The overall estimated tempo of a track in beats per minute (BPM). In musical terminology, tempo is the speed or pace of a given piece and derives directly from the average beat duration.","metadata":{}},{"cell_type":"code","source":"# Create data frame with features\ndef features(df,who):\n if who == 1:\n features = df.loc[: ,['acousticness', 'danceability','energy','instrumentalness','liveness', 'loudness','speechiness', 'tempo','valence']] \n elif who == 0 : \n features = df.loc[:,['acousticness', 'danceability', 'energy', 'instrumentalness','liveness', 'loudness', 'speechiness', 'tempo', 'valence','popularity']] \n else:\n return 'Error'\n return features","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_audio_features_df = features(spotify_music_other_df, 1)\nspotify_music_other_audio_features_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_audio_features_df = features(spotify_music_df,0)\nspotify_music_audio_features_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"# Let us find the no of records for both datasets with respect to artist\nspotify_music_other_df.artist.count()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_df.album.count()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"Now let create a dictionary in which the keys are the artists of both dataframes and the values are the total of songs for each singer or group.","metadata":{}},{"cell_type":"code","source":"spotify_music_df['album'].value_counts().head(50).plot(kind='barh')","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_df['artist'].value_counts().head(100).plot(kind='barh', figsize=(20,20))","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"### Visualise the data:\nWe will plot a Bar chart and a Radar Chart showing the means of the features.","metadata":{}},{"cell_type":"code","source":"# Number of features\nN = len(spotify_music_audio_features_df.mean())\n# Array with the number of features\nind = np.arange(N) \nwidth = 0.35 \n\n#Bar plot with Micheal Jackson data\nplt.barh(ind, spotify_music_audio_features_df.mean() , width, label='Spotify Music Data - Micheal Jackson', color = 'blue')\n#X- label\nplt.xlabel('Mean', fontsize = 12)\n# Title\nplt.title('Mean Values of the Audio Features for Micheal Jackson')\n#Vertical ticks\nplt.yticks(ind + width / 2, (list(spotify_music_audio_features_df)[:]), fontsize = 12)\n#legend\nplt.legend(loc='best')\n# Figure size\nplt.rcParams['figure.figsize'] =(8,8)\n# Set style\nstyle.use(\"ggplot\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"# Number of features for other artists\nN = len(spotify_music_other_audio_features_df.mean())\n# Array with the number of features\nind = np.arange(N) \nwidth = 0.35 \n\n#Bar plot with Other artists data\nplt.barh(ind, spotify_music_other_audio_features_df.mean() , width, label='Spotify Music Data - Other Artists', color = 'red')\n#X- label\nplt.xlabel('Mean', fontsize = 12)\n# Title\nplt.title('Mean Values of the Audio Features for Other Artists')\n#Vertical ticks\nplt.yticks(ind + width / 2, (list(spotify_music_other_audio_features_df)[:]), fontsize = 12)\n#legend\nplt.legend(loc='best')\n# Figure size\nplt.rcParams['figure.figsize'] =(8,8)\n# Set style\nstyle.use(\"ggplot\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"labels= list(spotify_music_audio_features_df)[:]\nstats= spotify_music_audio_features_df.mean().tolist()\n\n\nangles=np.linspace(0, 2*np.pi, len(labels), endpoint=False)\n\n# close the plot\nstats=np.concatenate((stats,[stats[0]]))\n\nangles=np.concatenate((angles,[angles[0]]))\n\n#Size of the figure\nfig=plt.figure(figsize = (18,18))\n\nax = fig.add_subplot(221, polar=True)\nax.plot(angles, stats, 'o-', linewidth=2, label = \"Micheal Jackson\", color= 'blue')\nax.fill(angles, stats, alpha=0.25, facecolor='blue')\nax.set_thetagrids(angles * 180/np.pi, labels , fontsize = 13)\n\n\nax.set_rlabel_position(250)\nplt.yticks([0.2 , 0.4 , 0.6 , 0.8 ], [\"0.2\",'0.4', \"0.6\", \"0.8\"], color=\"blue\", size=12)\nplt.ylim(0,1)\n\n\nax.set_title('Mean Values of the audio features for Micheal Jackson')\nax.grid(True)\n\nplt.legend(loc='best', bbox_to_anchor=(0.1, 0.1))","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"labels= list(spotify_music_other_audio_features_df)[:]\nstats= spotify_music_other_audio_features_df.mean().tolist()\n\n\nangles=np.linspace(0, 2*np.pi, len(labels), endpoint=False)\n\n# close the plot\nstats=np.concatenate((stats,[stats[0]]))\n\nangles=np.concatenate((angles,[angles[0]]))\n\n#Size of the figure\nfig=plt.figure(figsize = (18,18))\n\nax = fig.add_subplot(221, polar=True)\nax.plot(angles, stats, 'o-', linewidth=2, label = \"Other Artists\", color= 'red')\nax.fill(angles, stats, alpha=0.25, facecolor='red')\nax.set_thetagrids(angles * 180/np.pi, labels , fontsize = 13)\n\n\nax.set_rlabel_position(250)\nplt.yticks([0.2 , 0.4 , 0.6 , 0.8 ], [\"0.2\",'0.4', \"0.6\", \"0.8\"], color=\"red\", size=12)\nplt.ylim(0,1)\n\n\nax.set_title('Mean Values of the audio features for other artists')\nax.grid(True)\n\nplt.legend(loc='best', bbox_to_anchor=(0.1, 0.1))","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"The standard deviation of the audio features themselves do not give us much information ( as we can see in the plots below), we can sum them up and calculate the mean of the standard deviation of the lists.","metadata":{}},{"cell_type":"code","source":"plt.subplot(221)\n\nspotify_music_audio_features_df.std().sort_values(ascending= False).plot(kind = 'bar', color = 'lightslategray')\n\nplt.xlabel('Features', fontsize = 14)\nplt.ylabel('Standard Deviation', fontsize = 14)\nplt.title(\"Standard Deviation of Micheal Jackson Audio Features\")\n\nplt.subplot(222)\n\nspotify_music_other_audio_features_df.std().sort_values(ascending= False).plot(kind = 'bar', color = 'mediumvioletred')\n\nplt.xlabel('Features', fontsize = 14)\nplt.ylabel('Standard Deviation', fontsize = 14)\nplt.title(\"Standard Deviation of Other Artist Audio Features\")\nplt.rcParams['figure.figsize'] =(20,20)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"\n### Correlation Between Variables\n\nWe will correlate the feature **valence** which describes the musical positiveness with **danceability** and **energy**.\n\n\n#### Valence and Energy\nThe correlation between valence and energy shows us that there is a conglomeration of songs with high energy and a low level of valence. This means that many of my energetic songs sound more negative with feelings of sadness, anger and depression ( NF takes special place here haha). whereas when we look at the grays dots we can see that as the level of valence - positive feelings increase, the energy of the songs also increases. Although her data is split , we can identify this pattern which indicates a kind of 'linear' correlation between the variables.","metadata":{}},{"cell_type":"code","source":"fig, ax = plt.subplots()\nstyle.use('seaborn')\nspotify_music_audio_features_df.plot(kind='scatter',x='valence', y='energy',ax = ax ,c='red', colormap = 'Accent_r' ,title=\"Valence x Energy for Micheal Jackson\")\nax.set_xlabel(\"Valence\")\nax.set_ylabel(\"Energy\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"fig, ax = plt.subplots()\nstyle.use('seaborn')\nspotify_music_other_audio_features_df.plot(kind='scatter',x='valence', y='energy',ax = ax ,c='red', colormap = 'viridis_r' ,title=\"Valence x Energy for other artists\")\nax.set_xlabel(\"Valence\")\nax.set_ylabel(\"Energy\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### Valence and Danceability","metadata":{}},{"cell_type":"code","source":"fig,ax = plt.subplots()\nspotify_music_audio_features_df.plot(kind = 'scatter', x = 'valence', y = 'danceability', c = 'red',ax = ax, colormap = 'Accent_r', title = 'Valence x Danceability for Micheal Jackson')\nax.set_xlabel(\"Valence\")\nax.set_ylabel(\"Danceability\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"fig,ax = plt.subplots()\nspotify_music_other_audio_features_df.plot(kind = 'scatter', x = 'valence', y = 'danceability', c = 'red',ax = ax, colormap = 'Accent_r', title = 'Valence x Danceability for other artists')\nax.set_xlabel(\"Valence\")\nax.set_ylabel(\"Danceability\")\nplt.show()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"## 2. The Machine Learning Approach\nI will be using different algorithms as I improve this kernel notebook to improve the model accuracy.So please keep watching this space on a frequent basis.\n\nRemoving Features\nThe first step is to preprocess our data set in order to have a dataframe with numerical values in all of the columns. So let's start off dropping all features which are not relevant to our model such as id, album, name, uri, popularity and track_number and separate the target from other artist dataframe. We can easily do that by building the function feature_elimination which receives a list with the features we want to drop as a parameter.\n\nNotice that after its removal, we still have a categorical feature (artist). So, we'll have to deal with that in the second step. Also, important to mention that we have two slightly balanced classes which indicate whose list the song belongs to.","metadata":{}},{"cell_type":"code","source":"def feature_elimination(features_list):\n for i in features_list:\n spotify_music_other_df.drop(i, axis = 1, inplace = True)\n return ';)'","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"feature_elimination(['Unnamed: 0', 'song_title', 'duration_ms', 'time_signature', 'mode', 'key'])\nspotify_music_other_df.head(3)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"#Remove target column from our data set\ntarget = spotify_music_other_df['target']\nspotify_music_other_df.drop('target', axis = 1, inplace = True)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"target.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"# Let us observe how the data is ? Is it balanced or not .Let us see.\ntarget.value_counts()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"So it is well balanced dataset","metadata":{}},{"cell_type":"code","source":"spotify_music_other_df.head()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### Label Encoder\nThe second task is to transform all categocal data (artists names) into numeric data. Why do we have to do that? Well, the ML algorithm only accepts numerical data, hence, the reason why we have to use the class LabelEncoder to encode each artist name into a specific number. The encoding process is shown below.","metadata":{}},{"cell_type":"code","source":"# Import Label Encoder\nfrom sklearn.preprocessing import LabelEncoder\n\n# create Label Encoder instance\nlabel_encoder = LabelEncoder()\n\n# Set the artist labels\nartist_labels = label_encoder.fit_transform(spotify_music_other_df.artist)\n\n#Create column containing the labels\nspotify_music_other_df['labels_artists'] = artist_labels\n\n#Remove artist column as it contains categorical data\nfeature_elimination(['artist'])\nspotify_music_other_df.sample(10)","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"spotify_music_other_df.labels_artists.value_counts()","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"# URBAN Sound CLASSIFICATION\n\n\n### Introduction\nWhen we get started with data science, we start with simple projects like Loan Prediction problem or Big Mart Sales Prediction. These problems have structured data arranged neatly in a tabular format i.e we are spoon-fed the hardest part in data science pipeline.The datasets in real life are much more complex and unstructured format like audio/image, collect it from various sources and arrange it in a format which is ready for processing. \n\n\nI have choosen an unstructured data as this problem of urban sound classification as it represents huge under-exploited opportunity. It is closer to how we communicate and interact as humans. It also contains a lot of useful & powerful information. For example, if a person speaks; you not only get what he / she says but also what were the emotions of the person from the voice.Also the body language of the person can show you many more features about a person, because actions speak louder than words! So in short, unstructured data is complex but processing it can reap easy rewards.\n\n\n#### So what is audio data really mean ? \n\nLets understand this with some theory before we actually jump in the real problem and its solution.\n\nDirectly or indirectly, you are always in contact with audio. Your brain is continuously processing and understanding audio data and giving you information about the environment. A simple example can be your conversations with people which you do daily. This speech is discerned by the other person to carry on the discussions. Even when you think you are in a quiet environment, you tend to catch much more subtle sounds, like the rustling of leaves or the splatter of rain. This is the extent of your connection with audio.\n\nSo in order to catch this audio floating around us there are devices which record in computer readable format. Examples of these formats are\n\n- wav (Waveform Audio File) format\n- mp3 (MPEG-1 Audio Layer 3) format\n- WMA (Windows Media Audio) format\n\nAudio typically looks like a wave like format of data, where the amplitude of audio change with respect to time. This can be pictorial represented as follows.\n\n\n\n\nReal Time Applications of Audio Processing include but not limited\n\n- Indexing music collections according to their audio features.\n- Recommending music for radio channels\n- Similarity search for audio files (aka Shazam)\n- Speech processing and synthesis – generating artificial voice for conversational agents \n\n#### Data Handling in audio domain\n\nAudio data has a couple of preprocessing steps which have to be followed namely,\n\n- Firstly Load the data into a machine understandable format. \n For this, we simply take values after every specific time steps. For example; in a 2 second audio file, we extract values at half a second. This is called ***sampling of audio data***, and the rate at which it is sampled is called the ***sampling rate***.\n In this approach we have disadvantage i.e When we sample an audio data, we require much more data points to represent the whole data and also, the sampling rate should be as high as possible.To offset this we can look at second approach.\n\n- The second approach of representing audio data is by converting it into a different domain of data representation, namely the ***frequency domain*** which require lesser computational space is required. . \n\nNow let us get more idea on this in detail\n\n\n\nHere, we separate one audio signal into 3 different pure signals, which can now be represented as three unique values in frequency domain.\n\nThere are a few more ways in which audio data can be represented, for example. using MFCs (Mel-Frequency cepstrums. PS: We will cover this in the later article). These are nothing but different ways to represent the data.\n\nNow the next step is to extract features from this audio representations, so that our algorithm can work on these features and perform the task it is designed for. Here’s a visual representation of the categories of audio features that can be extracted.\n\n\n\n\nAfter extracting these features, it is then sent to the machine learning model for further analysis.\n\nNow enough theory.Lets jump into solving the Urban Sound Classifcation Problem\n\n### Objective\n\nThe automatic classification of environmental sound is a growing research field with multiple applications to largescale, content-based multimedia indexing and retrieval. In particular, the sonic analysis of urban environments is the subject of increased interest, partly enabled by multimedia sensor networks, as well as by large quantities of online multimedia content depicting urban scenes.\n\nHowever, while there is a large body of research in related areas such as speech, music and bioacoustics, work on the analysis of urban acoustic environments is relatively scarce.Furthermore, when existent, it mostly focuses on the classification of auditory scene type, e.g. street, park, as opposed to the identification of sound sources in those scenes, e.g.car horn, engine idling, bird tweet. \n\n\n\nThere are primarily two major challenges with urban sound research namely\n\n- Lack of labeled audio data. Previous work has focused on audio from carefully produced movies or television tracks from specific environments such as elevators or office spaces and on commercial or proprietary datasets . The large effort involved in manually annotating real-world data means datasets based on field recordings tend to be relatively small (e.g. the event detection dataset of the IEEE AASP Challenge consists of 24 recordings per each of 17 classes).\n\n- Lack of common vocabulary when working on urban sounds.This means the classification of sounds into semantic groups may vary from study to study, making it hard to compare results\n\nso the objective of this notebook is to address the above two mentioned challenges.\n\n\n### Data\n\nThe dataset is called UrbanSound and contains 8732 labeled sound excerpts (<=4s) of urban sounds from 10 classes: -\nThe dataset contains 8732 sound excerpts (<=4s) of urban sounds from 10 classes, namely:\n\n- Air Conditioner\n- Car Horn\n- Children Playing\n- Dog bark\n- Drilling\n- Engine Idling\n- Gun Shot\n- Jackhammer\n- Siren\n- Street Music\n\nThe attributes of data are as follows:\n\nID – Unique ID of sound excerpt\n\nClass – type of sound\n\nThe evaluation metric for this problem is \"Accuracy Score\"\n\n#### Source\n\n- Source of the dataset : https://drive.google.com/drive/folders/0By0bAi7hOBAFUHVXd1JCN3MwTEU\n- Source of research document : https://serv.cusp.nyu.edu/projects/urbansounddataset/salamon_urbansound_acmmm14.pdf\n\n\nNow let me look at a glance a sample sound excerpt from the dataset","metadata":{"_uuid":"d6135ad1b7f034266e1f6db3633b021889ea3a27"}},{"cell_type":"code","source":"import IPython.display as ipd\nipd.Audio('../input/ultrasound-dataset/train/Train/2022.wav')","metadata":{"trusted":true,"_uuid":"f4bcec54397111dc01d2ad8996be458a5a5ece7c"},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"To load the audio files into the jupyter notebook ass a numpy array I have used 'librosa' library in python by using the pip command as follows\n\n ***pip install librosa***","metadata":{"_uuid":"f29de04532240585cb5818c7e39b0b21d35e0934"}},{"cell_type":"code","source":"!pip install librosa","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"import os\nimport pandas as pd\nimport librosa\nimport librosa.display\nimport glob\n%pylab inline\nfrom sklearn.preprocessing import LabelEncoder\nimport numpy as np\nfrom keras.utils import np_utils\nfrom keras.models import Sequential\nfrom keras.layers import Dense, Dropout, Activation, Flatten\nfrom keras.layers import Convolution2D, MaxPooling2D\nfrom keras.optimizers import Adam\nfrom sklearn import metrics ","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"Now let us load a sample audio file using librosa","metadata":{"_uuid":"91f98dc661b1d87f9d6ba9c4aa7dff30c88e5303"}},{"cell_type":"code","source":"data,sampling_rate = librosa.load('../input/ultrasound-dataset/train/Train/2010.wav')\nplt.figure(figsize=(12,4))\nlibrosa.display.waveplot(data,sr=sampling_rate)","metadata":{"trusted":true,"_uuid":"d8306846e5e9bf0e3d9ee4ac4094d1dd6469e1e9"},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"Now let us visually inspect data and see if we can find patterns in the data","metadata":{"_uuid":"0d44e64d3c5365cbd5462187c4c2a20c35059beb"}},{"cell_type":"code","source":"train = pd.read_csv('../input/ultrasound-dataset/train/train.csv')\ni = random.choice(train.index)\n\naudio_name = train.ID[i]\npath = os.path.join('../input/ultrasound-dataset/train/', 'Train', str(audio_name) + '.wav')\n\nprint('Class: ', train.Class[i])\nx, sr = librosa.load('../input/ultrasound-dataset/train/Train/' + str(train.ID[i]) + '.wav')\n\nplt.figure(figsize=(12, 4))\nlibrosa.display.waveplot(x, sr=sr)","metadata":{"trusted":true,"_uuid":"55f24ebdec94e87f9351a312de8951f5a991c29a"},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"As you can see the air conditioner class is shown as random class and we can see its pattern.Let us again see another class by using the same code to randomly select another class and observe its pattern","metadata":{"_uuid":"225885357b4a7b5568ab9b28c2661e74e2936e2a"}},{"cell_type":"code","source":"i = random.choice(train.index)\naudio_name = train.ID[i]\npath = os.path.join('../input/ultrasound-dataset/train/', 'Train', str(audio_name) + '.wav')\nprint('Class: ', train.Class[i])\nx, sr = librosa.load('../input/ultrasound-dataset/train/Train/' + str(train.ID[i]) + '.wav')\nplt.figure(figsize=(12, 4))\nlibrosa.display.waveplot(x, sr=sr)","metadata":{"trusted":true,"_uuid":"789325dcfde1a02bea2e451faffd7ac303b5c13f"},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"Let us see the class distributions for this problem","metadata":{"_uuid":"df1042ccc44a8ef8a0dd46593b9cc9abd99e51ba"}},{"cell_type":"code","source":"print(train.Class.value_counts(normalize=True)) #distribution of data","metadata":{"trusted":true,"_uuid":"593203a5c675dcb7050a1cdfa5eb7ed9d0cceec0"},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"It appears that jackhammer has more count than any other classes\n\nNow let us see how we can leverage the concepts we learned above to solve the problem. We will follow these steps to solve the problem.\n\n- Step 1: Load audio files & Extract features\n- Step 2: Convert the data to pass it in our deep learning model\n- Step 3: Run a deep learning model and get results\n\n#### Step 1: Load audio files & Extract features\n\nLet us create a function to load audio files and extract features","metadata":{"_uuid":"7a5edc0e3d276f18cd7e8162657bc0cda878bb6a"}},{"cell_type":"code","source":"def parser(row):\n file_name = os.path.join(os.path.abspath('../input/ultrasound-dataset/train/'),'Train',str(row.ID)+'.wav')\n try:\n # here kaiser_fast is a technique used for faster extraction\n X,sample_rate = librosa.load(file_name,res_type='kaiser_fast')\n # we extract mfcc feature from data\n mfccs = np.mean(librosa.feature.mfcc(y=X,sr=sample_rate,n_mfcc=40).T,axis=0)\n except Exception as e:\n print('Error encountered while parsing the file:',file_name)\n \n return 'None', 'None'\n \n feature = mfccs\n \n label = row.Class\n #print(file_name)\n print(feature)\n print(label)\n return pd.Series([feature, label],index=['feature','label'])","metadata":{"trusted":true,"_uuid":"6cd0d5eb913efd2dd5a9fdbdca876e721511cb58"},"outputs":[],"execution_count":null},{"cell_type":"code","source":"temp = train.apply(parser,axis =1)\ntemp.columns = ['feature', 'label']","metadata":{"trusted":true,"_uuid":"786b607c60748d35391d9d6692867b5d98c31740","_kg_hide-output":true},"outputs":[],"execution_count":null},{"cell_type":"markdown","source":"#### Step 2: Convert the data to pass it in our deep learning model\n","metadata":{"_uuid":"433d28c32afb1ae9c3e0c8b030ca883671e28fcc"}},{"cell_type":"code","source":"X = np.array(temp.feature.tolist())\ny = np.array(temp.label.tolist())\n\nlabel_encoder = LabelEncoder()\nprint(temp.label.dtype)","metadata":{"trusted":true,"_uuid":"f70092010147fe50a5ccdc6e6aad7a3df32138b4"},"outputs":[],"execution_count":null},{"cell_type":"code","source":"y = np_utils.to_categorical(label_encoder.fit_transform(y)) ","metadata":{"trusted":true,"_uuid":"8da4d73ed70585adeb322bb47e5b0bcb53f9917b"},"outputs":[],"execution_count":null},{"cell_type":"code","source":"39.4s 1 /usr/local/lib/python3.10/dist-packages/traitlets/traitlets.py:2915: FutureWarning: --Exporter.preprocessors=[\"remove_papermill_header.RemovePapermillHeader\"] for containers is deprecated in traitlets 5.0. You can pass `--Exporter.preprocessors item` ... multiple times to add items to a list.\n9.4s 2 warn(\n9.4s 3 [NbConvertApp] Converting notebook __notebook__.ipynb to notebook\n9.8s 4 [NbConvertApp] Writing 2776 bytes to __notebook__.ipynb\n11.4s 5 /usr/local/lib/python3.10/dist-packages/traitlets/traitlets.py:2915: FutureWarning: --Exporter.preprocessors=[\"nbconvert.preprocessors.ExtractOutputPreprocessor\"] for containers is deprecated in traitlets 5.0. You can pass `--Exporter.preprocessors item` ... multiple times to add items to a list.\n11.4s 6 warn(\n11.4s 7 [NbConvertApp] Converting notebook __notebook__.ipynb to html\n12.3s 8 [NbConvertApp] Writing 274626 bytes to __results__.html","metadata":{"trusted":true},"outputs":[],"execution_count":null},{"cell_type":"code","source":"## If you like this kernel greatly appreciate to UPVOTE.","metadata":{"trusted":true},"outputs":[],"execution_count":null}]}