{"cells":[{"metadata":{},"cell_type":"markdown","source":"\n# Understand Bengali and the DataSet\nThis notebook is to shed more light on Bengali language and the dataset on how to analyse and make a general model on it.\n\n### This Kernal is for beginners who are new for KERAS and TensorFlow,\n### This kernal is teaches how to create your own custom CNN models layer by layer !!\n\n\nTo understand this you need to know ,\n 1. Python\n 2. Basics of Keras and TF\n 3. Basic Understanding for CNN\n \nCHECK OUT - [Bengali AI: 3-Output model Tutorial using TF](https://www.kaggle.com/chekoduadarsh/bengali-ai-3-output-model-tutorial-using-tf)"},{"metadata":{},"cell_type":"markdown","source":"# Bengali\n\nBengali also known by its endonym Bangla, is an Indo-Aryan language primarily spoken by the Bengalis in South Asia. It is brahmic language which is assumed to be evoloved from Sanskrit\n\n## Alphabets\nThe Bengali script can be divided into vowels and vowel diacritics/marks, consonants and consonant conjuncts, diacritical and other symbols, digits, and punctuation marks. Vowels & consonants are used as alphabet and also as diacritical marks. Bengali contains 28 letters\n### Vowels\nThe Bengali script has a total of 9 vowel graphemes, each of which is called swôrôbôrnô \"vowel letter\"\n\n| Vowels | Vowels phoneme | \n|---|---|\n| **অ** |ô|\n| **আ ** | a |\n| **ই** | i |\n| **ঈ** | ī/ee |\n| **উ** | u |\n| **ঊ** | ū/oo |\n|**ঋ** | ṛ/ri |\n| **ৠ** | ṝ/rri |\n| **ঌ** | ḷ/li |\n| **ৡ** | ḹ/lli |\n\n#### Complex Vowels\nBengali also has 4 complex vowels\n\n| Complex Vowels | Vowels phoneme | \n|---|---|\n| **এ ** | e |\n| **ঐ** | oi |\n| **ও** | o |\n| **ঔ** | ou |\n\n### Consonants\nConsonant letters are called bænjônbôrnô \"consonant letter\" in Bengali. The names of the letters are typically just the consonant sound plus the inherent vowel. \n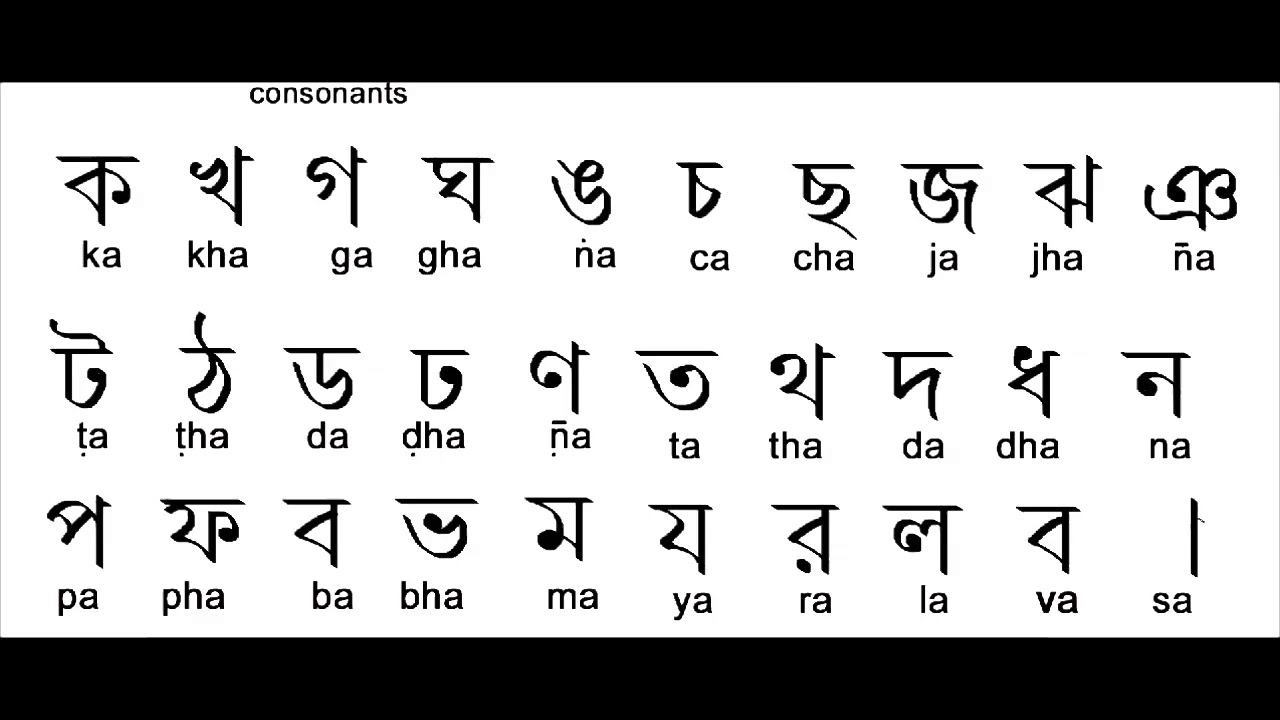\n\n\n\nSince they work on combination there are 19 x 9 letters to be identified."},{"metadata":{},"cell_type":"markdown","source":"# TakeAway \n \n1. Since it is a brahmic language models which perform well on other brahmic language like [Devanagiri-Recognizer](https://github.com/akshaybahadur21/Devanagiri-Recognizer) will perform better than new models\n\n2. As we noticed the difference between two characters are very less so we need a model which also gives important to minute details so it is not wise to put big kernal size\n\n3. As with all type of MNIST Here also imagedatagenerator will help you to do better"},{"metadata":{},"cell_type":"markdown","source":"# Data\n\nLets jump into it. \n\nThe training dataset contains images and csv files representing its grapheme root and vowel and consonants id which are used to construct the image"},{"metadata":{"_cell_guid":"b1076dfc-b9ad-4769-8c92-a6c4dae69d19","_uuid":"8f2839f25d086af736a60e9eeb907d3b93b6e0e5","trusted":true},"cell_type":"code","source":"#Load em...\nfrom matplotlib import pyplot as plt\nimport numpy as np # linear algebra\nimport pandas as pd # data processing, CSV file I/O (e.g. pd.read_csv)\nimport PIL.Image as Image, PIL.ImageDraw as ImageDraw, PIL.ImageFont as ImageFont\nimport random \nimport os\nimport cv2\nimport gc\nfrom tqdm.auto import tqdm\nfor dirname, _, filenames in os.walk('/kaggle/input'):\n for filename in filenames:\n print(os.path.join(dirname, filename))\n\n# Any results you write to the current directory are saved as output.\n\ntrain_data = pd.read_csv('/kaggle/input/bengaliai-cv19/train.csv')\ntest_data= pd.read_csv('/kaggle/input/bengaliai-cv19/test.csv')\nclass_map_data = pd.read_csv('/kaggle/input/bengaliai-cv19/class_map.csv')\nsample_sub_data = pd.read_csv('/kaggle/input/bengaliai-cv19/sample_submission.csv')","execution_count":null,"outputs":[]},{"metadata":{"_cell_guid":"79c7e3d0-c299-4dcb-8224-4455121ee9b0","_uuid":"d629ff2d2480ee46fbb7e2d37f6b5fab8052498a","trusted":true},"cell_type":"code","source":"train_data.head()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Train_data\nContains,\n1. Image_id -> Id of training Image\n2. grapheme_root -> character number (vowel + consonant)\n3. vowel_diacritic -> root vowel id number\n4. consonant_diacritic -> root consonant id number"},{"metadata":{"trusted":true},"cell_type":"code","source":"test_data.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"class_map_data.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def resize(df, size=64, need_progress_bar=True):\n resized = {}\n for i in range(df.shape[0]):\n image = cv2.resize(df.loc[df.index[i]].values.reshape(137,236),(size,size))\n resized[df.index[i]] = image.reshape(-1)\n resized = pd.DataFrame(resized).T\n return resized","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"# CNN Model"},{"metadata":{"trusted":true},"cell_type":"code","source":"import numpy as np\nimport keras\nfrom keras.models import Sequential\nfrom keras.layers import Dense, Dropout, Flatten\nfrom keras.layers import Conv2D, MaxPooling2D\nfrom keras.optimizers import SGD\nfrom keras.layers.normalization import BatchNormalization\nfrom keras.layers import LeakyReLU\nfrom keras.models import clone_model\nfrom sklearn.model_selection import train_test_split\nfrom keras.callbacks import ReduceLROnPlateau\nfrom keras.preprocessing.image import ImageDataGenerator\n\nimport tensorflow as tf\nfrom tensorflow import keras\nfrom tensorflow.keras import layers\nimport numpy as np\nimport datetime as dt\n","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Design your repetitive block!!"},{"metadata":{"trusted":true},"cell_type":"code","source":"def res_net_block_1(input_data, filters):\n \n x1 = layers.Conv2D(filters, 3, activation='relu', padding='same')(input_data)\n x1 = tf.nn.leaky_relu(x1, alpha=0.01, name='Leaky_ReLU') \n x2 = layers.BatchNormalization()(x1)\n x2 = layers.Dropout(0.1)(x2)\n \n x3 = layers.Conv2D(filters, 5, activation=None, padding='same')(x2)\n x3 = tf.nn.leaky_relu(x3, alpha=0.01, name='Leaky_ReLU') \n x4 = layers.BatchNormalization()(x3)\n x4 = layers.Dropout(0.1)(x4)\n \n x5 = layers.Conv2D(filters, 1, activation=None, padding='same')(input_data)\n x5 = tf.nn.leaky_relu(x5, alpha=0.01, name='Leaky_ReLU') \n\n x = layers.Add()([x4 , x5 ])\n x = layers.Activation('relu')(x)\n return x","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"def res_net_block_2(input_data, filters):\n \n x1 = layers.Conv2D(filters, 3, activation='relu', padding='same')(input_data)\n x1 = tf.nn.leaky_relu(x1, alpha=0.01, name='Leaky_ReLU') \n x2 = layers.BatchNormalization()(x1)\n x2 = layers.Dropout(0.1)(x2)\n \n x3 = layers.Conv2D(filters, 5, activation=None, padding='same')(input_data)\n x3 = tf.nn.leaky_relu(x3, alpha=0.01, name='Leaky_ReLU') \n x4 = layers.BatchNormalization()(x3)\n x4 = layers.Dropout(0.1)(x4)\n \n x5 = layers.Conv2D(filters, 1, activation=None, padding='same')(input_data)\n x5 = tf.nn.leaky_relu(x5, alpha=0.01, name='Leaky_ReLU') \n\n x = layers.Add()([x2 , x4 , x5 ])\n x = layers.Activation('relu')(x)\n return x","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Try using both block_1 and block_2 separately"},{"metadata":{"trusted":true},"cell_type":"code","source":"def resnet(inputsize,outputsize,depth):\n inputs = keras.Input(shape=(inputsize,inputsize,1))\n x = layers.Conv2D(32, (3,3), activation='relu')(inputs)\n x = tf.nn.leaky_relu(x, alpha=0.01, name='Leaky_ReLU') \n x = layers.Conv2D(64, (3,3), activation='relu')(x)\n x = tf.nn.leaky_relu(x, alpha=0.01, name='Leaky_ReLU') \n #x = \n x = layers.MaxPooling2D(3)(x)\n x = layers.Dropout(0.1)(x)\n num_res_net_blocks = depth\n for i in range(num_res_net_blocks):\n #x = res_net_block_1(x, 64)\n x = res_net_block_2(x, 64)\n x = layers.Conv2D(64, 3, activation='relu')(x)\n x = tf.nn.leaky_relu(x, alpha=0.01, name='Leaky_ReLU') \n x = layers.GlobalAveragePooling2D()(x)\n x = layers.Dense(256, activation='relu')(x)\n x = layers.Dropout(0.5)(x)\n output = layers.Dense(outputsize, activation='softmax')(x)\n model = keras.Model(inputs, output)\n return model\n\nResNet = True \nCNN = False\nmodel_root = resnet(64, 168,10) # Input imagesize, outputtensor size, depth\nmodel_vowel = resnet(64, 11,10)\nmodel_consonant = resnet(64, 7,10)\n\n\n\nfrom tensorflow.keras.utils import plot_model #Plot the models for visualization\nplot_model(model_root, to_file='model1.png')\nplot_model(model_vowel, to_file='model2.png')\nplot_model(model_consonant, to_file='model3.png')\n\n","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Creating 3 similar model for Graphemes_root, vowel and consonant"},{"metadata":{"trusted":true},"cell_type":"code","source":"model_root.compile(optimizer=\"adam\", loss=['categorical_crossentropy'], metrics=['accuracy']) # Adam optimizer with catagorical_crossentropy modern best\nmodel_vowel.compile(optimizer=\"adam\", loss=['categorical_crossentropy'], metrics=['accuracy'])\nmodel_consonant.compile(optimizer=\"adam\", loss=['categorical_crossentropy'], metrics=['accuracy'])","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"batch_size = 128\nepochs = 20","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Train it"},{"metadata":{"trusted":true},"cell_type":"code","source":"num_dataset = 1","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"learning_rate_reduction = ReduceLROnPlateau(monitor='val_accuracy', \n patience=3, \n verbose=1,\n factor=0.5, \n min_lr=0.00001)","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"model_dict = {\n 'grapheme_root': model_root,\n 'vowel_diacritic': model_vowel,\n 'consonant_diacritic': model_consonant\n}\n\nhistory_list = []\ntrain_data = pd.read_csv('/kaggle/input/bengaliai-cv19/train.csv')","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"for i in range(num_dataset): \n b_train_data = pd.merge(pd.read_parquet(f'/kaggle/input/bengaliai-cv19/train_image_data_{i}.parquet'), train_data, on='image_id').drop(['image_id'], axis=1)\n train_image = b_train_data.drop(['grapheme_root', 'vowel_diacritic', 'consonant_diacritic','grapheme'], axis=1)\n train_image = resize(train_image)/255\n train_image = train_image.values.reshape(-1, 64, 64, 1) # Image with 64x64x1 diamentions\n \n for target in ['grapheme_root', 'vowel_diacritic', 'consonant_diacritic']:\n Y_train = b_train_data[target]\n Y_train = pd.get_dummies(Y_train).values\n x_train, x_test, y_train, y_test = train_test_split(train_image, Y_train, test_size=0.05, random_state=666)\n datagen = ImageDataGenerator(\n featurewise_center=False, # set input mean to 0 over the dataset\n samplewise_center=False, # set each sample mean to 0\n featurewise_std_normalization=False, # divide inputs by std of the dataset\n samplewise_std_normalization=False, # divide each input by its std\n zca_whitening=False, # apply ZCA whitening\n rotation_range=8, # randomly rotate images in the range (degrees, 0 to 180)\n zoom_range = 0.15, # Randomly zoom image \n width_shift_range=0.15, # randomly shift images horizontally (fraction of total width)\n height_shift_range=0.15, # randomly shift images vertically (fraction of total height)\n horizontal_flip=False, # randomly flip images\n vertical_flip=False) # randomly flip images\n\n\n # This will just calculate parameters required to augment the given data. This won't perform any augmentations\n datagen.fit(x_train)\n history = model_dict[target].fit_generator(datagen.flow(x_train, y_train, batch_size=batch_size),\n epochs = epochs, validation_data = (x_test, y_test),\n steps_per_epoch=x_train.shape[0] // batch_size, \n callbacks=[learning_rate_reduction])\n history_list.append(history)\n #histories.append(history)\n del x_train\n del x_test\n del y_train\n del y_test\n history_list.append(history)\n gc.collect()\n \n # Delete to reduce memory usage\n del train_image\n del b_train_data\n \ndel train_data\ngc.collect()","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Plot the training results"},{"metadata":{"trusted":true},"cell_type":"code","source":"%matplotlib inline\ndef plot_loss(his, epoch, title):\n plt.figure()\n plt.plot(np.arange(0, epoch), his.history['loss'], label='train_loss')\n plt.plot(np.arange(0, epoch), his.history['val_loss'], label='val_loss')\n \n plt.title(title)\n plt.xlabel('Epoch #')\n plt.ylabel('Loss')\n plt.legend(loc='upper right')\n plt.show()\n\ndef plot_acc(his, epoch, title):\n plt.figure()\n plt.plot(np.arange(0, epoch), his.history['accuracy'], label='accuracy') \n plt.plot(np.arange(0, epoch), his.history['val_accuracy'], label='val_accuracy')\n plt.title(title)\n plt.xlabel('Epoch #')\n plt.ylabel('Accuracy')\n plt.legend(loc='upper right')\n plt.show()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"for dataset in range(num_dataset):\n plot_loss(history_list[dataset], epochs, f'Training Dataset: {dataset}')\n plot_acc(history_list[dataset], epochs, f'Training Dataset: {dataset}')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":""},{"metadata":{"trusted":true},"cell_type":"code","source":"model_save = {\n 'grapheme_root': 'lir_model_root.h5',\n 'vowel_diacritic': 'lir_model_vowel.h5',\n 'consonant_diacritic': 'lir_model_consonant.h5'\n}\n\n\nmodel_root.save('model_root.h5')\nmodel_vowel.save('model_vowel.h5')\nmodel_consonant.save('model_consonant.h5')","execution_count":null,"outputs":[]},{"metadata":{},"cell_type":"markdown","source":"## Predict"},{"metadata":{"trusted":true},"cell_type":"code","source":"preds_dict = {\n 'grapheme_root': [],\n 'vowel_diacritic': [],\n 'consonant_diacritic': []\n}","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"components = ['consonant_diacritic', 'grapheme_root', 'vowel_diacritic']\ntarget=[] # model predictions placeholder\nrow_id=[] # row_id place holder\nfor i in range(4):\n test_img = pd.read_parquet('/kaggle/input/bengaliai-cv19/test_image_data_{}.parquet'.format(i)) \n test_img.set_index('image_id', inplace=True)\n\n X_test = resize(test_img)/255\n X_test = X_test.values.reshape(-1, 64, 64, 1)\n\n for pred in preds_dict:\n preds_dict[pred]=np.argmax(model_dict[pred].predict(X_test), axis=1)\n\n for k,id in enumerate(test_img.index.values): \n for i,comp in enumerate(components):\n id_sample=id+'_'+comp\n row_id.append(id_sample)\n target.append(preds_dict[comp][k])\n del test_img\n del X_test\n gc.collect()\n\ndf_sample = pd.DataFrame(\n {\n 'row_id': row_id,\n 'target':target\n },\n columns = ['row_id','target'] \n)\ndf_sample.to_csv('submission.csv',index=False)\ndf_sample.head()","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]},{"metadata":{"trusted":true},"cell_type":"code","source":"","execution_count":null,"outputs":[]}],"metadata":{"kernelspec":{"display_name":"Python 3","language":"python","name":"python3"},"language_info":{"codemirror_mode":{"name":"ipython","version":3},"file_extension":".py","mimetype":"text/x-python","name":"python","nbconvert_exporter":"python","pygments_lexer":"ipython3","version":"3.6.6"}},"nbformat":4,"nbformat_minor":1}