
Hi all,
\n\nA beginner here.. Trying to understand how K-fold CV should be used in computer vision problems. Do you guys train a model with different folds just to evaluate the model and finally train with whole data to get final predictions? If yes, how would you fix number of epochs for the final training since we can't early stop/pick min loss since validation data is not there?
\n\nOr is it like train with k folds and average predictions of k folds?
\n\nThanks in advance.
", "messages": [ { "id": "608173", "postDate": "08/26/2019 12:41:47", "content": "Hi all,
\n\nA beginner here.. Trying to understand how K-fold CV should be used in computer vision problems. Do you guys train a model with different folds just to evaluate the model and finally train with whole data to get final predictions? If yes, how would you fix number of epochs for the final training since we can't early stop/pick min loss since validation data is not there?
\n\nOr is it like train with k folds and average predictions of k folds?
\n\nThanks in advance.
", "rawMarkdown": "Hi all,\n\nA beginner here.. Trying to understand how K-fold CV should be used in computer vision problems. Do you guys train a model with different folds just to evaluate the model and finally train with whole data to get final predictions? If yes, how would you fix number of epochs for the final training since we can't early stop/pick min loss since validation data is not there?\n\nOr is it like train with k folds and average predictions of k folds?\n\nThanks in advance.", "votes": null }, { "id": "608197", "postDate": "08/26/2019 13:36:28", "content": "
Thanks @simakov .. So the first approach doesn't make sense in this case?
", "rawMarkdown": "Thanks @simakov .. So the first approach doesn't make sense in this case?", "votes": null }, { "id": "608240", "postDate": "08/26/2019 14:32:11", "content": "I think, early stopping and bagging are more important than the bigger training set in this case.
", "rawMarkdown": "I think, early stopping and bagging are more important than the bigger training set in this case.", "votes": null }, { "id": "608314", "postDate": "08/26/2019 16:04:34", "content": "Hi JM100, we continue with the same weights for the next split after we are done with the previous/current split right ?
", "rawMarkdown": "Hi JM100, we continue with the same weights for the next split after we are done with the previous/current split right ?", "votes": null }, { "id": "608327", "postDate": "08/26/2019 16:20:42", "content": "@vaibhargava, no, this strategy leads to a target leak: your validation set in the current step have been used for training model in the previous step. So, the model is overfits and the validation score is higher than should be. So, you should reset weights for every split.
", "rawMarkdown": "vaibhargava, no, this strategy leads to a target leak: your validation set in the current step have been used for training model in the previous step. So, the model is overfits and the validation score is higher than should be. So, you should reset weights for every split.", "votes": null }, { "id": "608360", "postDate": "08/26/2019 17:00:08", "content": "Thank you. So, I should go with the parameters which had the best performance with regards to the validation set in anyone of the split of the k-fold ?
", "rawMarkdown": "Thank you. So, I should go with the parameters which had the best performance with regards to the validation set in anyone of the split of the k-fold ?", "votes": null }, { "id": "610426", "postDate": "08/28/2019 19:36:59", "content": "you should go with the parameters which give the best CV score. That means the parameters that make the model generalize better overall the (Splits) folds
", "rawMarkdown": "you should go with the parameters which give the best CV score. That means the parameters that make the model generalize better overall the (Splits) folds", "votes": null }, { "id": "616313", "postDate": "09/03/2019 01:55:43", "content": "Good , Also a beginner here. do you guys can share a K-fold code ,I have try other tricks on my model except K-fold.
", "rawMarkdown": "Good , Also a beginner here. do you guys can share a K-fold code ,I have try other tricks on my model except K-fold.", "votes": null } ], "comments": [ { "id": 608197, "author_name": "simakov", "author_url": "", "post_date": "08/26/2019 13:36:28", "content": "Thanks @simakov .. So the first approach doesn't make sense in this case?
", "votes": null, "replies": [] }, { "id": 608240, "author_name": "simakov", "author_url": "", "post_date": "08/26/2019 14:32:11", "content": "I think, early stopping and bagging are more important than the bigger training set in this case.
", "votes": null, "replies": [] } ] }, { "id": 608231, "author_name": "jmourad100", "author_url": "", "post_date": "08/26/2019 14:13:45", "content": "
Hi JM100, we continue with the same weights for the next split after we are done with the previous/current split right ?
", "votes": null, "replies": [] }, { "id": 608327, "author_name": "simakov", "author_url": "", "post_date": "08/26/2019 16:20:42", "content": "@vaibhargava, no, this strategy leads to a target leak: your validation set in the current step have been used for training model in the previous step. So, the model is overfits and the validation score is higher than should be. So, you should reset weights for every split.
", "votes": null, "replies": [] }, { "id": 608360, "author_name": "vaibhargava", "author_url": "", "post_date": "08/26/2019 17:00:08", "content": "Thank you. So, I should go with the parameters which had the best performance with regards to the validation set in anyone of the split of the k-fold ?
", "votes": null, "replies": [] }, { "id": 610426, "author_name": "jmourad100", "author_url": "", "post_date": "08/28/2019 19:36:59", "content": "you should go with the parameters which give the best CV score. That means the parameters that make the model generalize better overall the (Splits) folds
", "votes": null, "replies": [] }, { "id": 616313, "author_name": "chopinforest1986", "author_url": "", "post_date": "09/03/2019 01:55:43", "content": "Good , Also a beginner here. do you guys can share a K-fold code ,I have try other tricks on my model except K-fold.
", "votes": null, "replies": [] } ] } ], "raw_markdown_by_id": { "608173": "Hi all,\n\nA beginner here.. Trying to understand how K-fold CV should be used in computer vision problems. Do you guys train a model with different folds just to evaluate the model and finally train with whole data to get final predictions? If yes, how would you fix number of epochs for the final training since we can't early stop/pick min loss since validation data is not there?\n\nOr is it like train with k folds and average predictions of k folds?\n\nThanks in advance.", "608197": "2.", "608231": "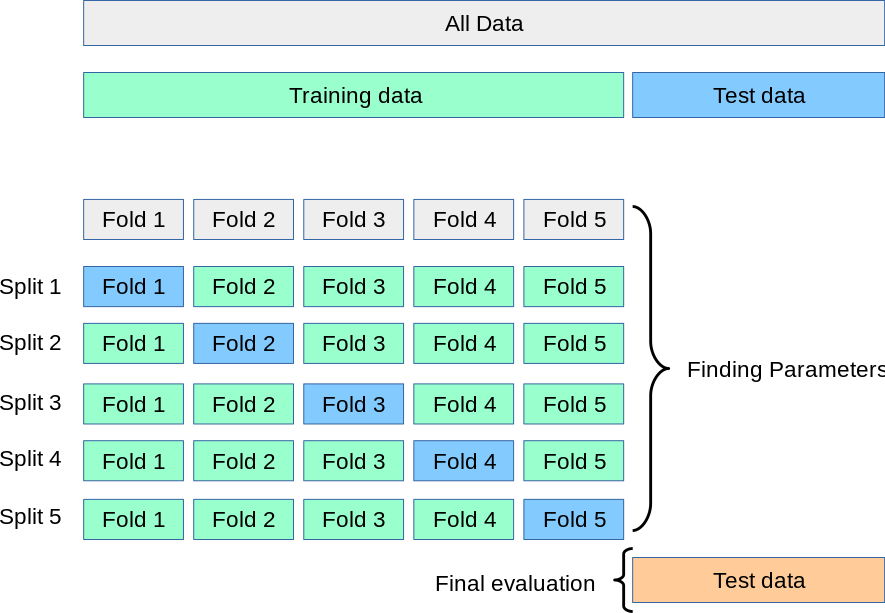", "608232": "Thanks @simakov .. So the first approach doesn't make sense in this case?", "608240": "I think, early stopping and bagging are more important than the bigger training set in this case.", "608314": "Hi JM100, we continue with the same weights for the next split after we are done with the previous/current split right ?", "608327": "vaibhargava, no, this strategy leads to a target leak: your validation set in the current step have been used for training model in the previous step. So, the model is overfits and the validation score is higher than should be. So, you should reset weights for every split.", "608360": "Thank you. So, I should go with the parameters which had the best performance with regards to the validation set in anyone of the split of the k-fold ?", "610426": "you should go with the parameters which give the best CV score. That means the parameters that make the model generalize better overall the (Splits) folds", "616313": "Good , Also a beginner here. do you guys can share a K-fold code ,I have try other tricks on my model except K-fold." }, "source": "meta" }